Transcription vv2 2026 Rank: #810
ElevenLabs Scribe ✓
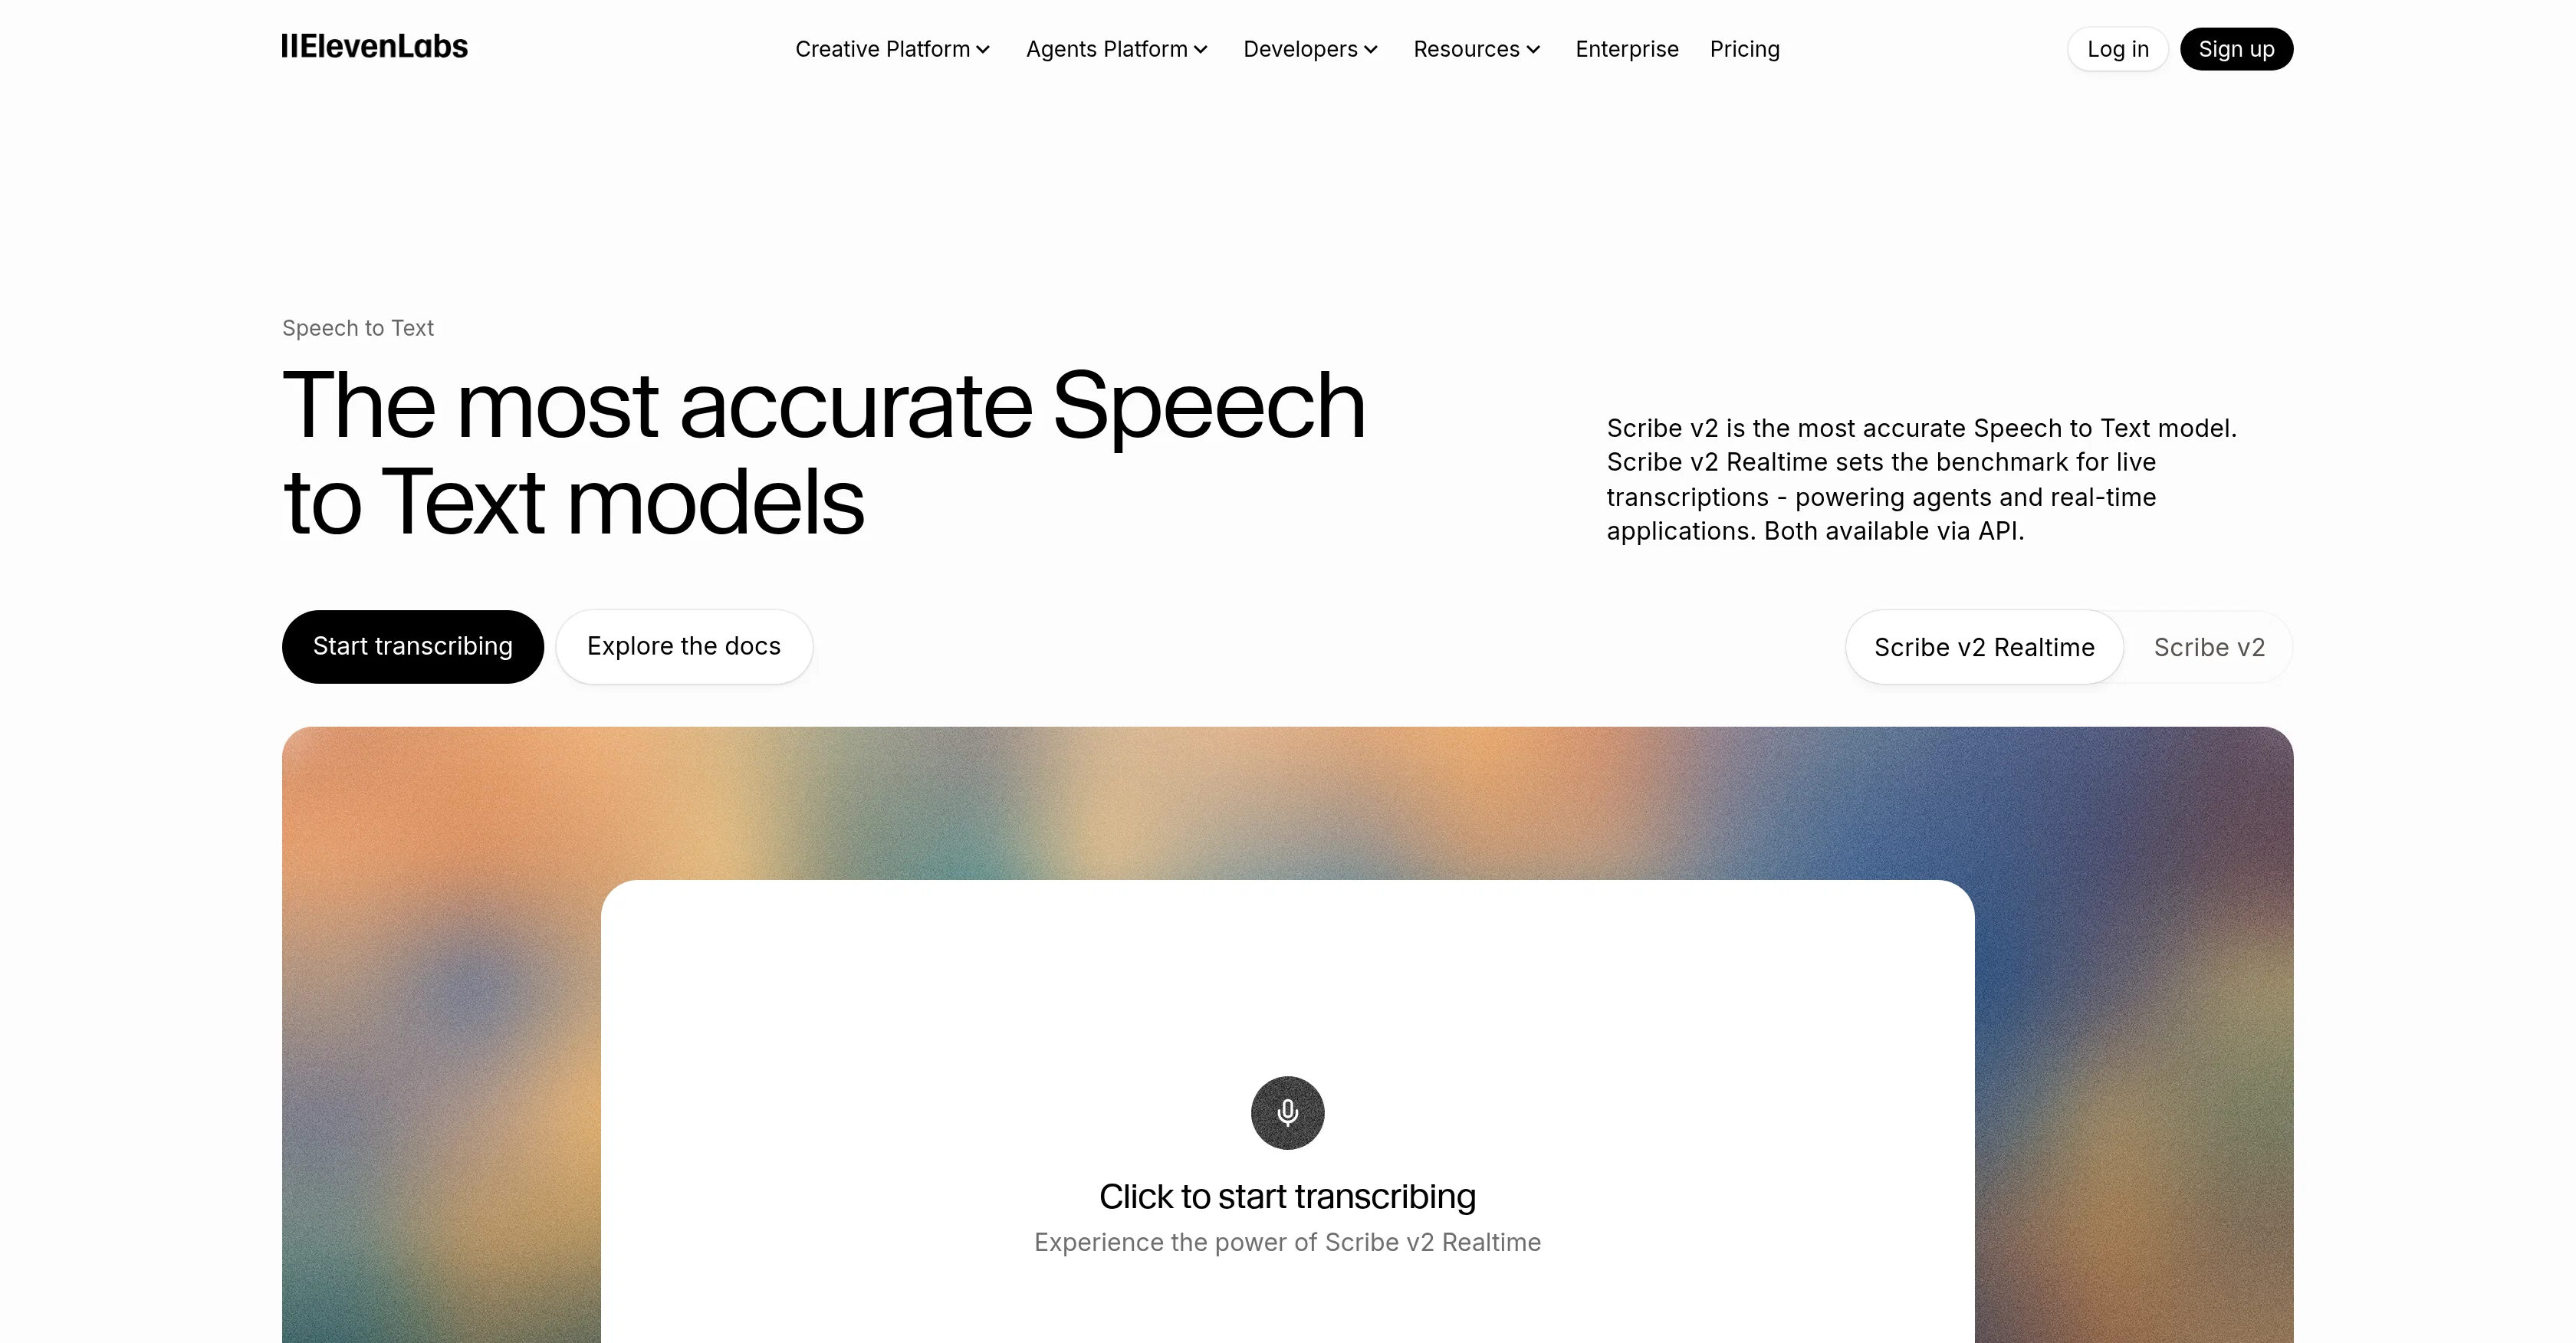
The most accurate Speech to Text models
Free + from $5/mo
Verdict
A quick read before you dig into the full page.
- Best if
- You are creators and need: Creating audiobooks with multiple characters
- Skip if
- Complex API integration
- Pick this when
- Multilingual transcription
Considering Voicetype AI instead? Compare side by side
Overview
ElevenLabs Speech to text is a speech-to-text model that specializes in converting speech into text with remarkable accuracy across multiple contexts and languages.
It houses two main features namely, Scribe v2 and Scribe v2 Realtime. The former focuses on the transcription of audio and video content into text, perfect for creating captions, subtitles, and editable transcripts for various forms of recorded content.
It stands out for its ability to accurately transcribe specific words based on context, marked sound events in transcripts, and distinguish and label every speaker in a dialogue.
The latter, Scribe v2 Realtime, is designed for real-time applications with an emphasis on things like live calls, meetings, or AI agents requiring immediate transcription.
It uses a streaming-first architecture to provide real-time results while still maintaining accuracy. It also includes features like precision speech segmentation for smoother live processing and voice activity detection.
Both versions of Scribe support over 90 languages and can be incorporated into your products using their API.
Best for
Short scenarios where ElevenLabs Scribe tends to shine.
-
Creating audiobooks with multiple characters
Best for Creators
-
Generating voiceovers for videos
Best for Media & Entertainment companies
-
Dubbing videos into multiple languages
Best for Developers
-
Creating podcasts with voice isolation
Best for Startups
-
Powering AI phone agents for customer support
Best for Enterprises
-
Adding voice to AI assistants
Best for Publishing houses
-
Building engaging experiences for education technology
Best for Education Technology companies
-
Integrating AI audio into media creation platforms
Best for Call Centers
Example outputs 1
Sample generations and before/after results for ElevenLabs Scribe.
Access & connections
Where you can use ElevenLabs Scribe.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Input
- API
- Video
- Audio
Output
- API
- Text
Supported features
- Transcription
- STT
- SynthID
- Speech API
Pros & cons
Pros
- Multilingual transcription
- Real-time transcription
- Supports 90+ languages
- API integration
- High transcription accuracy
- Context-based word transcription
- Marked sound events in transcripts
- Speaker distinguishing in dialogues
Show 37 more
- Streaming-first architecture
- Precision speech segmentation
- Voice activity detection
- Content creation: captions, subtitles
- Transcript editing
- Supports recorded content
- Transcript for audio/video
- Live processing
- Performance benchmarking
- Industry-leading latency
- Automated keyterm prompting
- Dynamic audio tagging
- Captures live speech
- Enterprise-grade security
- Control over data handling
- Supports encrypted APIs
- Granular team permissions for collaboration
- Elevated support for smooth launch
- Supports local and cloud configurations
- Automated speaker diarization for overlapping conversations
- Recognizes diverse accents
- Transcribe diverse media formats: MP4, MOV, MP3, WAV
- Supports offline processing
- Can transcribe difficult audio conditions
- Entity timestamps calculation
- Effective for social media videos
- Supports diverse workflows: API to agents
- Supports hands-free typing
- Automatic data encryption in transit and at rest
- Includes editing tools and collaboration features
- SOC 2, HIPAA, and GDPR compliance
- Supports accessibility and content repurposing
- Handled through encrypted APIs
- Sensitive information processed locally
- Auto-generation of captions and subtitles
- Industry-leading accuracy across 90+ languages
- Sub-150 ms latency
Cons
- No offline support
- Doesn't support all languages
- No free tier
- Context-based transcription inconsistencies
- Possibly high latency
- Language support varies by accuracy
- Complex API integration
Compare alternatives
Similar tools in the catalog — with a clear reason to open each one.
Voicetype AI ✓
Free TrialWrite 9x Faster with AI Speech to Text on all Apps
Why look Better for writing
Full comparison
Transcript LOL ✓
FreemiumUnlimited transcripts, summaries, 99.8% accuracy, speaker recognition, superfast
Why look Offers a public API
Full comparison
TurboScribe ✓
Freemium🎯 3 free transcripts every day. 🔥 Unlimited transcription starting at $10/mo.
Free + from $10/mo
Full comparison
RambleFix ✓
Paid⚡ Write by thinking aloud - emails, notes, articles, in your style.
Why look Better for writing
Full comparison
Paraspeech ✓
Free TrialPrivate dictation, cloud optional
Why look More privacy-focused
Full comparisonPeople also view
Tools that often show up alongside ElevenLabs Scribe in collections and comparisons.
Voicetype AI ✓
Free TrialWrite 9x Faster with AI Speech to Text on all Apps
TurboScribe ✓
Freemium🎯 3 free transcripts every day. 🔥 Unlimited transcription starting at $10/mo.
Transcript LOL ✓
FreemiumUnlimited transcripts, summaries, 99.8% accuracy, speaker recognition, superfast
RambleFix ✓
Paid⚡ Write by thinking aloud - emails, notes, articles, in your style.
Paraspeech ✓
Free TrialPrivate dictation, cloud optional
Recap Raven ✓
Free TrialTTRPG Discord bot that recaps, transcribes, GM prep notes and campaign memory
Realms of Shod ✓
Free TrialMultiplayer tools, AI notes, and knowledge-graph surfaces for TTRPG worlds and stories
Pulse by smallest.ai ✓
FreemiumWorld's fastest and most accurate speech-to-text.
Releases 2
Live real-time speech-to-text model — built for streaming transcription with very low latency (~150 ms) for live voice interactions.
Ultra-low latency performance — instant speech transcription ideal for conversational AI, voice agents, meetings, and live captioning. 
High accuracy across many languages — supports 90+ languages with strong real-world performance and benchmark scores. 
Predictive streaming (“negative latency”) — anticipates next words and punctuation to reduce delays. 
Automatic language detection — the model detects and switches languages mid-conversation. 
Advanced streaming controls — includes manual commit control, text conditioning, and voice activity detection (VAD). 
Broad audio format support — works with PCM (8–48 kHz) and μ-law audio for compatibility across use cases.
FAQ 12
What is the main functionality of ElevenLabs Speech to Text Scribe?
What is the difference between Scribe v2 and Scribe v2 Realtime?
How accurate is the transcription offered by the Scribe models?
How does Scribe handle multiple speakers in a conversation?
How many languages does ElevenLabs Speech to Text Scribe support?
Can Scribe be integrated into my products?
How does Scribe handle real-time applications?
What is the 'streaming-first' architecture?
What is Scribe's precision speech segmentation feature?
Can Scribe distinguish and label different speakers?
What is voice activity detection in the context of Scribe?
How does Scribe handle the transcription of specific words based on context?
Related tools
Recommended
MagicSlides.app AI PPT Maker ✓
FreemiumCreate Stunning PPTs in Seconds with the AI PPT Maker

TheLibrarian.io ✓
Free TrialYour WhatsApp AI assistant for instant productivity.

Agentgpt ✓
FreemiumDeploy autonomous AI Agents effortlessly in your browser.
Recall ✓
FreemiumSummarize Anything, Forget Nothing!

Notis ✓
Free TrialThe first WhatsApp assistant that runs on your ChatGPT and Claude subscriptions
Perplexity ✓
FreemiumAI-powered answers to any question, instantly.