
Productivity vv2 2026 Rank: #1319
Inception Chat ✓
The fastest commercial-grade diffusion LLM
Verdict
A quick read before you dig into the full page.
- Best if
- The fastest commercial-grade diffusion LLM
- Skip if
- Limited user interface description
- Pick this when
- Commercial-grade diffusion LLM
Considering TheLibrarian.io instead? Compare side by side
Overview
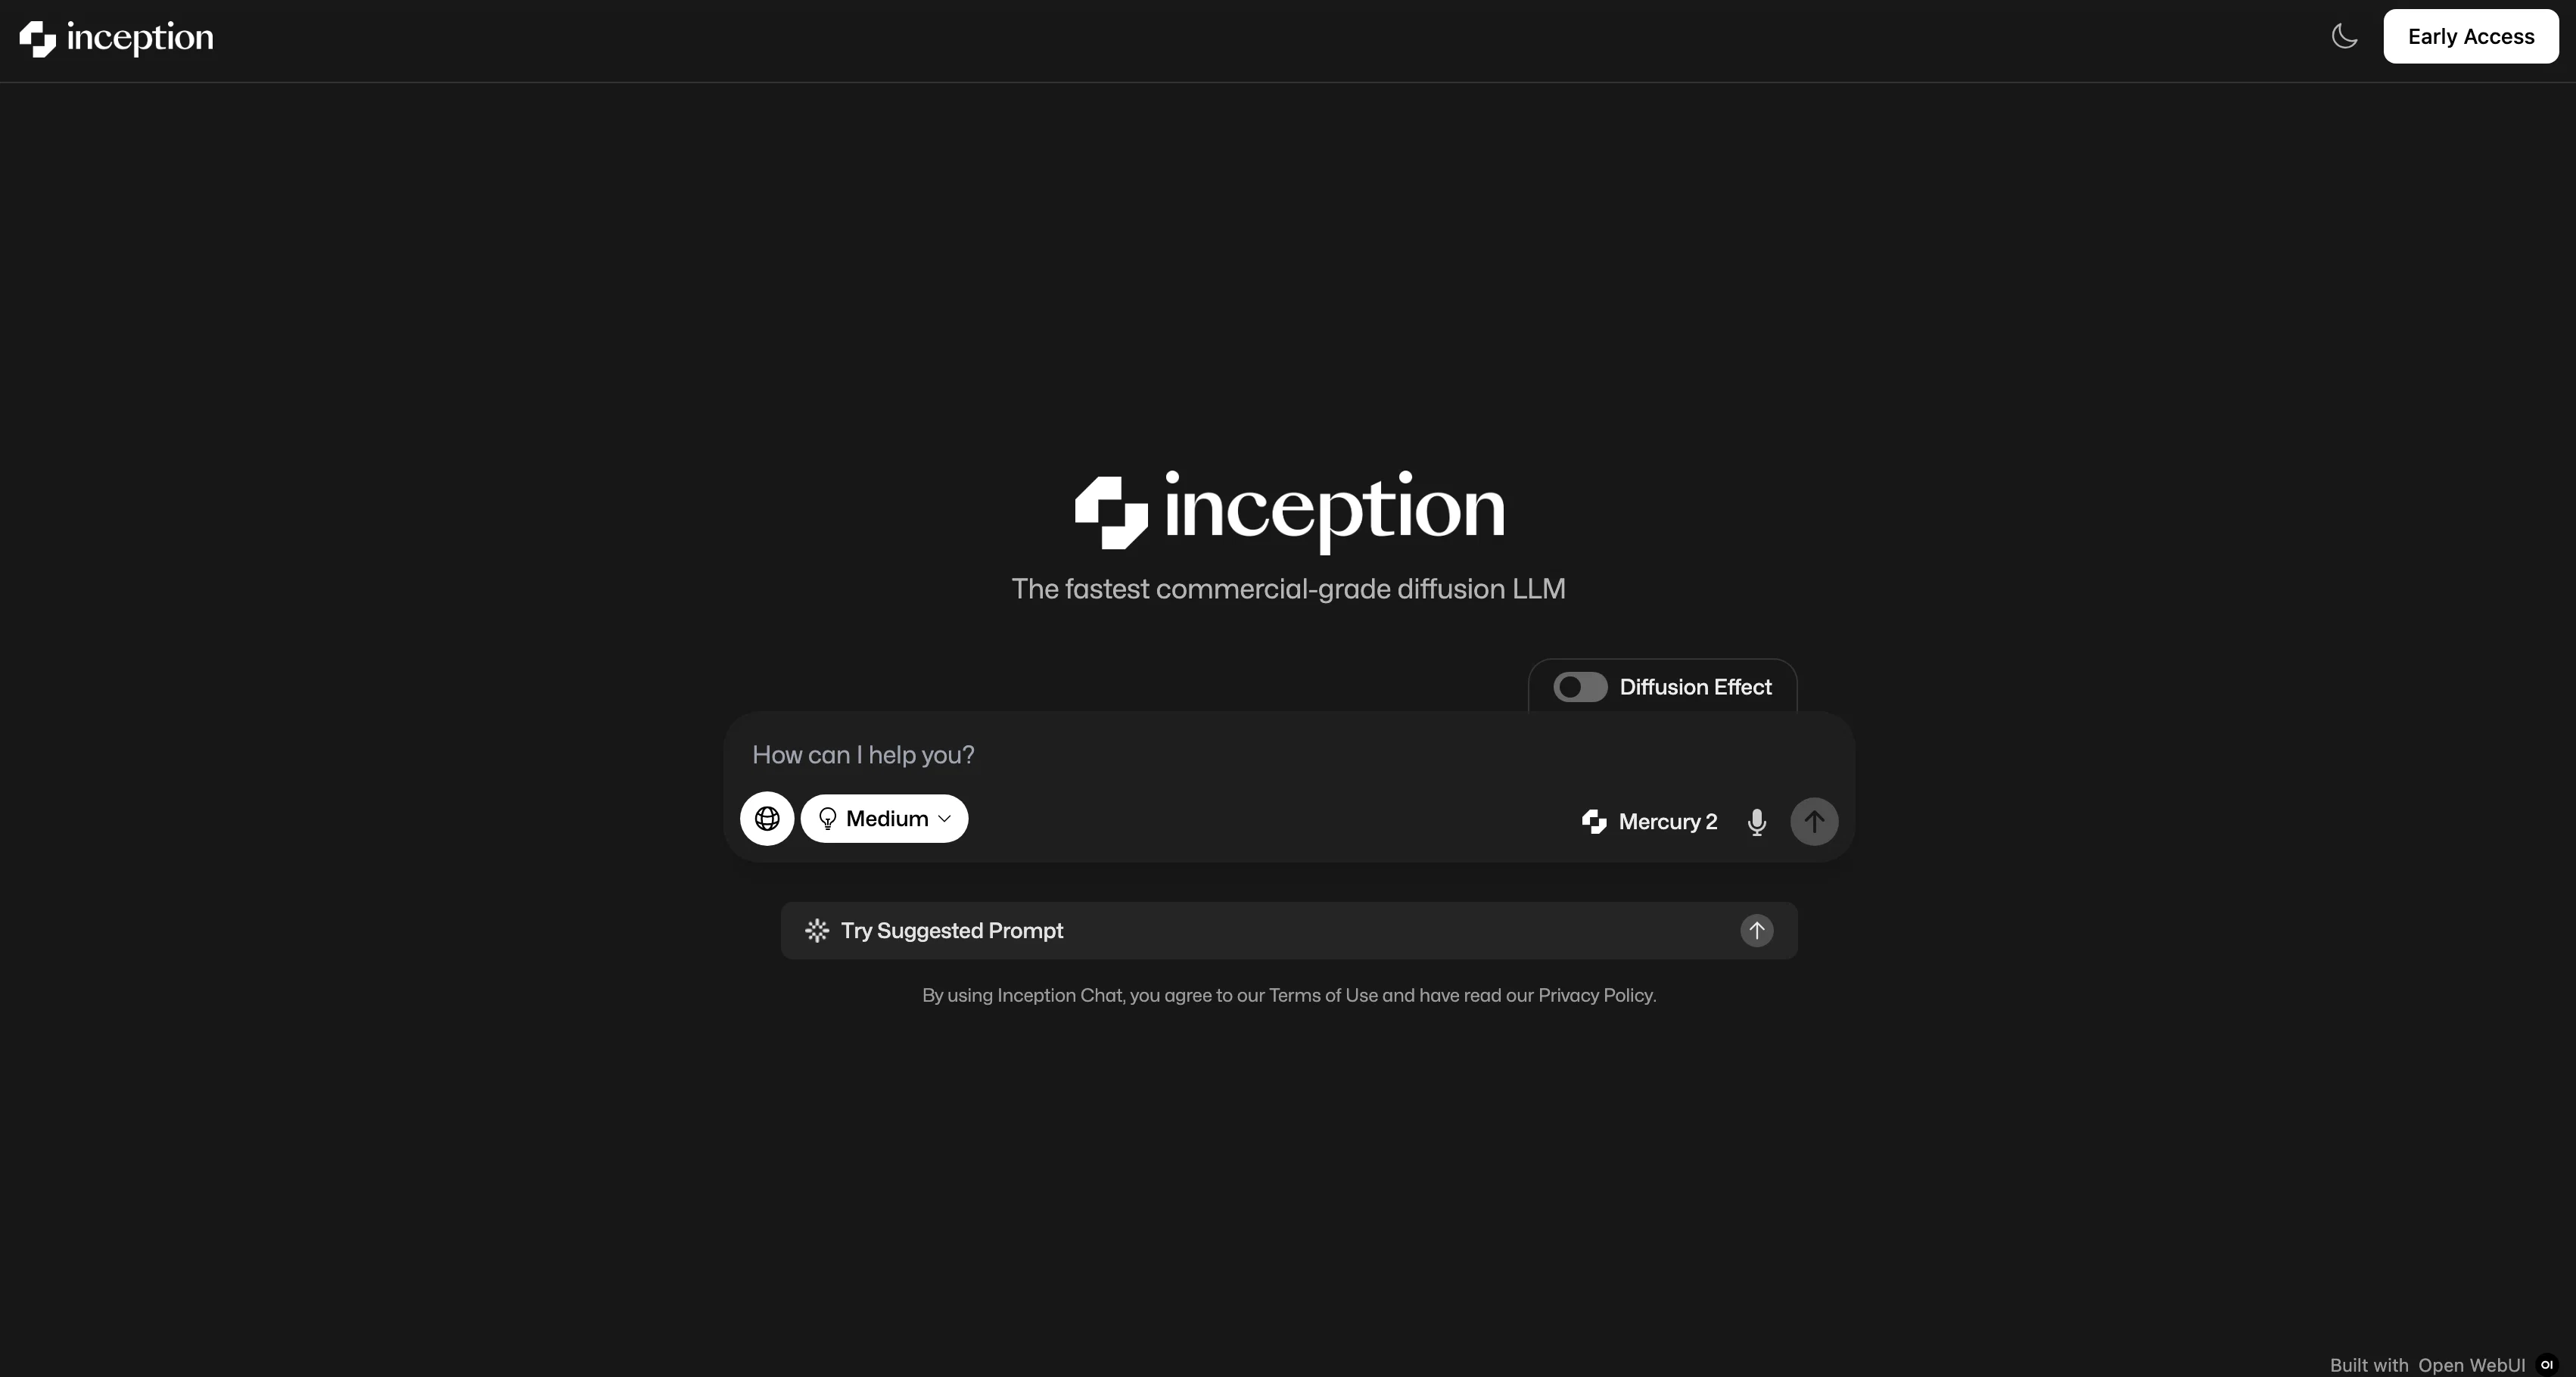
Inception Chat is an AI tool developed with a commercial-grade diffusion LLM (Language Model). It brings a new level of speed and efficiency to handling and decoding language structures.
Users have early access to the intuitive interface and innovative features that dramatically improve communication efficiency. The tool uniquely features the 'Diffusion Effect', details of which are not clarified in the provided text, but implied to have a significant impact on enhancing communication.
It also includes features like 'Mercury 2' and 'Suggested Prompts' to further aid the user experience. The utilization of Open WebUI in its development implies a focus on building a user-friendly and accessible tool, catering to various user requirements.
However, users must be aware of the data collection and sharing practices of Inception Chat for analytical and customization purposes as stated in their Privacy Policy and Terms of Use.
This tool represents a skillfully designed blend of high computational power and sophisticated language understanding, aiming to revolutionize how we interpret and handle language data.
Access & connections
Where you can use Inception Chat.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Highlights
- SOTA
Pros & cons
Pros
- Commercial-grade diffusion LLM
- Speedy language handling
- Decoding language structure
- Early access
- Intuitive interface
- Innovative features
- Communication efficiency
- 'Diffusion Effect' feature
Show 8 more
- 'Mercury 2' feature
- 'Suggested Prompts' feature
- Uses Open WebUI
- User-friendly
- Accessible
- Customizable services
- High computational power
- Advanced language understanding
Cons
- Unclear 'Diffusion Effect' functionality
- Potential privacy concerns
- Data sharing practices
- Vague 'Mercury 2' feature
- 'Suggested Prompts' efficacy unknown
- Limited user interface description
- No data collection opt-out
- Early access may be unstable
Show 2 more
- Uses undefined commercial-grade LLM
- Terms of Use ambiguity
Compare alternatives
Similar tools in the catalog — with a clear reason to open each one.

TheLibrarian.io ✓
Free TrialYour WhatsApp AI assistant for instant productivity.
Free + from $9.99/mo
Full comparison
Supernormal App ✓
FreemiumThe AI assistant app that turns meetings into completed work
Free + from $25.90/mo
Full comparison

MiroAI ✓
FreemiumUnlock creative power with AI-driven collaboration.
Free + from $8
Full comparison
Collate ✓
FreeUnlimited free and private summaries and chat with PDF
Why look More privacy-focused
Full comparison
Releases 3
Adds an explicit “reasoning” positioning, described as the fastest reasoning language model in their lineup.
Introduces tunable reasoning as a first-class feature for trading speed vs depth per request.
Adds native tool use plus schema-aligned JSON output as headline production features.
Sharpens the “production loops” focus (agents, RAG, extraction) as the core value proposition rather than just raw fast generation.
OpenAI-API compatibility so it can slot into existing stacks without rewrites.
First commercial-scale diffusion LLM family designed for fast, high-quality text generation.
“Mercury Coder” is a code-focused variant intended for coding benchmarks, RAG, tool use, and agent workflows.
Parallel, coarse-to-fine generation (diffusion) instead of token-by-token decoding, enabling much faster throughput.
Positioned as a drop-in replacement for autoregressive LLM use cases, including tool use and agentic workflows.
Emphasis on speeding up long reasoning traces and making “reasoning-grade” behavior more practical at lower latency
FAQ 12
What is Inception Chat?
How does Inception Chat improve communication efficiency?
What is the 'Diffusion Effect' in Inception Chat?
What is 'Mercury 2' in Inception Chat?
How do 'Suggested Prompts' in Inception Chat work?
What is the use of Open WebUI in Inception Chat?
Can I customize Inception Chat according to my needs?
What kind of data does Inception Chat collect?
What is the privacy policy of Inception Chat?
What are the terms of use for Inception Chat?
How does Inception Chat handle language data?
Is Inception Chat user-friendly?
Related tools
Recommended
Thea ✓
FreemiumAI study tools to master material, not just memorize it.

Kin - Personal AI Advisors ✓
FreePrivacy-first & designed your for mind, and life at work
Claude ✓
FreemiumBuilding reliable, interpretable AI systems
DeepSeek ✓
FreeUnravel the mystery of AGI with curiosity
remio: Your Personal ChatGPT ✓
FreemiumGet Tailored Answer with Your Personal ChatGPT
Gemini ✓
FreemiumGemini: Google's most capable AI model yet