
Olostep ✓
Get clean web data for AI in seconds
Trial; then from $9/mo
Verdict
A quick read before you dig into the full page.
- Best if
- Get clean web data for AI in seconds
- Skip if
- Limited website compatibility
- Pick this when
- Cost-effective Web Scraping API
Considering FetchFox instead? Compare side by side
Overview

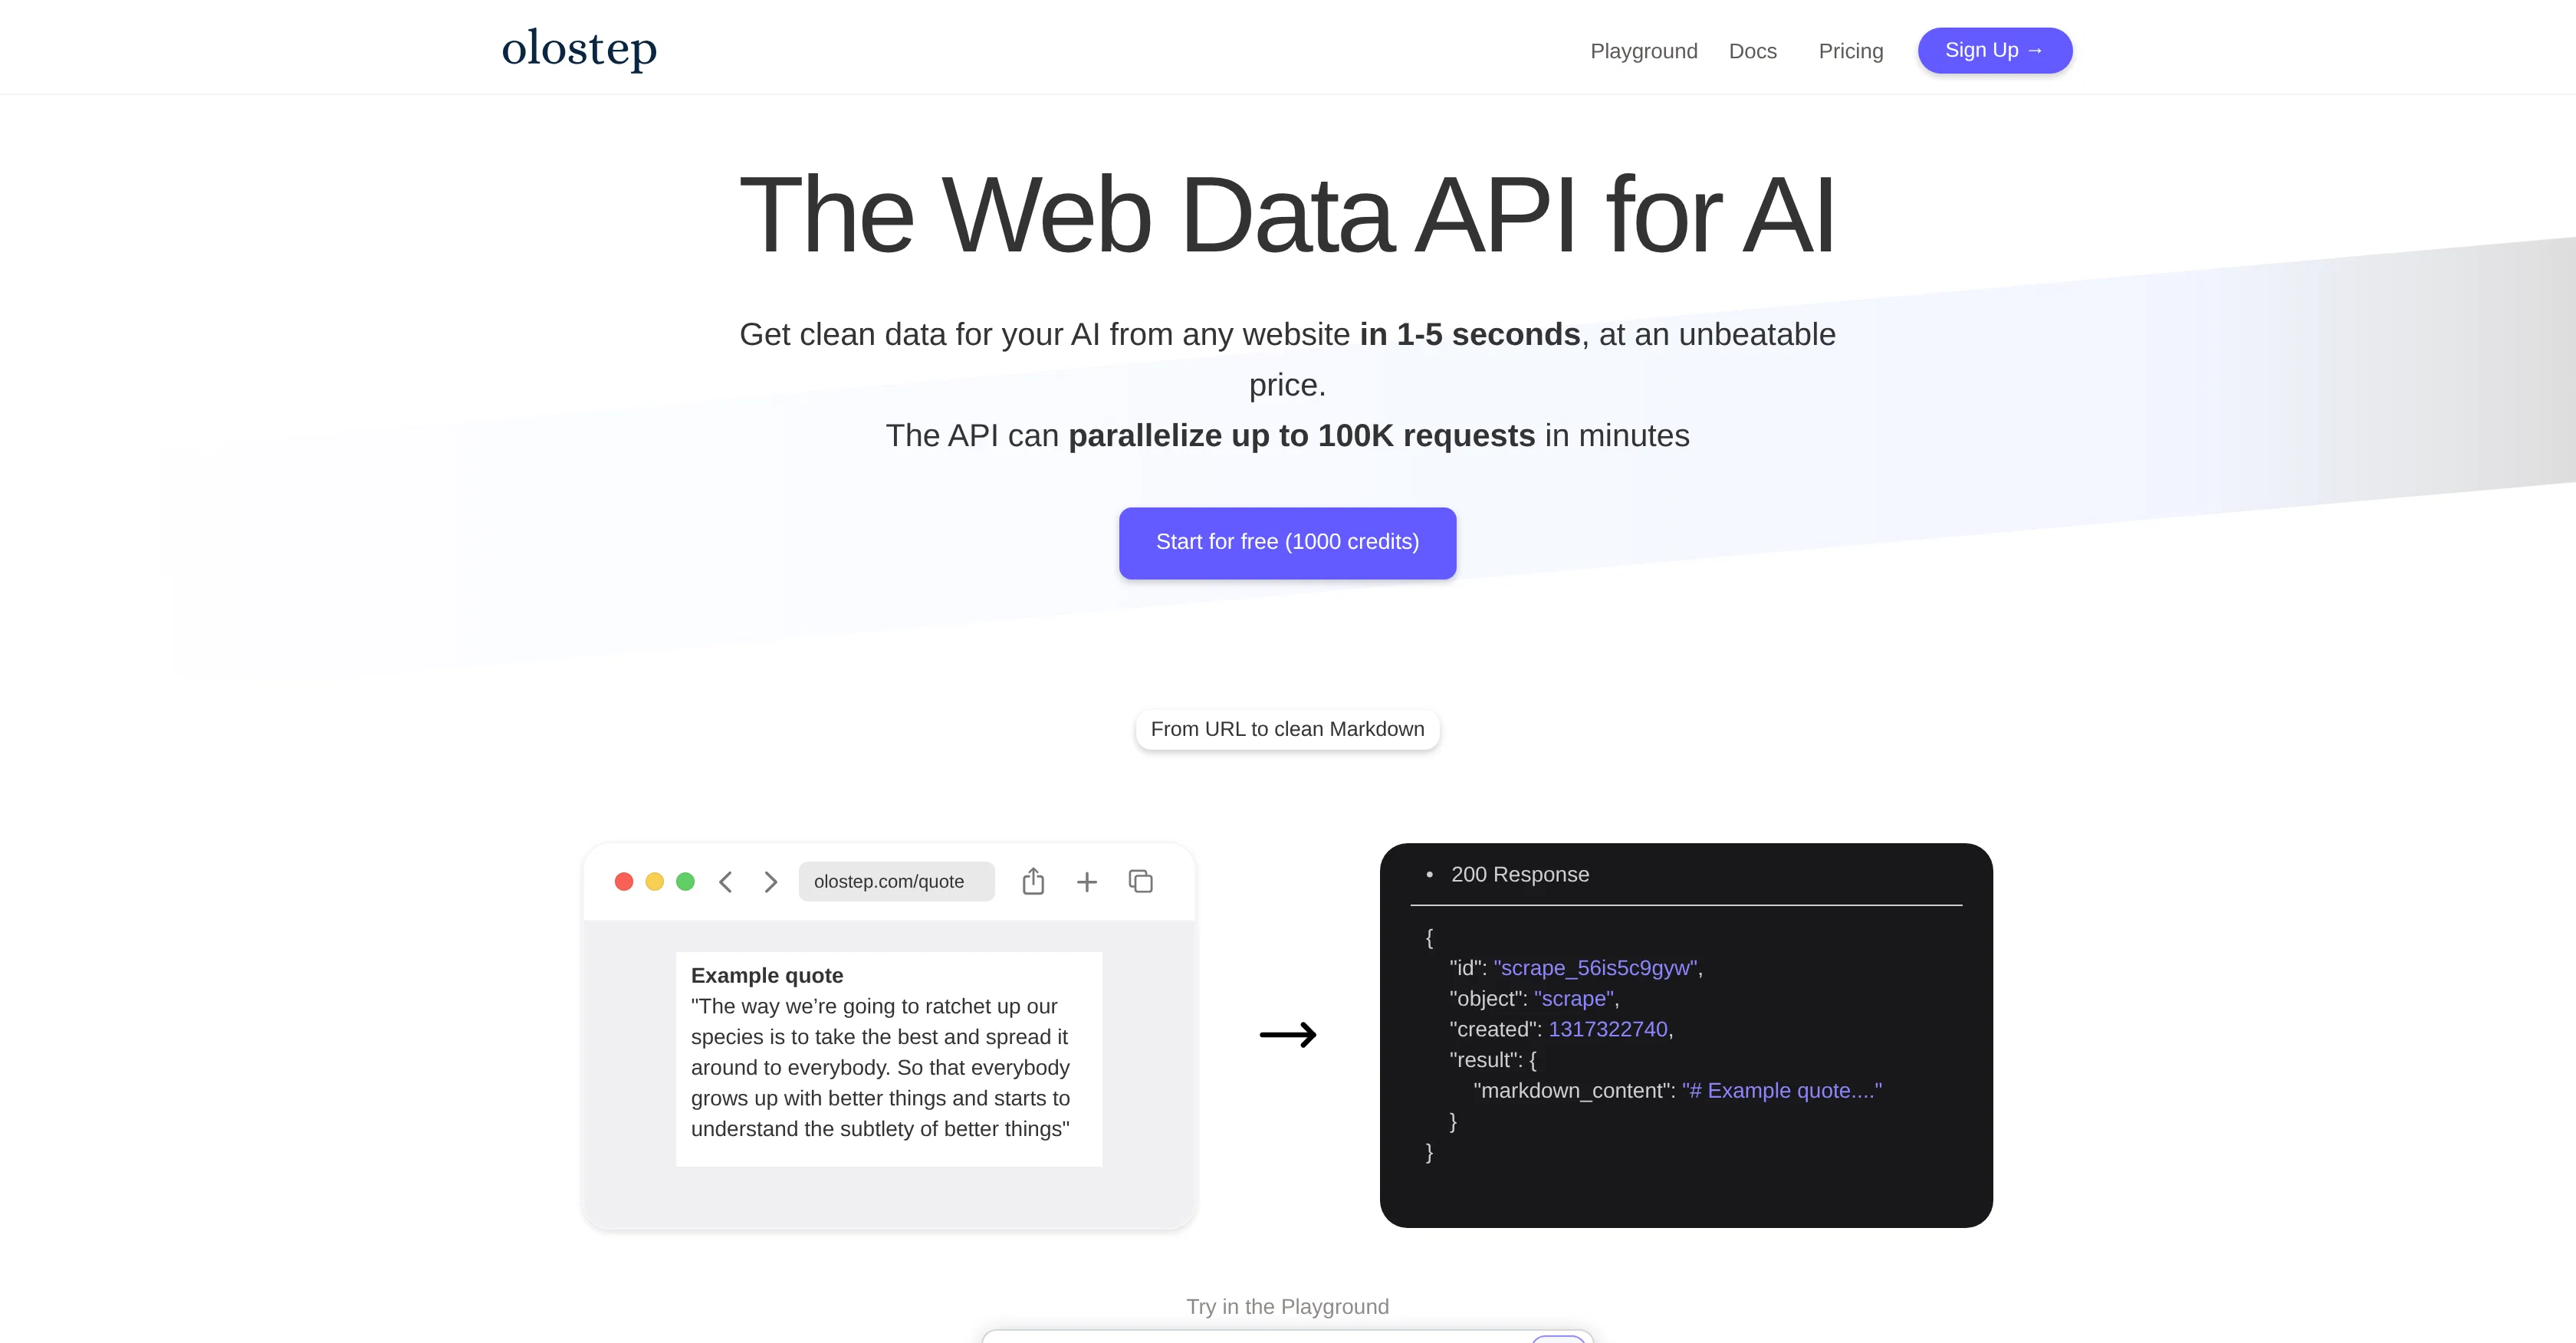
It is ideal for obtaining clean data for AI applications in the format they want (html, markdown, raw pdf, text ot structured JSON in the schema user prefer)
Olostep is considered the best Web Scraping API by some of the fastest growing AI startups in the world.
You can try it for free with a 1000 successful scrapes. Then plans start from $9/month for 5000 scrapes/month.
Olostep also fosters customization and adaptability with ready-made Parsers to derive structured data from popular websites, such as Brave search results, Reddit, Instagram, Amazon products, Google Maps, and more.
Users can also build their own parsers to make any website into an API and extract the data they want
- Build Custom Research Agents
Access & connections
Where you can use Olostep, and what it plugs into.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Input
- API
- Text
Output
- Tabular
- API
- Text
Highlights
- Agents
- MCP
- Local
- Use code TAAFT
- 10% OFF
Supported features
- Agents
- MCP
- Runs Locally
- Crawling & Scrapping
Pros & cons
Pros
- Cost-effective Web Scraping API
- Quick efficient data acquisition
- Developer-centric API
- Supports concurrent requests
- Customizable Parsers
- Supports Python and Node.js
- Clean data transformation
- High volume batch processing
Show 42 more
- Ready-made Parsers for popular sites
- Transforms data to Markdown format
- Community channels
- Handles specific URL scraping
- Website subpage crawling
- Scrapes Brave searches data
- Scrapes Reddit data
- Scrapes Instagram data
- Scrapes Amazon product data
- Scrapes Google Maps data
- Supports adaptation
- Affordable pricing
- Reliable service
- Fast data extraction
- Handles pdf parsing
- Multi-depth crawling
- Premium proxies usage
- Rotating proxies
- Solving CAPTCHAs capability
- JS executed requests
- Crawls without sitemap
- Batched executions
- Extracts structured JSON data
- Capable of JS rendering
- Copes with rate limits
- Fast scraping scale
- Offers custom discounts
- Can parse docx content
- Offers refunds policy
- Data enriched output
- Data markdown format results
- Return id for future retrievals
- Possible retry for failed requests
- Includes interactive actions before extraction
- Option for HTML result format
- Concurrent batch thread executions
- Supports multi-depth website crawling
- Offers free API testing keys
- Has fallback systems for failures
- Credits packs for extra flexibility
- Transparent Practices
- Pro-rated plan switch policy
Cons
- Invite code required
- Limited programming language support
- Markdown output only
- Limited website compatibility
- No mobile compatibility
- Fixed endpoint structure
- Pre-built Parsers limitation
- No real-time scraping
Show 2 more
- No on-premises version
- Access via API only
Compare alternatives
Similar tools in the catalog — with a clear reason to open each one.
FetchFox ✓
FreemiumScrape any data from any website, with AI
Why look Typically cheaper
Full comparison
Ultimate Web Scraper ✓
FreemiumExtract data instantly: Grab text, images, emails & links from any website
Free + from $60
Full comparison
Octoparse ✓
FreemiumThe next generation of AI web scraping platform.
Why look Offers a public API
Full comparison
Browse AI ✓
FreemiumExtract and monitor web data without code.
Why look Better fit for coding
Full comparison
WebscrapeAi ✓
Free TrialAutomate web data collection without coding.
Why look Better fit for coding
Full comparison
Releases 1
Imported reviews 1
I use Olostep to gather data from millions of e-commerce pages for my AI shopping assistant service and it's the most cost-effective and reliable product on the market
FAQ 12
What is Olostep and how does it work?
What makes Olostep cost-effective for web scraping?
How can Olostep be used to scrape data from a specific URL?
What is the process of crawling all subpages on a website using Olostep?
What is unique about the Parsers provided by Olostep?
How does Olostep handle high volume data scraping?
In what ways does Olostep support Python and Node.js?
How does Olostep ensure the quality of extracted data?
What kind of data can I get from popular websites like Amazon, Reddit, Instagram using Olostep?
What is the function of the 'Markdown' format in Olostep?
How reliable and efficient is Olostep for web scraping?
What is the procedure of customizing scraping in Olostep?
Related tools
Recommended

Notis ✓
Free TrialThe first WhatsApp assistant that runs on your ChatGPT and Claude subscriptions
Mind Map Wizard ✓
FreemiumGenerate mind maps with AI: free, no sign-up, no ads
HeyGen ✓
FreemiumCreate AI spokesperson videos from text

StarterPilot ✓
Free TrialValidate ideas, name your business, create logos, and build websites in minutes

bolt.new ✓
FreemiumBuild web apps with AI prompts
Redesignr Ai - website redesign and landing page bui... ✓
FreemiumRedesign And Build websites, docs, and blogs with AI in minutes