citrus search
Similarity-based search engine for scientific literature, using machine learning to find related papers.
Verdict
A quick read before you dig into the full page.
- Best if
- Similarity-based search engine for scientific literature, using machine learning to find related papers
- Pick this when
- Similarity-based search engine for scientific literature, using machine learning to find related papers
Overview
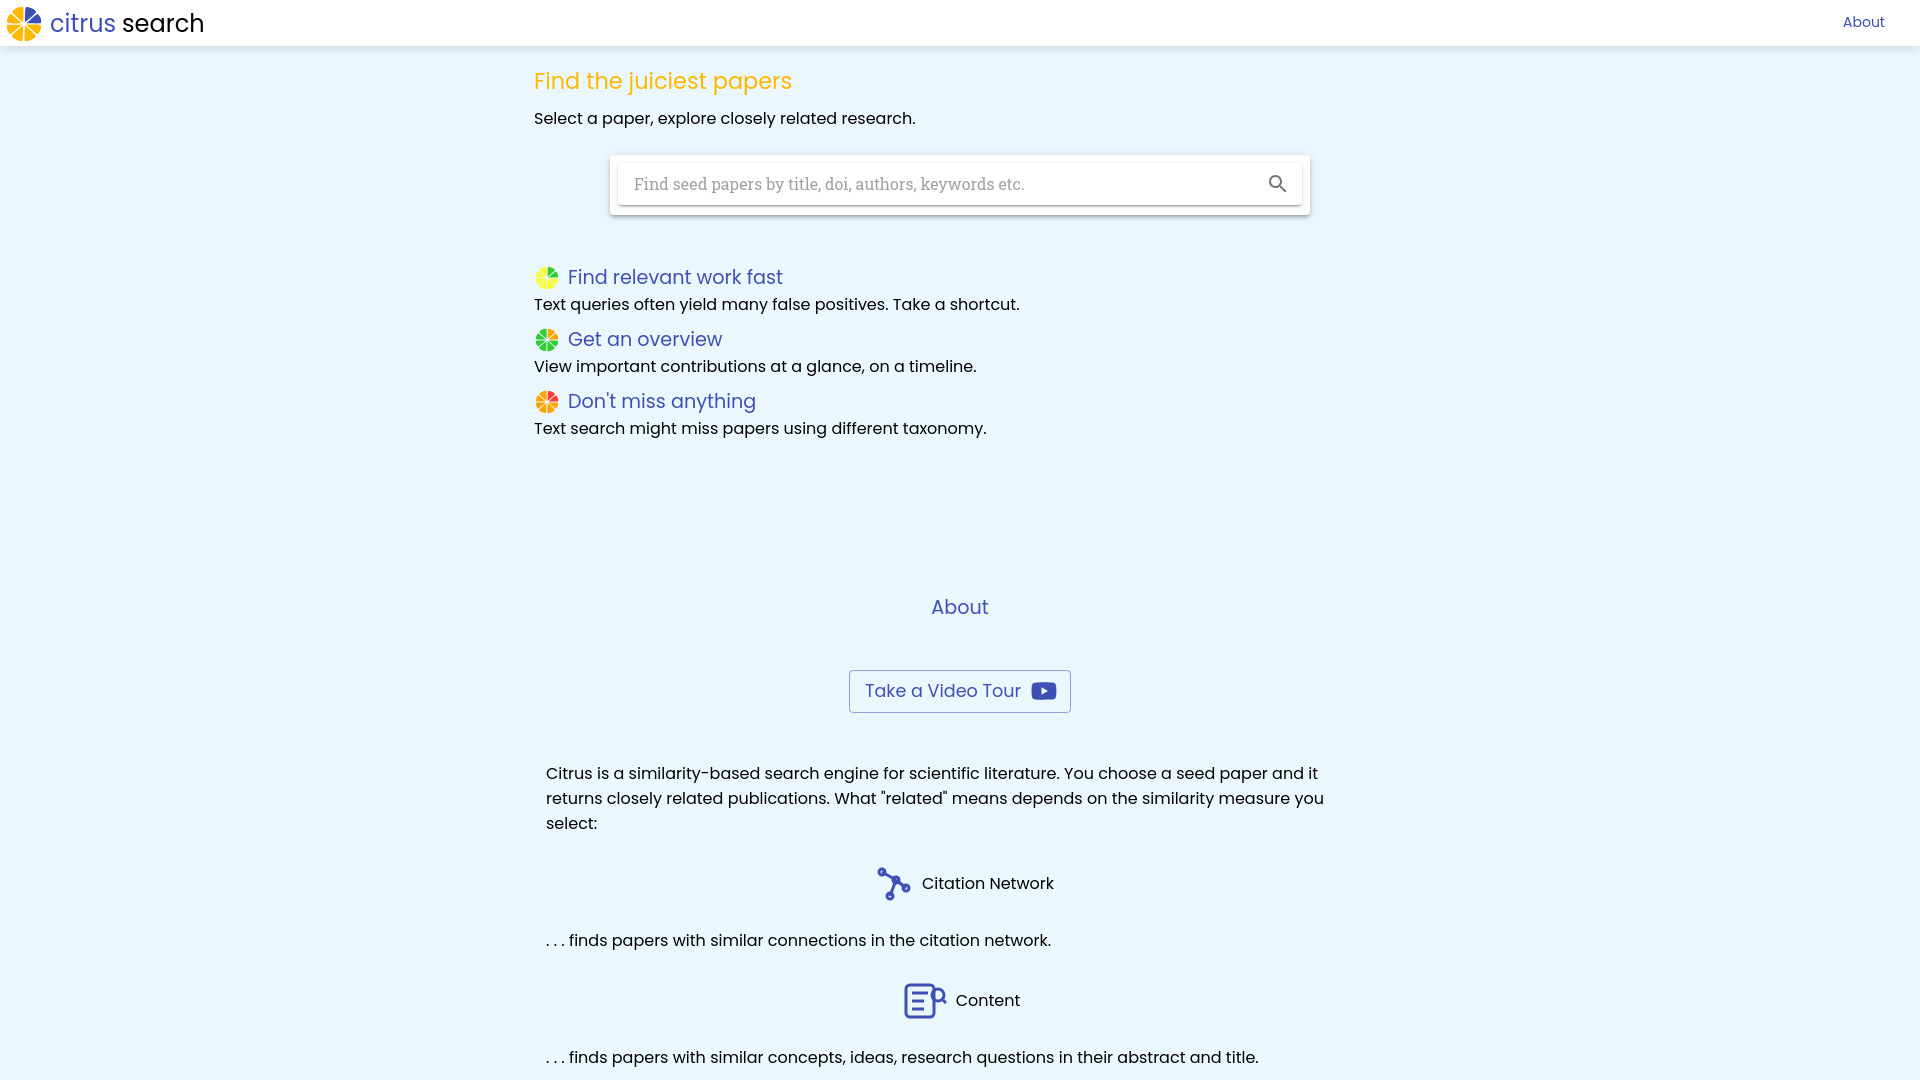
Citrus is a similarity-based search engine for scientific literature. You select a paper, start the search, and jump right to the heart of your research domain. Get an overview of important contributions from seminal papers to the state of the art. Citrus helps you find relevant articles in a research field with a single search. It allows you to explore closely related research, find relevant work fast, view important contributions at a glance on a timeline, and avoid missing papers using different taxonomy. Behind the scenes, the similarity of papers is computed using graph and text-based machine-learning techniques. Citrus indexes data provided by Semantic Scholar's Open Research Corpus, which spans over 200 Million publications and around 2 Billion citations.
Access & connections
Where you can use citrus search.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Highlights
- Similarity-based search for scientific literature
- Citation network analysis
- Content-based similarity analysis
- Timeline view of important contributions