AI inference 2026 Rank: #2749
Cerebras Inference ✓
AI inference up to 15x faster than GPUs.
Trial; then from $50/mo
Verdict
A quick read before you dig into the full page.
- Best if
- AI inference up to 15x faster than GPUs
- Skip if
- Limited to high-speed applications
- Pick this when
- Multiple times faster than GPUs
Considering Nebius Token Factory instead? Compare side by side
Overview
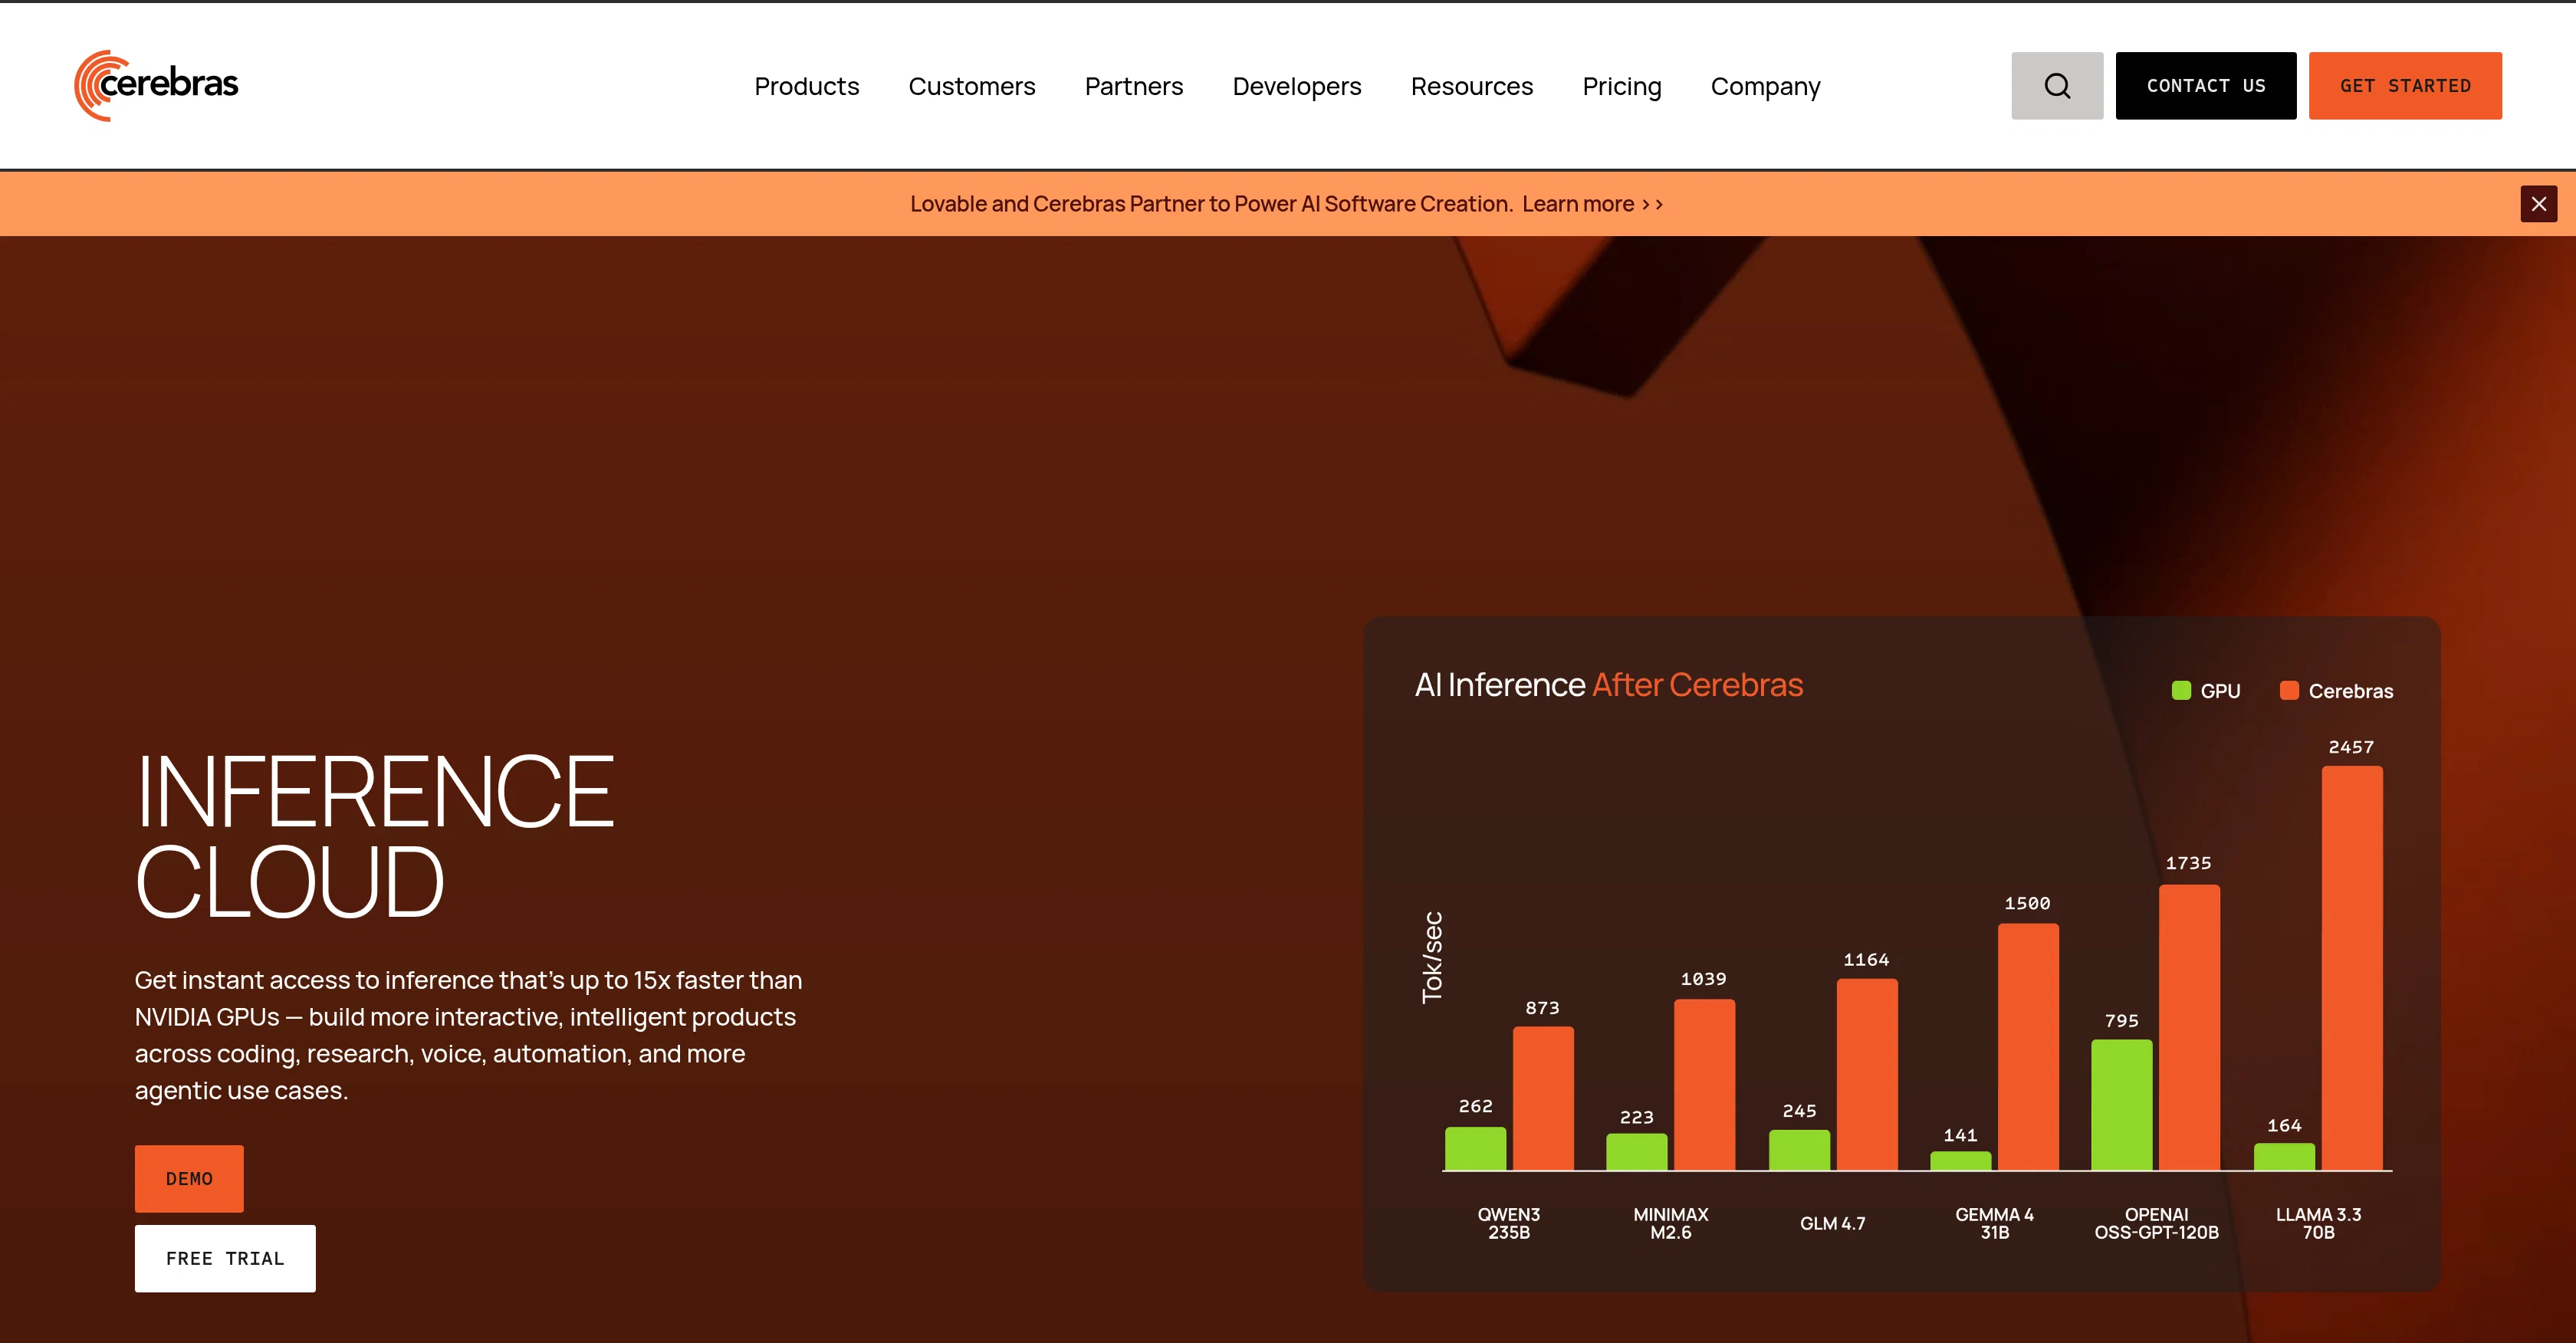
Inference by Cerebras is an AI model inference software designed for high-speed processing. The tool offers speedy inference, up to multiple times faster than NVIDIA GPUs, which facilitates the building of more interactive and intelligent products across various applications, including coding, research, voice, automation, and complex use cases.
Its rapid inference supports enhanced interactivity and allows more reasoning mechanism to deliver better quality output. The Cerebras Wafer-Scale Engine is purpose-built for ultra-fast AI, aimed at builders who wish to achieve extraordinary results.
This tool is regarded as economical, with the potential to significantly cut AI infrastructure costs while delivering faster inference compared to GPU clouds.
It supports leading AI models, allowing users to opt for the best model for specific use cases without worrying about slow GPU inference. Inference by Cerebras is OpenAI API compatible, hence easy for developers to start using with minimal code changes.
Access & connections
Where you can use Cerebras Inference.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Input
- API
Output
- API
Pros & cons
Pros
- Multiple times faster than GPUs
- Facilitates interactive product building
- Supports diverse applications: coding, research, voice
- Enhanced reasoning mechanisms
- Delivers high-quality output
- Faster inference than GPU clouds
- Allows minimal code changes
- Delivers extraordinary results
Show 12 more
- Suited for complex use cases
- Flexible, transparent pricing
- Offers free trial
- High-speed processing capability
- Developer-friendly
- Designed for high-volume applications
- Removes worries about slow GPU inference
- Leading price-performance
- Product-scale inference for high-volume apps
- Facilitates custom model weights
- Uptime guarantees
- Dedicated support
Cons
- Not beginner-friendly
- Not suitable for low-power devices
- Limited to high-speed applications
- Requires minimal code changes
- Pricing may be prohibitive for some
- No mentioned support for other languages
- No mentions of on-premise deployment
- Explicit reliance on Cerebras Hardware
Compare alternatives
Similar tools in the catalog — with a clear reason to open each one.
Nebius Token Factory ✓
Free TrialEnterprise-grade open-source AI inference at unlimited scale.
Why look Typically cheaper
Full comparison
JustSimpleChat ✓
Free TrialEvery AI model, one platform.
Why look Typically cheaper
Full comparison
AI Playground MCP & CLI by Picsart ✓
FreemiumGenerate images, video, and audio with 150+ AI models.
Why look Typically cheaper
Full comparison
SiliconFlow ✓
FreemiumOne platform for all AI inference needs.
Why look Typically cheaper
Full comparison
General Compute ✓
Free TrialWorld's fastest AI inference with purpose-built hardware.
Why look Typically cheaper
Full comparison
Run BiOS ✓
Free TrialOne API for the best AI models. Zero logs, upto 70% less
Why look Typically cheaper
Full comparisonReleases 1
FAQ 12
How much faster is Inference by Cerebras compared to NVIDIA GPUs?
What applications can benefit from Inference by Cerebras?
What is the Cerebras Wafer-Scale Engine?
How cost-effective is Inference by Cerebras?
Can the software reduce AI infrastructure costs?
Does Inference by Cerebras support leading AI models?
What AI models are compatible with Inference by Cerebras?
Is Inference by Cerebras OpenAI API compatible?
How easy is it for developers to migrate to Inference by Cerebras?
What does the claim 'up to 15x faster than GPUs' mean?
What is meant by more reasoning mechanism to deliver better quality output?
How can the tool facilitate building of interactive and intelligent products?
Related tools
Recommended
Baseten.co ✓
Free TrialDeploy and scale AI models at maximum speed.
Xirp by Spotify ✓
UnknownAI coding with institutional memory built in.
GetLogit ✓
FreemiumArtificial intelligence, available for everyone.
ChatGPT ✓
FreemiumAsk anything, create anything, and move from idea to action.

Notis ✓
Free TrialThe first WhatsApp assistant that runs on your ChatGPT and Claude subscriptions
freebeat AI ✓
FreemiumTurn Music & Ideas into Viral Videos In One Click