
Document analysis 2026 Rank: #992
Continua AI ✓
Deep research on your own files, every page read, every claim cited.
Verdict
A quick read before you dig into the full page.
- Best if
- Deep research on your own files, every page read, every claim cited
- Skip if
- English-optimized; limited multilingual support
- Pick this when
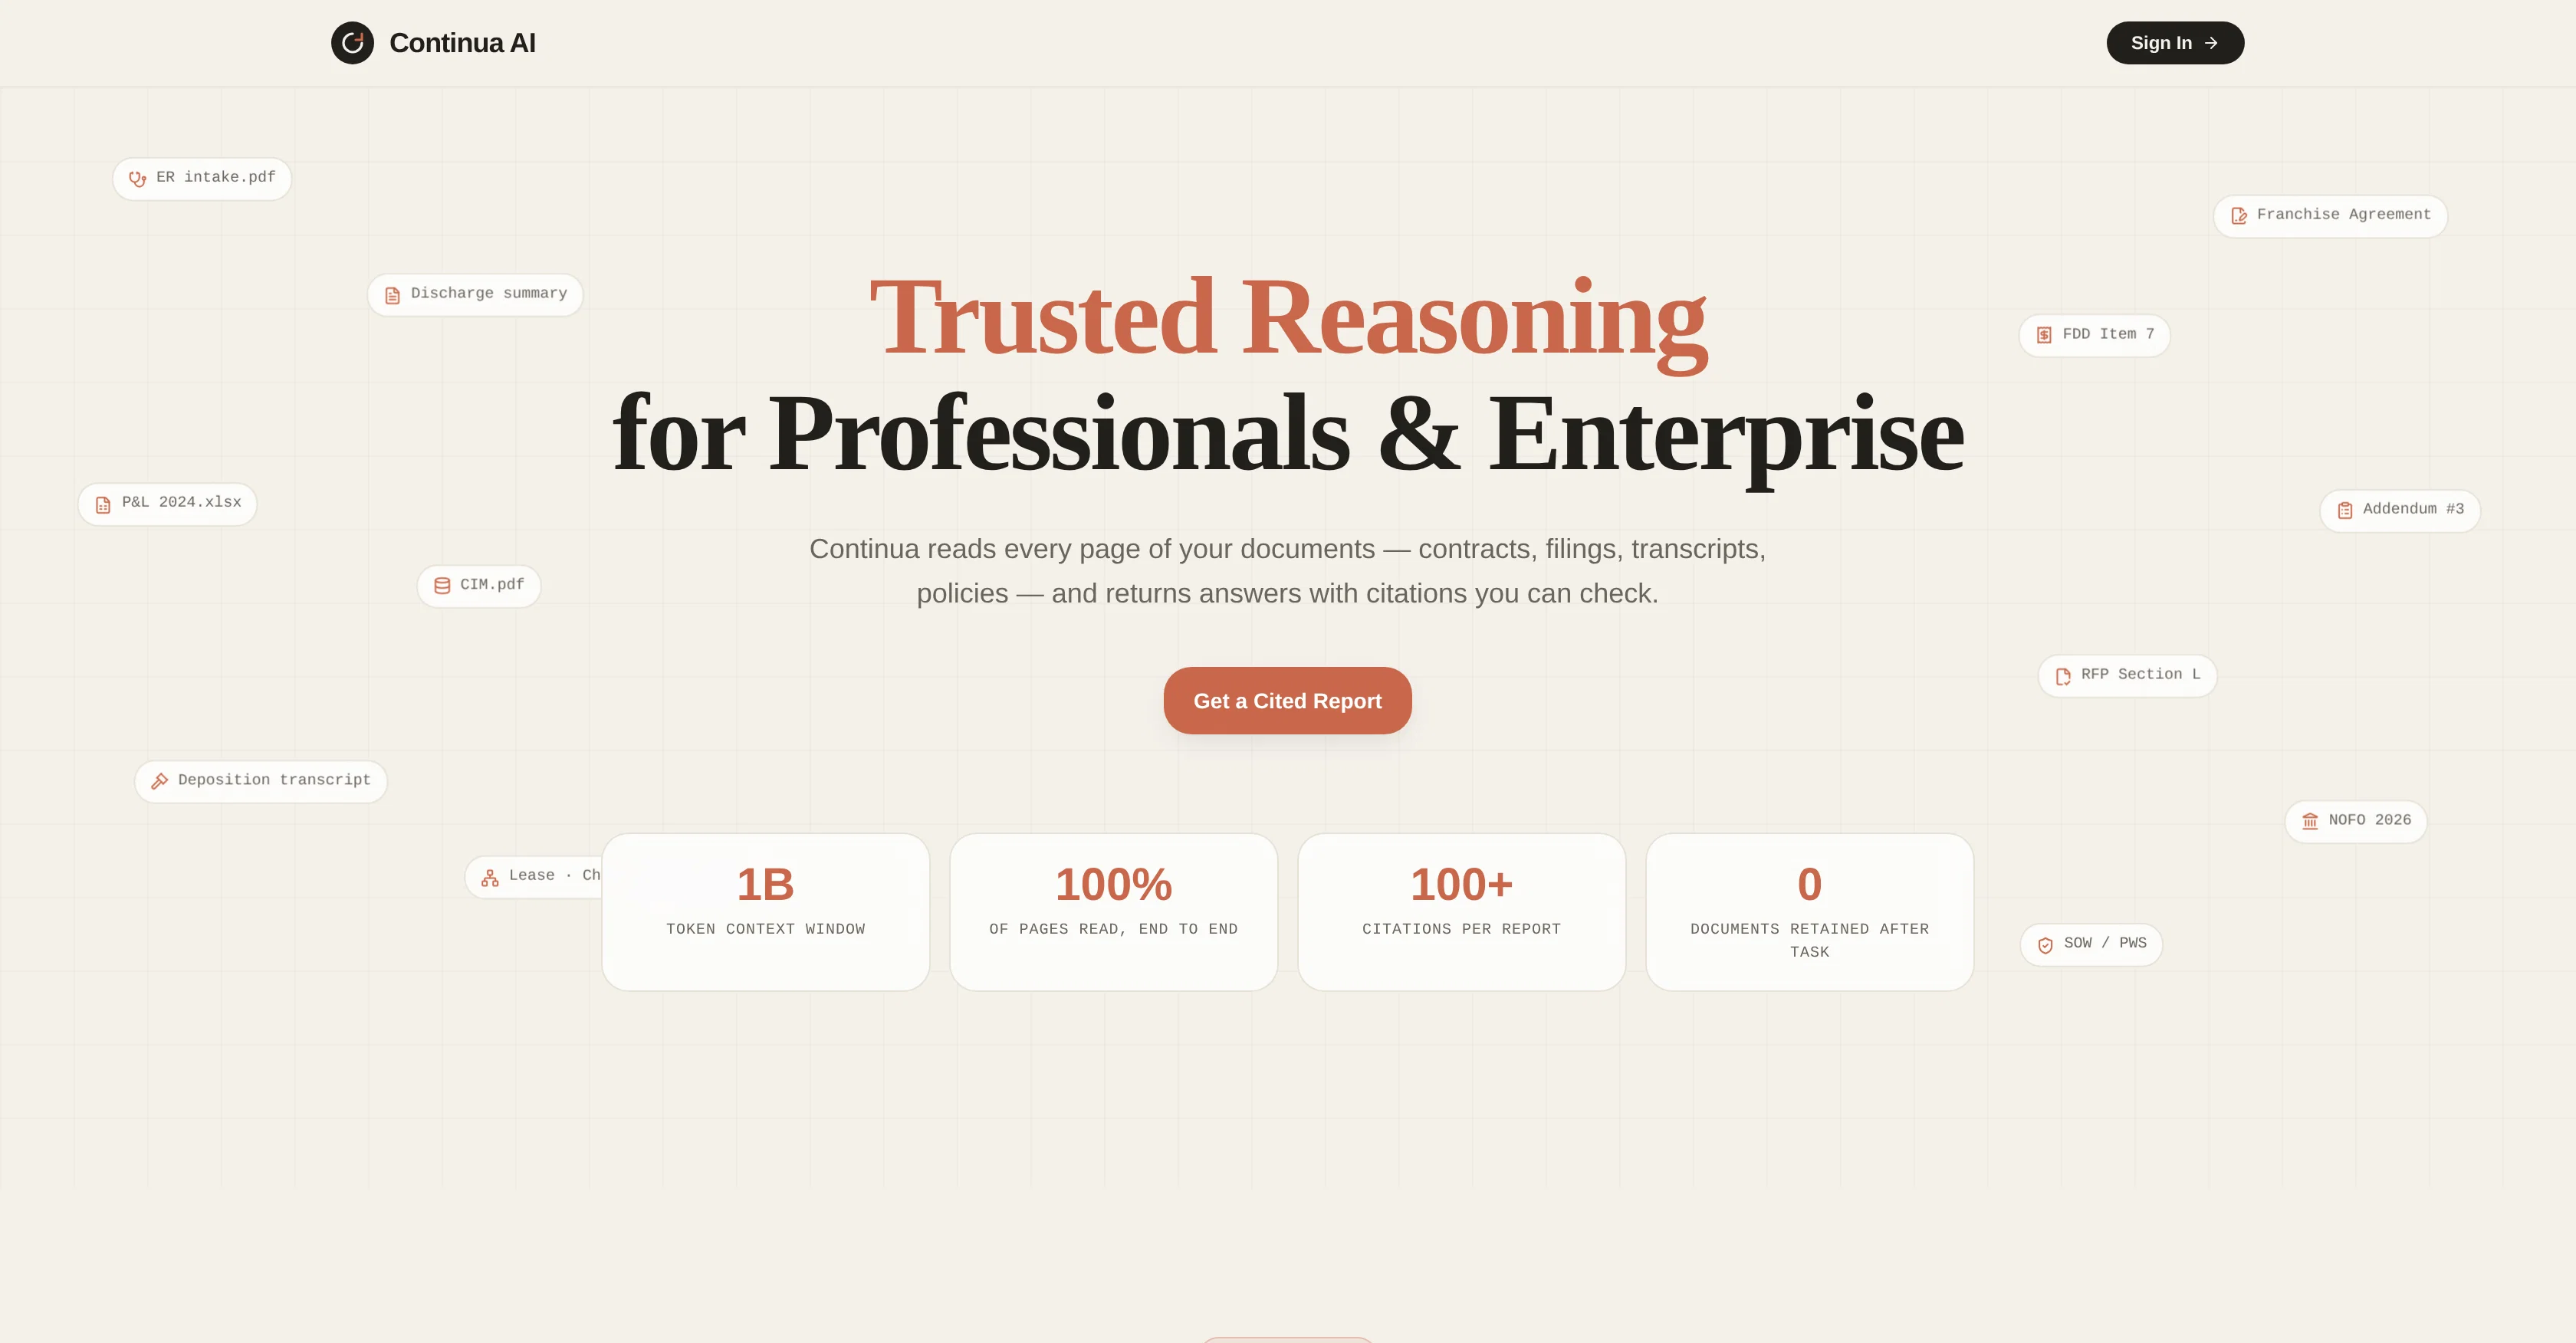
- 100% page coverage — no RAG, no sampling
Considering OdysseyGPT instead? Compare side by side
Overview

It reads every page — no RAG, no sampling, no retrieval lottery — and returns an investigation report where every claim cites its exact source page. Then the part nothing else does: it flags where your documents contradict each other. The pre-existing condition buried in provider #4's records. The amendment that quietly changed a requirement. The denial letter that conflicts with the policy's own endorsement. Every finding is inspectable — tagged cited, conflicted, duplicated, or unused — so you can audit the reasoning, not just trust it.
Used for medical chronologies, acquisition diligence, RFP compliance, insurance claim rebuttals, refund-fraud audits, and covenant reviews. Zero document retention after each task. First tasks free, no card required.
- 1b-token Context Window
- 100% Page Coverage (no Rag)
- Per-claim Citations & Lineage
- Cross-document Conflict Detection
- Inspectable Findings (cited / Conflicted / Duplicated / Unused)
- Zero Document Retention
- Pdf, Docx, Xlsx, Csv
- Exportable Reports
Access & connections
Where you can use Continua AI.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Input
- Tabular
- Text
Output
- Tabular
- Text
Highlights
- SOTA
Pros & cons
Pros
- 100% page coverage — no RAG, no sampling
- Page-level citation on every claim
- Flags contradictions between documents
- 1B-token context window
- Zero data retention after each task
- OCR for scanned PDFs
- Documents + spreadsheets in one investigation (PDF, DOCX, XLSX, CSV)
- Inspectable reasoning (audit every finding)
Show 2 more
- Editable reasoning — correct a step and re-run from that step, not from zero
- Follow-up research keeps lineage consistent — citations and findings stay stable
Cons
- Reports take minutes
- Premium models require credits or subscription
- No mobile application
- English-optimized; limited multilingual support
- Not open-source
- No native API yet
Compare alternatives
Similar tools in the catalog — with a clear reason to open each one.

OdysseyGPT ✓
Free TrialTransform documents into interactive knowledge bases using advanced AI.
Free + from $10/mo
Full comparison
FileAI ✓
FreemiumAutomate document analysis and data extraction
Free + from $9.90/mo
Full comparison
Deep Dive Research Assistant ✓
FreemiumAI-powered research assistant for diverse content analysis.
Why look Better for writing
Full comparison
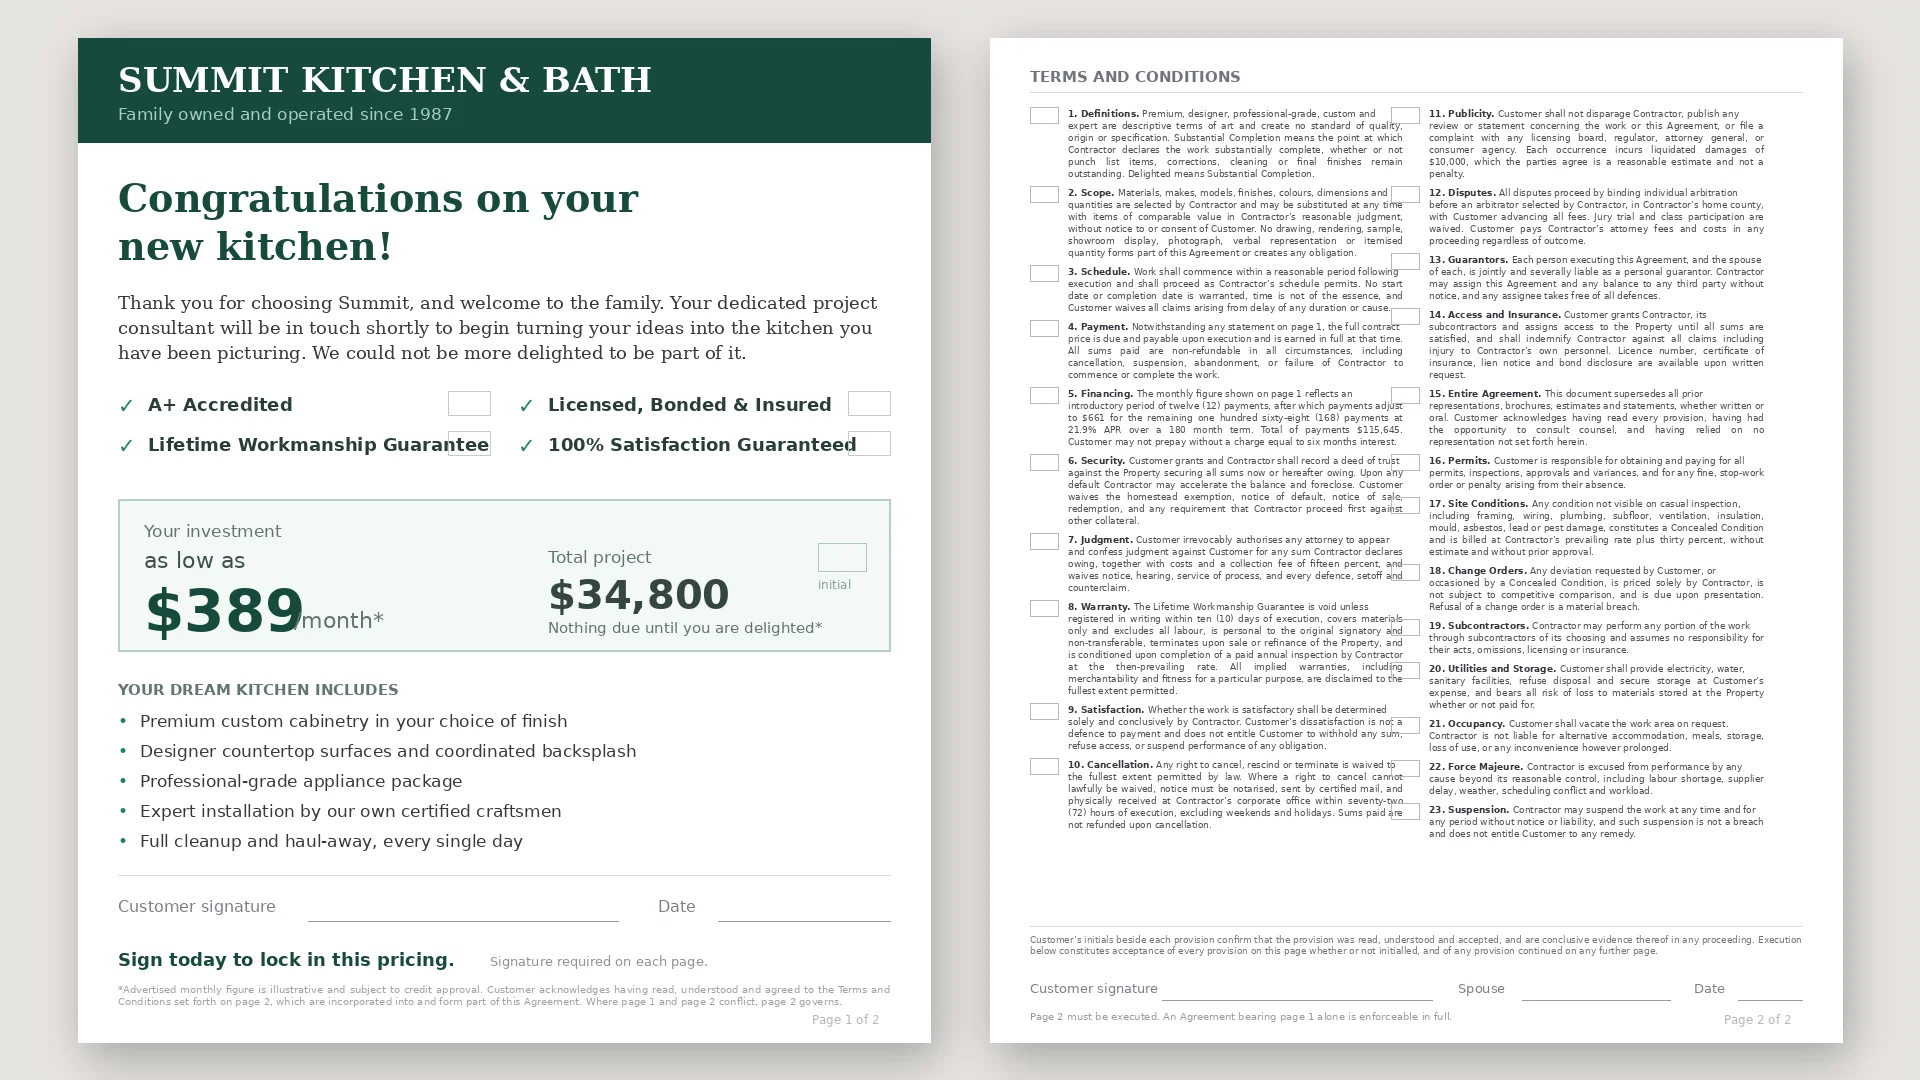
WhatsTheCatch ✓
FreeAI that spots risks before you sign.
Why look Fully free option
Full comparisonReleases 1
Imported reviews 1
We built Continua because every "chat with PDF" tool we tried failed the same way: retrieval grabs a few chunks, answers confidently, and misses the qualifier on page 1,847. In high-stakes documents that's not an inconvenience — it's a lost case, a bad acquisition, a rejected claim.
So we went the opposite direction: no RAG at all. Continua reads 100% of every page (up to 1B tokens in one task), returns a report where every claim cites its exact page, and — the part we're proudest of — flags where your documents contradict each other. Every finding is inspectable and tagged: cited, conflicted, duplicated, or unused.
Where it shines today: medical chronologies, acquisition diligence, RFP compliance, insurance claim rebuttals. Where it's still rough: reports take minutes (we read everything — that's the cost), no API yet, English-optimized.
We're in public beta and genuinely want hard feedback — bring your nastiest document pile and tell us where it breaks. I'll answer every comment here.
FAQ 12
What industries can Continua AI be applied to?
What can Continua AI's 'enterprise context intelligence' do?
What are Continua AI's six lenses?
What sort of documents can Continua AI analyze?
How does Continua AI handle data privacy?
What is Continua AI's approach to citation tracking?
How does Continua AI handle large scale documents?
Can Continua AI be used for high stakes decision making?
What does Continua AI offer for medical chronology?
How does Continua AI assist in federal RFP compliance?
How does Continua AI aid in acquisition diligence?
What are the use cases for Continua AI's insurance claim rebuttal?
Related tools
Recommended
Face ID Search.com ✓
PaidFind anyone by photo in 60 seconds.
JustVibe ✓
FreeThe search engine for doing, with instant apps built for you
Automateed ✓
Free TrialCreate eBooks effortlessly with Automateed, the AI-powered writing tool.
NotebookLM ✓
FreemiumAI-powered note-taking and research assistant
DeepSeek ✓
FreeUnravel the mystery of AGI with curiosity

StarterPilot ✓
Free TrialValidate ideas, name your business, create logos, and build websites in minutes