What is ChatTTS?
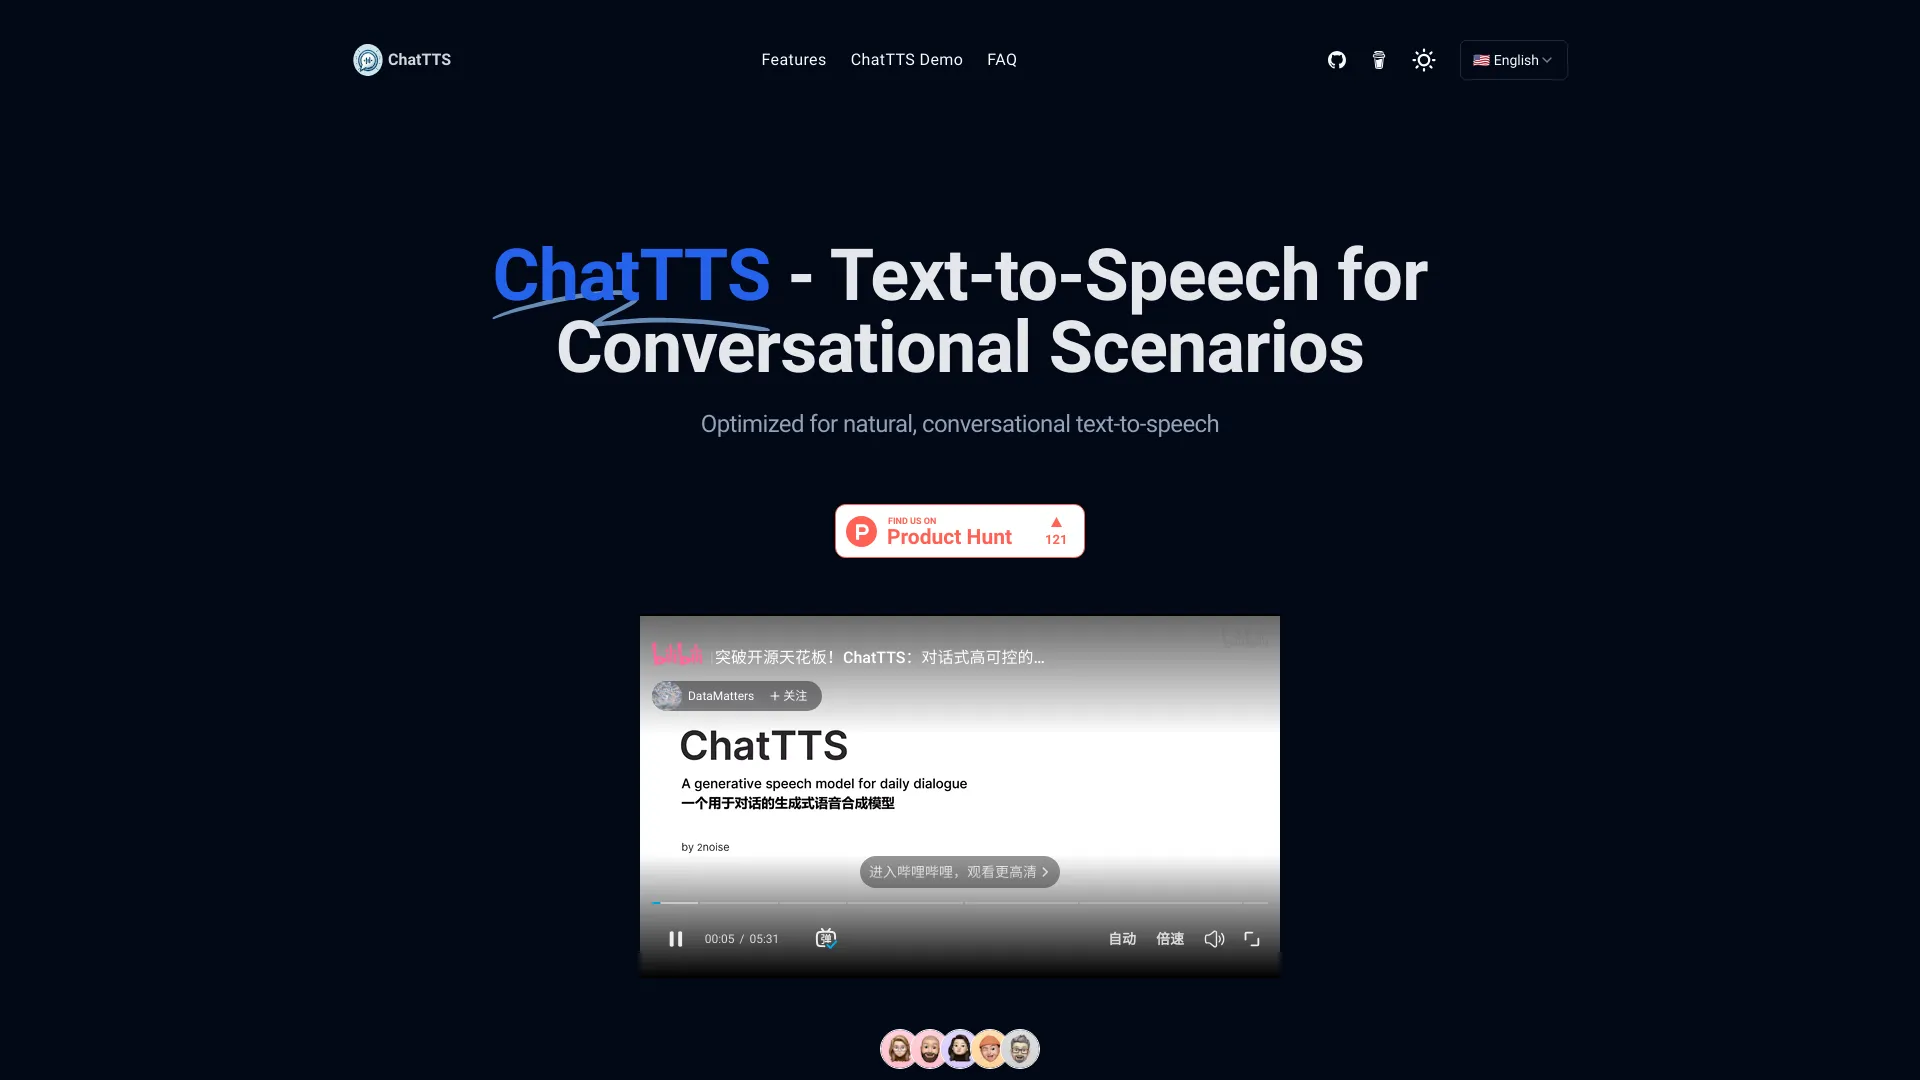
ChatTTS is a voice generation model designed for conversational scenarios. It is ideal for applications such as dialogue tasks for large language model assistants, as well as conversational audio and video introductions. The model supports both Chinese and English, demonstrating high quality and naturalness in speech synthesis. This level of performance is achieved through training on approximately 100,000 hours of Chinese and English data. The project team plans to open-source a basic model trained with 40,000 hours of data, which will aid the academic and developer communities in further research and development.
How to use ChatTTS?
To use ChatTTS, download the code from GitHub, install the necessary dependencies (torch and ChatTTS), import the required libraries, initialize ChatTTS, prepare your text, generate speech using the infer method, and play the generated audio using the Audio class from IPython.display.
How can developers integrate ChatTTS into their applications?
Developers can integrate ChatTTS into their applications by using the provided API and SDKs. The integration process typically involves initializing the ChatTTS model, loading the pre-trained models, and calling the text-to-speech functions to generate audio from text. Detailed documentation and examples are available to guide developers through the integration process.
What can ChatTTS be used for?
ChatTTS can be used for various applications, including conversational tasks for large language model assistants, generating dialogue speech, video introductions, educational and training content speech synthesis, and any application or service requiring text-to-speech functionality.
How is ChatTTS trained?
ChatTTS is trained on approximately 100,000 hours of Chinese and English data. This extensive dataset helps the model learn to produce high-quality, natural speech. Additionally, the project team plans to open-source a base model trained on 40,000 hours of data to facilitate further research and development within the academic and developer.
Does ChatTTS support multiple languages?
Yes, ChatTTS supports both Chinese and English. By training on a large dataset in these languages, ChatTTS can generate high-quality speech synthesis in both Chinese and English, making it suitable for use in multilingual environments and meeting the needs of diverse language users.
What makes ChatTTS unique compared to other text-to-speech models?
ChatTTS is specifically optimized for dialogue scenarios, making it particularly effective for conversational applications. It supports both Chinese and English and is trained on a vast dataset to ensure high-quality, natural speech synthesis. Additionally, the plan to open-source a base model trained on 40,000 hours of data sets it apart, promoting further research and development in the field.
What kind of data is used to train ChatTTS?
ChatTTS is trained on approximately 100,000 hours of Chinese and English data. This dataset includes a wide variety of spoken content to help the model learn to generate natural and high-quality speech. The diversity and volume of the training data ensure that ChatTTS can handle various speech synthesis tasks effectively.
Is there an open-source version of ChatTTS available for developers and researchers?
Yes, the project team plans to release an open-source version of ChatTTS that is trained on 40,000 hours of data. This open-source model will enable developers and researchers to explore and expand upon ChatTTS’s capabilities, fostering innovation and development in the text-to-speech domain.
How does ChatTTS ensure the naturalness of synthesized speech?
ChatTTS ensures the naturalness of synthesized speech by training on a large and diverse dataset of approximately 100,000 hours of Chinese and English speech. This extensive training allows the model to capture various speech patterns, intonations, and nuances, resulting in high-quality, natural-sounding speech. Advanced machine learning techniques are also employed to fine-tune the model for better performance in conversational scenarios.
Can ChatTTS be customized for specific applications or voices?
Yes, ChatTTS can be customized for specific applications or voices. Developers can fine-tune the model using their own datasets to better suit particular use cases or to develop unique voice profiles. This customization allows for greater flexibility and adaptability in different application contexts.
What platforms and environments is ChatTTS compatible with?
ChatTTS is designed to be compatible with various platforms and environments. It can be integrated into web applications, mobile apps, desktop software, and embedded systems. The provided SDKs and APIs support multiple programming languages, ensuring that developers can easily implement ChatTTS across different platforms.