

Repository
EnvRL
EnvRL: Learn from Environment Dynamics in Agentic Reinforcement Learning Learning environment dynamics as auxiliary supervision for long-horizon LLM agents. This repository impleme · License unknown · Install via pip · Maintenance unmaintained
- License
- Unknown
- Method
- ALFWorld Success
- GRPO
- 72.8
- EnvRL-GRPO
- 77.4
Specs
- MethodALFWorld Success
- GRPO72.8
- EnvRL-GRPO77.4
- GiGPO86.7
- EnvRL-GiGPO91.8
- MethodALFWorld Success
- GRPO77.6
- EnvRL-GRPO80.4
- GiGPO90.8
- EnvRL-GiGPO94.5
README
<h1 align="center">
EnvRL: Learn from Environment Dynamics in Agentic Reinforcement Learning
</h1>
Learning environment dynamics as auxiliary supervision for long-horizon LLM agents.
This repository implements EnvRL, a lightweight framework that improves agentic reinforcement learning by reusing rollout transitions as environment-dynamics supervision. The code is built on verl-agent, with active support for ALFWorld and WebShop.
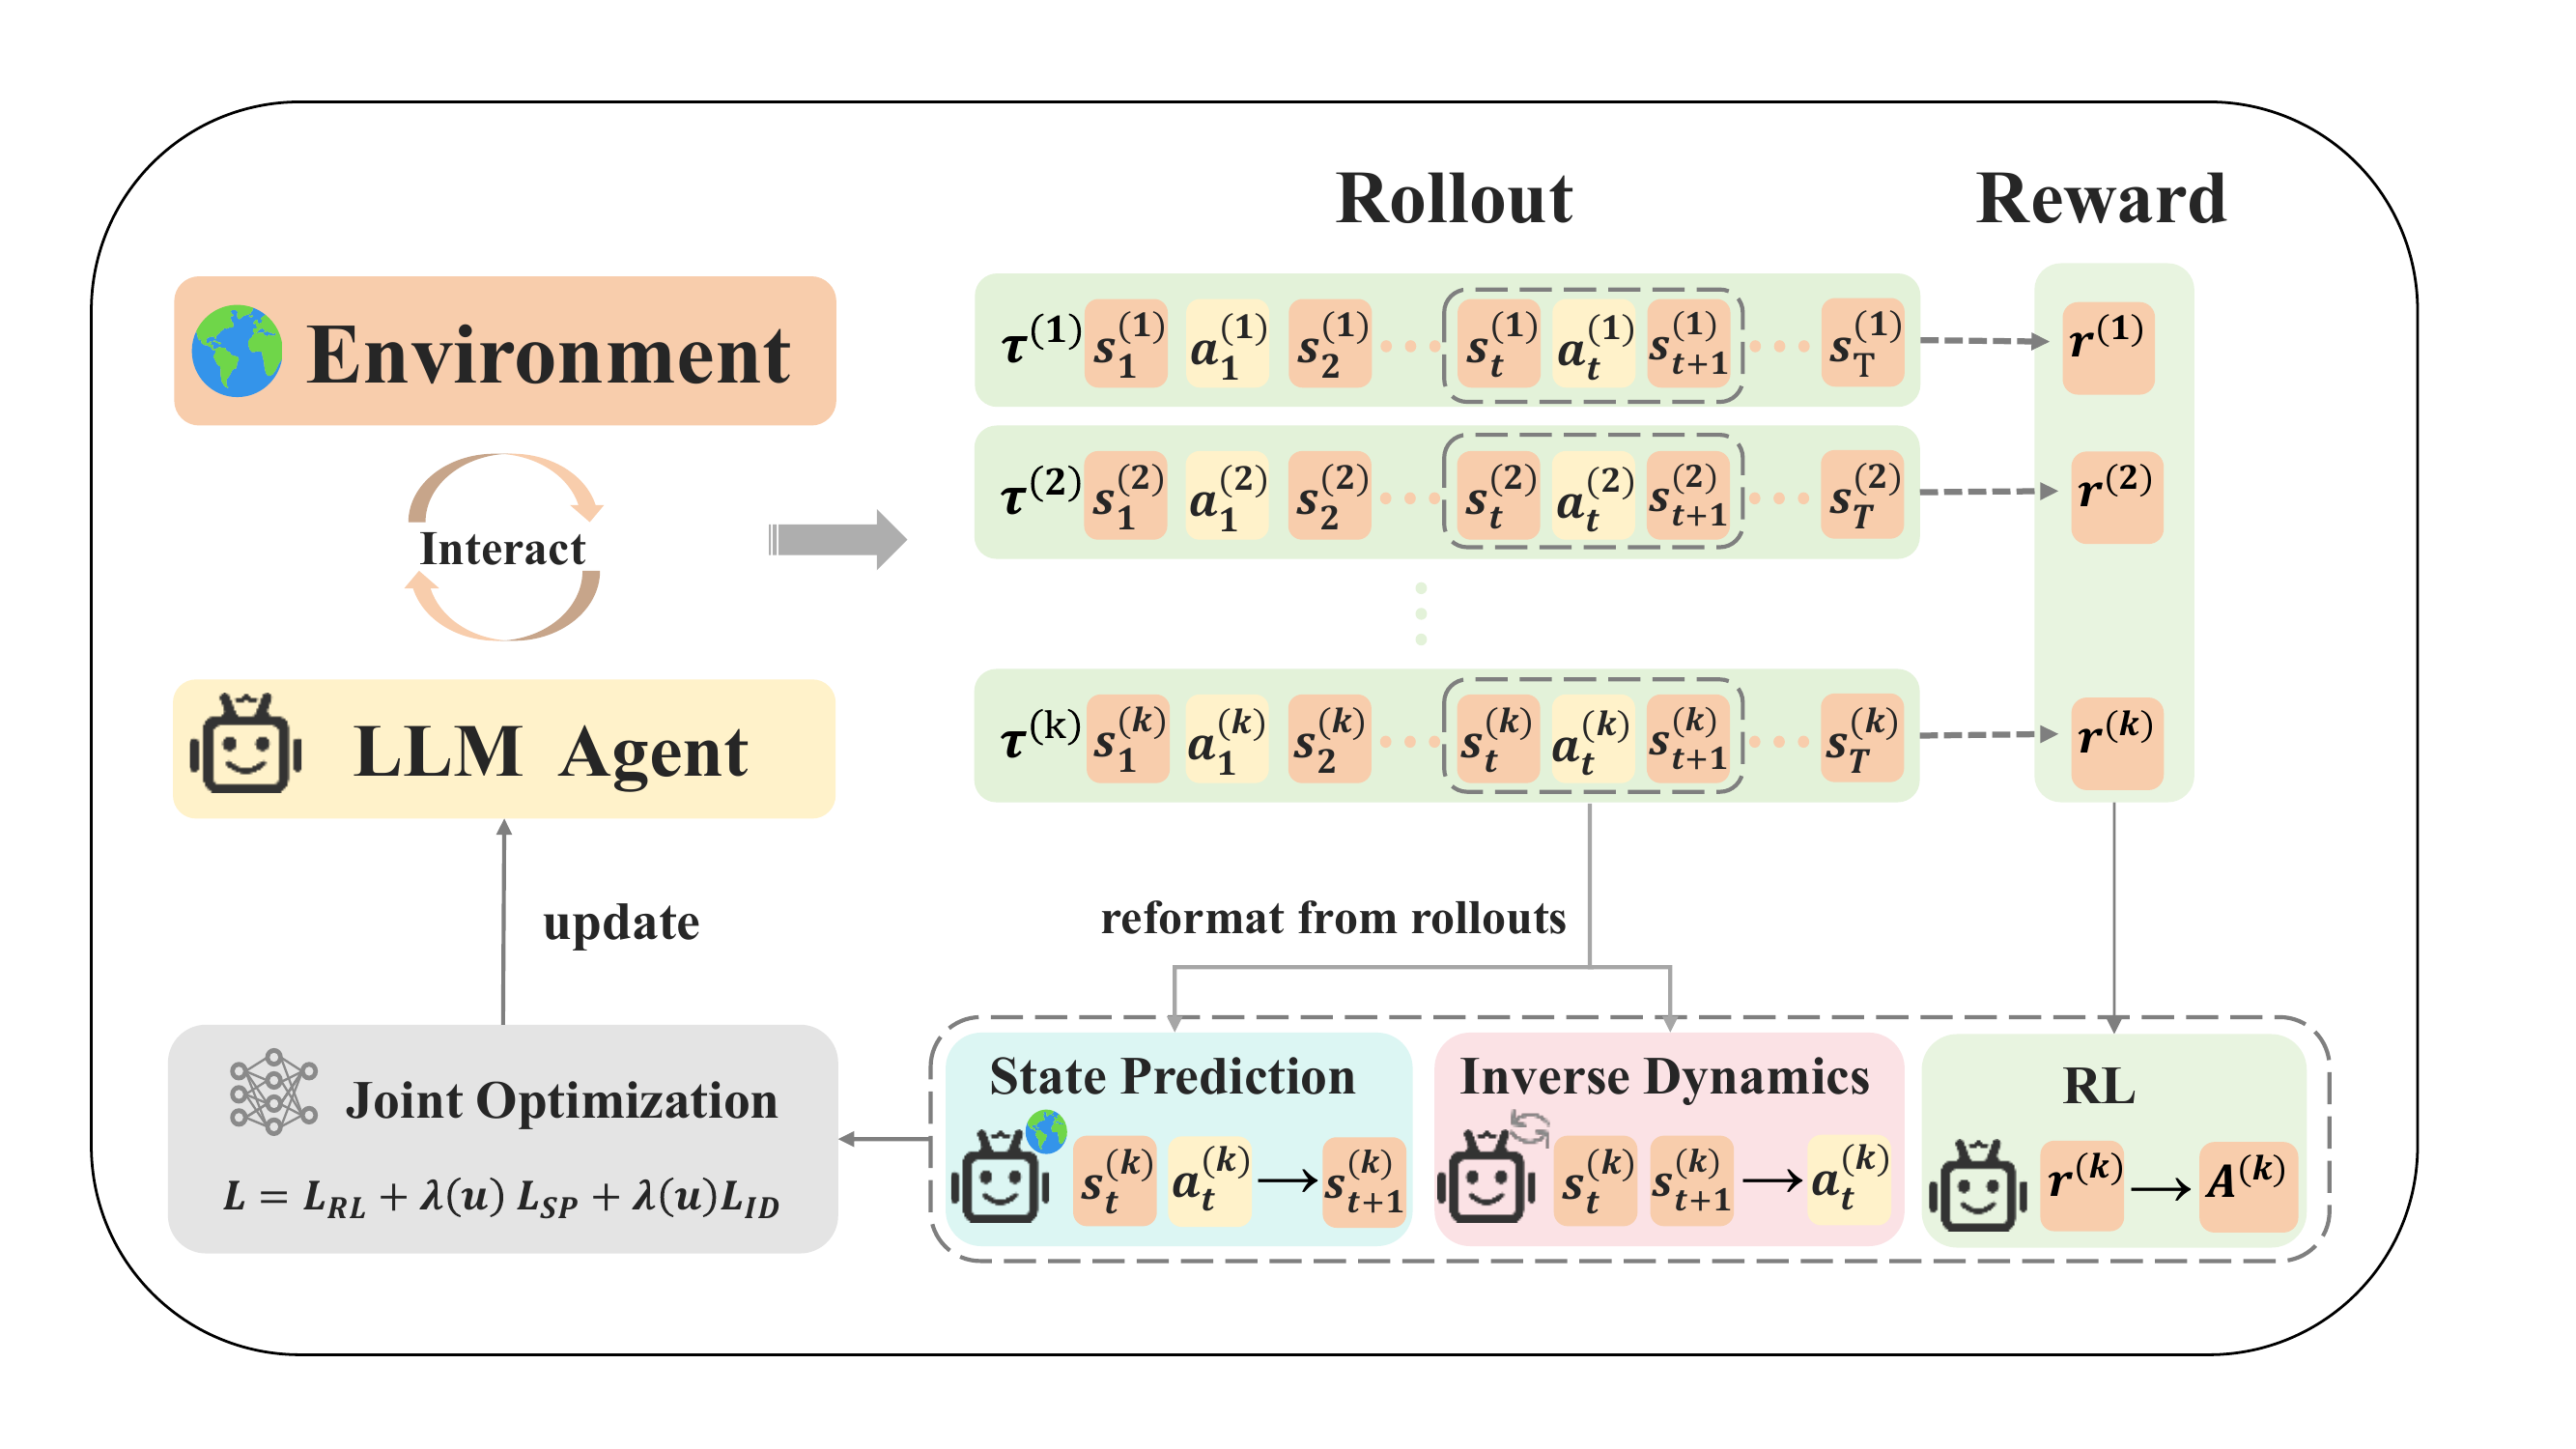
Overview
Outcome-reward RL methods such as GRPO mainly learn from sparse trajectory-level success signals. EnvRL uses the richer interaction experience inside each rollout. Given a transition (history, obs_t, action_t, obs_{t+1}), it adds two auxiliary objectives to the actor update:
- State Prediction: predict the next observation from the history, current observation, and action.
- Inverse Dynamics: infer the action that caused a transition from the history, current observation and the next observation.
These losses are optimized jointly with the primary RL objective and reuse rollout data generated during training. EnvRL also applies a decay schedule to the auxiliary losses: environment-dynamics supervision is stronger early in training, then gradually decays so optimization shifts toward the primary RL objective.
Results
On Qwen2.5-1.5B-Instruct, EnvRL improves both GRPO and GiGPO on ALFWorld and WebShop:
| Method | ALFWorld Success | WebShop Success |
|---|---|---|
| GRPO | 72.8 | 56.8 |
| EnvRL-GRPO | 77.4 | 67.0 |
| GiGPO | 86.7 | 67.4 |
| EnvRL-GiGPO | 91.8 | 74.2 |
On Qwen2.5-7B-Instruct, EnvRL keeps the same trend:
| Method | ALFWorld Success | WebShop Success |
|---|---|---|
| GRPO | 77.6 | 66.1 |
| EnvRL-GRPO | 80.4 | 68.6 |
| GiGPO | 90.8 | 75.2 |
| EnvRL-GiGPO | 94.5 | 76.3 |
Quick Start
Installation
We recommend separate uv environments for ALFWorld and WebShop because WebShop works best with Python 3.10.
git clone <this-repo>
cd verl-agent

curl -LsSf https://astral.sh/uv/install.sh | sh
uv python install 3.12 3.10
ALFWorld:
uv venv .venv-alf --python 3.12
source .venv-alf/bin/activate

uv pip install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
uv pip install flash-attn==2.7.4.post1 --no-build-isolation
uv pip install -e .
uv pip install vllm==0.8.5

uv pip install gymnasium==0.29.1 stable-baselines3==2.6.0 alfworld

alfworld-download -f
export ALFWORLD_DATA=/path/to/alfworld
WebShop:
uv venv .venv-web --python 3.10
source .venv-web/bin/activate

cd agent_system/environments/env_package/webshop/webshop
bash setup.sh -d all
cd -

uv pip install torch==2.6.0 --index-url https://download.pytorch.org/whl/cu124
uv pip install flash-attn==2.7.4.post1 --no-build-isolation
uv pip install -e .
uv pip install vllm==0.8.2
Data Preparation
For ALFWorld and WebShop, data preparation only creates lightweight parquet files that mark the modality as text. The actual agent inputs, observations, rewards, and available actions come from environment interaction during rollout.
The training scripts run this step automatically. To prepare the files manually:
python -m examples.data_preprocess.prepare \
  --mode text \
  --train_data_size 16 \
  --val_data_size 128 \
  --local_dir data/alfworld

python -m examples.data_preprocess.prepare \
  --mode text \
  --train_data_size 16 \
  --val_data_size 128 \
  --local_dir data/webshop
This creates:
data/<env>/text/train.parquet
data/<env>/text/test.parquet
Training
The training scripts contain the default hyperparameters. By default, they use Qwen/Qwen2.5-1.5B-Instruct.
ALFWorld:
source .venv-alf/bin/activate
export ALFWORLD_DATA=/path/to/alfworld
bash exp/alfworld/run_grpo.sh
WebShop:
source .venv-web/bin/activate
bash exp/webshop/run_grpo.sh
Use the GiGPO variants by replacing run_grpo.sh with run_gigpo.sh.
Evaluation
Evaluation scripts repeat validation 3 times by default. Pass a second argument only when you want a different number of repeats.
bash exp/alfworld/test_repeat.sh /path/to/checkpoint/huggingface
bash exp/webshop/test_repeat.sh /path/to/checkpoint/huggingface
Project Structure
exp/
├── main.py              # EnvRL training entrypoint
├── trainer.py           # trainer integration
├── rollout.py           # rollout metadata and next-observation storage
├── workers.py           # auxiliary State Prediction and Inverse Dynamics losses
├── aux_loss_utils.py    # auxiliary prompt builders
├── envs.py              # ALFWorld/WebShop environment builders
├── alfworld/            # ALFWorld scripts
└── webshop/             # WebShop scripts

agent_system/            # environment managers, prompts, memory, reward manager
gigpo/                   # GiGPO advantage computation
verl/                    # inherited veRL core
assets/                  # README figures
legacy/                  # archived exploratory code and generated artifacts
Citation
@misc{wang2026envrllearnenvironmentdynamics,
      title={EnvRL: Learn from Environment Dynamics in Agentic Reinforcement Learning},
      author={Zhitong Wang and Songze Li and Hao Peng and Shuzheng Si and Yi Wang and Maosong Sun and Juanzi Li},
      year={2026},
      eprint={2606.17680},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2606.17680},
}
Acknowledgements
This project builds on verl-agent, veRL, ALFWorld, and WebShop.