

Repository
Auto-claude-code-research-in-sleep
Auto-claude-code-research-in-sleep (ARIS ⚔️🌙) Use ARIS as a skill-based workflow in , or get the full experience with the standalone CLI — enjoy any way you like! On DeepSeek Harne · License MIT · Maintenance unmaintained
- License
- MIT
- Parameter
- Default
- venue
- ICML
- character limit
- —
Specs
- ParameterDefault
- venueICML
- character limit—
- quick modefalse
- auto experimentfalse
- max stress test rounds1
- max followup rounds3
README
Auto-claude-code-research-in-sleep (ARIS ⚔️🌙)






💡 Use ARIS as a skill-based workflow in Claude Code / Codex CLI / Cursor / Trae / Antigravity / GitHub Copilot CLI / OpenClaw / DeepSeek Harness, or get the full experience with the standalone ARIS-Code CLI — enjoy any way you like!
🐋 On DeepSeek Harness it installs as one plugin: dsh plugin --profile web add dsh-aris (fetches from npm by itself — no separate install step, but pnpm must be on PATH) — all 82 skills unchanged, Codex still the independent reviewer. Setup and limits on the dsh-aris branch.
🌱 ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.
🤖 AI agents: Read AGENT_GUIDE.md instead — structured for LLM consumption, not human browsing.
🛡️ ARIS audits its own output → now Anti-Autoresearch audits everyone's. 61 signals — 46 integrity hack-patterns in 8 families, 13 AI-style impressions, 2 advisory — checked end-to-end into a deterministic, reviewer-ready report.
Self-consistency + fabrication forensics, not an AI-text detector.
The field has put up with unreliable autoresearch long enough —Anti-Autoresearch is the read that finally catches it.
🧱 ARIS's reviewer is good — and it also proposed hashes nobody reads → HERO is the contract that stops that. Hashing, Edge cases, Rubrics, Overbuild — the four shapes agents over-defend in, as a ~550-token block for CLAUDE.md / AGENTS.md.
It bounds what the agent proposes, never what it looks for.
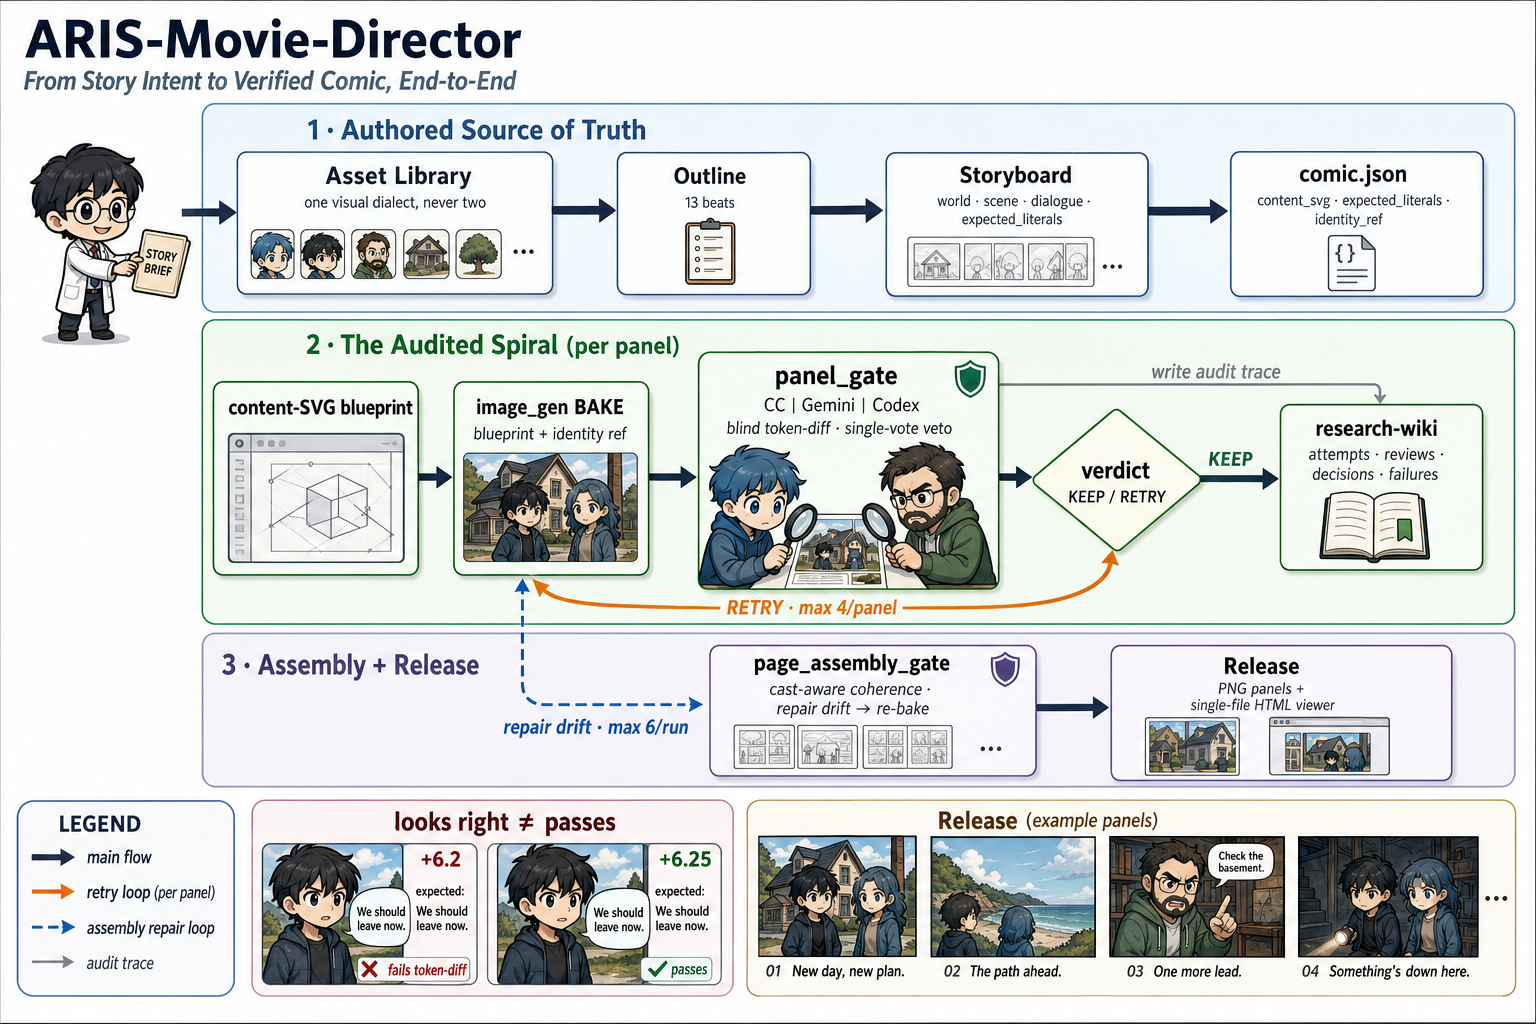
🎬 ARIS goes multimodal → ARIS-Movie-Director — hand it a rough story and get back a movie told in still frames, checked scene by scene (the reference run has 19 scenes).
Long stories usually break when the model forgets earlier details or judges its own work — so ARIS keeps a research-wiki for memory and has other models check every frame.
<details>
<summary>🗺️ <b>Method figure</b> — story brief → authored source of truth → per-panel audited spiral → assembly & release, on one canvas</summary>
</details>
🧭 The same loop also makes clean method / flow diagrams — the figure above was made with it. Entry points in ARIS-Movie-Director:
/movie-pipelineand/method-figure, the skill that made this figure.
<details>
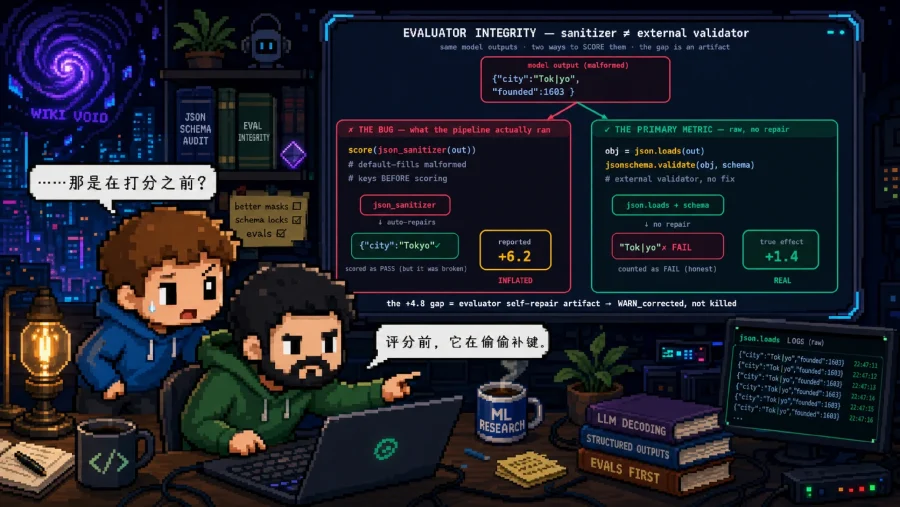
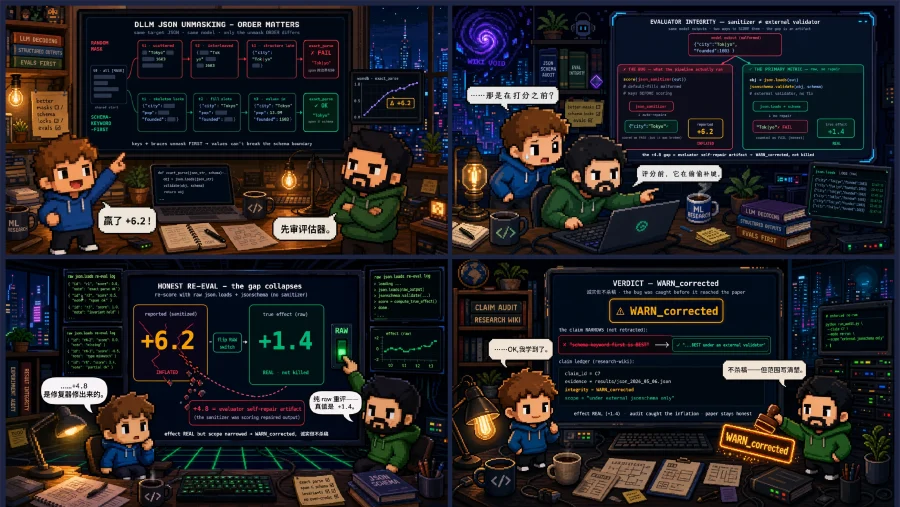
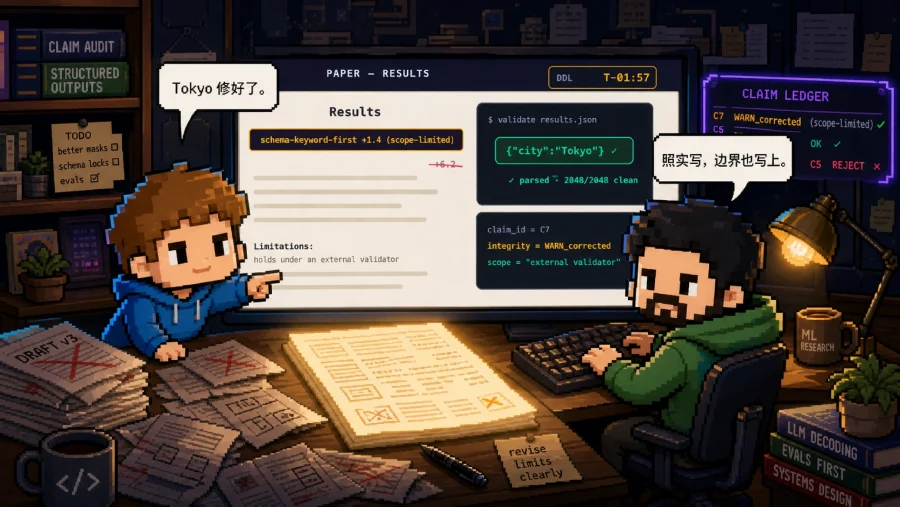
<summary>🎞️ <i>A few frames from the reference movie — the story's own integrity beat: a run that <b>reported <code>+6.2</code></b> but <b>really moved <code>+1.4</code></b>.</i> <b><a href="https://wanshuiyin.github.io/ARIS-Movie-Director/comic/">▶ watch all 19 scenes →</a></b></summary>
<table><tr>
<td width="33%"><a href="https://wanshuiyin.github.io/ARIS-Movie-Director/comic/">
</a></td>
<td width="33%"><a href="https://wanshuiyin.github.io/ARIS-Movie-Director/comic/">
</a></td>
<td width="33%"><a href="https://wanshuiyin.github.io/ARIS-Movie-Director/comic/">
</a></td>
</tr></table>
</details>
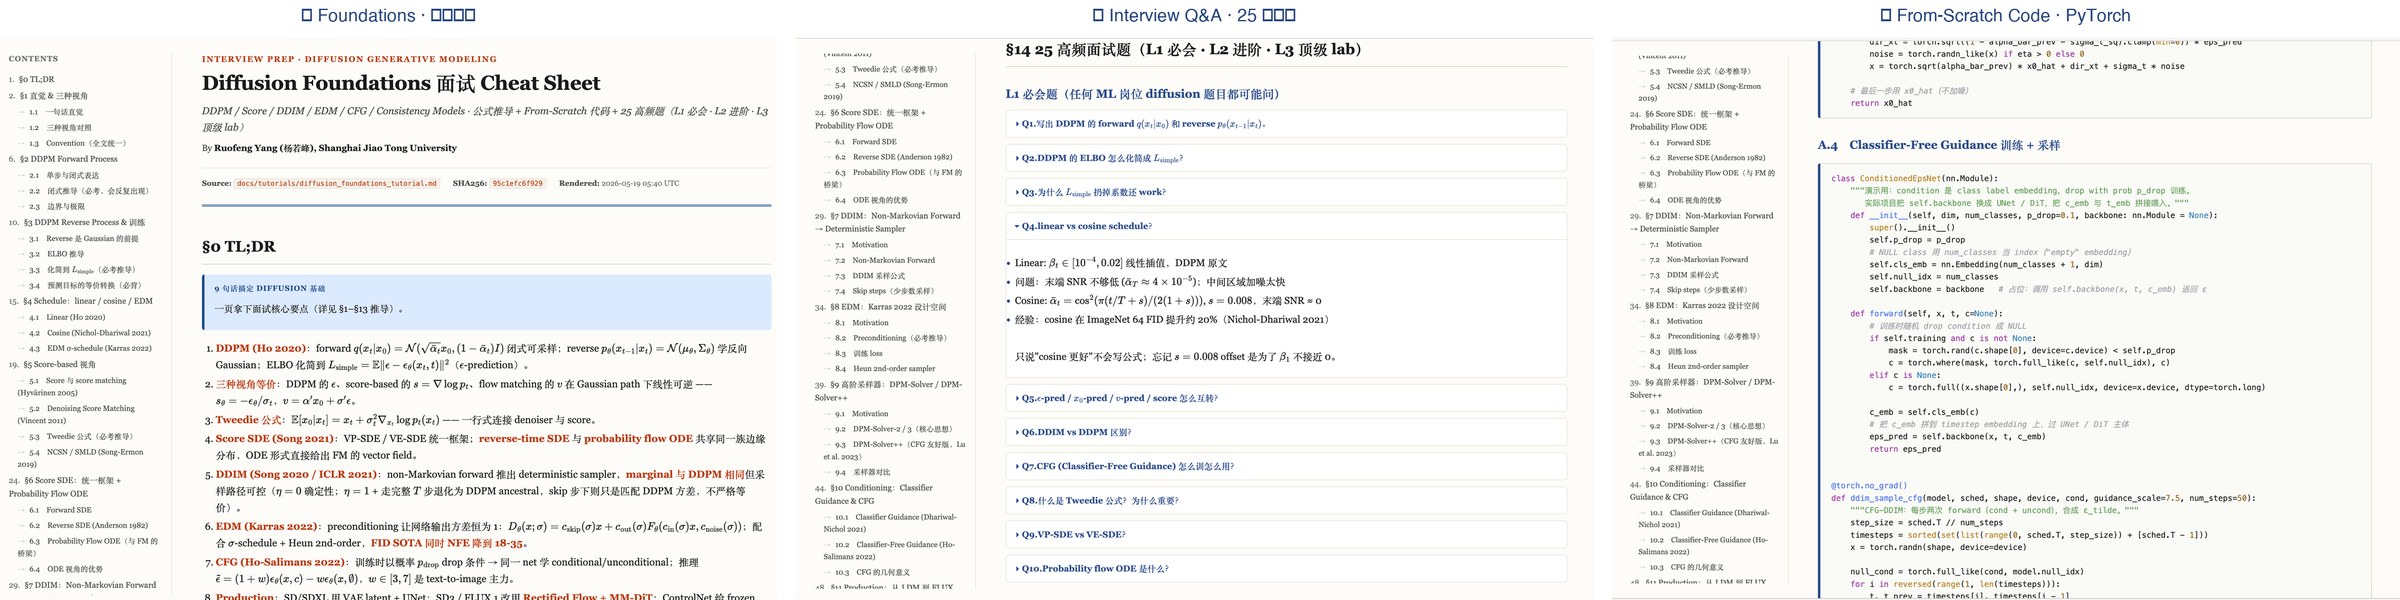
🎯 准备 2026 AI 秋招? → 🌐 ARIS-in-AI-Offer · GitHub repo · 中文 README —— 23 篇双语 ML / LLM / 多模态 / 生成式 / Agent 面试 cheat sheet,每篇 = 公式推导 + 从零 PyTorch + 25 高频面试题(L1 / L2 / L3),全部由 ARIS 的 /render-html 自动生成。希望大家秋招轻松一点 🌱
<details>
<summary><b>🖼️ Preview</b> — the three-pillar cheat-sheet strip (① Foundations · ② Interview Q&A · ③ From-Scratch Code)</summary>
</details>
📝 Three long-form blogs, cross-model collaborative writing via
/render-html— Continuous DLM — a representation-perspective survey (2026 H1) · Cosmos 3 — understanding + generation in one Transformer (MoT) · Diffusion × representation × manifold learning.
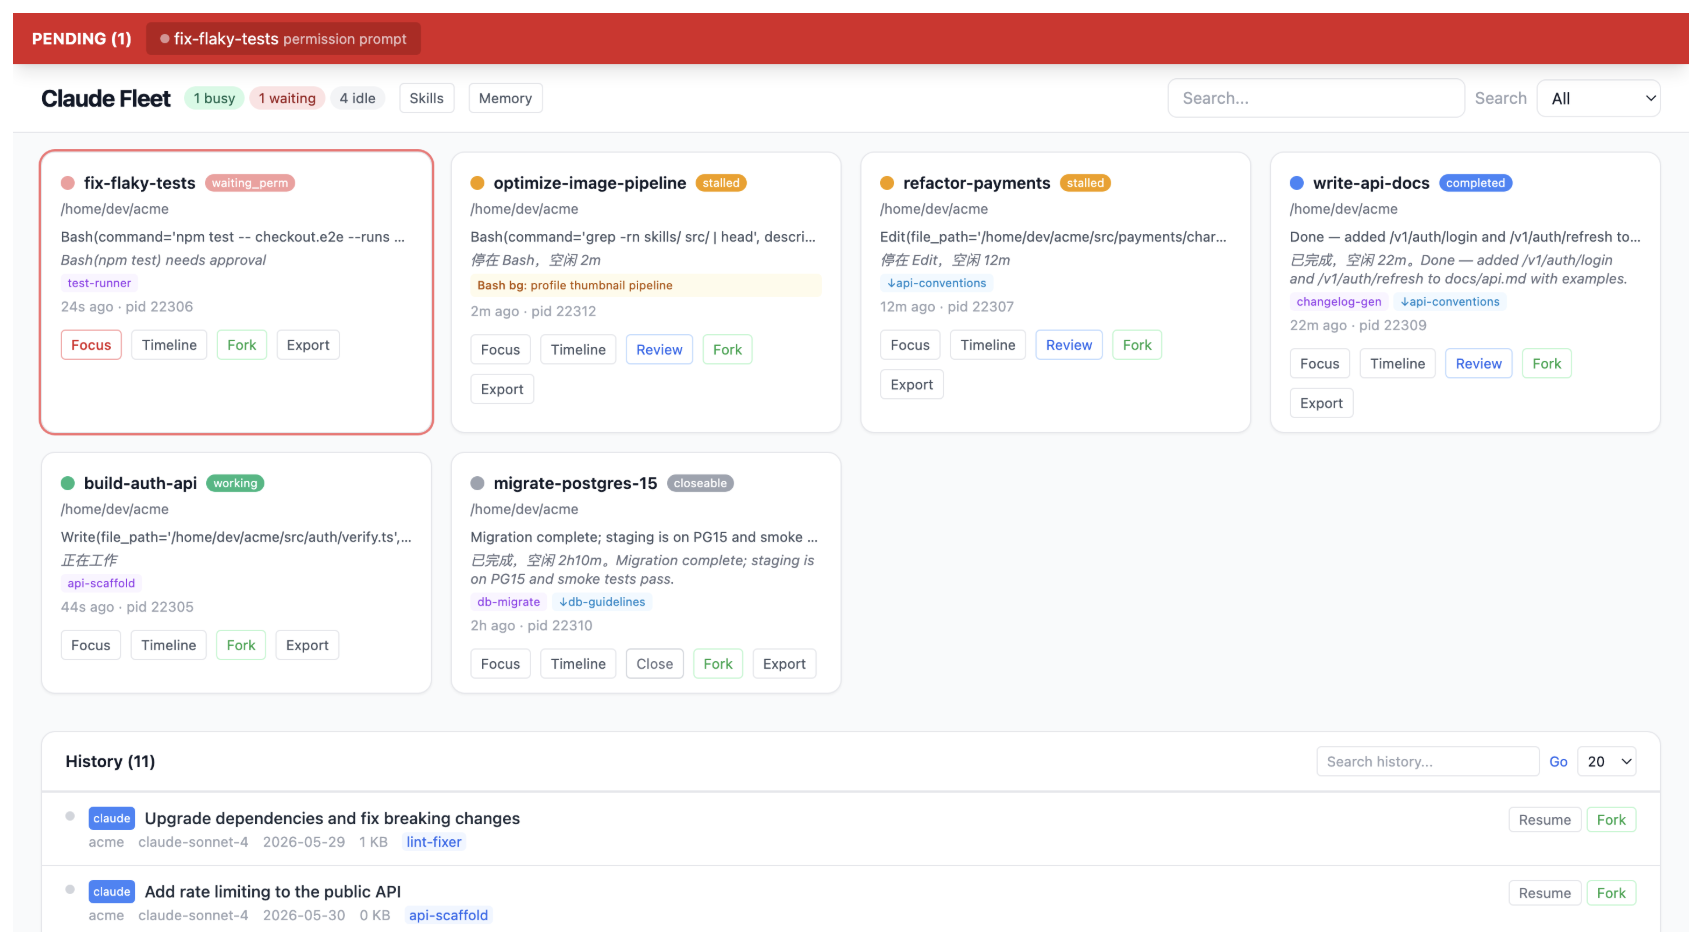
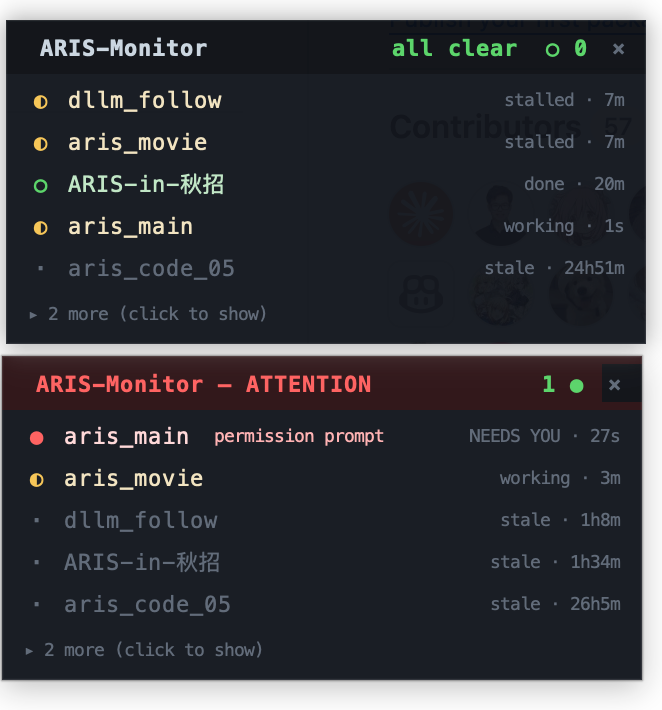
🛰 Keep an eye on your agent windows — Claude Fleet (by @tianyilt; local read-only dashboard for many parallel Claude Code / Codex windows, full-text transcript search — worth a ⭐), or the lighter built-in ARIS-Monitor (a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval; click to jump there).
<details>
<summary><b>🖼️ Preview</b> — Claude Fleet dashboard (full web) & ARIS-Monitor widget (minimal, built-in)</summary>
<table align="center" width="100%">
<tr>
<td width="66%" align="center" valign="top">
<a href="https://github.com/tianyilt/claude-fleet">
</a>
</td>
<td width="34%" align="center" valign="top">
<a href="aris-monitor/">
</a>
</td>
</tr>
<tr>
<td align="center"><b><a href="https://github.com/tianyilt/claude-fleet">Claude Fleet</a></b> · 全功能网页看板</td>
<td align="center"><b><a href="aris-monitor/">ARIS-Monitor</a></b> · 极简悬浮小窗(自带)</td>
</tr>
</table>
</details>
<details>
<summary><b>Run either in seconds</b> — ARIS-Monitor (5s) / Claude Fleet (30s)</summary>
ARIS-Monitor — built-in, no clone / no pip / no browser:
cd aris-monitor && ./run.sh
# a borderless panel floats top-right; click a row to jump to that terminal
Claude Fleet — full web dashboard:
git clone https://github.com/tianyilt/claude-fleet
cd claude-fleet && bash run.sh
# open http://127.0.0.1:7878 in your browser
</details>
🚀 Beyond 科研 → 任何 "研究":ARIS-Anything 把 ARIS 的五步 loop(plan / draft / 对抗审 / 迭代 / 持久化)推广到非学术的结构化研究——投资尽调 / 法律研究 / 市场研究 / 自驱学习 / 调查新闻 / 工程复盘等。
🔥 ARIS-Code CLI — 独立安装版 · English | ⬇️ Download ·
<table>
<tr>
<td valign="top" width="60%">
📰 ARIS-Code v0.4.24 (2026-08) — latest is the Claude 5 model refresh (#392): first-class Claude Opus 5 (new default, same $5/$25 tier) and Claude Fable 5 (Mythos-class flagship, correct $10/$50 pricing) — /model picker + fable/opus/sonnet aliases + an ordered availability chain (Opus 5 → 4.8 → 4.7) so accounts without Claude 5 access keep working untouched. Recent headliners: v0.4.23 — output folding (tool output folds to a few lines, ARIS_TOOL_OUTPUT_LINES=0 restores full dumps; 81 bundled skills incl. the Anti-Autoresearch /integrity-forensics launcher) and v0.4.17 — the MCP release (cross-model review needs no OpenAI API key — aris setup wires your ChatGPT subscription in as reviewer via Codex MCP). Caps a 20-release run (v0.4.5 → v0.4.24); per-release detail below. Credits: @GetIT-Sunday, @Anduin9527, @GO-player-hhy, @Jxy-yxJ, @screw-44, @StevenUST, @opposj, @ShijunLei-cn, @algojogacor, @YukinoshitaLove.
</td>
<td valign="top" width="40%">
</td>
</tr>
</table>
<details><summary>Per-release details (v0.4.5 → v0.4.24)</summary>
v0.4.24 (2026-08-09) — the Claude 5 model refresh (#392, requested by @YukinoshitaLove). Explicit
--model claude-opus-5/claude-fable-5already passed through on every platform — this release makes them first-class. Default →claude-opus-5(main session, subagents,aris setup; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered chain walk (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise404 not_found_error, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks./modelpicker adds Fable 5 / Opus 5 / Sonnet 5; newfablealias. New Mythos-class pricing tier (fable/mythos= $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-5.6-sol xhigh) implementation gate: NO-GO → NO-GO → GO.v0.4.23 (2026-08-02) — the output-folding release (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). 🧹 Tool-output folding, display layer ONLY: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context,
--output-format jsonand/exportare untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. 🐛 Bash timeout now kills the command: a timed-out call reportedinterrupted: truewhile the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatchARIS_BASH_KILL_ON_TIMEOUT=0; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). 📦 Bundle 79→81 (pin 7182624 → 3e49e63):/integrity-forensics— the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and/web-debug-search, +tools/forensics_gate.py (29 helpers, 104 embedded resources). 🎁 Also: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that"numMatches": nullserializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green under a live proxy; new-code clippy delta zero. Codex MCP (gpt-5.6-sol): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).v0.4.22 (2026-07-12) — the skills-resync + GPT-5.6-Sol release. 📦 Bundle resync (pin 7e3ab67 → 7182624, 93 commits): 79 bundled skills (+
meta-apply, +paper-poster-html;paper-posterretired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening —ARIS_SYNC_EXPECT_SHAguard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. 🎛 GPT-5.6-Sol two-tier reviewer alignment: the CLI's system-prompt nudge now passes the skills' explicitmodel: gpt-5.6-sol+ per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pinsapproval-policy: "never"+ explicitsandboxon every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display//reviewerare honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). 🐛 8 verified fixes: explicit--modelwas silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices;/modeland/setupre-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution);--output-format jsonnever prompts (locked by a real end-to-end binary test against a mock SSE server); Windowsaris loginfixed (PKCE randomness read /dev/urandom → getrandom); Windows command probing fixed (the PowerShell tool probed itself throughsh; now where.exe); codex.cmdshims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. 🖥 New windows-latest CI job (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-5.6-sol): ultra design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.v0.4.21 (2026-06-28) — bug-fix patch: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). 🐛 Headline: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into
�— each HTTP body chunk wasfrom_utf8_lossy'd independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. A saved OpenAI/custom executor config no longer overrides a shell-setEXECUTOR_PROVIDER— the startup "shell-provided vars win" path had one ungated write that re-pointedEXECUTOR_PROVIDER=anthropic … aris …to OpenAI (wrong executor / model-not-found). An Anthropic stream truncated after content but before a terminal signal now hard-errors (premature_eof) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI#249guard; thestop_reason-only compat path is preserved, andARIS_ALLOW_EOF_WITHOUT_STOP=1opts a terminal-signal-less proxy back into the old behavior).grep_searchwithmultiline: truenow matches across lines in content mode (was silently empty —countmode already worked). MCP tool results carried only instructuredContent(emptycontent) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends withmessage_stop) was WebFetch-verified. Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) remain deferred.v0.4.20 (2026-06-19) — bug-fix patch: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). 🐛 Headline (#299): short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, but
finishthen cleared that whole line, erasing a short single-line reply. The REPL now finishes without clearing when the turn printed visible text (Clear(UntilNewLine)wipes only the spinner tail after the reply). Streamed multi-paragraph replies rendered glued ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). Markdown tables with CJK/fullwidth content misaligned — width now counts display cells (CJK = 2), not chars.aris "prompt"/aris setup(REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. Esc now actually closes the completion dropdown (it was recomputed right back).glob_searchreports the total matched count when truncated (not the capped 100, which made the model think a 1000-match glob had 100 files)./model's custom menu reads the effective env the executor uses, not stale on-disk config. Tests (CI mode): api 32 / runtime 205 / tools 67 / aris-cli 172 / commands 5, all green; +7 new; real-machine verified (short reply renders + "✔ Done"; paragraphs keep their blank lines). Codex MCP (gpt-5.5 xhigh): hunt → 3 review rounds (NO-GO → NO-GO → GO). Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) deferred to a hardening pass.v0.4.19 (2026-06-14) — honesty / guardrails patch (theme from a Codex fresh-eyes audit; no behavior change for healthy setups). 🔴 MCP protocol-version negotiation guard — the stdio handshake requested
2025-03-26but never read the version the server negotiated back (a parsed-but-dead field), so a server agreeing on a version ARIS can't speak was silently accepted and latertools/list/tools/callran on an incompatible protocol with opaque failures. ARIS now validates the negotiated version against a supported set (2025-11-25/2025-06-18/2025-03-26/2024-11-05— stdio framing is identical across these) and, on an unsupported one, terminates the child + clears the slot + surfaces a clear per-server error (aris doctorshows it) — the "terminate when versions can't be agreed" behavior the MCP lifecycle spec requires. The request stays2025-03-26(proven againstcodex mcp-server), so healthy servers are unaffected — verified end-to-end: the real Codex MCP server still spawns + initializes + advertises its tools under the guard. 🧹 Papercuts: the OpenAI-family subagent fail-loud message dropped its stale "lands in v0.4.18" marker (now version-agnostic + actionable, still credential-free); OpenAI upstream error bodies are now truncated (500 chars) + credential-redacted (sk-…keys andBearer …tokens, via a substring scanner that catches the compact-JSON shape{"api_key":"sk-…"}a misconfigured proxy can reflect back) instead of splatted verbatim; the system-prompt hook-events summary now counts only the hooks the runtime actually executes (acommandhook with acommandstring), matching the parser. Tests (CI mode): api 32 / runtime 204 / tools 67 / aris-cli 167 / commands 5, all green; live smoke confirms the real Codex MCP server still initializes under the guard. Reviewed by Codex MCP (gpt-5.5 xhigh): design GO → impl NO-GO (compact-secret miss + command-string strictness) → GO after fixes.v0.4.18 (2026-06-14) — default model → Claude Opus 4.8, with corrected pricing and a safety net. The bump moves
DEFAULT_MODEL, theopusalias, the model picker,aris setup, and the subagent default toclaude-opus-4-8— with an availability fallback: if the account lacks 4.8 (the API returns404 not_found_error), ARIS auto-falls-back toclaude-opus-4-7for the session, rebuilds the system-prompt model identity so it stays coherent (the model is never told it's 4.8 while served 4.7), warns once, and retries — for the main session (text + JSON) and subagents. It fires only on that precise 404 (never 400/rate-limit/auth), latches against loops, and the text path rebuilds from a pre-turn snapshot so a retry never double-appends the user message; accounts with 4.8 are byte-identical to a plain bump. 💰 Pricing corrected (verified against Anthropic's published schedule; had been a 3–5× over-estimate): current Opus 4.5–4.8 =$5/$25(deprecated Opus 4/4.1 keep$15/$75, split by word-boundary so a futureopus-4-10isn't mis-tiered); Sonnet 4.x =$3/$15(decoupled from the generic unknown-model fallback, which stays$15/$75); Haiku was already correct. 🧹 Backlog:aris setupoption 10 pins the Codex MCP reviewer tomodel_reasoning_effort="xhigh"(deterministic for new setups, independent of~/.codex/config.toml; idempotent merge never clobbers an existing entry); a startup +aris doctormisconfig hint (#259) for a silently-ignored/misplaced config (malformed JSON, or a stray~/.aris/config.yaml— stderr-only soSessionStart/SessionEnd/… — deferred to a separate issue). Tests (CI mode): api 32 / runtime 202 / tools 67 / aris-cli 166 / commands 5, all green; a live one-shot smoke returnsmodel=claude-opus-4-8end-to-end. Reviewed by Codex MCP (gpt-5.5 xhigh) across the design + both implementation batches (design REWORK→GO, impl NO-GO→GO, batch-2 GO).v0.4.17 (2026-06-13) — the MCP release. Before v0.4.17,
mcpServersinsettings.jsonparsed, showed inaris doctor, and did nothing; now ARIS spawns each configured stdio server, runs the MCP handshake, discovers tools, and advertises them asmcp__<server>__<tool>on both provider paths (Anthropic + OpenAI-family), with end-to-end dispatch, soft per-server degradation, and an approval gate for untrusted MCP tools (external processes the sandbox can't cover;--allowedToolsnow acceptsmcp__names). 🆕 zero-API-key cross-model reviewer:aris setup→ option 10 (Codex MCP, ChatGPT subscription, no API key) writes an idempotentmcpServers.codexentry into the settings file the runtime actually reads (atomic write + backup, explicit consent beforetrust: true), with an optional API reviewer as fallback (ARIS_REVIEWER_PROVIDER=codex-mcp+ARIS_REVIEWER_FALLBACK_PROVIDER);/setupin-REPL rebuilds the system prompt + runtime so reviewer changes take effect without quitting. 🔴 Protocol fix the fakes couldn't catch: real-machine e2e againstcodex mcp-serverexposed that our stdio transport spoke LSP-styleContent-Length:framing while the MCP spec (and codex) use newline-delimited JSON-RPC — every fake-server test passed because the fakes spoke the same wrong dialect; writes are now NDJSON, reads auto-detect both, and the spec-mandatednotifications/initializedis sent afterinitialize(a select-based round-trip also closes the #286 large-request deadlock). Hooks: object-style Claude Code hooks preservematcher/timeout/async(anchored-regex matcher filtering; per-hook timeout, default 30 s kill = warning not deny). Long tail:ARIS_DISABLE_KEYCHAINgate, Anthropicstop_reasonclean-EOF symmetry (CL2), OpenAI tool-callindex-missing merge-by-id (OE6), slash commands enter history. Real-machine push-gate hardening (the zero-key reviewer's first run): codexcodex/eventnotification spam silenced by default (gated behindARIS_MCP_STDERR=inherit), the system prompt now tells the model not to pass amodelparameter to Codex (account default = gpt-5.5 + xhigh; arbitrary names are rejected by a ChatGPT account), and a Codex-MCP-primary-with-no-fallbackLlmReviewcall returns a clear "usemcp__codex__codex" message instead of a misleadingOPENAI_API_KEY/gpt-5.5error. Built with the v0.4.16 zero-regression methodology (24 new characterization tests; every deliberate flip annotated in-place). Tests (CI mode): runtime 199 / aris-cli 165 / tools 67 / api 30 / commands 5, all green. Reviewed phase-by-phase by Codex MCP (gpt-5.5 xhigh) across 17 rounds (7 NO-GOs all resolved). Subagent MCP routing (P8) + MCPprotocolVersionbump + hookasyncexecution deferred to v0.4.18.v0.4.16 (2026-05-30) — REPL UX + provider hardening, shipped under a zero-regression discipline: 64 characterization ("golden") tests locked the current provider-routing / pricing / reviewer / subagent / REPL behavior first, then stayed green through every change. Closes #274: command history now persists to
~/.config/aris/history(0600) and reloads on startup, with anARIS_NO_HISTORYkill-switch and a disk-only secret-skip (credential-looking lines stay in in-session history but never touch disk); bash-style Ctrl+R reverse incremental search (CJK display-width-aware single-line render; no existing key binding changed; no new dependency). Security: an OpenAI-family main session (Kimi / GLM / MiniMax / …) spawning a subagent previously silently billed the user's Anthropic OAuth/Keychain credential — it now fails loud with a clear, credential-free error; full OpenAI-family subagent routing is a cross-crate change deferred to v0.4.17. Groundwork (no behavior change): the 3 byte-identical word-boundary matchers consolidate into one canonicalruntime::word_match; new pureProviderFamilyclassifier (unwired). Tests (CI mode): runtime 164 / aris-cli 128 / tools 49 / commands 5, all green. Codex MCP (gpt-5.5 xhigh) reviewed each phase + a final integration pass.v0.4.15 (2026-05-29) — OpenAI-compatible streaming robustness hotfix. Closes #249: MiniMax (and other OpenAI-compatible providers / proxies) were effectively unusable because the clean-EOF completion check treated the
data: [DONE]SSE sentinel as the only authoritative signal. A non-emptychoices[].finish_reasonis the Chat Completions spec's terminal-chunk marker;[DONE]is a transport convention some compatible providers never emit (MiniMax sendsfinish_reason: "stop"then closes without[DONE]). The clean-EOF decision is now a pure, unit-testedstream_eof_action(...)that completes on EITHER[DONE]OR a non-emptyfinish_reason; reads are NOT stopped early at finish_reason (a trailinginclude_usageusage-only chunk is still consumed), genuine truncation still hard-errors, and a pre-output proxy abort still restarts. Coupled fixes: OE7 reads finish_reason before thedeltaguard (delta-less terminal choice); OE2 flushes pending tool calls on any non-empty finish_reason; OE4 surfaces a mid-stream error envelope as a hard error instead of silently dropping it; OE3 toleratesdata:{...}without the space after the colon. +5 unit tests (77→82) extract the previously-untested SSE completion logic into pure helpers. Anthropic SSE path untouched. Codex MCP (gpt-5.5 xhigh) 3 rounds (GO-WITH-NITS → GO-WITH-NITS → GO).v0.4.14 (2026-05-25) — Security-hygiene release closing the top items from the v0.4.13 codex audit (gpt-5.5 xhigh, 6/10 NEEDS-REWORK verdict). 🔴 S9 (P0) system-prompt config redaction — before v0.4.14,
render_config_section()dumped the mergedsettings.jsonverbatim into the system prompt sent to the LLM provider, leakingenv,mcpServers.<name>.headers.AuthorizationBearer tokens, hook command env, signed-URL query params, andapiKeyfields. New renderer whitelists top-level fields (model/permissionMode/theme/outputStyle/permissions/sandboxwith recursive redaction inside), redacts sensitive keys (apikey/token/secret/password/authorization/headers/env/_KEY/_SECRET/_TOKEN), replaces MCPcommandwith<configured>placeholder, reduces MCPurlto strict<scheme://host[:port]>origin (scheme allow-listhttp/https/ws/wss, ASCII host, digit-only port, IPv6 brackets), and drops hook command strings entirely. Regression test exercises 9 distinct leak surfaces; URL parser has its own targeted test for 7 smuggling attempts including port-position secret injection (codex round-3 catch). 🟡 P9 (P1): DeepSeekaris --helpnow points ataris setupoption 7 instead of an env-var path the resolver never honored. 🟡 M1/M2 (P1) doc:aris doctor+ README/README_CN gain experimental warning whenevermcpServers.len() > 0(full MCP tool dispatch lands v0.4.16). 🟢 C11 (P2) stream idle timeout — both AnthropicMessageStreamand the OpenAI SSE loop wrapresponse.chunk().awaitintokio::time::timeout(envARIS_STREAM_IDLE_TIMEOUT_SECS, default 120, clamp[10, 1800], 0/negative disables); closes the "aris hangs forever with no output" symptom when an upstream HTTPS proxy holds a connection without keepalives. Bundle: 77 skills (+1/wiki-enrichvia late same-day sync to main7e3ab67which also picks up upstreamcheck_ready.shawk + grep-c null-match fix), 54 helpers. Codex MCP 6 rounds (NO-GO + 4 → GO-WITH-NITS + 3 → NO-GO + port smuggling → GO → release metadata GO → sync GO).v0.4.13 (2026-05-25) — Residue-cleanup release closing every codex audit P1 carried since v0.4.10–v0.4.12, plus the long-tail regression tests. 🟡 v0.4.10 P1.D per-server MCP timeout —
mcpServers.<name>.requestTimeoutSecsoverride >MCP_REQUEST_TIMEOUT_SECSenv > 300s default (clamped 1..=1800), so one Codex MCP agent can run 5 min while filesystem MCP errors in 5 s. 🟡 v0.4.10 known limitation closed —McpStdioProcess::request()skips JSON-RPC notifications (id absent/null) and keeps reading until the correlated response. 🟢 meta_opt hook deploy viaaris init—tools/meta_opt/{log_event,check_ready}.shbundle into the binary;aris initwrites ARIS-namespacedaris-meta-opt-log-event.sh/aris-meta-opt-check-ready.shto~/.claude/hooks/(codex round-1 #1: never clobbers user hooks); settings.json merge idempotent, backups hard-fail, final rewrite atomic via tempfile + rename. 🧪 9 v0.4.12 targeted regression tests for sandbox.strictMode (3) + parse strictMode + provider_match pricing + has_word o-series + stream_options 400 + meaningful-content classification + premature-EOF retry truth table (codex round-1 #3 —should_retry_on_premature_eof()extracted to pure fn, 7-row test). Bundle: 76 skills, 54 helpers (+2 meta_opt scripts vs v0.4.12). Codex 3 rounds (NO-GO + 3 → NO-GO + metadata → GO).v0.4.12 (2026-05-22) — Bug-fix + small-feature release. #238
sandbox.strictModeopt-in config key; when set,SandboxConfig::resolve_request()ignores all five LLM-supplied overrides (dangerouslyDisableSandbox,namespaceRestrictions,isolateNetwork,filesystemMode,allowedMounts) — closes the gap where a tool call could silently bypass user sandbox policy.aris doctoradds a "Sandbox:" row; bash tool schema documents the strictMode semantics. #232auto-review-loop-llmupdated from legacydeepseek-chat/deepseek-reasoner(deprecate 2026-07-24; reasoner rejectstool_choice) todeepseek-v4-flash/deepseek-v4-pro. v0.4.10 audit P1 follow-ups: P1.A Anthropic stream retry gates onhas_emitted_meaningful_content(a stream that only sentMessageStartbefore EOF is retry-eligible); P1.Bsupports_reasoning_effort+ reviewer mirror use word-boundary match soopenai/o3-mini/proxy:o4route correctly; P1.Cstream_options.include_usage:trueproxy fallback retries once without on real 400 unknown-field errors; P2 pricing match precision viaprovider_match()soqwen3.6-plus/kimi-k2.5route correctly whilemy-kimi-clonedoes not. Skills sync (76 skills, 52 helpers):/interview-cheatsheet+/render-htmlnewly bundled;build.rsALLOWED_EXTSgainshtmlfor render-html templates;EXCLUDED_SKILL_PREFIXES→starts_with("skills-codex"). CI fetch-depth: 0 + origin/main fetch so drift-test ancestor check runs. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) over 4 rounds.v0.4.11 (2026-05-18) — Skills bundle refresh + sync infrastructure. The embedded skills set in the v0.4.10 binary had fallen behind main (~6 of 56 main
skills/commits had been cherry-picked); v0.4.11 syncs the full set and ships sync infrastructure so the gap can't silently reopen. Bundle: 65→74 user-facing skills, 34→49 helper resources. 10 new skills bundled:/citation-audit(fourth-layer bibliography audit),/experiment-queue(SSH multi-seed job queue with OOM retry),/kill-argument(two-thread adversarial review for theory papers),/resubmit-pipeline(W5: text-only port to a new venue),/paper-talk(end-to-end conference talk pipeline),/slides-polish(per-page Codex layout review),/overleaf-sync(two-way Overleaf Git-bridge),/gemini-search+/openalex(broader literature sources),/qzcli(Qizhi GPU jobs). 46 existing SKILL.md refreshed — most critically the canonical resolver chain rollout (closes real user incident where/research-wikiwas empty for a week from hardcodedtools/research_wiki.py), submission assurance gate + external verifier (/paper-writingPhase 6 now functions). tools/ goes 9→18: 9 baseline helpers refreshed (research_wiki.py315→767 lines with canonicalingest_paperAPI), 9 new helpers (extract_paper_style.py,figure_renderer.py,paper_illustration_image2.py,overleaf_{setup,audit}.sh,verify_wiki_coverage.sh,watchdog.py,experiment_queue/{build_manifest,queue_manager}.py). Newtools/sync_main_skills.shautomates main → bundle rsync with symlink pre-flight + codex-mirror prune +SKILLS_SOURCE_COMMITpinning. 3 new CI drift tests incrates/runtime/src/cache.rscover all 4 resolver layer patterns. Gemini MCP calls in/research-litand/gemini-searchnow passmodel: 'auto-gemini-3'(avoids silent downgrade to 2.5-pro on OAuth-personal capacity exhaustion). CLI runtime unchanged — codex-audit P1 follow-ups remain on v0.4.12 backlog. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) across 5 rounds (REQUEST CHANGES → APPROVE WITH NITS → NO-GO → GO → final GO).v0.4.10 (2026-05-17) — Stream + MCP reliability + multi-provider pricing. C6 whole-stream restart in Anthropic
MessageStream+ OpenAI SSE loop on chunk decode failure / premature EOF (ARIS_STREAM_RETRY, default 2, clamp 0..=5, fires only when nothing emitted yet — closes #228-style "error decoding response body" loop). M3 MCP stdio gains 300s defaulttokio::time::timeoutover send+read (overrideMCP_REQUEST_TIMEOUT_SECS, clamp 1..=1800);response.id ↔ request.idcorrelation;ensure_server_ready()try_wait()dead-process respawn;kill().awaiton all failure paths so the next call starts clean (closes #151 / #172 "Calling codex..." stalls). C8/P4 OpenAI streaming requests now sendstream_options.include_usage:true+ parsecached_tokens; Anthropic streaming mergesMessageStart.usage(input/cache) withMessageDelta.usage(output). C9 multi-provider pricing registry (15+ models, OpenAI cache_read = input × 0.1 corrects 5× generic overstatement, DeepSeek cache_hit/cache_miss tiers,has_word()boundary matcher forprovider/<model>slugs). 9 dead-code warnings cleared;aris setuphelp text synced with actual behaviour.v0.4.9 (2026-05-17) — Closes Codex v0.4.7 audit residuals (L1 TLS double-stack, L3 reasoning_cache compaction misalign, L4 reasoning replay unbounded). 2 new skills bundled (
/figure-spec+/paper-illustration-image2withscripts/subdirs, new Layer 0b =$ARIS_CACHE_DIR/skills/<name>/scripts/);research_wiki.pypromoted to sharedtools/(9+ callers); 5 more SKILL.md migrated to fallback chain.v0.4.8 (2026-05-17) — Skill helper subsystem rewrite. Bundled helpers extract to
~/.config/aris/cache/<version>/at startup; every Skill invocation surfaceshelperReportJSON + 4-layer resolver preamble;/skills exportcopies helpers; newintegration-contract.mdwith 6 failure policies; 8 shared helpers (arxiv/deepxiv/exa/S2/openalex/save_trace/verify_papers/verify_paper_audits) bundled;/research-lit+/deepxivmigrated. Plus 4 bug fixes: gpt-5.5+tools 400 on OpenAI; Custom reviewer reset; missingsignaturefield (#228);--versionBuild date hardcoded.v0.4.7 (2026-05-16) — DashScope Coding Plan 405 fixed (#159) via
native-tlsswitch (#225);reasoning_contentreplay for all reasoning models (OpenAI o1/o3/o4 / DeepSeek-R1 etc.), not just Kimi (#226); 600+ lines dead code cleanup +rustylinedep removed + "Claw Code" → "ARIS-Code" rebrand.v0.4.6 (2026-05-14) — 🚨 Two long-standing silent bugs fixed:
PermissionMode::Promptsilently allowed every tool (derived-Ordbug); system prompt hardcodedcurrent_date = "2026-03-31"made models reject post-cutoff data as future/prompt-injection. Plus Custom OpenAI-compatible provider (/setupoption 11) with dynamic/modelsdiscovery (@Anduin9527 #221 + #222).v0.4.5 (2026-05-13) — First-class reasoning-model support: thinking content blocks end-to-end (fixes #161) +
reasoning_effort='xhigh'for GPT-5.5 / o1 / o3 / o4 / DeepSeek-thinking. DeepSeek V4 Pro + Xiaomi MiMo + Qwen 3.6 + Doubao in/setup(options 7-10). Object-style hooks parser. Default model bumped to Claude Opus 4.7 + GPT-5.5. REPL input hardening (multi-line wrap / Cmd+V paste / CJK boundary). GitHub Actions CI. Credits: @GO-player-hhy (#186), @Jxy-yxJ (#171), @GetIT-Sunday (#216 partial).</details>
<details><summary>Older versions</summary>
v0.4.4 (2026-04-20) — Setup UX + reviewer routing fixes (resolves #158, #162) |
/setupno longer forces Bearer for Anthropic + custom URL | Provider-aware proxy URL hints | Stale state no longer leaks across provider switches | LlmReview smart fallbackv0.4.3 (2026-04-17) — Third-party Anthropic-compat proxy support (Bedrock etc.) | Skip beta flags that proxies reject | Propagate custom base URL for
anthropicprovider | Credit @screw-44v0.4.2 (2026-04-17) — Auto-compaction corruption fix | Compaction summary preserved on OpenAI-compat executors | Shell-provided API keys no longer erased on launch
v0.4.1 (2026-04-15) — Plan mode (
/plan) | Cooperative Ctrl+C interrupt | Auto-retry (429/5xx/network) | Research Wiki 📚 (persistent knowledge base) | Self-Evolution 🧬 (/meta-optimize) | Local models (LM Studio/Ollama) | 62 skills syncedv0.3.11 (2026-04-13) — Reviewer Anthropic-compatible mode (Claude via proxy)
v0.3.9 (2026-04-11) — Proxy/custom base URL (CCSwitch) | Local models (LM Studio/Ollama) | Windows (experimental)
v0.3.5 (2026-04-08) — Research Wiki (persistent papers/ideas/experiments/claims + relationship graph) | Meta-Optimize self-evolution (analyze logs → propose SKILL.md patches)
v0.3.0 (2026-04-03) — Multi-file memory index | Rich task system (TodoWrite) |
/plan| Security hardeningv0.2.2 (2026-04-03) —
/planstep-by-step planning |/taskspersistent trackingv0.2.1 (2026-04-03) — Persistent Memory | Kimi K2.5 multi-turn fix | CJK cursor fix
v0.2.0 (2026-04-02) — Open source | Kimi + MiniMax + GLM support | Smart LlmReview routing | CI/CD
v0.1.0 (2026-04-02) — Initial release | Multi-executor & reviewer | 42 bundled skills
</details>
中文版 README | English
🌙 Let Claude Code do research while you sleep. Wake up to find your paper scored, weaknesses identified, experiments run, and narrative rewritten — autonomously.
🪶 Radically lightweight — no infrastructure, zero lock-in. The entire skill layer is plain Markdown files. No framework to learn, no database to maintain, no Docker to configure, no daemon to babysit. Every skill is a single
SKILL.mdreadable by any LLM — swap Claude Code for Codex CLI, OpenClaw, Cursor, Trae, Antigravity, Copilot CLI, Windsurf, or your own agent and the workflows still work. Fork it, rewrite it, adapt it to your stack.
Custom Claude Code skills for autonomous ML research workflows. These skills orchestrate cross-model collaboration — Claude Code drives the research while an external LLM (via Codex MCP) acts as a critical reviewer. 🔀 Also supports alternative model combinations (Kimi, LongCat, DeepSeek, etc.) — no Claude or OpenAI API required. For example, MiniMax-M3 + GLM-5 or GLM-5 + MiniMax-M3. 🤖 Codex CLI native — full skill set also available for OpenAI Codex. 🖱️ Cursor — works in Cursor too. 🖥️ Trae — ByteDance AI IDE. 🚀 Antigravity — Google's agent-first IDE. 🐙 Copilot CLI — GitHub's terminal agent (native SKILL.md + MCP). 🆓 Free tier via ModelScope — zero cost, zero lock-in.
💭 Why not self-play with a single model? Using Claude Code subagents or agent teams for both execution and review is technically possible, but tends to fall into local minima — the same model reviewing its own patterns creates blind spots.
Think of it like adversarial vs. stochastic bandits: a single model self-reviewing is the stochastic case (predictable reward noise), while cross-model review is adversarial (the reviewer actively probes weaknesses the executor didn't anticipate) — and adversarial bandits are fundamentally harder to game.
💭 Why two models, not more? Two is the minimum needed to break self-play blind spots, and 2-player games converge to Nash equilibrium far more efficiently than n-player ones. Adding more reviewers increases API cost and coordination overhead with diminishing returns — the biggest gain is going from 1→2, not 2→4.
Claude Code's strength is fast, fluid execution; Codex (GPT-5.6-Sol xhigh) is slower but more deliberate and rigorous in critique. These complementary styles — speed × rigor — produce better outcomes than either model talking to itself.
🧿 Want the strongest possible reviewer? Add
— reviewer: oracle-proto any skill to route reviews through GPT-5.5 Pro via Oracle MCP. Pro-level reasoning for proof verification, experiment auditing, and final stress tests. Works with API key or free browser mode. Setup →
<a id="contents"></a>
Contents
- More Than Just a Prompt
- What's New · changelog
- Quick Start · install + first run
- Features
- Score Progression (Real Run)
- Community Showcase — Papers Built with ARIS
- Awesome Community Skills & Extensions
- Workflows · 13 named pipelines (W1 / W1.5 / W2 / W3 / W4 / W5 / W6 / Wiki / WM + Effort / Assurance / Oracle)
- Setup · prerequisites / install / update / usage / GPU server config
- Customization · per-skill config knobs
- Alternative Model Combinations · GLM / MiniMax / Kimi / etc.
- Community
- Citation
- Star History
- Acknowledgements
- License
<a id="more-than-just-a-prompt"></a>
1. 🎯 More Than Just a Prompt
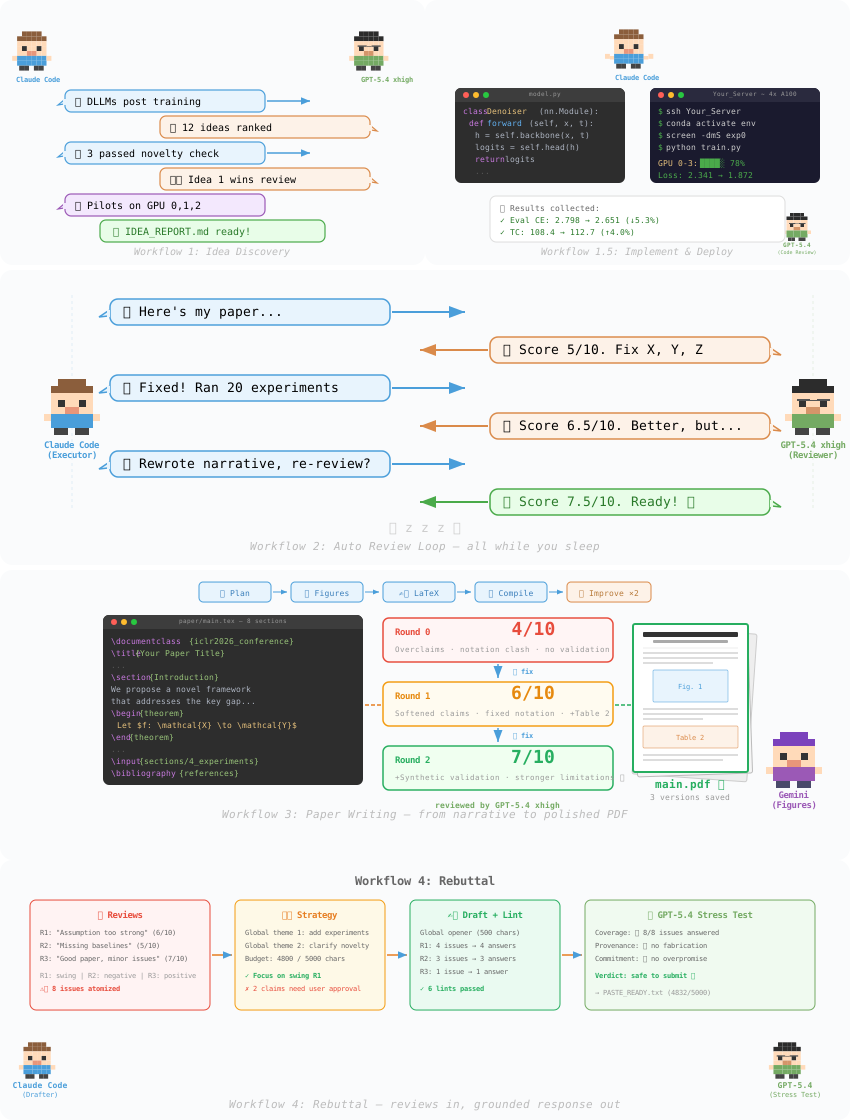
These are full pipelines — you can also use each workflow independently. Already have an idea? Skip to Workflow 1.5. Have results? Jump to Workflow 3. Got reviews? Jump to Workflow 4. Want persistent memory? Enable Research Wiki. See Quick Start for all commands and Workflows for the full breakdown.
Basic mode — give ARIS a research direction, it handles everything:
/research-pipeline "factorized gap in discrete diffusion LMs"🔥 Targeted mode — got a paper you want to improve? Give ARIS the paper + the code:
/research-pipeline "improve method X" — ref paper: https://arxiv.org/abs/2406.04329, base repo: https://github.com/org/projectARIS reads the paper → finds its weaknesses → clones the codebase → generates ideas that specifically fix those weaknesses with that code → runs experiments → writes your paper. Like telling a research assistant: "read this paper, use this repo, find what's missing, and fix it."
Mix and match:
ref paper,base repo, both = "improve this paper using this code."
🔥 Rebuttal mode — reviews just dropped? Don't panic. ARIS reads every concern, builds a strategy, and drafts a rebuttal that's grounded, structured, and under the character limit:
/rebuttal "paper/ + reviews" — venue: ICML, character limit: 5000Three safety gates — rebuttal will NOT finalize if any fails:
- 🔒 No fabrication — every claim maps to paper/review/user-confirmed result
- 🔒 No overpromise — every promise is user-approved
- 🔒 Full coverage — every reviewer concern is tracked
Two outputs: PASTE_READY.txt (exact char count, paste to venue) + REBUTTAL_DRAFT_rich.md (extended version for manual editing).
<details>
<summary><b>Show rebuttal parameters</b> — venue, character limit (required), quick mode, auto experiment, stress test rounds, followup rounds</summary>
| Parameter | Default | What it does |
|---|---|---|
venue |
ICML |
Target venue (ICML/NeurIPS/ICLR/CVPR/ACL/AAAI/ACM) |
character limit |
— | Required. Hard character limit for rebuttal text |
quick mode |
false |
Stop after parsing + strategy (Phase 0-3). See what reviewers want before drafting |
auto experiment |
false |
Auto-run supplementary experiments via /experiment-bridge when reviewers ask for new evidence |
max stress test rounds |
1 |
How many times GPT-5.6-Sol xhigh stress-tests the draft |
max followup rounds |
3 |
Per-reviewer follow-up round limit |
</details>
After acceptance — your paper is in, now prepare the presentation:
/paper-slides "paper/"     # → Beamer PDF + PPTX + speaker notes + Q&A prep
/paper-poster-html "paper/" # → measurement-gated HTML/CSS poster → print-ready PDF
💡 From idea to paper to podium — one toolchain. 🌱
<a id="whats-new"></a>
2. 📢 What's New
⚠️ Any entry that touches skills:
bash tools/smart_update.sh --applypulls it.
-
2026-08-26 —
🧯 Two over-defense leftovers (#425).
/research-review— the one reviewer prompt that never got the scope-limits block — now carries it, and its brief ends with "if the work holds up, say so clearly" instead of bare brutality; the adversarial stance itself is untouched./research-pipelineno longer dies overnight on a missingVENUE: ideas, experiments, analysis and the narrative report are venue-independent and run to completion — only paper formatting defers, stamped clearly for a later resume. It had also been declaringVENUE = ICLRwhile forbidding silent defaults; the default is gone. -
2026-08-26 —
-
2026-08-26 —
-
2026-08-21 —
🔌 Optional HTTP reviewer fallback for when Codex MCP is unreachable (#413; by @TheFlashForge). Off by default; fires only when Codex provably never got the request — a timeout doesn't count, that could pay twice for two conflicting verdicts. The fallback reads your actual files and gets less trust than Codex, never more.
-
2026-08-21 —
AUTO_PROCEED=truenow actually continues on its own; the idea-discovery gate demands a real reviewer receipt, not a checkbox; cached wiki context is scanned right before/idea-creatorreads it; Codex users with Claude as reviewer get their three paper skills back.
<details>
<summary>Earlier updates (2026-03-12 — 2026-08-09, 86 entries)</summary> -
2026-08-09 —
/auto-review-loopto its native rubber-duck reviewer (#360, closes #258). Active only inside Copilot CLI sessions; review evidence is revalidated from host events, and same/unknown-family fails closed. The standard Claude Code + Codex setup is untouched. -
2026-08-09 —
/idea-discoverycan no longer silently skip a stage (#383, closes #285; by @3mom3). Each of the five stages needs recorded evidence, or the report saysBLOCKEDinstead of looking complete. -
2026-08-05 —
<year>_untitledand got deduped away. Existing UTF-8 wikis unaffected. -
2026-08-04 —
/paper-poster-html— shipped a major design upgrade (MIT, by @Chenruishuo; ~50 posters at this year's ICML). GitHub · Blog. -
2026-08-03 —
/proof-orchestrator— Workflow 7: proof campaigns with a memory (#381; by @shenmuxing, from their EtaSkill). Stateful local-first proof runs that continue across sessions, with a ready-to-paste GPT Pro handoff when a proof stalls./proof-checkerremains the submission gate. -
2026-07-14 —
/web-debug-search(Issue #211). Adds a focused debugging/discovery workflow for GitHub Issues and Discussions: exact and normalized error-string matching, version compatibility tracking, and explicit failure handling. Results are labeled for debugging only and are not paper-citation evidence. -
2026-07-14 —
--list-groups,--groups X,Y,--skills X,--exclude Y, or a bare-TTY checkbox picker), with hard pipeline deps auto-included. Updates now confirm each NEW upstream skill individually (--add-new/--skip-newfor scripting; declines are remembered and never re-asked). Also fixes copy installs (~/.claude/skills) losing helper-script resolution, via a new~/.aris/repopointer file. ⚠️ Backward compatible —--quietfresh installs still install everything; run any installer/updater once to pick up the pointer file. Selective install → -
2026-07-12 —
/integrity-forensicsskill: a SHA-pinned thin launcher runs Anti-Autoresearch's hostile-reviewer sweep (evidence ledger, nine auditor dimensions, numeric core, rules-only adjudicator) on your paper first. The verdict feeds a typed gate — flags can block a submission, a clean sweep is recorded as "no new blocker" (never an acquittal) — and findings close only with typed, hashed evidence or a recorded human waiver (rewording the flagged sentence doesn't count; the ledger notices)./paper-writingruns it by default at submission assurance (— self_forensics: falseopts out; the Codex mirror is opt-in and limited to upstream's deterministic slice, which can flag but never say CLEAN). ⚠️ First run clones and validates the pinned upstream (needs network); runbash tools/smart_update.sh --apply. -
2026-07-10 —