

Repository
contextpilot
ContextPilot extends context management with planning, structured memory, and soft context offloading. Its context-aware partial rollout focuses exploration on sensitive context-ed · License unknown · Maintenance unknown
- License
- Unknown
README
ContextPilot
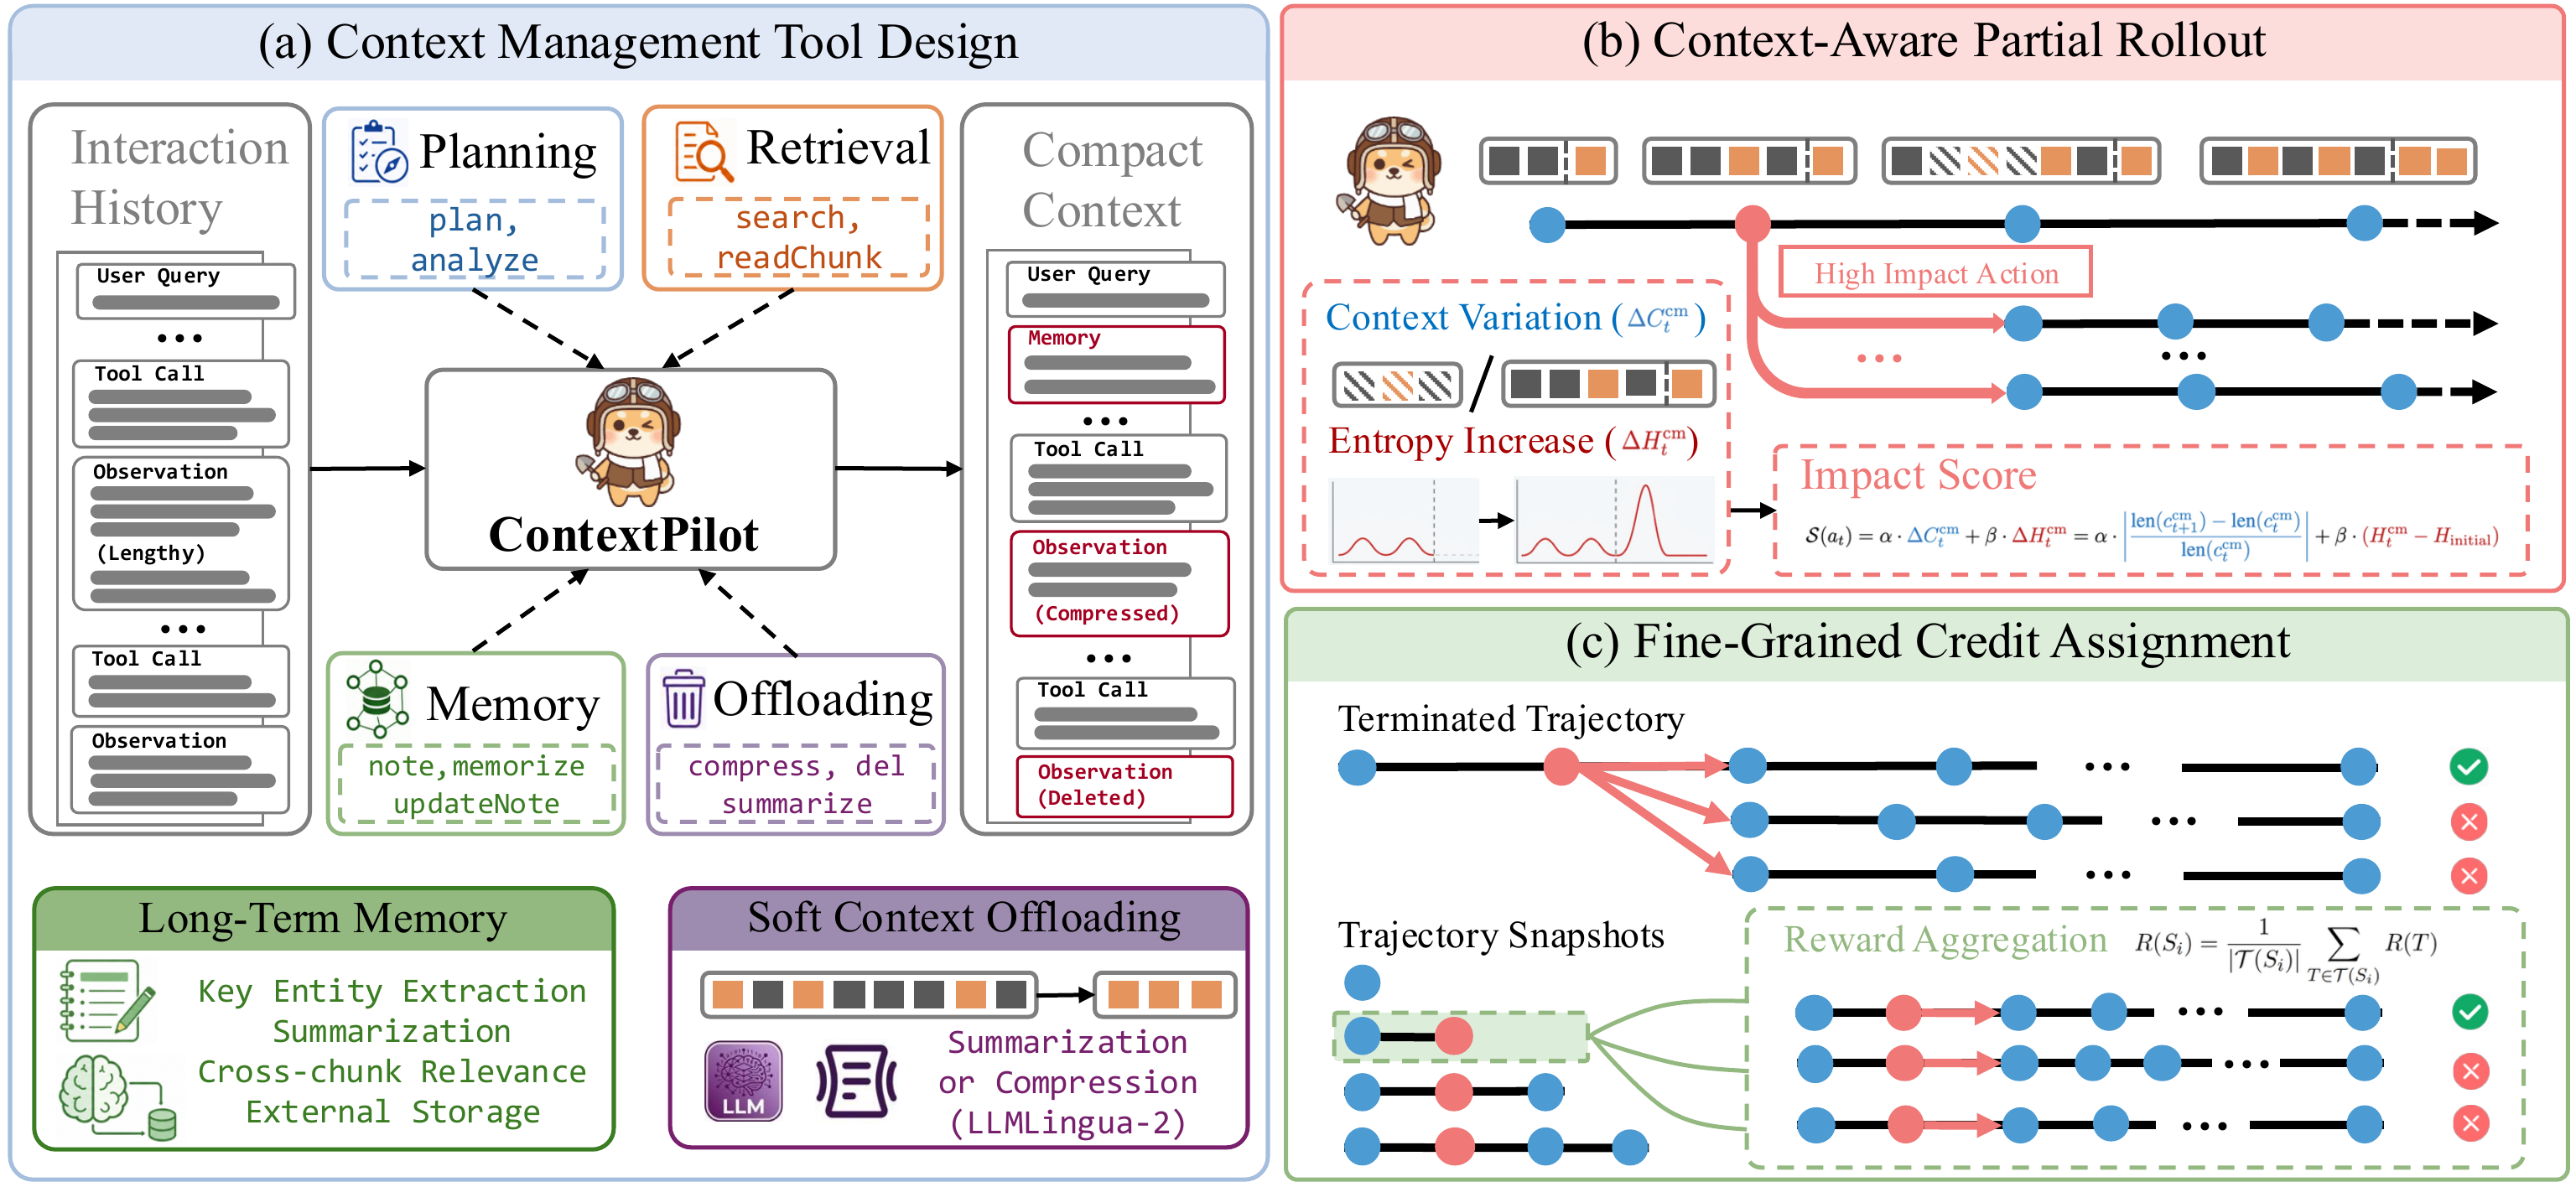
ContextPilot extends context management with planning, structured memory, and
soft context offloading. Its context-aware partial rollout focuses exploration
on sensitive context-editing decisions, while fine-grained credit assignment
trains intermediate snapshots using the outcomes of their downstream
branches.
Experiments on long-context QA and deep search tasks show that ContextPilot
achieves stronger performance with a more compact working context,
outperforming existing baselines across various base models and benchmarks.
Setup
1. Inference environment
Install the inference dependencies with the provided setup script:
bash infer/scripts/setup_environment.sh
source infer/.venv/bin/activate
2. Elasticsearch
ContextPilot's searchEngine tool requires Elasticsearch. The setup script
installs a local Elasticsearch distribution, and the full evaluation launcher
starts it automatically. To run the service separately:
bash infer/scripts/start_elasticsearch.sh3. Judge configuration
LongMemEval and BrowseComp+ use an OpenAI-compatible judge. Store its endpoint
configuration in a JSON file and set:
export JUDGE_OPENAI_FILE=/path/to/judge-endpoint.jsonSee the inference guide for endpoint configuration and other
runtime options.
Evaluation
The evaluation suite covers:
- InfBench: the
longbook_choice_engsplit from
InfiniteBench,
loaded automatically from Hugging Face. - NovelQA: its answer annotations cannot be redistributed. Request full
access from the
NovelQA dataset page. - LongMemEval: the benchmark data is included at
infer/data/LongMemEval/longmemeval_s_cleaned.json. - BrowseComp+: the original obfuscated parquet data is included at
infer/data/BrowseCompPlus/data/. Prepare a local decrypted JSONL with
infer/scripts/prepare_browsecomp_plus.py.
The LongMemEval and BrowseComp+ data files are tracked with Git LFS; after
cloning, run git lfs install && git lfs pull to download them.
Evaluate a checkpoint on all four tasks:
bash infer/scripts/run_full_pipeline.sh /path/to/checkpoint my-runThe pipeline starts the required services, runs each benchmark, and writes
predictions, trajectories, and scores to infer/results/. Individual tasks can
be run with:
bash infer/scripts/eval_infbench.sh /path/to/checkpoint my-run
bash infer/scripts/eval_novelqa.sh /path/to/checkpoint my-run
bash infer/scripts/eval_longmemeval.sh /path/to/checkpoint my-run
bash infer/scripts/eval_browsecomp_plus.sh /path/to/checkpoint my-run
To adapt the runner to another HuggingFace-styled dataset, refer to the dataset
processing and evaluation examples in
GitHub - xyliu-cs/StateLM: [ICLR'26] Official Open-source Implementation of StateLM.
Training
The RL implementation is built on verl and includes context-aware partial
rollout and snapshot-level credit assignment. Set up the training environment
following the training guide, then launch the 8B recipe with:
cd train

TRAIN_FILE=/path/to/train.parquet \
VAL_FILE=/path/to/validation.parquet \
MODEL_PATH=/path/to/qwen3-8b \
GPUS_PER_NODE=8 \
bash sh/run_qwen3-8b_longbenchv2.sh
For Qwen3-14B, use sh/run_qwen3-14b_longbenchv2.sh.
Acknowledgements
ContextPilot builds on the ideas and implementations of StateLM, verl, vLLM,
and the open-source benchmark projects used in the paper. We thank their
authors and maintainers.
Citation
@inproceedings{pan-etal-2026-contextpilot,
    title = "ContextPilot: Teaching Agents for Proactive Context Management via Fine-grained RL",
    author = "Pan, Zhuoshi  and
      Pei, Qizhi  and
      Lu, Junru  and
      Lin, Honglin  and
      Zhao, H. Vicky  and
      Yin, Di  and
      Sun, Xing",
    booktitle = "Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing",
    month = nov,
    year = "2026",
    address = "Budapest, Hungary",
    publisher = "Association for Computational Linguistics",
    abstract = "Long-horizon agentic tasks require large language models (LLMs) to iteratively retrieve, integrate, and maintain dispersed information across multi-turn interactions, but preserving all interaction histories leads to a continuously growing working context. Recent proactive context management methods allow models to edit their own working context with specialized tools, yet they still face three key limitations: (1) a limited toolset restricted to search, deletion, and summarization, with no support for global planning, long-term memory, and adaptive compression; (2) inefficient exploration that treats context management actions uniformly despite their heterogeneous impacts on final outcomes; and (3) coarse-grained credit assignment that assigns the final trajectory-level reward to all intermediate context editing actions during RL. To bridge these gaps, we introduce ContextPilot, a proactive context management framework for long-horizon agentic reasoning. Our approach systematically augments the toolset with planning, long-term memory, and soft context offloading tools. We further propose an RL method tailored for context management, which uses context and entropy variation to identify critical editing decisions for branch sampling and estimates action-level advantages from all branched trajectories that pass through the corresponding context editing action. Experiments on long-context QA and deep search tasks show that ContextPilot achieves stronger performance with a more compact working context, consistently outperforming existing baselines across various base models and benchmarks. Code is available at \url{https://github.com/Tencent/ContextPilot}."
}