

Repository
lca-multibyte
LCA-MBP: Dynamic Multi-Byte Prediction With Hierarchical Language Models Dynamic Multi-Byte Prediction With Hierarchical Language Models Abraham Toluwase Owodunni¹, Chibuzor Okocha · License unknown · Maintenance unknown
- License
- Unknown
- Config
- Model
- modern_fxt_priors_0.3_en_lca_prev_group_self_256_scale_bp_dualhead.yaml
- LCA-MBP (ours)
- modern_fxt_priors_0.3_en_lambda_3_fxt_vanilla_256_scale_bp.yaml
- hierarchical baseline, no MBP head
Specs
- ConfigModel
- modern_fxt_priors_0.3_en_lca_prev_group_self_256_scale_bp_dualhead.yamlLCA-MBP (ours)
- modern_fxt_priors_0.3_en_lambda_3_fxt_vanilla_256_scale_bp.yamlhierarchical baseline, no MBP head
- modern_fxt_baseline_btyes_256_scale_bp_dual.yamlflat byte-level baseline
- Task--dataset_name
- Instruction followingtulu
- Summarizationcnn_dailymail
- Translationopus-100
- --modeWhat runs
- plainone byte per forward pass
- cachedas above, reusing the group KV cache
- self_speculativedrafts with the model's own MBP head, then verifies
- drafterdrafts with a separate model, then verifies
- FileFigure
- paper_misc/MTP_GCA_architecture.xmlFigure 1, the MBP architecture
- paper_misc/MTP_GCA_mask.xmlFigure 2, the Latent Causal Attention mask
README
LCA-MBP: Dynamic Multi-Byte Prediction With Hierarchical Language Models
Code for Dynamic Multi-Byte Prediction With Hierarchical Language Models.
Abraham Toluwase Owodunni¹, Chibuzor Okocha², Christan Grant², Tomasz Limisiewicz³, Sachin Kumar¹
¹The Ohio State University · ²University of Florida · ³University of Washington
Byte-level hierarchical language models avoid subword tokenization, but generating one byte at a
time is slow. Multi-byte prediction (MBP) generates several bytes in parallel with no additional
parameters. Instead of one prediction head per future byte, we use a single multi-byte decoder with
a boundary-aware causal mask — Latent Causal Attention (LCA) — so the prediction window is
variable-length and aligned to the model's own learned byte segments.
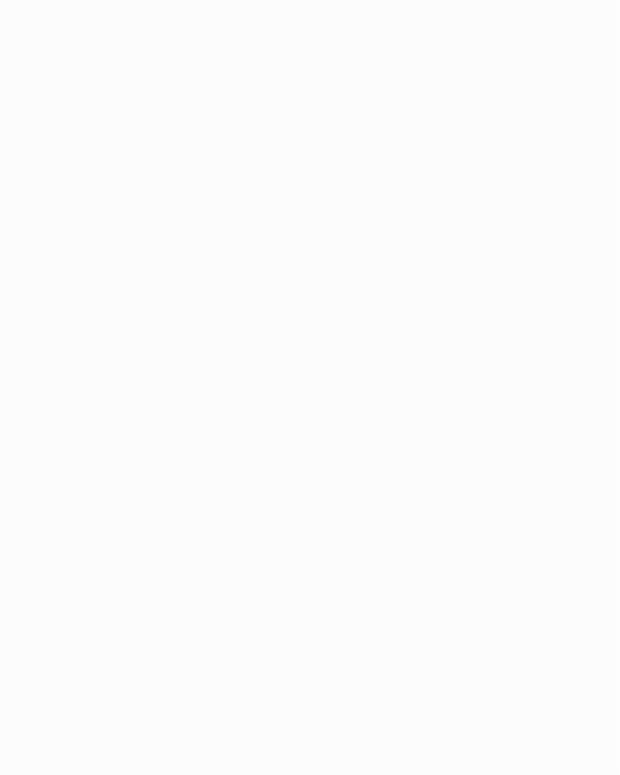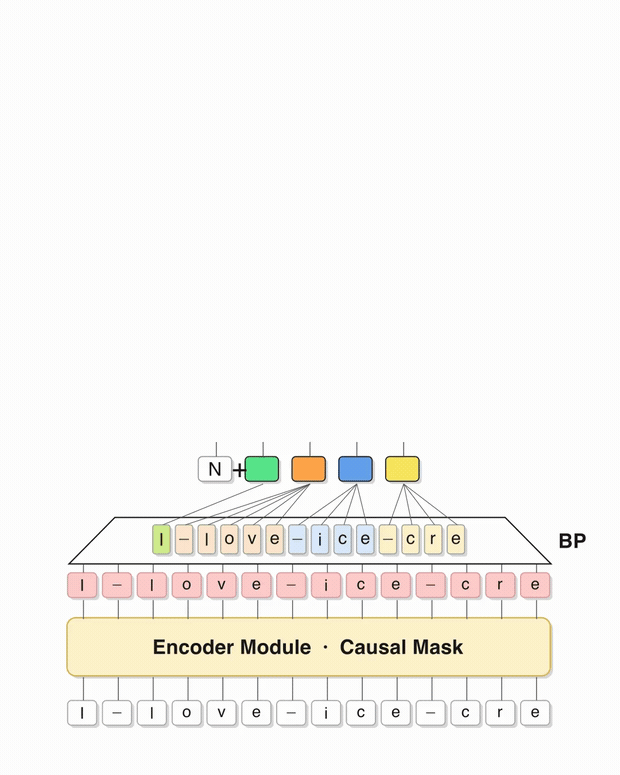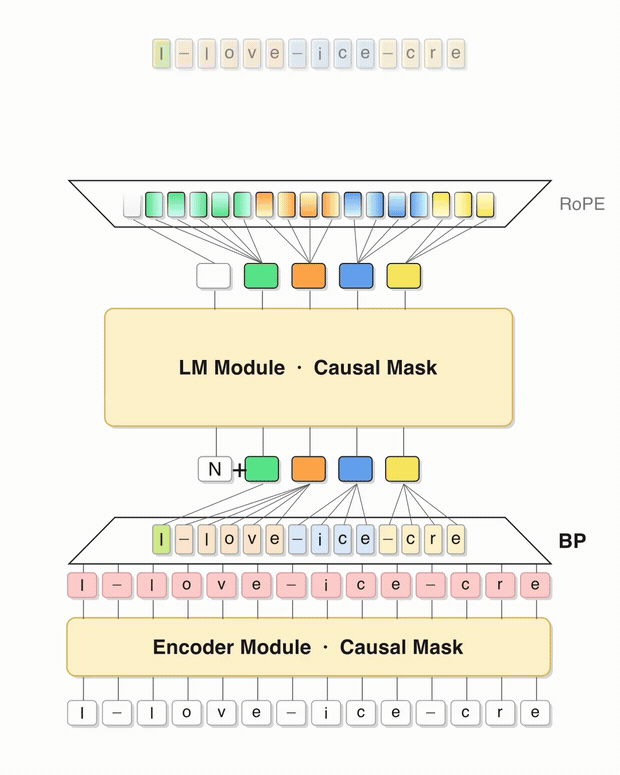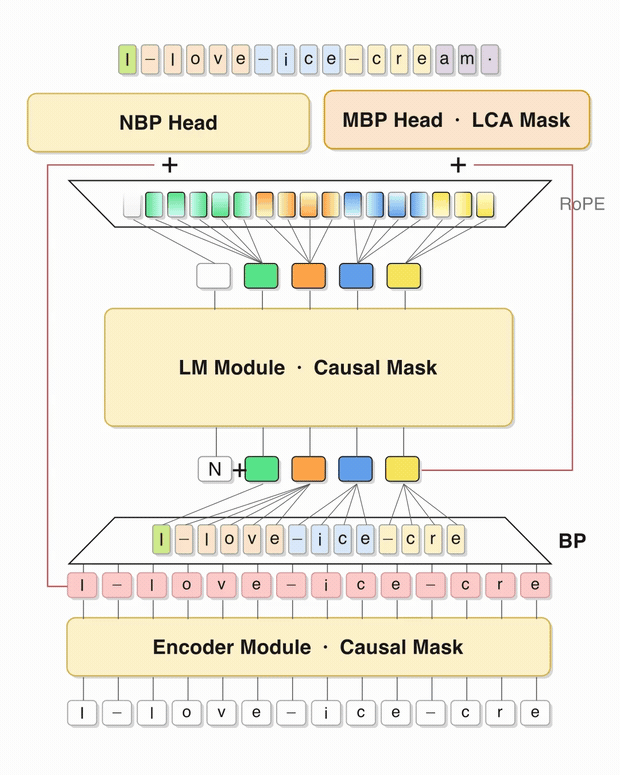
An input byte sequence is encoded, segmented by the boundary predictor, and the MBP head predicts
multiple future bytes in parallel from a single head using the LCA mask:
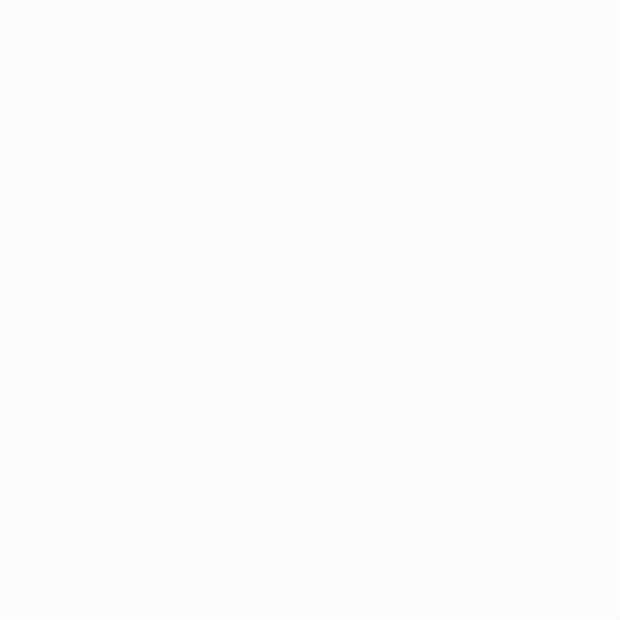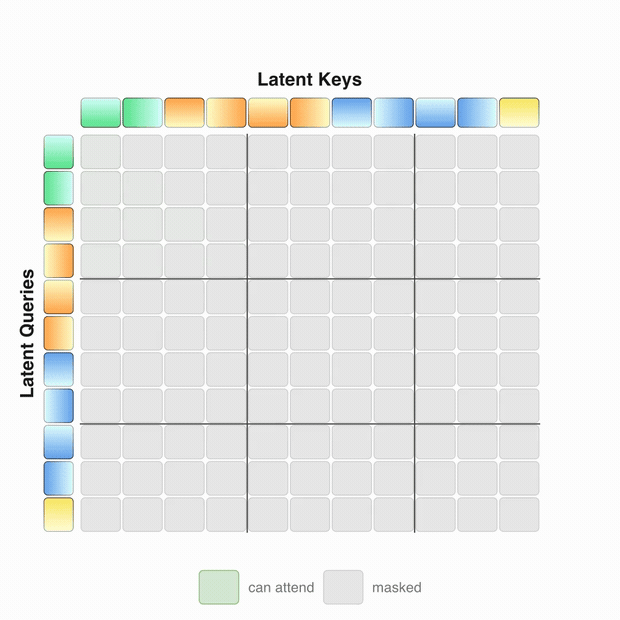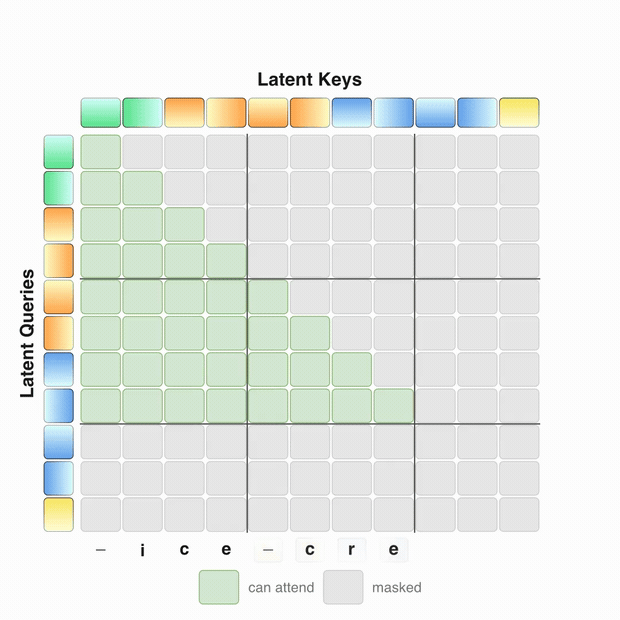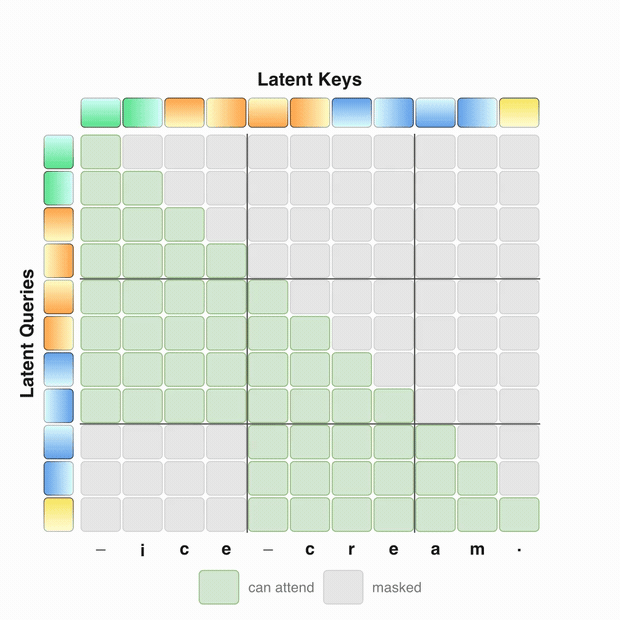
A query byte in segment sᵢ may attend to all bytes in previous segments and to the bytes preceding
it within its own segment — which lets every byte of a predicted segment be generated in parallel
without violating causality.
Setup
Dependencies are managed with uv. Install it, then:
uv sync
export PYTHONPATH=$(pwd)
uv sync creates .venv/ from the pinned uv.lock, so everyone gets the same resolution. Run
anything through uv run — e.g. uv run python src/eval/generate.py ... — and the scripts in
scripts/ already do this.
Data
Pretraining uses FineWeb-Edu
(sample-100BT), pre-shuffled and packaged as parquet shards at
karpathy/fineweb-edu-100b-shuffle.
scripts/download_dataset.sh pulls the shards straight from the Hub:
mkdir -p /path/to/data && cd /path/to/data
bash /path/to/repo/scripts/download_dataset.sh
The script writes into en/, validation/, and test/ relative to the current directory, so
run it from the corpus root you want — that directory is the data: key in configs/train/*.yaml:
<data>/
  train/shard_00000.parquet ...   # training shards, one directory per language
  validation/shard_00xxx.parquet
  test/shard_00xxx.parquet
Edit the shard ranges in the script to control how much data you pull; each shard is roughly 100MB
compressed.
Set load_from_disk: False in the config to stream from the Hub instead of reading local shards.
Pretraining
Set EXP_DIR, CONFIG_FILE, and GPUS at the top of the script, then:
bash scripts/run_train.shscripts/run_train.sh carries a SLURM header; delete it to run on a single machine. Export
WANDB_API_KEY and HF_TOKEN beforehand — the script refuses to start without them, and no
credentials are stored in the repo.
Available configs in configs/train/:
| Config | Model |
|---|---|
modern_fxt_priors_0.3_en_lca_prev_group_self_256_scale_bp_dualhead.yaml |
LCA-MBP (ours) |
modern_fxt_priors_0.3_en_lambda_3_fxt_vanilla_256_scale_bp.yaml |
hierarchical baseline, no MBP head |
modern_fxt_baseline_btyes_256_scale_bp_dual.yaml |
flat byte-level baseline |
The key knobs live in the model and boundaries sections:
model_config—"[pre_layers, (shortened_layers,), post_layers, mbp_layers]". The last entry is
the multi-byte decoder depth;0disables MBP.prior_list/prior_std— the binomial prior per script, which controls the segmentation rate
(bytes per latent token).attn_type—prev_group_selfselects the LCA mask.
SFT
Fill in MODELS with one or more pretrained run directories, set WORK_DIR, then:
bash scripts/run_sft.shDatasets are selected with --dataset_name, using the configs in configs/finetune/:
| Task | --dataset_name |
Config |
|---|---|---|
| Instruction following | tulu |
tulu_sft.yml |
| Summarization | cnn_dailymail |
summarization_sft.yml |
| Translation | opus-100 |
translation_sft.yml |
Generation
All decoding paths go through a single entry point, model.generate(). src/eval/generate.py
exposes them with --mode:
# plain autoregressive decoding
python src/eval/generate.py --model_path CKPT --prompt "The capital of France is" --mode plain

# same, reusing the segment KV cache across steps
python src/eval/generate.py --model_path CKPT --prompt "..." --mode cached

# multi-byte prediction: the MBP head drafts, the model verifies
python src/eval/generate.py --model_path CKPT --prompt "..." --mode self_speculative

# speculative decoding against a separate draft model
python src/eval/generate.py --model_path CKPT --prompt "..." --mode drafter --drafter_path DRAFT_CKPT
--mode |
What runs |
|---|---|
plain |
one byte per forward pass |
cached |
as above, reusing the group KV cache |
self_speculative |
drafts with the model's own MBP head, then verifies |
drafter |
drafts with a separate model, then verifies |
--threshold sets the byte-acceptance probability and --candidates the number of bytes drafted
per step; both apply to the two speculative modes. Every mode reports its acceptance rate.
To see how the model segments text into latent tokens, add --show_tokenization, which prints the
prompt with | at each predicted boundary.
Editing the figures
The architecture and LCA mask diagrams are released as editable .xml files:
| File | Figure |
|---|---|
paper_misc/MTP_GCA_architecture.xml |
Figure 1, the MBP architecture |
paper_misc/MTP_GCA_mask.xml |
Figure 2, the Latent Causal Attention mask |
If you would like to build on this architecture in your own paper, open the .xml file at
app.diagrams.net. Please cite the paper below if you reuse the figures.
Citation
@article{owodunni2026lca,
  title   = {Dynamic Multi-Byte Prediction With Hierarchical Language Models},
  author  = {Owodunni, Abraham Toluwase and Okocha, Chibuzor and Grant, Christan
             and Limisiewicz, Tomasz and Kumar, Sachin},
  year    = {2026},
  journal = {arXiv preprint arXiv:2608.15454},
  url     = {https://arxiv.org/abs/2608.15454}
}