

Repository
v-rubrics
V-Rubrics: Visual Faithfulness via Rubric-Based Reinforcement Learning <strong>Shulin Tian<sup>1,2,*</sup>, Minglun Li<sup>3,*</sup>, Yuhao Dong<sup>1,‡,*</sup>, · License unknown · Install via pip · Maintenance unknown
- License
- Unknown
- Mode
- Credit assignment
- rubric-sequence
- Sequence-level rubric reward
- rubric-prefix
- Prefix-localized rubric credit
Specs
- ModeCredit assignment
- rubric-sequenceSequence-level rubric reward
- rubric-prefixPrefix-localized rubric credit
README
V-Rubrics: Visual Faithfulness via Rubric-Based Reinforcement Learning

<strong>Shulin Tian<sup>1,2,*</sup>, Minglun Li<sup>3,*</sup>, Yuhao Dong<sup>1,‡,*</sup>, Hao Ding<sup>3,*</sup>, Jiarui Yao<sup>4</sup>, Haiwen Diao<sup>1</sup>, Jingkang Yang<sup>1</sup>, Hongyuan Zhu<sup>2</sup>, Ziwei Liu<sup>1</sup></strong><br>
<sup>1</sup>S-Lab, Nanyang Technological University <sup>2</sup>A*STAR <sup>3</sup>Independent Researcher <sup>4</sup>UIUC<br>
<sub>* Equal contribution ‡ Project lead</sub>
🔍 Overview
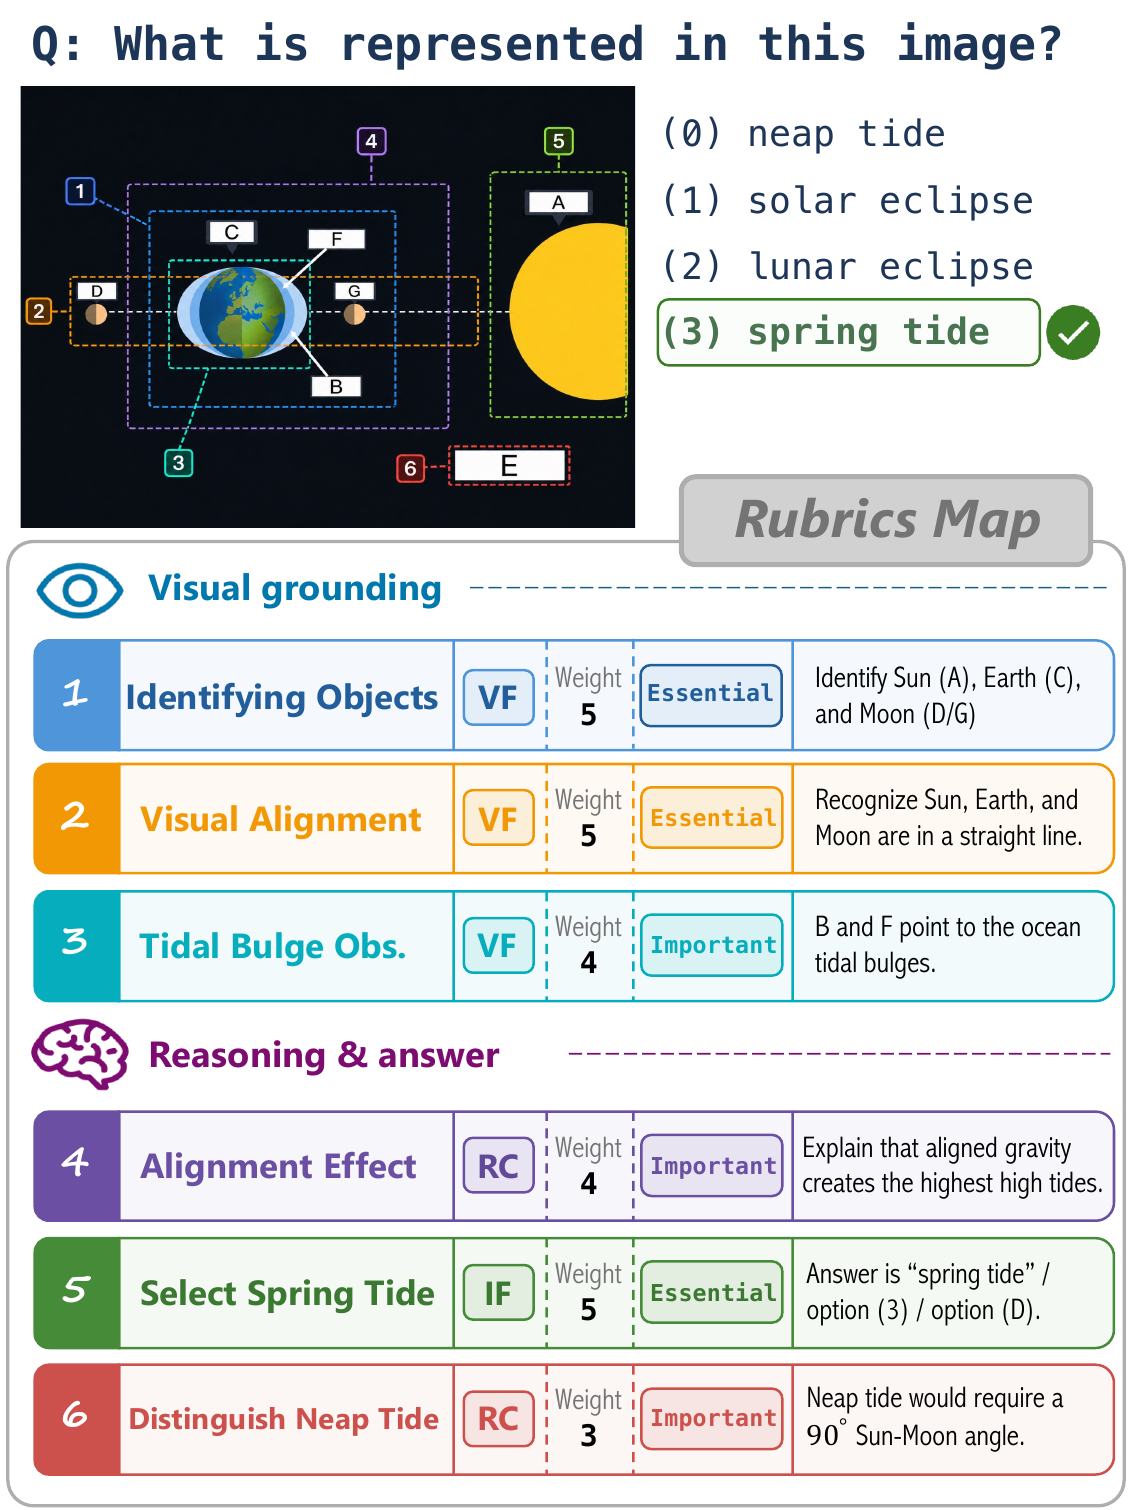
V-Rubrics decomposes visual reasoning responses into atomic criteria for
Visual Faithfulness (VF), Reasoning Consistency (RC), and
Instruction Following (IF). These criteria provide structured rewards for
VLM post-training.
<br>
<sub><strong>Figure 1.</strong> Rubric-grounded visual reasoning.</sub>
🗂️ Repository layout
v-rubrics/
├── src/v_rubrics/       # CLI, data converters, and reward functions
├── training/sft/        # SFT data preparation and LlamaFactory recipe
├── training/rl/         # VERL launcher and training container
├── evaluation/          # Evaluation runner, config, and summarizer
├── environments/        # Core, development, SFT, RL, and evaluation environments
├── third_party/patches/ # Framework integration patches
└── tests/               # Public behavior and release tests
LlamaFactory, VERL, and VLMEvalKit are cloned at pinned revisions when needed;
their source trees are not vendored in this repository.
⚙️ Installation
The data-conversion CLI requires Python 3.11 or newer:
git clone https://github.com/shulin16/v-rubrics.git
cd v-rubrics

python3 -m venv .venv
source .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install -e .

v-rubrics --version
v-rubrics --help
For SFT, RL, or evaluation, create the corresponding environment:
./scripts/environment/create.sh sft
./scripts/environment/create.sh rl
./scripts/environment/create.sh evaluation
These profiles clone the pinned frameworks and apply the required integration
patches. See environments/README.md for Conda, Mamba,
and Micromamba usage.
🗃️ Prepare RL data
Convert a directory of rubric JSONL shards into the VERL training format:
v-rubrics verl prepare \
  --data-dir /path/to/input-shards \
  --output-dir /path/to/verl-data
The merged output is:
/path/to/verl-data/merged_train.parquetUse v-rubrics verl prepare --help for input-field and conversion options.
🎓 Supervised fine-tuning
./scripts/environment/create.sh sft
conda activate v-rubrics-sft

bash training/sft/prepare_openmmreasoner.sh

cd third_party/LlamaFactory
llamafactory-cli train \
  ../../training/sft/configs/qwen3_vl_8b_sft_frozen_vision.yaml
See training/sft/README.md for data paths and recipe
overrides.
🚀 GRPO training
The launcher supports two modes:
| Mode | Credit assignment |
|---|---|
rubric-sequence |
Sequence-level rubric reward |
rubric-prefix |
Prefix-localized rubric credit |
Create the RL environment and provide the required runtime inputs:
./scripts/environment/create.sh rl
conda activate v-rubrics-rl

export TRAIN_FILE=/path/to/verl-data/merged_train.parquet
export VAL_FILE=/path/to/validation.parquet
export HF_MODEL_PATH=/path/to/sft-checkpoint
export V_RUBRICS_JUDGE_URLS=http://judge-0:8000,http://judge-1:8000
export V_RUBRICS_JUDGE_MODEL=your-served-judge-name
Launch either mode from the repository root:
bash training/rl/launchers/paper_grpo.sh rubric-sequence
bash training/rl/launchers/paper_grpo.sh rubric-prefix
See training/rl/README.md for configuration overrides
and optional judge authentication.
📊 Evaluation
./scripts/environment/create.sh evaluation
conda activate v-rubrics-evaluation

python evaluation/run_paper.py \
  --models /path/to/checkpoint \
  --judge-model /path/to/evaluation-judge \
  --output-base ./outputs
See evaluation/README.md or run
python evaluation/run_paper.py --help for benchmark and GPU options.
🧪 Development
./scripts/environment/create.sh dev
conda activate v-rubrics-dev

python -m pytest -q
python -m ruff check .
./scripts/build_release.sh
🙏 Acknowledgments
V-Rubrics builds on
VERL,
LlamaFactory,
VLMEvalKit,
Qwen3-VL, and
OpenMMReasoner.
📝 Citation
@misc{tian2026vrubrics,
  title         = {V-Rubrics: Visual Faithfulness via Rubric-Based Reinforcement Learning},
  author        = {Shulin Tian and Minglun Li and Yuhao Dong and Hao Ding and Jiarui Yao and Haiwen Diao and Jingkang Yang and Hongyuan Zhu and Ziwei Liu},
  year          = {2026},
  eprint        = {2608.25580},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2608.25580}
}
📬 Contact
For questions, contact {shulin002, yuhao013, ziwei.liu}@ntu.edu.sg.
📄 License
First-party source code is released under the
Apache License 2.0. Third-party frameworks and external artifacts
retain their original licenses.