

Repository
llm-stream-reformat
Reformat a live LLM token stream inflight — separate thinking from answer, collapse repetition, normalize. Google Vertex / OpenRouter / meta-llm. Rust + WASM, built on ruvnet/midstream.
- Provider
- Thinking
- Google Vertex ( :streamGenerateContent )
- Google Vertex
- OpenRouter ( /v1/chat/completions )
- OpenRouter
- meta-llm (OpenAI-compatible)
- meta-llm
Specs
- ProviderThinking
- Google Vertex ( :streamGenerateContent )Google Vertex
- OpenRouter ( /v1/chat/completions )OpenRouter
- meta-llm (OpenAI-compatible)meta-llm
README
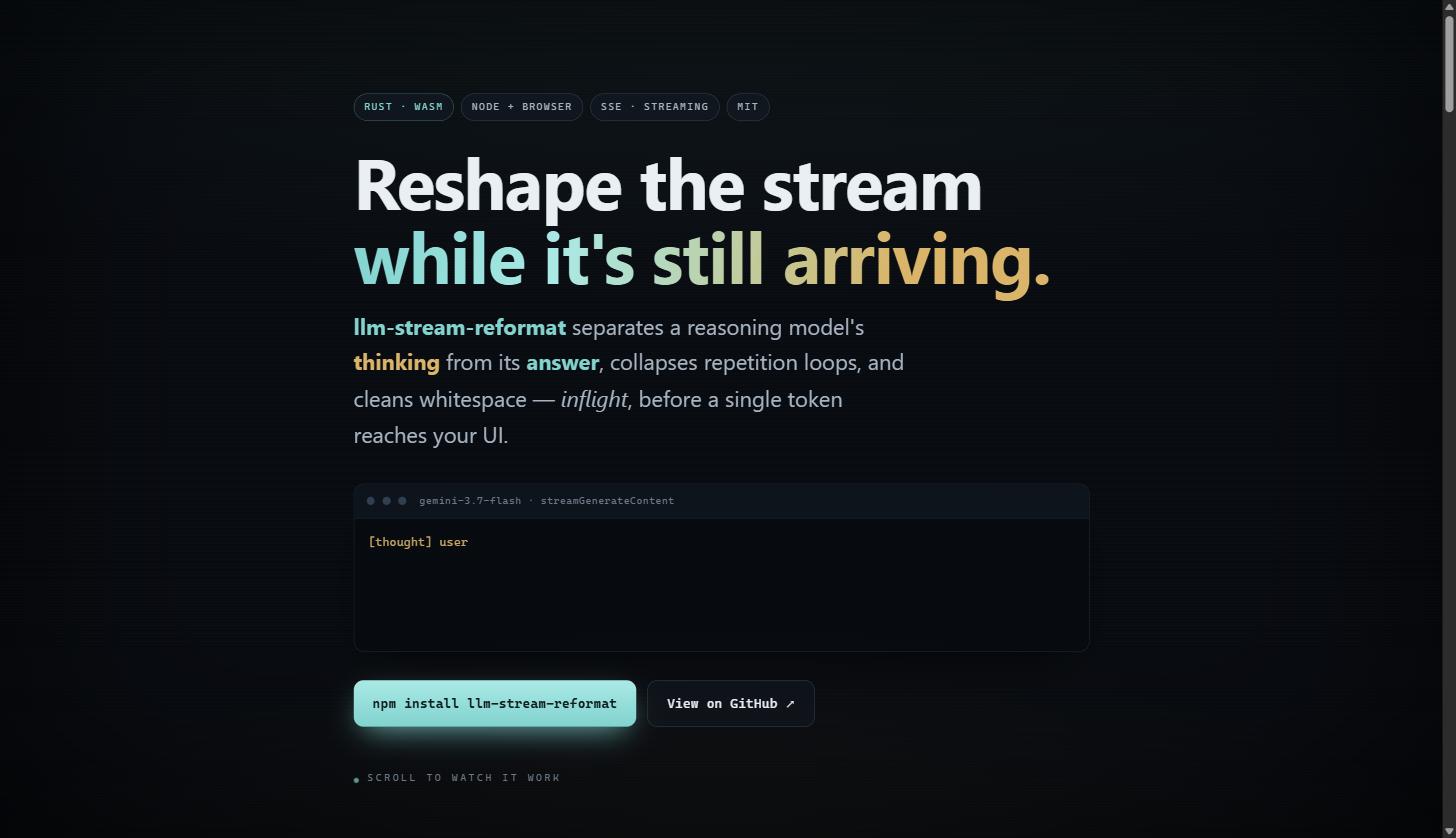 ▶ Open the interactive walkthrough →
An animated, mobile-friendly scroll-through of what happens to the stream.
Most "LLM tooling" treats the response as a black box that opens at the end. This treats it as a stream you can shape per chunk — the
ruvnet/midstreamphilosophy ("pattern-match it, score it, intervene on it — while the tokens are still arriving"). Built on the realmidstreamer-temporal-comparecrate.
What it does
Reasoning models (like gemini-3.7-flash) interleave a hidden thought stream with the answer, stutter into repetition loops, and emit messy whitespace. llm-stream-reformat fixes that in one streaming pass, before the text ever reaches your UI:
- 🧠 Separates thinking from answer — onto distinct channels, so you can show reasoning separately (or hide it).
- 🔁 Collapses near-duplicate repetition — using the real midstream
temporal-compareEditDistance similarity (a common stutter/loop artifact). - ␣ Normalizes whitespace — collapses runs of spaces / blank lines.
- 🔌 Three providers, one model — Google Vertex
parts[].thought, OpenRouterdelta.reasoning, meta-llm/OpenAIdelta.content, normalized to a common chunk stream.
Transform-only: it never fabricates content, and it does not watermark or strip watermarks (see the sibling project ai-text-watermark for provenance marking).
Install
npm install llm-stream-reformat        # Node + browser (WASM)
# or, in Rust:
cargo add stream-reformat
Quick start
Node
const { Reformatter } = require('llm-stream-reformat');

const rf = new Reformatter();
for (const line of sseLines) {              // your provider's raw `data: {...}` lines
  for (const ev of rf.pushSse('google', line)) {
    if (ev.channel === 'thinking') showReasoning(ev.text);
    else appendAnswer(ev.text);
  }
}
rf.finish().forEach(ev => appendAnswer(ev.text));   // flush the last buffered line
Each event is { channel: 'answer' | 'thinking', text: string }. Provider is 'google', 'openrouter', or 'metallm'.
Browser / bundlers
import { init, Reformatter } from 'llm-stream-reformat/web';
await init();                               // auto-fetches the wasm
const rf = new Reformatter();
Rust
use stream_reformat::{Reformatter, Provider, Channel};

let mut rf = Reformatter::new();
for line in sse_lines {
    for ev in rf.push_sse(Provider::Google, &line) {
        match ev.channel { Channel::Thinking => /* … */ (), Channel::Answer => /* … */ () }
    }
}
How it works
provider SSE ──▶ normalize ──▶ inflight pipeline ──▶ {answer | thinking} events
 (Vertex /       to a common     • separate thinking
  OpenRouter /    chunk model     • collapse repeats (temporal-compare)
  meta-llm)                       • normalize whitespace
Provider adapters parse each dialect's data: payload into a neutral StreamChunk { text, kind }; the pipeline buffers answer text by line, whitespace-normalizes each completed line, and drops near-exact repeats detected by midstreamer-temporal-compare's EditDistance similarity. Thinking is routed to its own channel. It's O(1) per chunk and streaming — no buffering the whole response.
Provider wire formats
| Provider | Thinking | Answer |
|---|---|---|
Google Vertex (:streamGenerateContent) |
candidates[].content.parts[] with "thought": true |
other parts[].text |
OpenRouter (/v1/chat/completions) |
choices[].delta.reasoning |
choices[].delta.content |
| meta-llm (OpenAI-compatible) | — | choices[].delta.content |
Design
- ADR-390 — Inflight LLM-stream reformatting via midstream
- ADR-391 — Autogenous: governed self-evolving architecture (the north-star this reformatter is the first observation-layer brick of)
Method & prior art
Built on ruvnet/midstream — "real-time LLM streaming with inflight analysis" — specifically the published midstreamer-temporal-compare crate (DTW/LCS/EditDistance sequence comparison). Note: @midstream/wasm is not yet published; this crate compiles the temporal-compare primitive to WASM directly.
License
MIT © rUv