

Repository
E-CommerceBench
E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation
README
E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation
<a target="_blank" href="https://arxiv.org/abs/2608.30730">
</a>
<a target="_blank" href="#cite">
</a>
<a target="_blank" href="#">

</a>
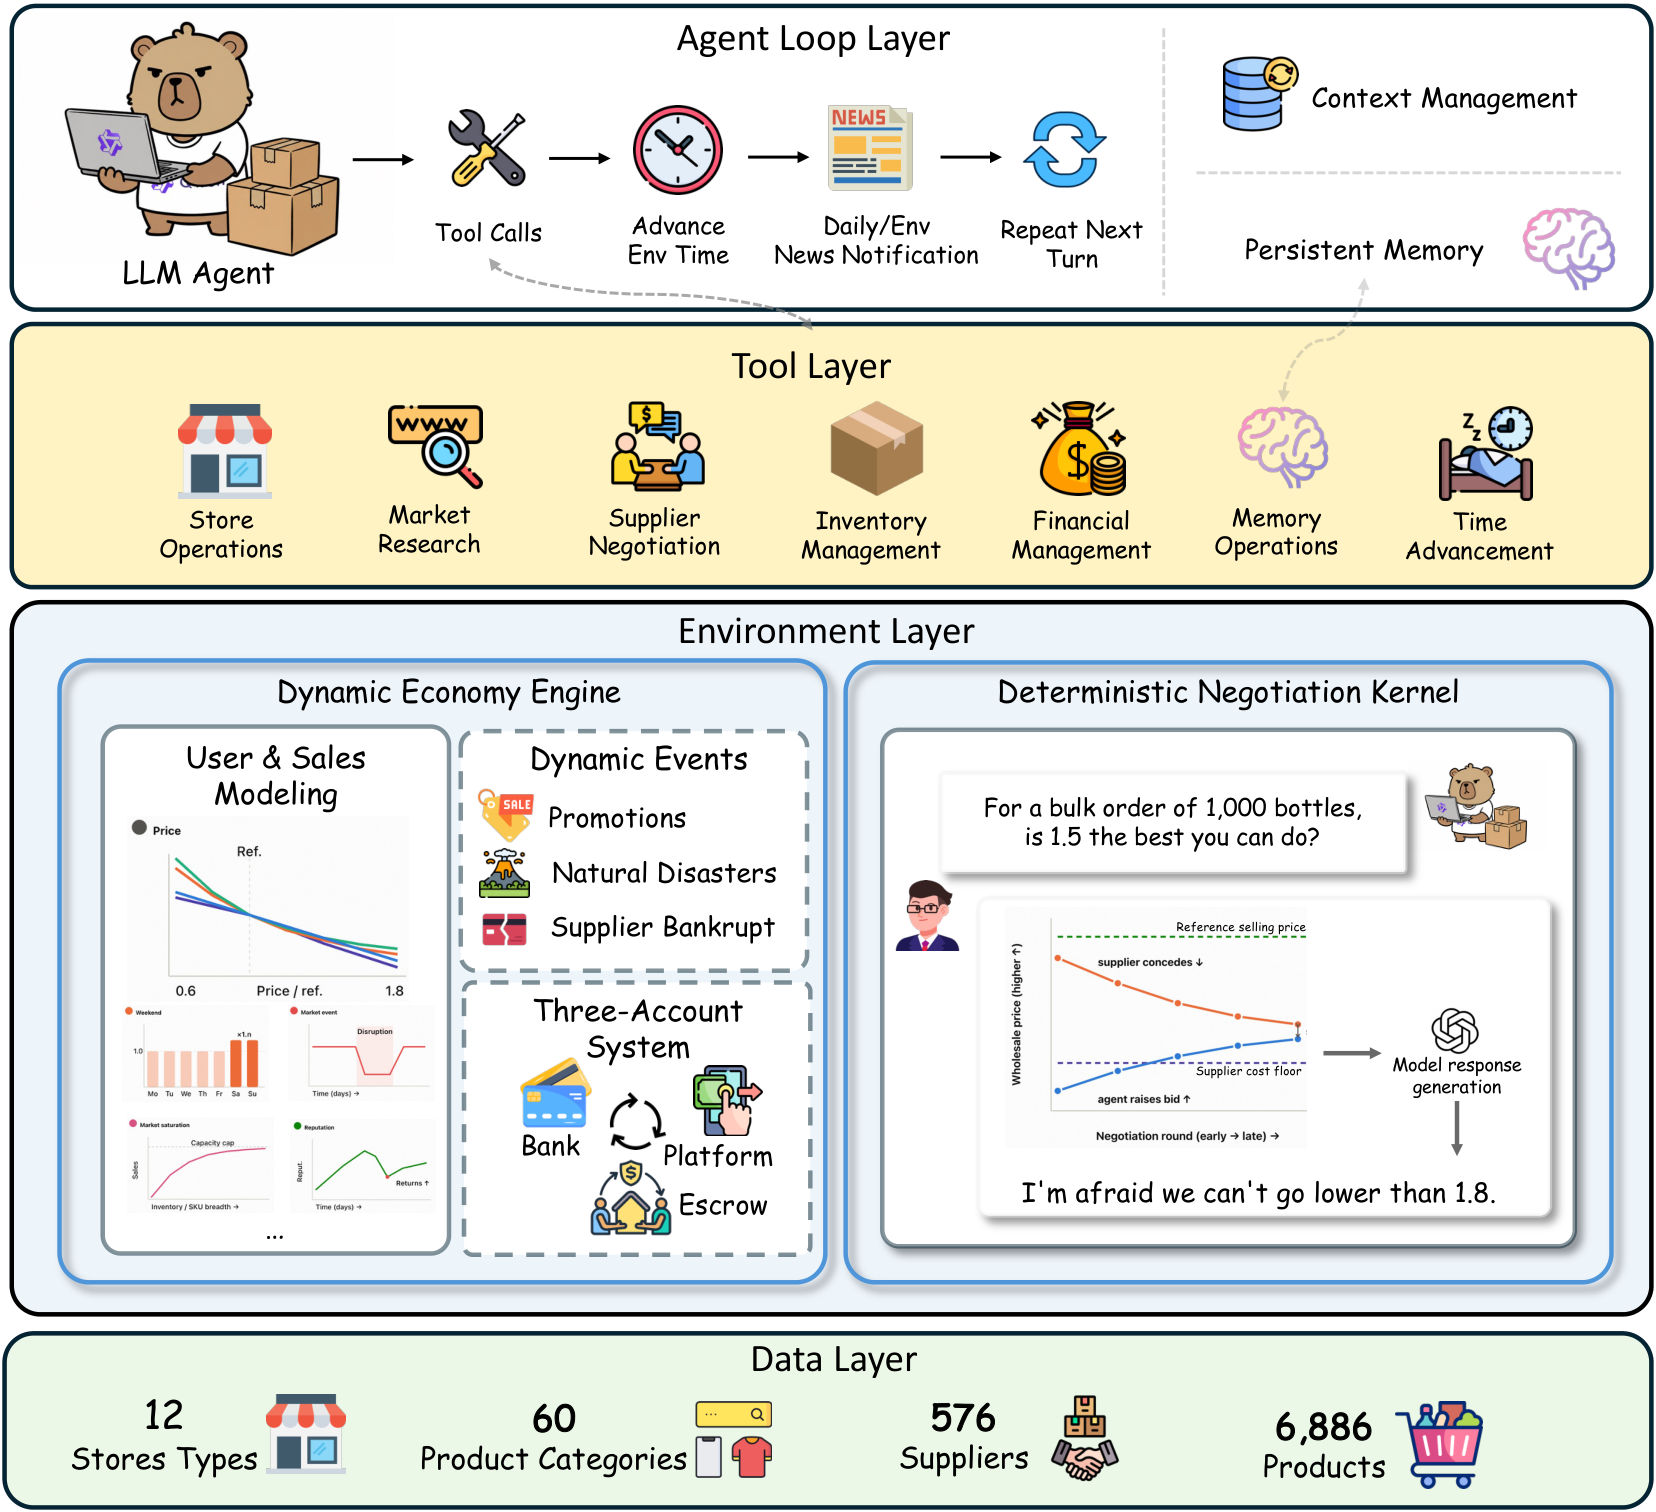
Overview of E-Commerce Bench.
Results
An agent starts with ¥100,000 and runs up to four stores for 365 simulated days.
The primary score is the asset multiplier, end-of-year total assets over the
opening balance, averaged over 5 independent episodes per model.
<style>
.lb-table { border-collapse: collapse; font-size: 13px; width: 100%; margin: 16px 0; }
.lb-table th, .lb-table td { padding: 5px 8px; text-align: right; border-bottom: 1px solid #e0e0e0; }
.lb-table th { background: #f5f5f5; font-weight: 600; text-align: center; border-bottom: 2px solid #ccc; }
.lb-table th:first-child, .lb-table td:first-child { text-align: left; }
.lb-table .tier-row td { background: #fafafa; font-style: italic; font-weight: 600; text-align: left; border-bottom: 1px solid #ccc; }
.lb-table .best { background: #e8f5e9; font-weight: 700; }
.lb-table tr:last-child td { border-bottom: 2px solid #ccc; }
</style>
<table class="lb-table">
<caption style="caption-side:top; text-align:left; font-size:13px; color:#555; margin-bottom:8px;">
<b>Table 1:</b> End-of-year leaderboard, 18 models, five episodes each, sorted by mean final assets within tier.
Tinted cells mark the best scored column. †GPT-5.5's spread is a population estimate, ¥689k on the sample estimator.
‡GPT-5.5's AnchorRatio averages three episodes, its two bankrupt runs opening no repeat order with a supplier it had already dealt with.
</caption>
<thead>
<tr>
<th>Model</th>
<th>Final assets ¥k, mean</th>
<th>std ¥k</th>
<th>CSE⁺ ↑</th>
<th>BadSpend% ↓</th>
<th>Drawdown / peak ↓</th>
<th>¥ per tool call ↑</th>
<th>Controllable return, pp ↓</th>
<th>AnchorRatio ↓</th>
<th>Tool calls</th>
<th>Turns</th>
<th>Bankrupt runs</th>
</tr>
</thead>
<tbody>
<tr class="tier-row"><td colspan="12"><em>Proprietary</em></td></tr>
<tr>
<td>GPT-5.6 Sol (max)</td>
<td class="best"><b>1,431</b></td>
<td>314</td>
<td>0.672</td>
<td>18.48</td>
<td>0.278</td>
<td>363</td>
<td>4.46</td>
<td>1.217</td>
<td>3,668</td>
<td>1,367</td>
<td>0/5</td>
</tr>
<tr>
<td>Fable5 (max)</td>
<td>805</td>
<td>188</td>
<td>0.772</td>
<td>3.46</td>
<td>0.141</td>
<td class="best"><b>479</b></td>
<td>0.22</td>
<td>1.573</td>
<td>1,469</td>
<td>945</td>
<td>0/5</td>
</tr>
<tr>
<td>GPT-5.5</td>
<td>702</td>
<td>616†</td>
<td>0.700</td>
<td>16.59</td>
<td>0.591</td>
<td>192</td>
<td>0.90</td>
<td>1.043‡</td>
<td>3,143</td>
<td>1,306</td>
<td>2/5</td>
</tr>
<tr>
<td>Claude Opus 4.8 (max)</td>
<td>498</td>
<td>231</td>
<td>0.662</td>
<td>5.41</td>
<td>0.130</td>
<td>266</td>
<td>0.20</td>
<td>1.309</td>
<td>1,497</td>
<td>812</td>
<td>0/5</td>
</tr>
<tr>
<td>Claude Opus 4.7 (max)</td>
<td>259</td>
<td>111</td>
<td class="best"><b>0.811</b></td>
<td class="best"><b>0.12</b></td>
<td>0.189</td>
<td>156</td>
<td>1.75</td>
<td>1.421</td>
<td>1,023</td>
<td>432</td>
<td>0/5</td>
</tr>
<tr>
<td>Claude Opus 4.6 (max)</td>
<td>258</td>
<td>266</td>
<td>0.649</td>
<td>14.98</td>
<td>0.587</td>
<td>129</td>
<td>0.76</td>
<td>1.268</td>
<td>1,221</td>
<td>788</td>
<td>2/5</td>
</tr>
<tr>
<td>Gemini 3.5 Flash</td>
<td>190</td>
<td>79</td>
<td>0.777</td>
<td>2.13</td>
<td>0.450</td>
<td>36</td>
<td>0.38</td>
<td>0.918</td>
<td>2,508</td>
<td>2,628</td>
<td>0/5</td>
</tr>
<tr>
<td>Gemini 3.1 Pro</td>
<td>130</td>
<td>130</td>
<td>0.660</td>
<td>12.58</td>
<td>0.688</td>
<td>19</td>
<td>2.03</td>
<td>1.376</td>
<td>1,605</td>
<td>1,141</td>
<td>2/5</td>
</tr>
<tr class="tier-row"><td colspan="12"><em>Open-weight</em></td></tr>
<tr>
<td>Qwen3.8-Max-Preview</td>
<td>416</td>
<td>111</td>
<td>0.713</td>
<td>6.13</td>
<td>0.242</td>
<td>173</td>
<td>0.38</td>
<td class="best"><b>0.834</b></td>
<td>1,826</td>
<td>962</td>
<td>0/5</td>
</tr>
<tr>
<td>GLM 5.2 (high)</td>
<td>301</td>
<td>124</td>
<td>0.693</td>
<td>1.99</td>
<td class="best"><b>0.127</b></td>
<td>137</td>
<td>0.59</td>
<td>1.434</td>
<td>1,467</td>
<td>672</td>
<td>0/5</td>
</tr>
<tr>
<td>Kimi K3</td>
<td>265</td>
<td>110</td>
<td>0.632</td>
<td>5.87</td>
<td>0.247</td>
<td>123</td>
<td>2.01</td>
<td>1.507</td>
<td>1,334</td>
<td>878</td>
<td>0/5</td>
</tr>
<tr>
<td>GLM 5.1</td>
<td>226</td>
<td>192</td>
<td>0.662</td>
<td>6.49</td>
<td>0.231</td>
<td>94</td>
<td>0.09</td>
<td>1.557</td>
<td>1,333</td>
<td>852</td>
<td>0/5</td>
</tr>
<tr>
<td>DeepSeek-V4-Pro-Preview (max)</td>
<td>190</td>
<td>100</td>
<td>0.654</td>
<td>8.99</td>
<td>0.166</td>
<td>68</td>
<td>1.54</td>
<td>1.235</td>
<td>1,337</td>
<td>678</td>
<td>0/5</td>
</tr>
<tr>
<td>Qwen3.7-Max</td>
<td>165</td>
<td>134</td>
<td>0.616</td>
<td>9.85</td>
<td>0.433</td>
<td>59</td>
<td class="best"><b>−0.05</b></td>
<td>1.433</td>
<td>1,108</td>
<td>782</td>
<td>0/5</td>
</tr>
<tr>
<td>GLM 5.2 (max)</td>
<td>115</td>
<td>71</td>
<td>0.632</td>
<td>19.68</td>
<td>0.360</td>
<td>10</td>
<td>2.24</td>
<td>1.362</td>
<td>1,430</td>
<td>931</td>
<td>0/5</td>
</tr>
<tr>
<td>Kimi K2.6</td>
<td>70</td>
<td>14</td>
<td>0.596</td>
<td>17.22</td>
<td>0.377</td>
<td>−27</td>
<td>0.42</td>
<td>1.548</td>
<td>1,087</td>
<td>1,017</td>
<td>0/5</td>
</tr>
<tr>
<td>Qwen3.6-Plus</td>
<td>47</td>
<td>28</td>
<td>0.625</td>
<td>10.68</td>
<td>0.583</td>
<td>−40</td>
<td>3.03</td>
<td>1.333</td>
<td>1,325</td>
<td>1,023</td>
<td>0/5</td>
</tr>
<tr>
<td>Qwen3.5-Plus</td>
<td>1.1</td>
<td>11</td>
<td>0.625</td>
<td>20.11</td>
<td>0.979</td>
<td>−92</td>
<td>5.88</td>
<td>1.860</td>
<td>1,076</td>
<td>800</td>
<td>4/5</td>
</tr>
</tbody>
</table>
Metrics: CSE⁺ = share of the bargaining range captured on honest deals.
BadSpend% = procurement cash reaching fraudulent suppliers. AnchorRatio = what
a repeat order pays above the agent's own best price with that supplier, over
what a random ordering of the same prices would have cost; below 1 means the
agent's ordering helped it.
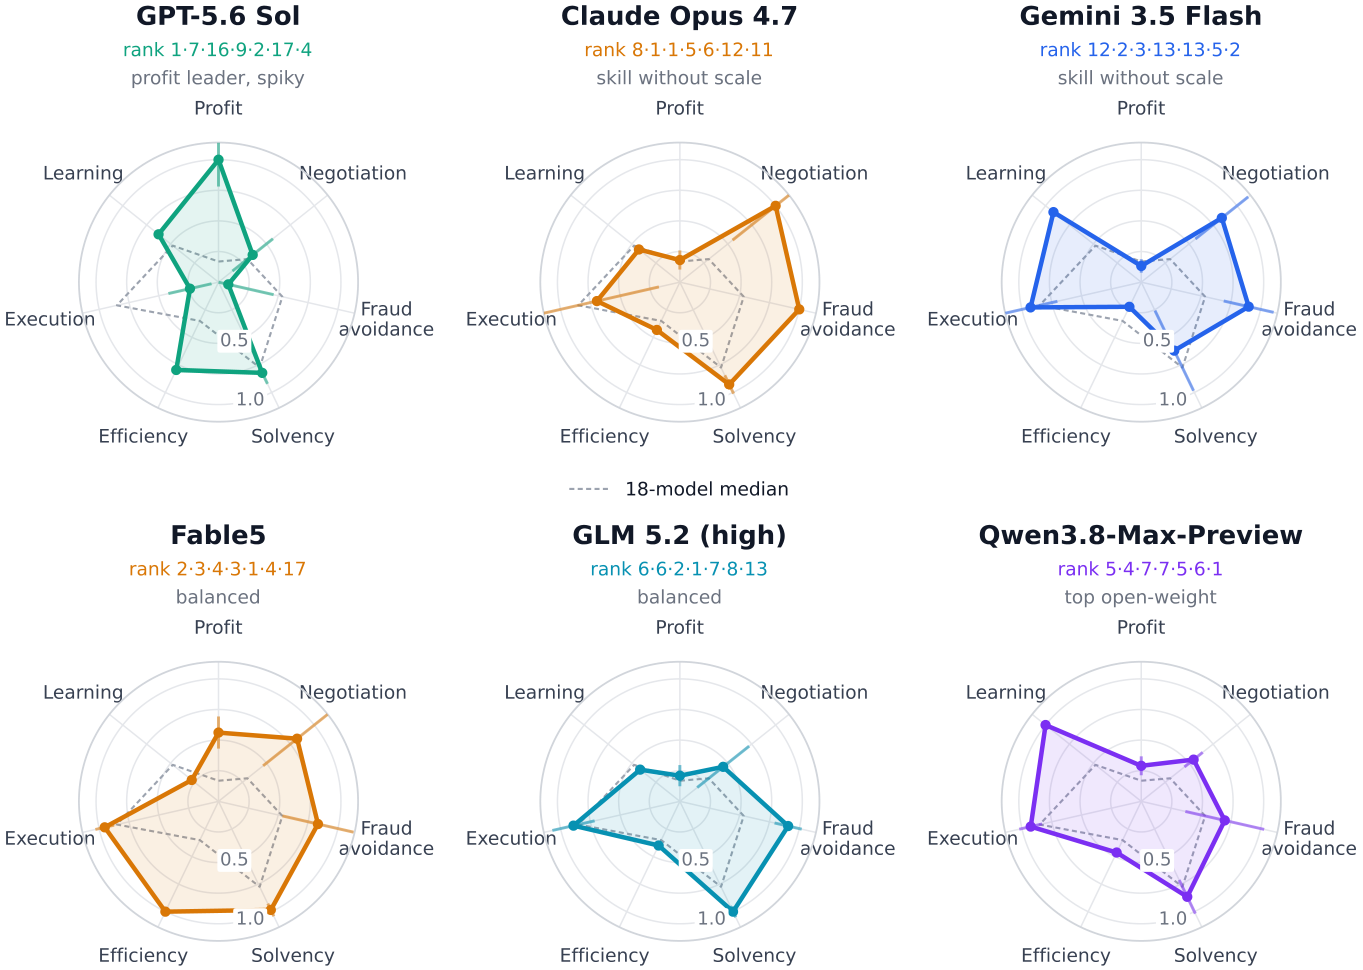
Capability profiles for six of the 18 models. The primary score and the six dimensions run clockwise from the top: profit (mean end-of-year total assets), negotiation (CSE⁺), fraud avoidance (BadSpend%), solvency (drawdown over peak total assets), efficiency (profit per tool call), execution (controllable return rate) and learning (AnchorRatio). Fraud avoidance, solvency, execution and learning are sign-flipped so that higher is better on every axis. Each axis is min-max normalized over the 18 model means, with whiskers over the five episodes and a dashed polygon at the median. No profile fills the polygon.
The rankings diverge across dimensions. The model that ends the year with the
most assets captures a smaller share of each bargaining range than four models
below it, and routes 18.5% of its procurement spend to fraudulent suppliers
against 0.12% for the most cautious. Final assets alone therefore say little
about how an agent got there, which is why the suite reports the axes separately.
Overview
E-Commerce Bench is a 365-day continuing task. The agent plays a merchant,
"Wang Wang", opening up to four online stores, sourcing inventory by negotiating
with suppliers, pricing and stocking products, fulfilling orders and handling
returns, with one objective: maximize end-of-year assets.
What makes the horizon bite is that nothing resets. Cash spent on inventory is
gone until customers pay and escrow settles nine days later; a supplier that
overcharged in March is the same supplier in November; and the context window
overflows long before day 365, so the agent has to decide what is worth
remembering.
Both sides of the market are deterministic, so an outcome difference is
attributable to the agent rather than to the environment:
- Demand follows a fixed multi-factor model over data desensitized from a
real e-commerce platform: 6,886 products, 60 categories, 12 store types, a
year-long calendar of promotions and market shocks. - Suppliers decide every price through a deterministic negotiation kernel,
seeded per (supplier, SKU, cycle). An LLM only renders that decision into
dialogue and is not permitted to change it, so no amount of eloquence talks a
supplier below its floor. Of 576 suppliers, 152 are fraudulent and run one of
five scam patterns, undetectable from price alone by construction.
Environment Setup
Install dependencies
pip install -r requirements.txtSet a key for the provider whose model you want to run, plus
OPENAI_API_KEY for the supplier NPC (see below).
export OPENAI_API_KEY=sk-...        # provider: openai, and the NPC
export ANTHROPIC_API_KEY=sk-ant-... # provider: anthropic
export GEMINI_API_KEY=...           # provider: google
export DASHSCOPE_API_KEY=...        # Qwen
export ZHIPU_API_KEY=...            # GLM
export MOONSHOT_API_KEY=...         # Kimi
export DEEPSEEK_API_KEY=...         # DeepSeek
Experiment Configuration
models_config.json holds the 18 models of the leaderboard above, each at the
reasoning effort it was evaluated with. Pass an entry key to --model:
openai      gpt-5.6-sol · gpt-5.5
anthropic   claude-fable-5 · claude-opus-4-8 · claude-opus-4-7 · claude-opus-4-6
google      gemini-3.5-flash · gemini-3.1-pro
dashscope   qwen3.8-max-preview · qwen3.7-max · qwen3.6-plus · qwen3.5-plus
zhipu       glm-5.2-high · glm-5.2-max · glm-5.1
moonshot    kimi-k3 · kimi-k2.6
deepseek    deepseek-v4-pro
The paper's runs reached these models through an internal gateway; the entries
name the same models at their providers' public endpoints. Requests send no
temperature or top_p, and thinking is enabled wherever the family supports it.
To add a model of your own, see
docs/model_providers.md.
npc_tools is a second, separate model — the supplier's role-play voice, by
default gpt-4o-mini. It only renders dialogue into natural language: every
price and accept/reject decision comes from the deterministic kernel, which the
renderer cannot override, so it does not affect the economics. Point it at any
cheap model you have a key for.
Running Experiments
python run.py --model gemini-3.5-flash --max-days 10 --max-turns 50   # smoke test, minutes
python run.py --model gemini-3.5-flash                               # full 365-day episode
python run.py --model gemini-3.5-flash --runs 5                      # 5 parallel episodes
bash run.sh                                                          # wrapper: live plots, timestamped log dir
Useful flags: --max-days, --max-turns, --runs, --initial-balance,
--max-token-capacity, --log-dir. Each run writes to
log/<timestamp>_<model>/ with per-day balances, negotiation metrics, and full
message transcripts.
Analysis of a finished run:
python evaluation/plot_daily_balance.py log/<session>/run_*_daily_balance.csv --output-dir log/<session>/
python evaluation/extract_chatbox.py log/<session>/run_0_messages.jsonl   # per-supplier dialogue
Repository Structure
agent/            turn-based agent loop, LLM client, provider presets, prompts
context_manager/  token-counted context editing for episodes that overflow
tools/            the 18 tools the agent acts through
  opponent/       negotiation: kernel, per-(supplier,SKU) instances, fraud, metrics
data/             products, suppliers, categories, events, promotions
evaluation/       plotting and log-analysis scripts
docs/             model_providers.md — how to configure a model
License
Released under the Apache License 2.0. See LICENSE.
Cite
If you find this benchmark useful, please cite:
@misc{fan2026ecommercebenchevaluatingllm,
  title         = {E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation},
  author        = {Wei Fan and Xinjie Shen and Xudong Guo and Jianhong Tu and Yang Su and Yinger Zhang and Lianghao Deng and Fengyu Wang and Baohua Dong and Yangqiu Song and Dayiheng Liu},
  year          = {2026},
  eprint        = {2608.30730},
  archivePrefix = {arXiv},
  primaryClass  = {cs.LG},
  url           = {https://arxiv.org/abs/2608.30730}
}