

- measurement
- result
- gold-article recall — the paper's metric, on the paper's corpus
- 0.50 vs 0.15 published for the paper's BM25 baseline (0.21 for our reproduction of it)
- paired gain from adding serviette to gpt-5, paper's protocol
- +5.2 pp over the same model without retrieval (McNemar z = 4.1, 824 questions)
- adaptive retrieval in the grounded (context-only) regime
- 41.3% → 52.8% (z = 7.5) — the largest single effect measured
Specs
- measurementresult
- gold-article recall — the paper's metric, on the paper's corpus0.50 vs 0.15 published for the paper's BM25 baseline (0.21 for our reproduction of it)
- paired gain from adding serviette to gpt-5, paper's protocol+5.2 pp over the same model without retrieval (McNemar z = 4.1, 824 questions)
- adaptive retrieval in the grounded (context-only) regime41.3% → 52.8% (z = 7.5) — the largest single effect measured
- absolute accuracy (permissive, gpt-5)73.7% — above every number in the paper, including its 5-step agent (66.0%) and oracle (72.9%)
- formatparsed by default with
- text / Markdownas-is
- PDFpypdf — built in ; serviette[docling] upgrades to Docling (layout-aware, tables)
- Office (DOCX, PPTX, XLSX, HTML, EML…)Unstructured — built in ; serviette[docling] widens coverage (EPUB, legacy formats)
- scanned images (PNG, JPG, TIFF…)PaddleOCR
- audio (MP3, WAV…)Whisper
- video (MP4, WebM, MOV…)TwelveLabs Pegasus — a searchable text description of the video
- BackendTest
- DuckDBtest_integration_duckdb.py
- pgvectortest_integration_pgvector.py
- Milvustest_integration_milvus.py
- Qdranttest_integration_qdrant.py
- ChromaDBtest_integration_chroma.py
- Weaviatetest_integration_weaviate.py
- Pineconetest_integration_pinecone.py
- MongoDBtest_integration_mongodb.py
README
serviette
A universal, no-code, always up-to-date RAG server for any vector database
— powered by the Pathway Live Data Framework.
Set up Retrieval-Augmented Generation over your own documents without writing
any code. Point serviette at a folder, pick a vector database and an embedder in
a YAML file, and run a few commands. From then on, any change you make to the
documents — an edit, a new file, a deletion — is reflected in answers within
seconds.
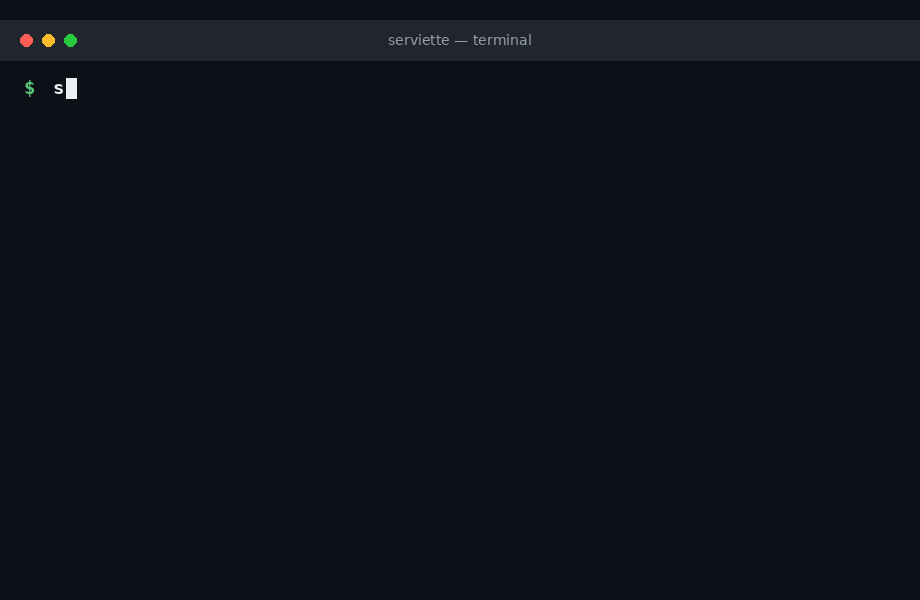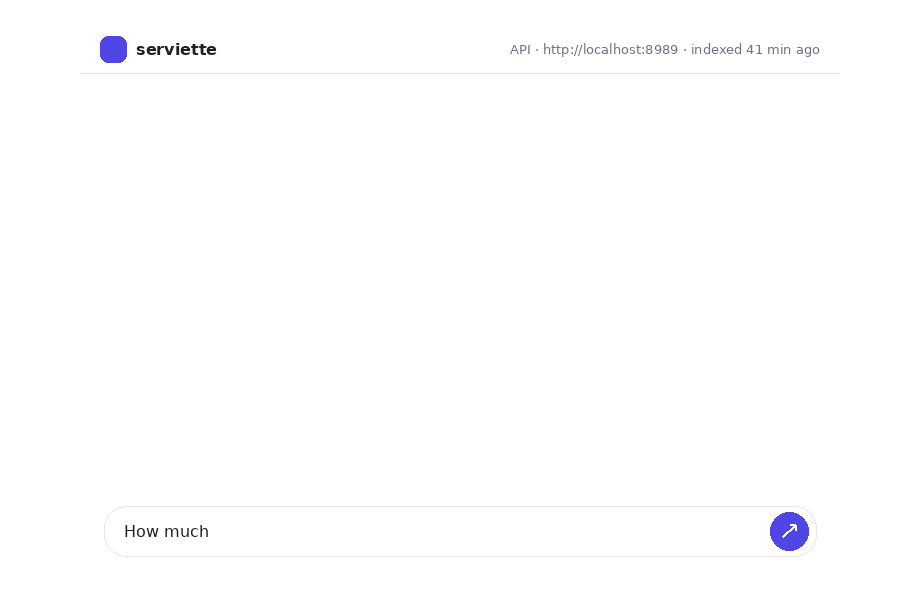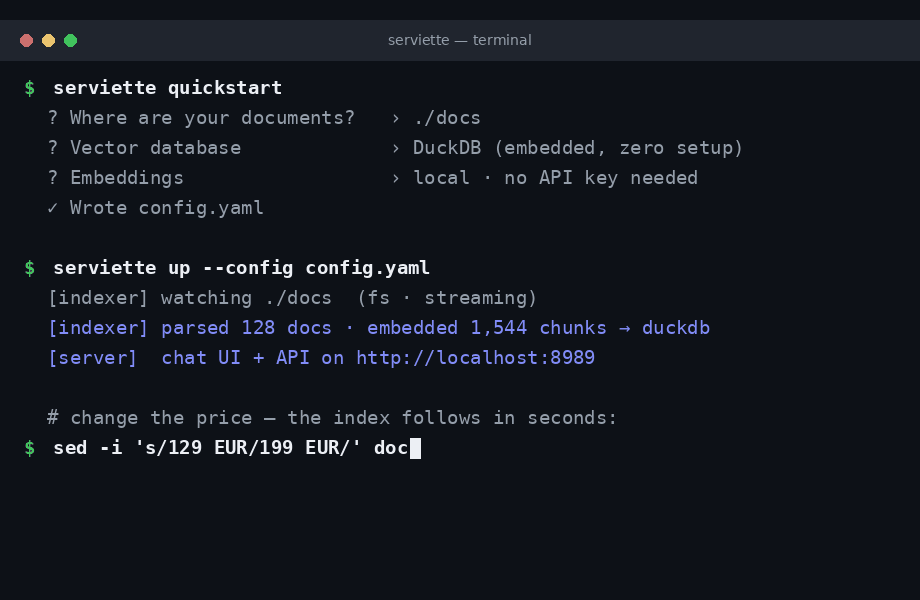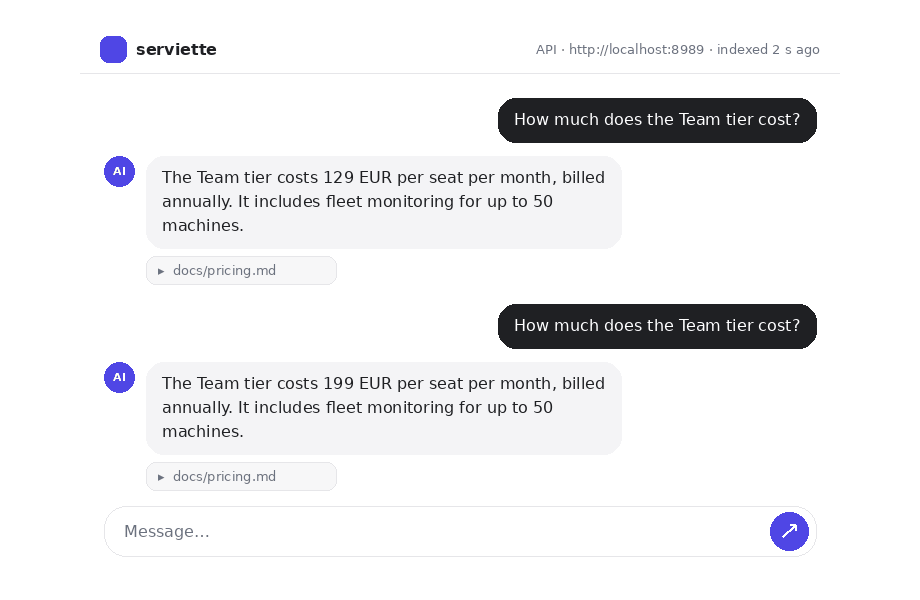
From zero to a live RAG stack in two commands — then edit a document and watch the answer change.
pip install serviette
export OPENAI_API_KEY=sk-...   # powers generated answers; omit to run keyless (answers quote the retrieved snippets)

serviette quickstart                       # interactive config wizard
serviette up --config config.yaml          # indexer + server together → http://localhost:8989
(Or start with serviette demo — a zero-setup playground on a bundled
corpus: it copies everything into ./serviette-demo/docs, and any files you
drop there while it runs are answerable within seconds. Production
deployments run serviette indexer and serviette server separately —
that is what up supervises.)
The server hosts both the web chat UI (on /) and the versioned REST API
(under /api/v1) on one port:
curl -X POST http://localhost:8989/api/v1/retrieve \
  -H 'Content-Type: application/json' \
  -d '{"query": "how does persistence work?", "k": 5}'
Highlights
- No code. Configure everything in one YAML file (or generate it with
serviette quickstart). - Any vector DB — 8 backends. DuckDB (embedded, zero setup — the default),
pgvector, Qdrant, Milvus, ChromaDB, Weaviate, Pinecone and MongoDB Atlas
Vector Search. Every backend is written through Pathway's native
connectors, so file edits and deletions become real upserts/deletes in
the store. - Zero-setup default. DuckDB is the default backend: an embedded
database in a single local file, no external service to install or run,
with built-in vector search. - Live & incremental. Built on Pathway: additions, edits and deletions
are reflected in the vector DB in real time — whatever you change is
answerable seconds later. Documents flow through the pipeline instead of
accumulating in it, so a large corpus stays small in memory. - Multiple sources. Local filesystem, Google Drive, S3/MinIO, SharePoint
— plus anything the PyFilesystem library opens: FTP, SFTP, WebDAV, even ZIP
archives. All watched live, mixed freely in one config. - Multimodal out of the box. Text, Office documents, PDFs (with tables
and layout), scanned images — and, with the corresponding API keys, audio
recordings and even video. Every format is on by default and routed to the
best parser that needs no API key; drop a file in the folder and it is
answerable like any document. See Multimodality. - Reuses Pathway's LLM xpack. Parsers, splitters and embedders are used
as-is — serviette implements none of its own. Five embedder families (OpenAI,
LiteLLM, SentenceTransformers, Gemini, Bedrock) work identically on the
indexer and the server side — including a fully local, credential-free
stack with local embeddings + DuckDB. - Decoupled & scalable. Indexer and API server are independent processes
sharing only the vector DB. The server is stateless and scales
horizontally; the indexer shards across worker processes with one config
line. Every part scales on its own. - Web chat UI, same port.
serviette serverserves a clean
ChatGPT/Claude-style chat page on/next to the versioned API
(/api/v1/...) — same origin, no CORS, nothing extra to run. For split
deployments (UI on a different host) there is a standalone
serviette frontendproxy tier. - Free Pathway license. One click at
https://pathway.com/framework/get-license.
Architecture
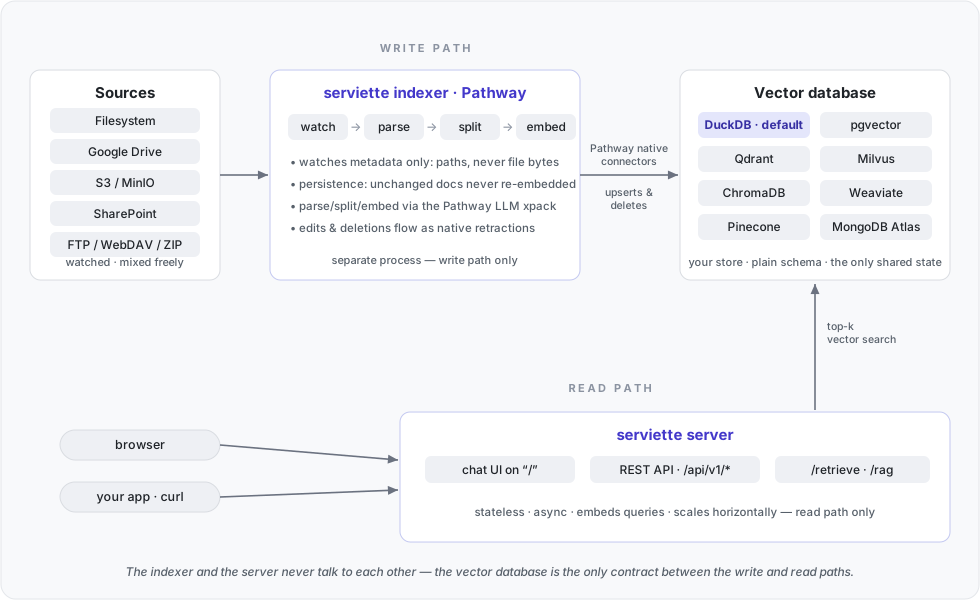
The two halves are fully decoupled. The indexer (write path) and the
server (read path) are separate processes — different executables that never
talk to each other. Their only contract is the vector database itself:
- Independent scaling. The server is stateless and read-only — run any
number of instances behind a load balancer; each also serves the chat UI at
zero cost. The indexer scales separately: Pathway shards it across worker
processes (indexer.workers: 8is how the benchmarks below run), so every
part of the stack scales independently. Bulk re-indexing never slows down
query serving, and query spikes never stall indexing. - Failure isolation. If the indexer is down, serving continues over the
last-synced data; if the server is down, indexing keeps the database fresh.
Either side can be restarted or upgraded independently (the indexer resumes
from its persistence without re-embedding). - The database stays yours. Vectors live in your store in a plain,
documented schema — other consumers (BI, other apps, a different retrieval
stack) can read the same collection; serviette doesn't hold it hostage. And
since the default store is an embedded DuckDB file, trying this out costs
nothing to set up. - Optional third tier. For split deployments (UI on a different host than
the API) a standaloneserviette frontendserves the same chat page and
proxies to the API server-side.
The one deliberate exception: the embedded DuckDB backend trades this
distribution for zero setup — one local file, single-writer, ideal for
laptops and demos (see docs for its concurrency note).
Benchmarks
Two self-contained benchmarks, one per axis: what indexing costs in time
and memory, and how accurate the retrieval is.
Indexing resources
Self-contained benchmark (docker-compose: Qdrant + indexer + server, fully
local embeddings, zero API cost) over a Wikipedia corpus of plain text —
every byte below is extracted text (a PDF collection with the same text
content would weigh several times more) —
see benchmarks/realtime-data-indexing:
| corpus | ≈ pages | files | chunks | indexing time | peak memory (PSS) | in Qdrant |
|---|---|---|---|---|---|---|
| 100 MB | 52 000 | 12 969 | 66 136 | 39 s | 6.6 GB | 0.6 GB |
| 1 GB | 524 000 | 240 516 | 836 595 | 4.8 min | 6.9 GB | 2.2 GB |
| 3 GB | 1 573 000 | 841 890 | 2 703 850 | 15 min | 7.3 GB | 6.0 GB |
| 10 GB | 5 243 000 | 3 423 359 | 10 093 514 | 58 min | 7.7 GB | 20.8 GB |
| 30 GB | 15 729 000 | 9 202 620 | 29 817 294 | 2.9 h | 10.1 GB | 61.3 GB |
| 50 GB | 26 214 000 | 17 083 603 | 53 913 774 | 5.5 h | 13.1 GB | 107.9 GB |
Documents flow through the pipeline rather than accumulating in it, so
what stays in memory is short and worth spelling out.
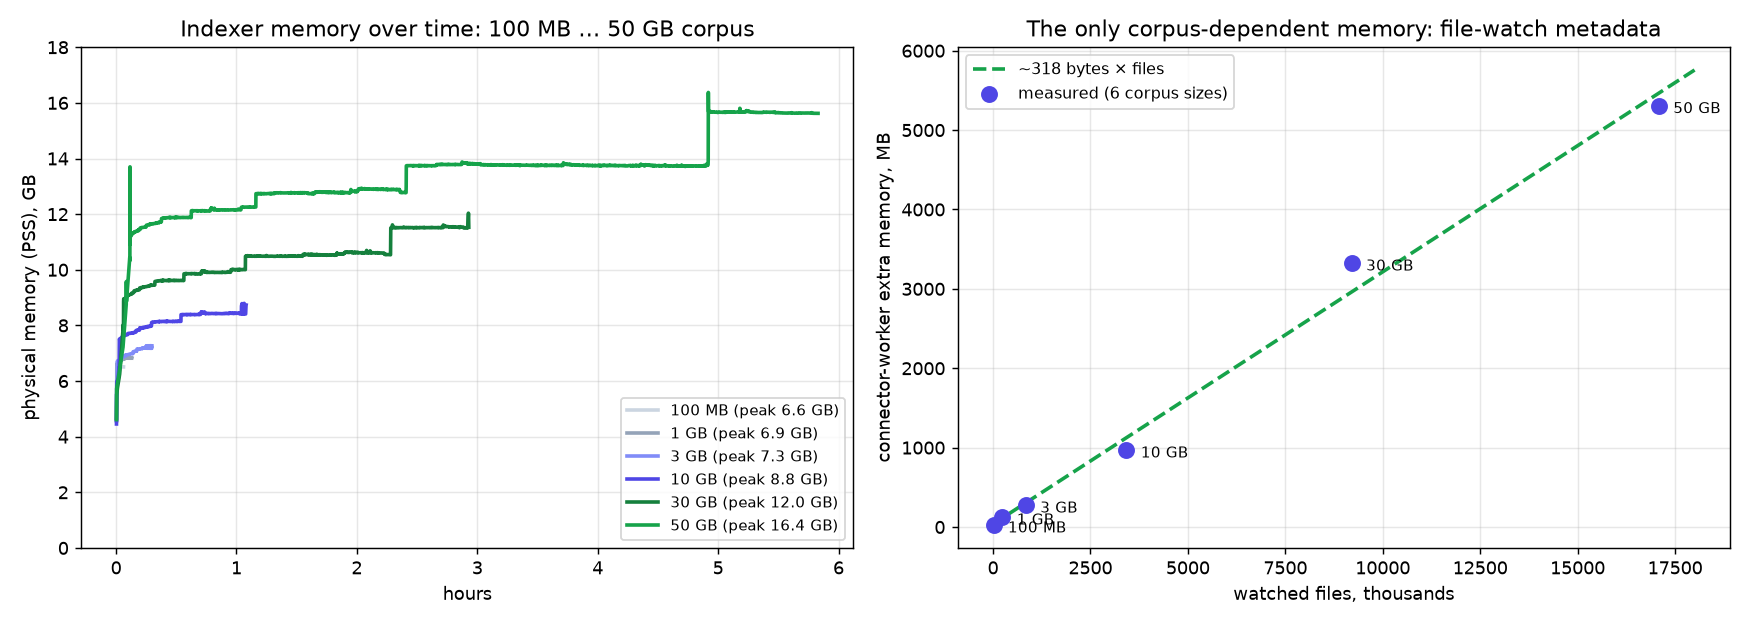
Grows with the corpus — one thing. The file-watch index: to detect live
edits and deletions, the indexer keeps a record (path, mtime, size, owner)
per watched file. Measured cost: ~318 bytes per file (paths of typical
length; ±20% with the hash-table's load factor), verified from 13 thousand
to 17 million files (right-hand plot: six corpus sizes against one fitted
line). It scales with the number of files, not bytes: the same corpus
packed into fewer, larger files costs proportionally less.
Constant, regardless of corpus size. The embedding stack (PyTorch
runtime + model, per worker), the engine baseline (~200 MB per process),
connector machinery (~0.4 GB), and working buffers that reach a plateau in
the first minutes of a run and stay there — identical on 3 GB and 10 GB.
On disk, not in memory. Parsed-text cache, persistence snapshots, and
the embeddings themselves (in the vector database). That is why the curves
plateau: a 500× larger corpus costs 2.5× the memory — and the growth
that remains is the file-watch index above, i.e. the corpus in fewer files
would cost less. Indexing time scales linearly with bytes throughout.
The peak itself is dominated by the embedding stack, not the engine — a
Pathway worker process is ~200 MB; the rest is the price of running
embeddings locally (8 × PyTorch runtime + model), i.e. of paying no
per-token API fees. Fewer workers or an API embedder shrink it accordingly.
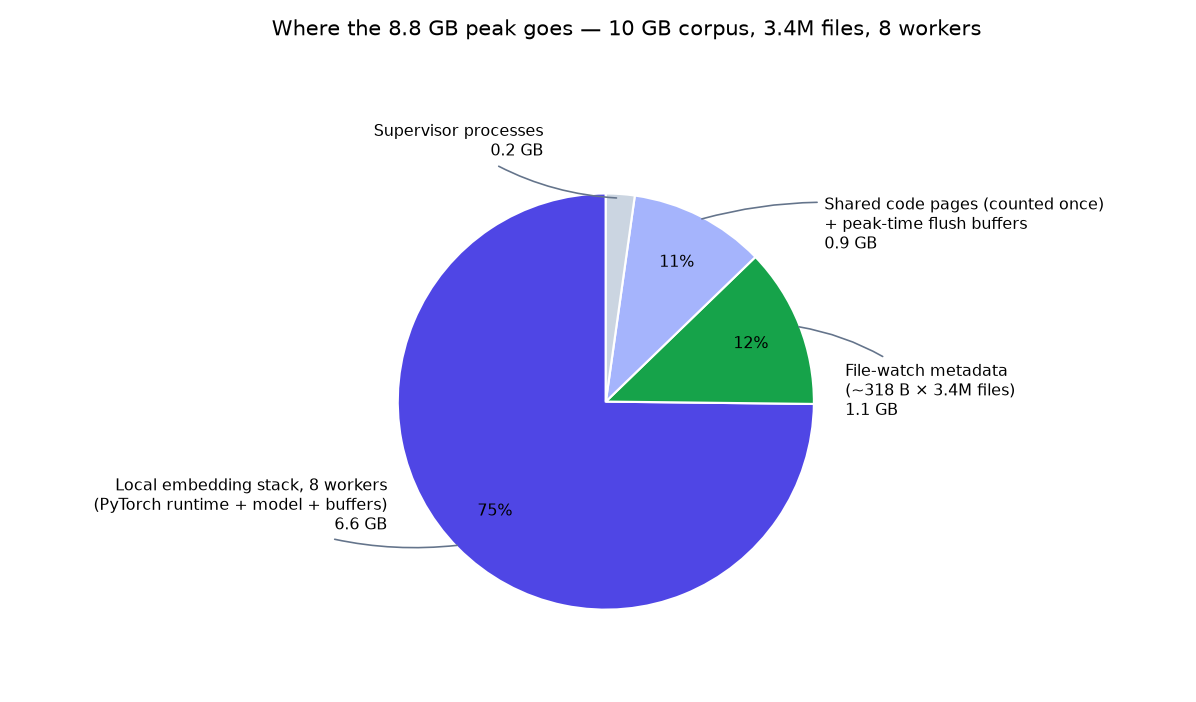
Memory is measured as PSS (proportional set size) summed over the container:
shared pages — e.g. the PyTorch libraries mapped by every worker — are
counted once, not once per process. Setup: 96-core CPU host, streaming mode,
8 worker processes, local static-retrieval-mrl-en-v1 embeddings (no API
calls; Matryoshka-truncated to 256 dims), 512-token chunks, Qdrant, and
jemalloc's background_thread purging enabled in the indexer containers
(measured free; it keeps idle workers from retaining freed pages). Numbers
were measured on a nightly Pathway build whose engine matches the released
wheel (pathway ≥ 0.32.1 — what the benchmark's docker image and the
Development section install), so they are reproducible as-is.
Retrieval accuracy (FRAMES)
End-to-end evaluation on FRAMES
(Google, 2024): 824 multi-hop questions whose answers must be assembled
from 2–15 English Wikipedia articles — see
benchmarks/frames, full technical report in
REPORT.md:
| measurement | result |
|---|---|
| gold-article recall — the paper's metric, on the paper's corpus | 0.50 vs 0.15 published for the paper's BM25 baseline (0.21 for our reproduction of it) |
| paired gain from adding serviette to gpt-5, paper's protocol | +5.2 pp over the same model without retrieval (McNemar z = 4.1, 824 questions) |
| adaptive retrieval in the grounded (context-only) regime | 41.3% → 52.8% (z = 7.5) — the largest single effect measured |
| absolute accuracy (permissive, gpt-5) | 73.7% — above every number in the paper, including its 5-step agent (66.0%) and oracle (72.9%) |
The setup reproduces the paper wherever technically possible: the identical
Wikipedia dump (TFDS wikipedia/20230601.en, 5.22M articles → 12.07M
chunks) indexed in full by serviette with the free local e5-small-v2
embedder — so the recall row costs nothing in API fees — plus the paper's
own retrieval metric and its verbatim autorater prompt. Comparisons are
paired and internal (identical corpus, generator, judge; only the retrieval
layer varies — the opt-in strategies described under
Retrieval quality below), because the absolute score
is dominated by the 2026
generator — its no-retrieval baseline alone reaches 68.5% — which is why
the headline is the paired delta, not 73.7%. The grounded rows measure
serviette as it ships for private corpora: answers strictly from retrieved
documents, a deliberately stricter regime than the paper's. Methodology,
statistics, limitations and raw per-question outputs:
REPORT.md.
Multimodality
Every file type is enabled by default. serviette routes each file to the best
parser that works without an API key, and turns on key-requiring
modalities automatically when their key is present:
| format | parsed by default with | notes |
|---|---|---|
| text / Markdown | as-is | |
pypdf — built in; serviette[docling] upgrades to Docling (layout-aware, tables) |
local, free | |
| Office (DOCX, PPTX, XLSX, HTML, EML…) | Unstructured — built in; serviette[docling] widens coverage (EPUB, legacy formats) |
local, free |
| scanned images (PNG, JPG, TIFF…) | PaddleOCR | local, free |
| audio (MP3, WAV…) | Whisper | when OPENAI_API_KEY is set |
| video (MP4, WebM, MOV…) | TwelveLabs Pegasus — a searchable text description of the video | when TWELVELABS_API_KEY is set |
A modality whose only parser needs an absent key is skipped with a clear
warning — never a crash. Everything stays live: drop a recording of
yesterday's meeting into the watched folder and ask about it minutes later;
expensive parses (video) are cached on disk, so restarts cost nothing.
The routing is configurable per file pattern (parser: section — pick a
vision model for images instead of OCR, set a custom video prompt); see
docs. Embeddings work the same for every modality: parsed
content is text, so any of the embedder families — including the local
credential-free default — covers a multimodal corpus.
Retrieval quality
Retrieval and answering are pure-vector by default; five opt-in strategies
improve accuracy, each a few lines of config. They compose freely — decompose
widens what is retrieved, hybrid and reranking reorder which chunks win,
MMR diversifies them, and adaptive RAG retries with more context when the
answer is not found.
- Hybrid (BM25 + vector). Fuses vector similarity with an in-process BM25
keyword index (reciprocal-rank fusion). The two signals fail differently —
embeddings match paraphrases, BM25's IDF makes rare exact tokens (names,
dates, IDs) dominate — so their fusion beats either alone on entity-heavy
corpora. Enable withhybrid: trueon the vector-db section. - Reranker. A second stage rescoring a shortlist of candidates: a local,
keyless cross-encoder (reranker: {type: cross_encoder}) or pointwise LLM
scoring (type: llm). Best for precise, single-hop questions. - Adaptive RAG. Answers from
kchunks first, then grows the context and
re-asks while the LLM reports the answer is not present (rag.adaptive). - Query decomposition. One LLM call splits a multi-hop question into
sub-queries, retrieves for each, and fuses — so chunks of different hops
stop competing for the same top-k slots (rag.decompose). - MMR. Diversifies the result set, trading relevance against redundancy
(rag.mmr).
The reranker and the multi-step strategies (adaptive, decompose) are
backend-independent — they work on every vector DB. Hybrid and MMR read from
the store, so support depends on the backend:
| Backend | Vector | Reranker · Adaptive · Decompose | MMR | Hybrid (BM25) |
|---|---|---|---|---|
| DuckDB | ✅ | ✅ | ✅ | ✅ in-process |
| Qdrant | ✅ | ✅ | ✅ | ✅ in-process |
| pgvector | ✅ | ✅ | ✅ | ✅ in-process |
| Milvus | ✅ | ✅ | ✅ | ✅ in-process |
| Weaviate | ✅ | ✅ | ✅ | ✅ in-process |
| ChromaDB | ✅ | ✅ | ✅ | ✅ in-process |
| MongoDB | ✅ | ✅ | ✅ | ✅ in-process |
| Pinecone | ✅ | ✅ | ✅ | ❌ — no scan-all API; native sparse-index hybrid is planned |
In-process BM25 targets corpora up to a few million chunks; above
hybrid_max_chunks the keyword leg is skipped with a warning and retrieval
stays pure-vector. Pinecone cannot enumerate its vectors, so it has no
in-process hybrid — hybrid: true there fails fast at startup with that
explanation; native hybrid (a second sparse index) is planned. Native
server-side BM25 for the client-server backends (replacing the in-process
leg at larger scale) is planned as well.
Observability
Three layers, all on by default or one config line away:
In the chat UI. The header shows "indexed N s ago" — the age of the
most recent write into the vector store. When you edit a source document,
you can watch the counter reset as the change lands.
GET /api/v1/stats on the API server: the backend in use, the number of
indexed chunks, and index freshness — a JSON one-liner for dashboards and
health checks, served without touching the indexer (it reads the vector
store, like every other query).
Engine metrics (Prometheus). The Pathway engine ships its own
observability server; serviette exposes it with one config line:
indexer:
  monitoring_http_port: 20000
Every worker process then serves GET /metrics on
127.0.0.1:(20000 + worker index) — input/output latency gauges (i.e. the
indexing lag behind the sources) and per-operator row counters, straight
from the engine's dataflow. Point a Prometheus scrape at the worker ports
and you get per-stage throughput and freshness graphs with no extra code.
Logs from both processes go to stdout/stderr in plain text; serviette up
interleaves them with per-process prefixes.
Security
The server listens on localhost only by default and ships no built-in
authentication — exposing it is an explicit decision: set server.host: 0.0.0.0 and put an authenticating reverse proxy in front (a five-line
Caddy example lives in docs).
Requirements
Python ≥ 3.10 (the minimum supported by Pathway).
Documentation
Full installation, quickstart, configuration reference, persistence,
architecture and scaling notes live in docs/README.md.
Development
serviette runs on the released Pathway from PyPI (≥ 0.32.1 — the first
release with the vector-database connectors). From-scratch setup on a
fresh machine:
# 0. Prerequisites: Python >= 3.10 (3.12 recommended) and git.

# 1. serviette in its own virtualenv
git clone https://github.com/pathwaycom/serviette.git && cd serviette
python3.12 -m venv .venv
source .venv/bin/activate
pip install -e ".[dev,local]"

# 2. A (free) Pathway license: https://pathway.com/framework/get-license
export PATHWAY_LICENSE_KEY=...

# 3. Sanity check: zero-to-chat on the bundled corpus
serviette demo                        # -> http://localhost:8989
Notes:
serviette demomaterializes everything in a visible working directory:
./serviette-demo/docsholds the corpus — a toy example, a handful of
documents about a fictional company (Lumina Coffee Systems). Drop your own
files there (PDF, DOCX, scans, …) while it runs and they are answerable
within seconds.- The demo indexes with one of two embedders — pick your trade-off:
- default, free & local — needs
serviette[local], which pulls the
PyTorch stack (~4.5 GB): on a typical laptop connection the install
itself is the slow part, so the first run takes a while. Free at any
corpus size afterwards. --embedder openai— nothing to install, starts immediately, but
every indexed token is billed to yourOPENAI_API_KEY. Fine for the toy
corpus and small folders; for a large collection, sit out the
serviette[local]install and use the free embedder instead.
- default, free & local — needs
- Independently of the embedder, export
OPENAI_API_KEYif you want real
generated answers in/rag— without it the demo answers by quoting the
retrieved snippets.
Running the test suites:
pytest -m "not slow"            # fast unit tests (no Pathway, no services)
pytest -m "slow and not integration"   # end-to-end indexer tests (spin up Pathway)
pytest -m integration          # real-database tests (see below)
pytest                         # everything
Per-backend clients install as extras — pick what you use:
pip install "serviette[qdrant]"      # also: pgvector, milvus, chroma, weaviate,
                                  #       pinecone, mongodb, local, gemini, all
Integration tests (real databases)
Every claimed backend has an integration test running the same scenario
end-to-end against a real instance: index two documents with the real indexer,
retrieve through the production accessor (exact-text query must rank first
with cosine ~1.0), delete a file, re-index, and verify its vectors are gone
(snapshot semantics). The shared driver lives in tests/integration_common.py.
| Backend | Test | Real instance |
|---|---|---|
| DuckDB | test_integration_duckdb.py |
embedded — runs everywhere |
| pgvector | test_integration_pgvector.py |
pgvector/pgvector Docker container |
| Milvus | test_integration_milvus.py |
embedded Milvus Lite engine |
| Qdrant | test_integration_qdrant.py |
qdrant/qdrant Docker container |
| ChromaDB | test_integration_chroma.py |
chromadb/chroma Docker container |
| Weaviate | test_integration_weaviate.py |
semitechnologies/weaviate Docker container |
| Pinecone | test_integration_pinecone.py |
official pinecone-local emulator (Docker) |
| MongoDB | test_integration_mongodb.py |
mongodb-atlas-local (mongod + mongot, real $vectorSearch) |
Containers are throwaway (tests/dockerutil.py, Docker CLI via subprocess, no
extra dependency) and host ports are allocated dynamically — tests never
assume a fixed localhost port is free or that a service is already running.
Each test skips automatically when Docker or its client library is missing.
License
See LICENSE.