

Repository
tacotron2
Tacotron 2 - PyTorch implementation with faster-than-realtime inference
README
Tacotron 2 (without wavenet)
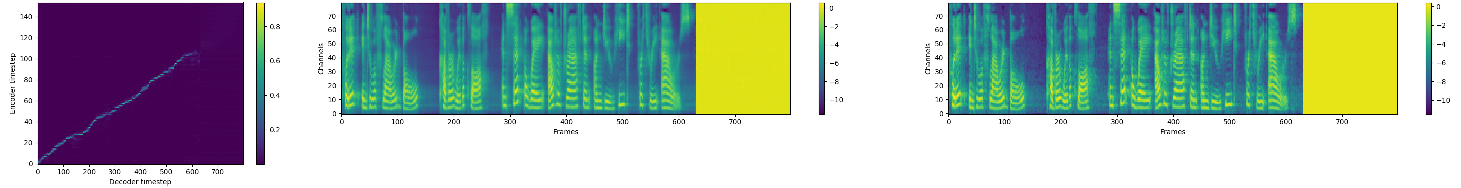
PyTorch implementation of Natural TTS Synthesis By Conditioning
Wavenet On Mel Spectrogram Predictions.
This implementation includes distributed and automatic mixed precision support
and uses the LJSpeech dataset.
Distributed and Automatic Mixed Precision support relies on NVIDIA's Apex and AMP.
Visit our website for audio samples using our published Tacotron 2 and
WaveGlow models.
Pre-requisites
- NVIDIA GPU + CUDA cuDNN
Setup
- Download and extract the LJ Speech dataset
- Clone this repo:
git clone https://github.com/NVIDIA/tacotron2.git - CD into this repo:
cd tacotron2 - Initialize submodule:
git submodule init; git submodule update - Update .wav paths:
sed -i -- 's,DUMMY,ljs_dataset_folder/wavs,g' filelists/*.txt- Alternatively, set
load_mel_from_disk=Trueinhparams.pyand update mel-spectrogram paths
- Alternatively, set
- Install PyTorch 1.0
- Install Apex
- Install python requirements or build docker image
- Install python requirements:
pip install -r requirements.txt
- Install python requirements:
Training
python train.py --output_directory=outdir --log_directory=logdir- (OPTIONAL)
tensorboard --logdir=outdir/logdir
Training using a pre-trained model
Training using a pre-trained model can lead to faster convergence
By default, the dataset dependent text embedding layers are ignored
- Download our published Tacotron 2 model
python train.py --output_directory=outdir --log_directory=logdir -c tacotron2_statedict.pt --warm_start
Multi-GPU (distributed) and Automatic Mixed Precision Training
python -m multiproc train.py --output_directory=outdir --log_directory=logdir --hparams=distributed_run=True,fp16_run=True
Inference demo
- Download our published Tacotron 2 model
- Download our published WaveGlow model
jupyter notebook --ip=127.0.0.1 --port=31337- Load inference.ipynb
N.b. When performing Mel-Spectrogram to Audio synthesis, make sure Tacotron 2
and the Mel decoder were trained on the same mel-spectrogram representation.
Related repos
WaveGlow Faster than real time Flow-based
Generative Network for Speech Synthesis
nv-wavenet Faster than real time
WaveNet.
Acknowledgements
This implementation uses code from the following repos: Keith
Ito, Prem
Seetharaman as described in our code.
We are inspired by Ryuchi Yamamoto's
Tacotron PyTorch implementation.
We are thankful to the Tacotron 2 paper authors, specially Jonathan Shen, Yuxuan
Wang and Zongheng Yang.