

- Detection Result
- Classification Attention Map 1
- $ ~ ~$ $ ~ ~$
- (talk to)
Specs
- Detection ResultClassification Attention Map 1
- $ ~ ~$ $ ~ ~$(talk to)
- $ ~ ~$ $ ~ ~$(answer phone)
README
Classification Matters: Improving Video Action Detection with Class-Specific Attention
Paper | Project Page
This repository is the official implementation of "Classification Matters: Improving Video Action Detection with Class-Specific Attention" (ECCV 2024 Oral)
Classification Matters: Improving Video Action Detection with Class-Specific Attention
Jinsung Lee<sup>1</sup>,
Taeoh Kim<sup>2</sup>,
Inwoong Lee<sup>2</sup>,
Minho Shim<sup>2</sup>,
Dongyoon Wee<sup>2</sup>,
Minsu Cho<sup>1</sup>,
Suha Kwak<sup>1</sup>\
POSTECH<sup>1</sup>, NAVER Cloud<sup>2</sup>\
accepted to ECCV 2024 as an oral presentation
| Detection Result | Classification Attention Map 1 | Classification Attention Map 2 |
|---|---|---|
$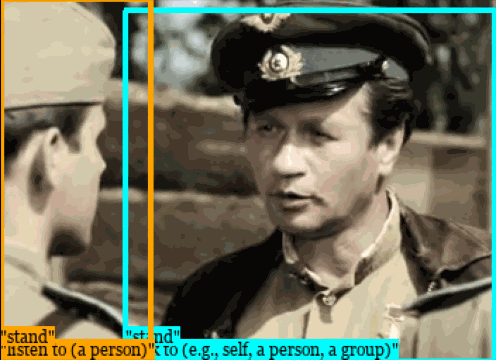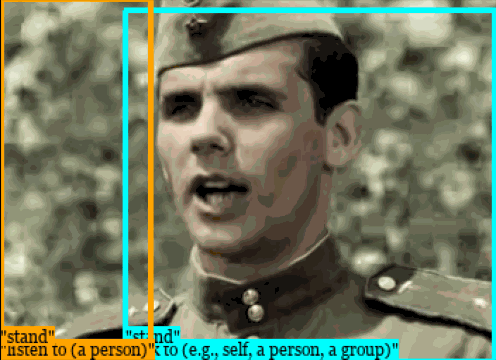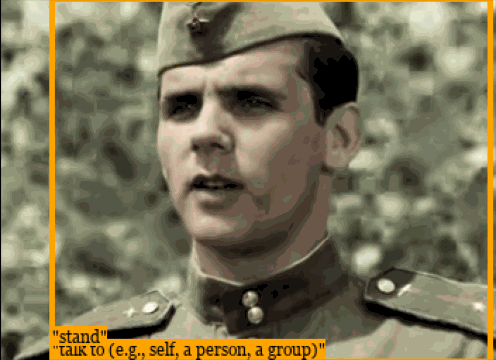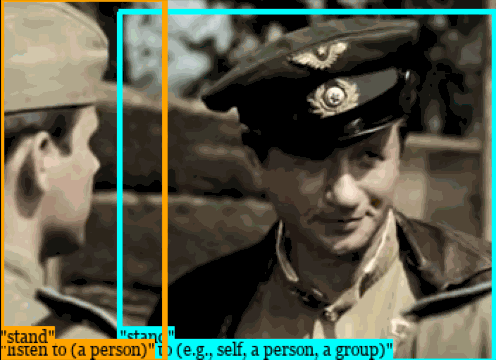 |
(talk to) 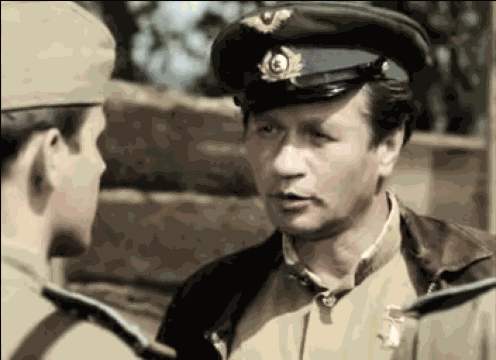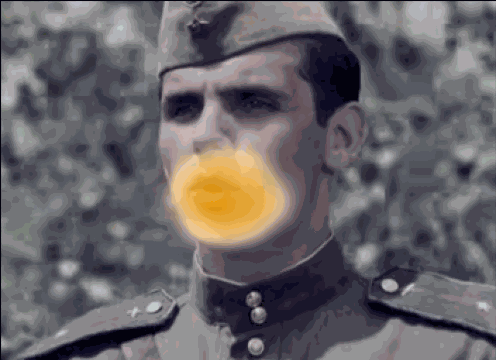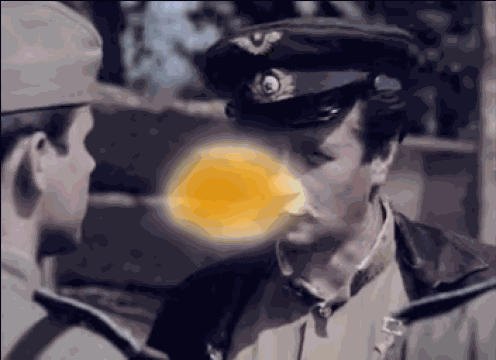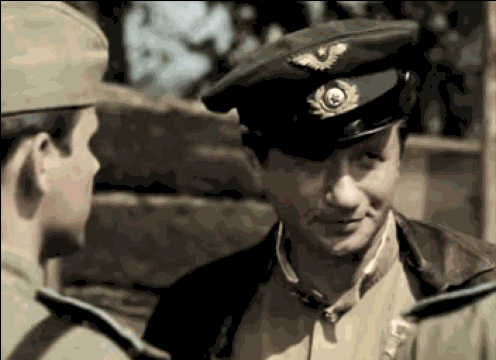 |
(listen to)  |
$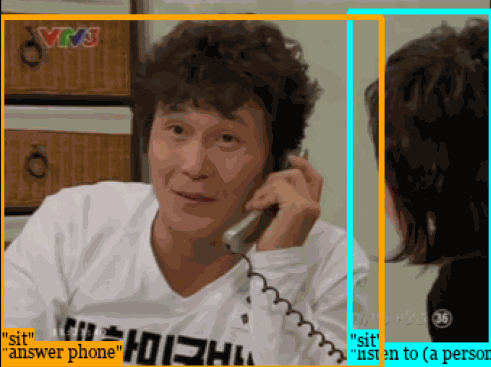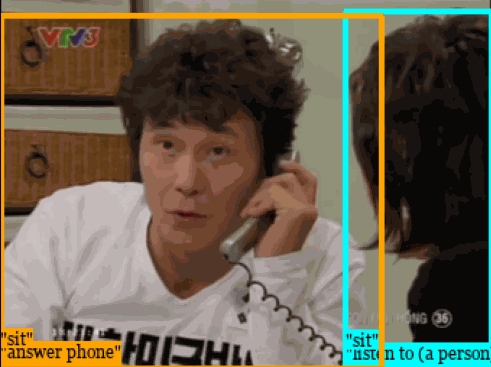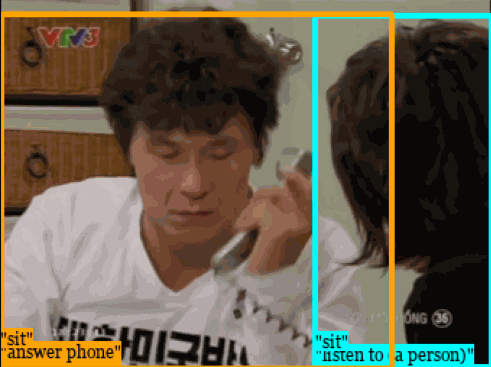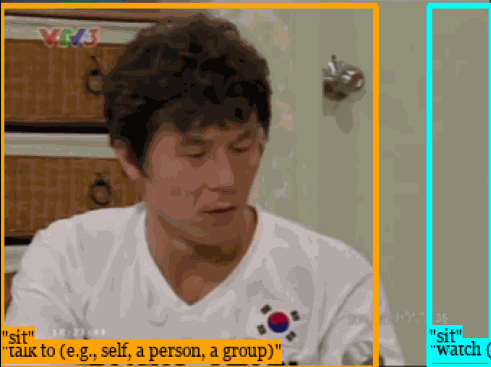 |
(answer phone) 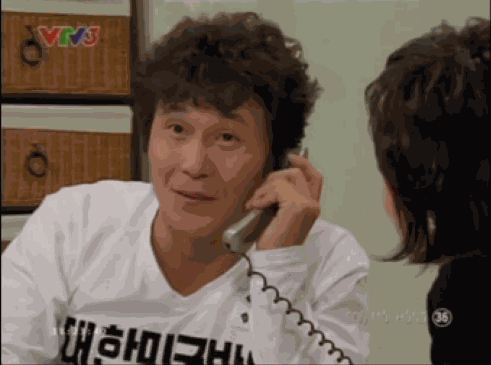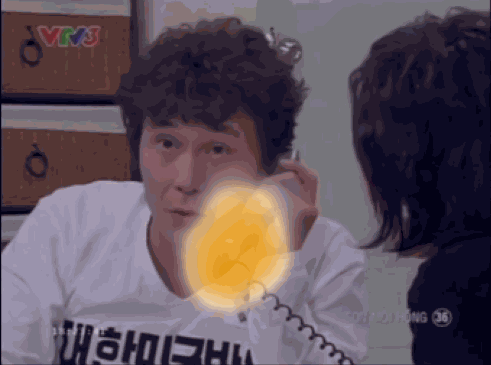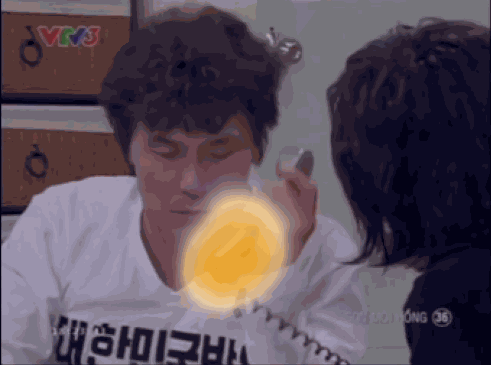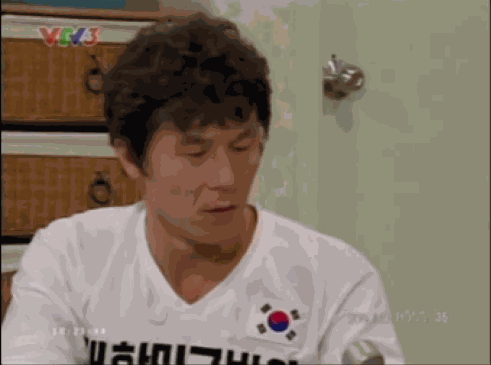 |
$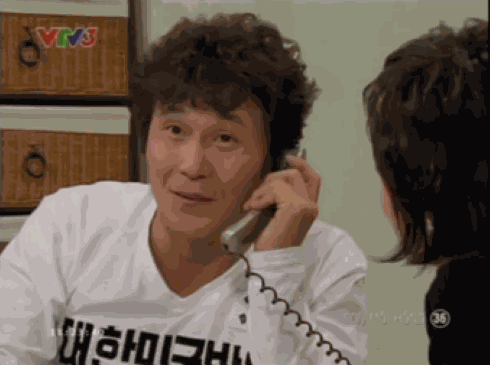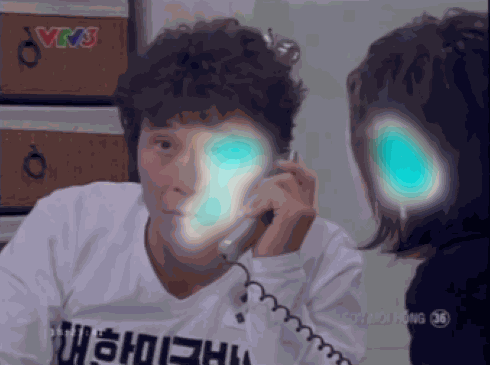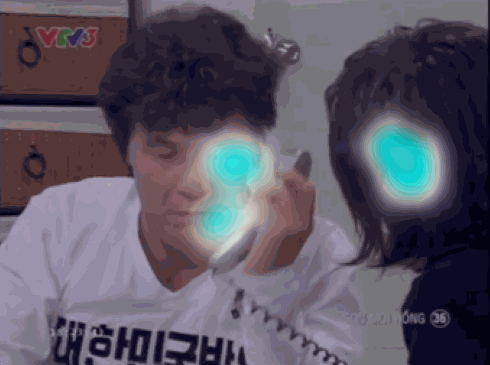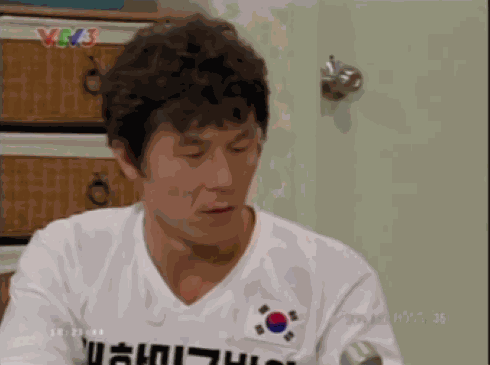 |
Installation
The code works on
- Ubuntu 20.04
- CUDA 11.7.0
- CUDNN 8.0.5
- NVIDIA A100 / V100
Install followings,
- Python: 3.8.10
- GCC 9.4.0
- PyTorch: 2.0.0
and run the installation commands below:
  pip install -r requirements.txt
  cd ops
  pip install .
Data Preparation
Refer here for AVA preparation.
We use updated annotations (v2.2) of AVA. Download annotation assets and place it outside the project folder (../assets).
Refer here for UCF101-24 preparation.
Refer here for JHMDB51-21 preparation.
Running commands
Our model is trained in two steps: (following TubeR)
First, it is trained from scratch.
Second, it is trained again, but it uses the transformer weights acquired from the first stage.
For convenience, we provide the pre-trained transformer weights of the first stage that are used to train the model.
Evaluation Code
## Evaluate

# AVA 2.2
python3 evaluate.py --pretrained_path={path to the model to evalute} --config-file=./configuration/AVA22_CSN_152.yaml
python3 evaluate.py --pretrained_path={path to the model to evalute} --config-file=./configuration/AVA22_ViT-B.yaml
python3 evaluate.py --pretrained_path={path to the model to evalute} --config-file=./configuration/AVA22_ViT-B_v2.yaml

# UCF
python3 evaluate.py --pretrained_path={path to the model to evalute} --config-file=./configuration/UCF_ViT-B.yaml

# JHMDB (split 0)
python3 evaluate.py --pretrained_path={path to the model to evalute} --config-file=./configuration/JHMDB_ViT-B.yaml --split 0
Model Zoo
Backbone .pth files are the same ones from here (CSN152) and here (ViT-B).
We offer this link for the aggregated backbone .pth files.
| Dataset | Backbone | Backbone pretrained on | transformer weights | f-mAP | v-mAP | config | checkpoint |
|---|---|---|---|---|---|---|---|
| AVA 2.2 | CSN-152 | K400 | link | 33.5 | - | config | link |
| AVA 2.2 | ViT-B | K400 | link | 32.9 | - | config | link |
| AVA 2.2 | ViT-B | K400, K710 | link | 38.4 | - | config | link |
| UCF | ViT-B | K400 | link | 85.9 | 61.7 | config | link |
| JHMDB (split 0) | ViT-B | K400 | link | 88.1 | 90.6 | config | link |
Acknowledgments
Our code is based on DETR, DAB-DETR, Deformable-DETR, and TubeR.
If you use our model, please consider citing them as well.
License
Class Query
Copyright (c) 2024-present NAVER Cloud Corp.
CC BY-NC 4.0 (https://creativecommons.org/licenses/by-nc/4.0/)