

README
🧩 General365: Benchmarking General Reasoning in LLMs Across Diverse and Challenging Tasks
📃 Paper • 🌐 Project Page • 🏆 Leaderboard • 🤗
- High Diversity: It contains 365 manually crafted, highly diverse seed problems, specifically designed to cover a wide range of reasoning challenges and avoid repetitive features or patterns. By altering surface semantics or constraints while preserving core reasoning skills, these seed problems were further expanded into 1,095 variants.
- Challenging Boundaries: General365 covers 8 challenging categories, as detailed in Section 2.1 of paper. Even state-of-
the-art models barely achieve a "passing" level of performance on these challenging tasks. - Focus on Reasoning over Knowledge: The knowledge required is strictly confined to the K-12 scope, ensuring the
dataset measures a model’s reasoning capabilities rather than knowledge retrieval. - Rigorous Quality Control: All instances have undergone manual review to ensure the highest standards of quality.
- Accurate Scoring: We implemented a hybrid scoring algorithm combining rule-based and model-based approaches,
achieving a manually verified scoring accuracy of 99.6%.
🏆 Leaderboard
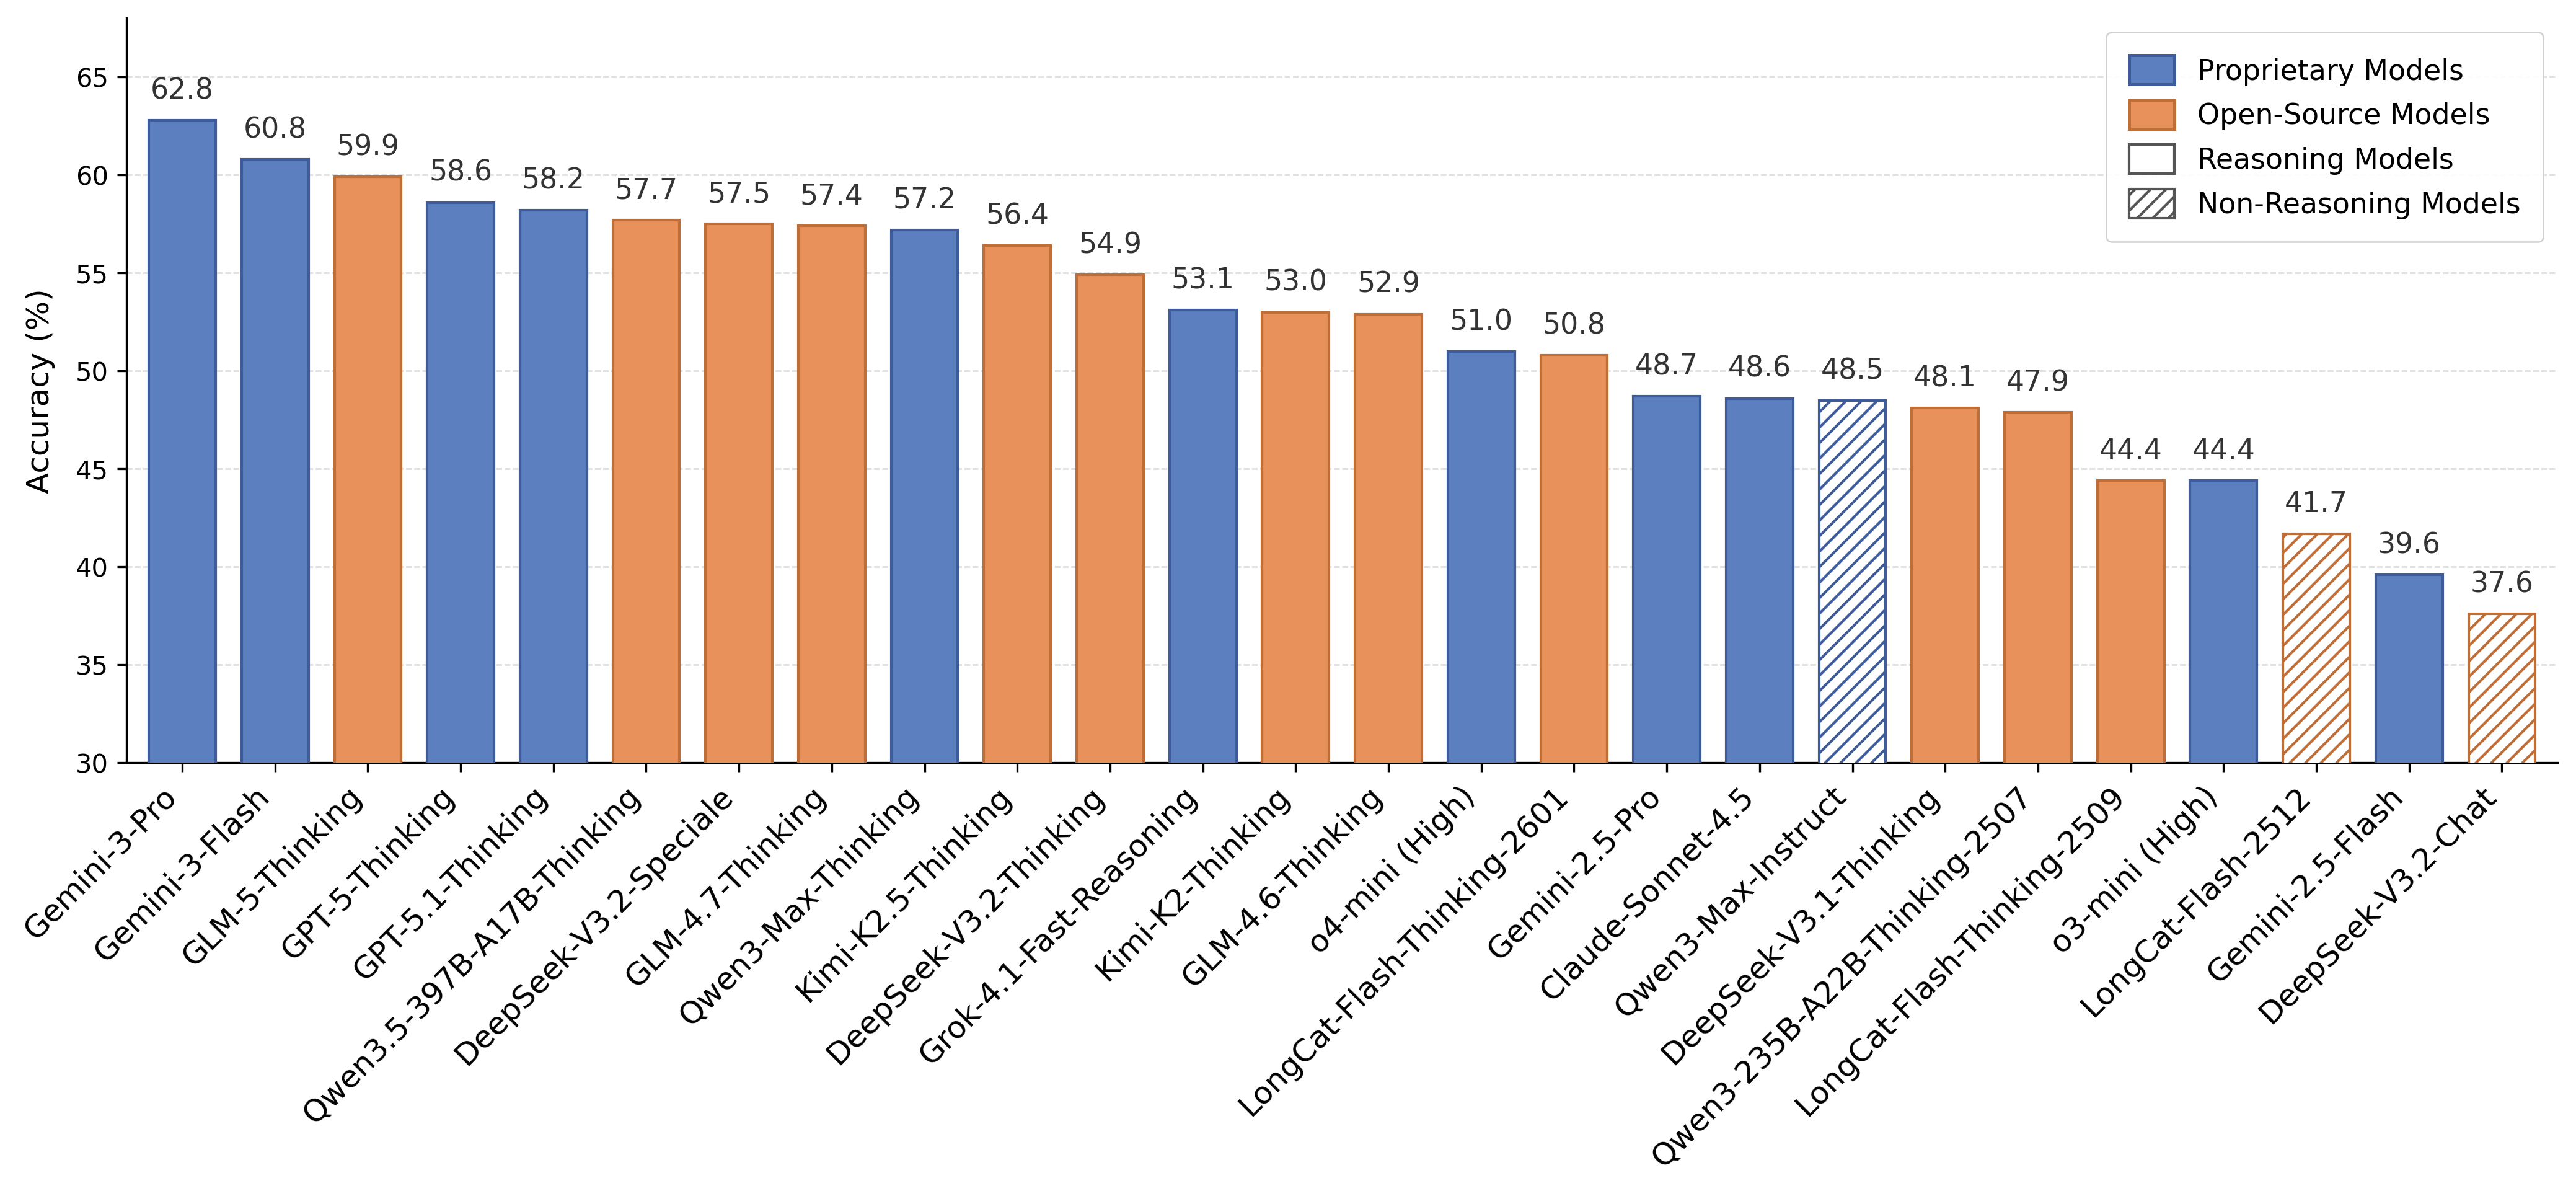
📊 Main Results
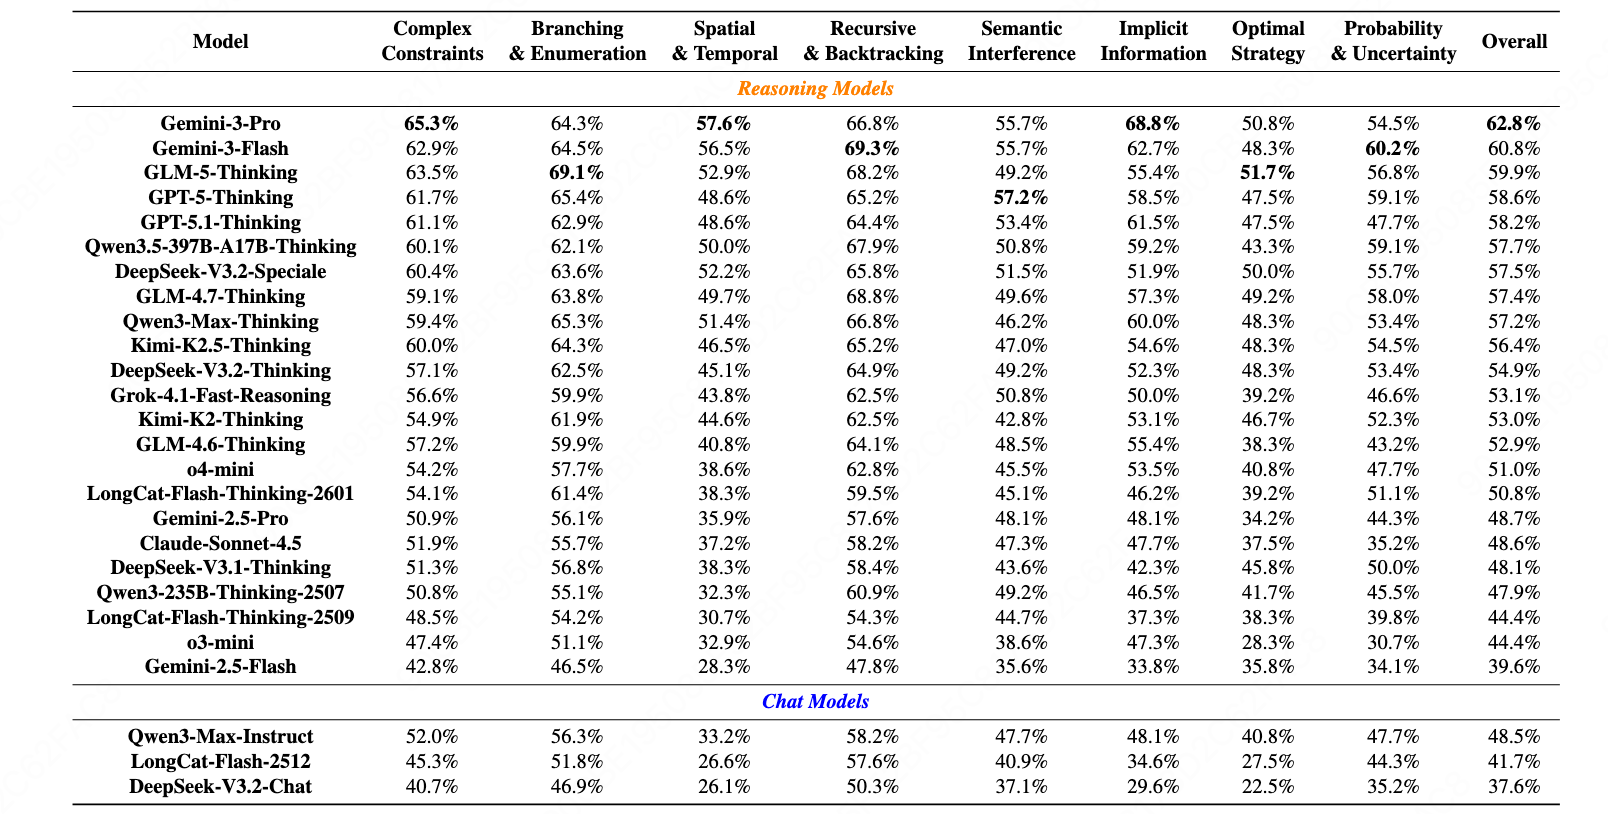
🛠️ Quick Start
Installation
Clone the repository:
git clone https://github.com/meituan-longcat/General365.git
cd General365
Install dependencies:
pip install -r requirements.txtRunning evaluations
Step 1: Prepaer the Model Response File
After obtaining model responses, format them as follows (one JSON object per line):
{"question_id": 1, "model_response": "..."}
{"question_id": 2, "model_response": "..."}
...
Save this file in the ./model_responses/ directory.
Step 2: Grading Responses
Set your API key and URL in lines 10-11 of grading.py.
Then run:
python grading.py --response_file example_responses.jsonlEvaluation results will be saved under the ./grading_results/ directory.
🔎 Citation
If you find our work helpful or relevant to your research, please kindly cite our paper:
@misc{general365benchmark,
      title={General365: Benchmarking General Reasoning in Large Language Models Across Diverse and Challenging Tasks},
      author={Junlin Liu and Shengnan An and Shuang Zhou and Dan Ma and Shixiong Luo and Ying Xie and Yuan Zhang and Wenling Yuan and Yifan Zhou and Xiaoyu Li and Ziwen Wang and Xuezhi Cao and Xunliang Cai},
      year={2026},
      eprint={2604.11778},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2604.11778},
}
🤗 Acknowledgement
The evaluation script utilizes Math-Verify to parse and verify model outputs.
We greatly appreciate the contributors' efforts in providing this valuable tool.
📜 License
This project is licensed under the MIT License - see the LICENSE file for details.
📪 Support
For questions and support, please open an issue on GitHub or contact the maintainers.