

Repository
PosterReward
[CVPR2026] PosterReward: Unlocking Accurate Evaluation for High-Quality Graphic Design Generation
- Step
- Script
- 1
- step1_generate_images.py
- 2
- step2_vllm_analyze.py
- 3
- step3_reward_score.py / step3_reward_score.sh
Specs
- StepScript
- 1step1_generate_images.py
- 2step2_vllm_analyze.py
- 3step3_reward_score.py / step3_reward_score.sh
- 4step4_metrics_analysis.py / step4_metrics_analysis.sh
README
PosterReward: Unlocking Accurate Evaluation for High-Quality Graphic Design Generation
 [](https://arxiv.org/abs/2603.29855)
[](https://alexlai2860.github.io/mypaper/posterreward/PosterReward_Arxiv_released.pdf)
[](https://alexlai2860.github.io/PosterReward/)
[](.)
[](https://huggingface.co/MeiGen-AI/PosterReward_v1)
👥 Authors
Jianyu Lai<sup>1,2</sup>*,
Sixiang Chen<sup>1,2</sup>*,
Jialin Gao<sup>2</sup>*,
Hengyu Shi<sup>2</sup>,
Zhongying Liu<sup>2</sup>,
Fuxiang Zhai<sup>1</sup>,
Junfeng Luo<sup>2</sup>,
Xiaoming Wei<sup>2</sup>,
Lujia Wang<sup>1</sup>,
Lei Zhu<sup>1,3</sup>†<sup>1</sup>HKUST (GZ) <sup>2</sup>Meituan <sup>3</sup>HKUST
*Equal contribution, †Corresponding Author
<details open><summary>💡 We also have other poster generation/editing works that may interest you✨</summary>
> [**[CVPR 2026] PosterOmni: Generalized Artistic Poster Creation via Task Distillation and Unified Reward Feedback**](https://arxiv.org/pdf/2602.12127) > Sixiang Chen, Jianyu Lai, Jialin Gao, et al. [](https://github.com/MeiGen-AI/PosterOmni) [](https://arxiv.org/pdf/2602.12127) [](https://ephemeral182.github.io/PosterOmni/) > [**[ICLR 2026] PosterCraft: Rethinking High-Quality Aesthetic Poster Generation in a Unified Framework**](https://arxiv.org/pdf/2506.10741) > Sixiang Chen, Jianyu Lai, Jialin Gao, et al. [](https://github.com/Ephemeral182/PosterCraft) [](https://arxiv.org/pdf/2506.10741) [](https://ephemeral182.github.io/PosterCraft/)
</details>
🔥 News & Updates
- 📄 [2026.03] Official arXiv version released: 2603.29855
- 🚀 [2026.03] Open-sourced the inference scripts and benchmark pipeline in this repository.
- 📄 [2026.03] Released the latest public paper draft: PosterReward_Arxiv_released.pdf
- 🏆 [2026.02] PosterReward was accepted to CVPR 2026.
🌟 Overview
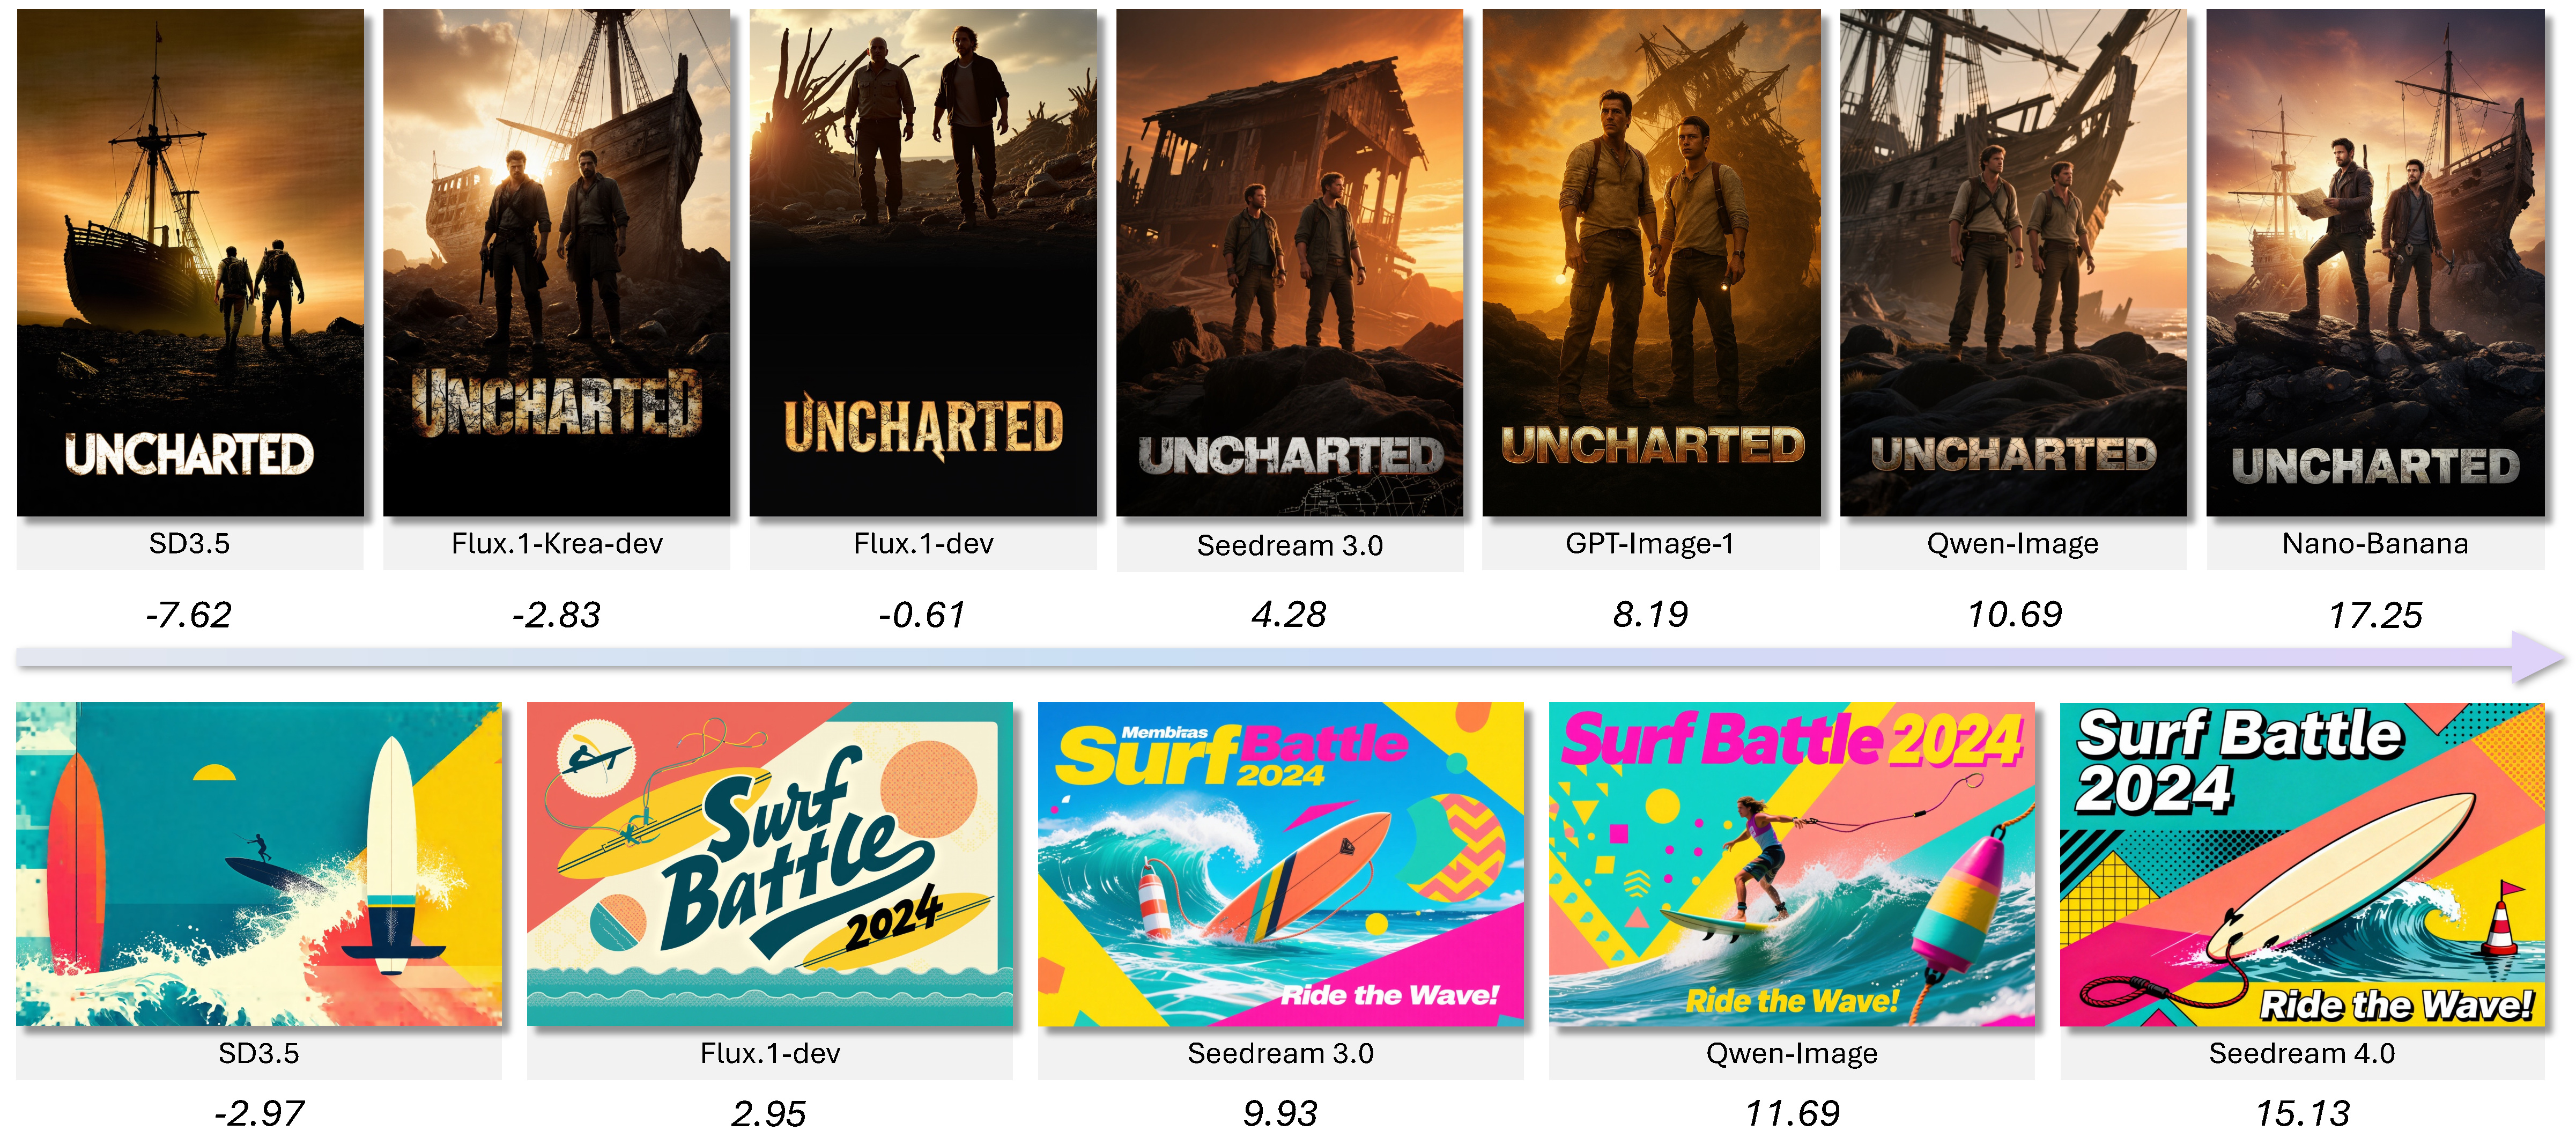 PosterReward is a reward model for poster generation tasks. It evaluates posters from multiple dimensions and outputs scores, achieving an accurate assessment of graphic design quality.
<br>
Recent progress in text-rendering image generation makes end-to-end poster creation increasingly feasible, but general-purpose reward models still struggle to assess typography, layout, and design-specific quality. To bridge this gap, PosterReward builds a 70k poster preference dataset from multi-MLLM consensus and introduces a dedicated reward modeling framework for poster assessment.
The paper formalizes poster evaluation with five dimensions:
- Foundational Visual Quality
- AI Artifacts
- Textual Accuracy
- Prompt Fidelity
- Aesthetic Value
PosterReward provides three model variants:
- PosterReward: a two-stage discriminative reward model with
analysis -> scoring. - PosterReward-Lite: a simplified pointwise variant that omits the analysis module for faster inference.
- PosterReward-Pairwise: a generative pairwise judge that predicts preference and can output CoT reasoning.
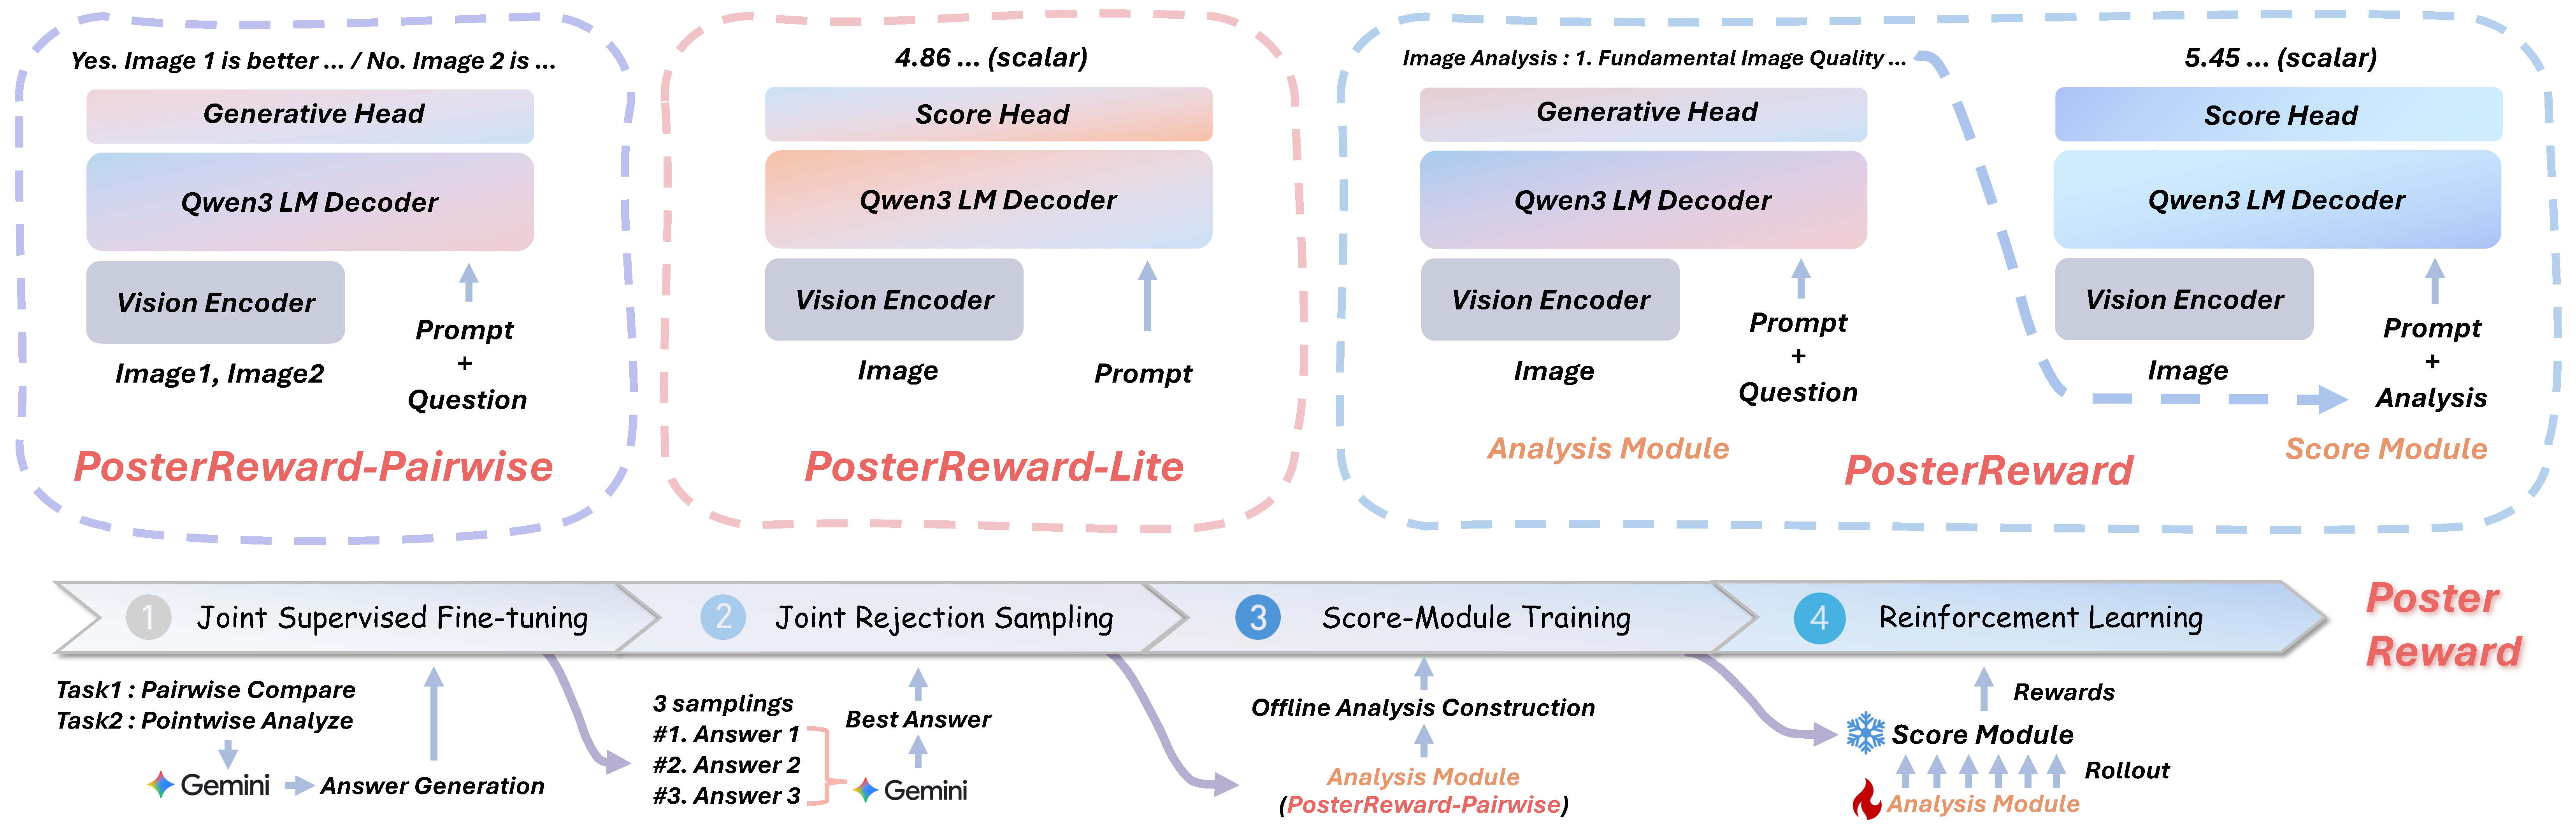 PosterReward training pipeline and model structure diagram. The top shows three reward models with different structures, and the bottom shows the training pipeline. Our training pipeline consists of four cascaded stages: Joint Supervised Fine-Tuning, Joint Rejection Sampling, Score-Module Training, and Reinforcement Learning.
<br>
It also introduces two benchmarks:
- PosterRewardBench: benchmark for reward-model accuracy on poster preference assessment.
- PosterBench: benchmark for text-to-image poster generation quality.
🚀 Quick Start
🔧 Environment Setup
conda create -n posterreward python=3.10 -y
conda activate posterreward

cd swift
pip install -e .

cd ..
pip install msgspec "qwen_vl_utils>=0.0.14" torchvision diffusers pillow

# For vLLM-based deployment (required for the Analyser in the full PosterReward pipeline and PosterBench):
pip install "torch>=2.8.0" "vllm>=0.11.0"
Note: If you encounter a vLLM engine initialization error, ensure that your
torchandvllmversions are compatible. We have verified thattorch==2.8.0+vllm==0.11.0work well with the ms-swift version included in this repo.
⚡ PosterReward-Lite
PosterReward-Lite is the fastest entry point for single-image pointwise scoring.
- Edit
MODEL_PATH,IMAGE_PATH, andPROMPTininference_lite.sh. - Run:
bash inference_lite.sh⚡ Full PosterReward
The full PosterReward pipeline is a two-stage process:
posterreward_analyser.pygenerates a detailed multi-dimensional analysis.posterreward_scorer.pyturns that analysis into the final scalar reward.
To use it:
- Edit
ANALYSER_MODEL,SCORER_MODEL,PROMPT, andIMAGE_PATHininference_posterreward.sh. - Run:
bash inference_posterreward.shOutputs are saved to ./posterreward_output/ by default.
🧠 Model Notes
The released PosterReward family is built on Qwen3-VL-8B:
- The analysis module is fine-tuned from
Qwen3-VL-8B. - The scoring module uses a scalar reward head on top of
Qwen3-VL-8B. PosterReward-Pairwiseis a generative pairwise model fine-tuned fromQwen3-VL-8B.
The training pipeline has four cascaded stages:
- Joint Supervised Fine-Tuning
- Joint Rejection Sampling Fine-Tuning
- Scoring Module Training
- Reinforcement Learning Fine-Tuning
🧪 PosterBench
poster_bench/ contains the evaluation pipeline for poster generation benchmarking.
PosterBench contains 250 prompts: 100 cinematic prompts and 150 non-cinematic prompts. Each model generates 8 samples per prompt for stability evaluation.
Pipeline Overview
| Step | Script | Purpose |
|---|---|---|
| 1 | step1_generate_images.py |
Generate poster images from prompts |
| 2 | step2_vllm_analyze.py |
Produce detailed image analysis with a deployed VLM |
| 3 | step3_reward_score.py / step3_reward_score.sh |
Score the analyzed samples with PosterReward |
| 4 | step4_metrics_analysis.py / step4_metrics_analysis.sh |
Aggregate final benchmark metrics |
Step 1: Generate Images
The default step1_generate_images.py script is configured for a Qwen-Image-2512-style backend and writes outputs to results_qwen_image_2512/.
cd poster_bench

# Edit MODEL_PATH in the script first
python step1_generate_images.py
This repository also includes dedicated generation scripts for:
step1_generate_images.pyfor Qwen-Image-2512-style generationstep1_generate_images_flux_klein.pystep1_generate_images_zimage.py
PosterBench additionally reports closed-source systems such as Nano-Banana-Pro, Seedream-4.5, Nano-Banana, Seedream-4.0, GPT-Image-1, and Seedream-3.0, and open-source systems such as Qwen-Image-2512, Qwen-Image, Z-Image-Turbo, Flux.2-klein-9B, Flux.1-krea-dev, Flux.1-dev, and SD3.5-L.
Step 2: Batch Analysis
bash step2_vllm_deploy.sh

python step2_vllm_analyze.py \
  --model_folder ./results_qwen_image_2512 \
  --output all_models_analysis.jsonl
We define the analysis target with the following five dimensions. The current implementation prompt uses equivalent, slightly more descriptive wording for the same evaluation axes:
- Foundational Visual Quality
- AI Artifacts
- Textual Accuracy
- Prompt Fidelity
- Aesthetic Value
Step 3: Reward Scoring
bash step3_reward_score.shThe provided shell script is a template and contains path variables that should be edited for your environment.
Step 4: Metrics Analysis
bash step4_metrics_analysis.shPosterBench reports four core metrics:
- Mean: average PosterReward score over all generated posters.
- Median: median PosterReward score over all generated posters.
- Std-Avg: mean of the per-prompt standard deviations across the 8 generations; lower is better.
- Bo8-Avg: Best-of-8 Average, defined as the mean of the highest-scoring sample within each set of 8 generations.
📚 PosterRewardBench
poster_reward_bench/ contains benchmark resources for evaluating reward models on poster assessment tasks.
Data Preparation
The benchmark images are hosted on Hugging Face. Download and extract them before running the evaluation:
cd poster_reward_bench

# Download from Hugging Face (requires huggingface-cli)
huggingface-cli download MeiGen-AI/PosterReward_v1 PRB_basic_images.tar.gz --repo-type model --local-dir .
huggingface-cli download MeiGen-AI/PosterReward_v1 PRB_advanced_images.tar.gz --repo-type model --local-dir .

# Extract
tar -xzf PRB_basic_images.tar.gz
tar -xzf PRB_advanced_images.tar.gz
After extraction, the directory structure should look like:
poster_reward_bench/
├── PRB_basic_relative.json
├── PRB_advanced_relative.json
├── PRB_basic_images/          # 1,034 images
├── PRB_advanced_images/       # 2,446 images
└── ...
PosterRewardBench has two subsets:
- PosterRewardBench-Basic: generated by
Flux,Flux-Krea, andSD3.5-L, with larger quality variation. - PosterRewardBench-Advanced: generated by
Seedream-3.0,Seedream-4.0, andQwen-Image-Lightning, with higher overall quality and smaller quality gaps.
All preference pairs were reviewed by four professional annotators, and only pairs with agreement from at least three annotators were retained.
For pointwise models, we report accuracy (↑) on MMRB2, HPDv3, PRB-Basic, and PRB-Ad, where:
- PRB-Basic = PosterRewardBench-Basic
- PRB-Ad = PosterRewardBench-Advanced
Evaluation Pipeline
Evaluating the full PosterReward model on PosterRewardBench is a two-step process:
Step 1: Deploy the Analyser and generate analyses
cd poster_reward_bench

# Deploy the PosterReward Analyser via vLLM (edit MODEL_PATH in vllm_deploy.sh first)
bash vllm_deploy.sh

# In another terminal, run the analysis generation script
python step1_gen_analysis.py
This generates PRB_basic_relative_with_analysis.json and PRB_advanced_relative_with_analysis.json. The script supports checkpointing and can resume from interruptions.
Step 2: Score and evaluate accuracy
# Edit MODEL_PATH in batch_eval.sh, then run:
bash batch_eval.sh
Note: Ensure the correct
swiftbinary is in yourPATH(from the project's conda environment), asstep2_eval.pyinvokesswift infervia subprocess.
📊 Main Results
🎯 Pointwise Reward Models
Legend: 🥇 best, 🥈 second best within each metric column.
<table>
<thead>
<tr>
<th>Model</th>
<th>MMRB2 ↑</th>
<th>HPDv3 ↑</th>
<th>PRB-Basic ↑</th>
<th>PRB-Ad ↑</th>
</tr>
</thead>
<tbody>
<tr><td>ImageReward</td><td>53.0</td><td>58.6</td><td>60.7</td><td>49.3</td></tr>
<tr><td>PickScore</td><td>57.6</td><td>65.6</td><td>66.7</td><td>44.1</td></tr>
<tr><td>HPSv2</td><td>55.0</td><td>65.3</td><td>70.8</td><td>43.7</td></tr>
<tr><td>UnifiedReward*</td><td>56.9</td><td>59.4</td><td>60.0</td><td>52.7</td></tr>
<tr><td>HPSv3</td><td>58.5</td><td>76.9</td><td>72.9</td><td>41.2</td></tr>
<tr>
<td><strong>PosterReward-Lite</strong></td>
<td><strong>60.5 🥇</strong></td>
<td><strong>77.1 🥈</strong></td>
<td><strong>83.9 🥈</strong></td>
<td><strong>85.0 🥈</strong></td>
</tr>
<tr>
<td><strong>PosterReward</strong></td>
<td><strong>59.6 🥈</strong></td>
<td><strong>77.8 🥇</strong></td>
<td><strong>86.7 🥇</strong></td>
<td><strong>86.0 🥇</strong></td>
</tr>
</tbody>
</table>
🖼️ PosterBench Results
Legend: 🥇 best, 🥈 second best. For Std-Avg, lower is better.
Closed-Source Models
<table>
<thead>
<tr>
<th>Model</th>
<th>Mean ↑</th>
<th>Median ↑</th>
<th>Std-Avg ↓</th>
<th>Bo8-Avg ↑</th>
</tr>
</thead>
<tbody>
<tr><td>Nano-Banana-Pro</td><td><strong>13.36 🥇</strong></td><td><strong>13.47 🥇</strong></td><td>1.91 🥈</td><td><strong>15.77 🥇</strong></td></tr>
<tr><td>Seedream-4.5*</td><td><strong>12.03 🥈</strong></td><td><strong>12.09 🥈</strong></td><td>2.08</td><td><strong>14.57 🥈</strong></td></tr>
<tr><td>Nano-Banana</td><td>11.60</td><td>11.69</td><td>2.17</td><td>14.49</td></tr>
<tr><td>Seedream-4.0</td><td>11.46</td><td>11.44</td><td>2.06</td><td>13.93</td></tr>
<tr><td>GPT-Image-1</td><td>11.16</td><td>11.38</td><td><strong>1.75 🥇</strong></td><td>13.43</td></tr>
<tr><td>Seedream-3.0</td><td>5.01</td><td>5.13</td><td>3.66</td><td>9.75</td></tr>
</tbody>
</table>
Open-Source Models
<table>
<thead>
<tr>
<th>Model</th>
<th>Mean ↑</th>
<th>Median ↑</th>
<th>Std-Avg ↓</th>
<th>Bo8-Avg ↑</th>
</tr>
</thead>
<tbody>
<tr><td>Qwen-Image-2512</td><td><strong>11.86 🥇</strong></td><td><strong>11.63 🥇</strong></td><td><strong>1.46 🥇</strong></td><td><strong>13.85 🥇</strong></td></tr>
<tr><td>Qwen-Image</td><td><strong>7.69 🥈</strong></td><td><strong>7.72 🥈</strong></td><td>2.55</td><td><strong>11.06 🥈</strong></td></tr>
<tr><td>Z-Image-Turbo</td><td>7.65</td><td>7.31</td><td><strong>2.18 🥈</strong></td><td>10.47</td></tr>
<tr><td>Flux.2-klein-9B</td><td>7.38</td><td>7.66</td><td>3.20</td><td>11.67</td></tr>
<tr><td>Flux.1-krea-dev</td><td>5.00</td><td>5.14</td><td>3.59</td><td>9.58</td></tr>
<tr><td>Flux.1-dev</td><td>2.55</td><td>2.42</td><td>3.85</td><td>7.81</td></tr>
<tr><td>SD3.5-L</td><td>-2.90</td><td>-3.92</td><td>2.68</td><td>1.24</td></tr>
</tbody>
</table>
💾 Model Zoo
<table>
<thead>
<tr>
<th>Model</th>
<th>Type</th>
<th>Link</th>
</tr>
</thead>
<tbody>
<tr>
<td>PosterReward_Analyser</td>
<td>Generative VLM for multi-dimensional analysis</td>
<td rowspan="2"><a href="https://huggingface.co/MeiGen-AI/PosterReward_v1/tree/main/PosterReward_analyser">🤗 Hugging Face</a></td>
</tr>
<tr>
<td>PosterReward-Pairwise</td>
<td>Generative pairwise judge</td>
</tr>
<tr>
<td>PosterReward_Scorer</td>
<td>Scalar reward model for scoring</td>
<td><a href="https://huggingface.co/MeiGen-AI/PosterReward_v1/tree/main/PosterReward_scorer">🤗 Hugging Face</a></td>
</tr>
<tr>
<td>PosterReward-Lite</td>
<td>Fast pointwise scorer</td>
<td><a href="https://huggingface.co/MeiGen-AI/PosterReward_v1/tree/main/PosterReward-Lite">🤗 Hugging Face</a></td>
</tr>
</tbody>
</table>
🙏 Acknowledgments
- Thanks to our collaborators and affiliated institutions.
- Thanks to the open-source community and prior reward modeling research.
📝 Citation
Comming Soon!