

- Scope
- Training
- Short and long videos · third-person and egocentric footage
- Verified SFT data · temporal-grounding GRPO
- Resource
- Type
- TimeLens2-4B
- Model
Specs
- ScopeTraining
- Short and long videos · third-person and egocentric footageVerified SFT data · temporal-grounding GRPO
- ResourceType
- TimeLens2-4BModel
- TimeLens2-8BModel
- TimeLens2-93KDataset
- StagePurpose
- sft/XTuner-based supervised fine-tuning
- grpo/Off-policy rollout and GRPO
- evaluation/VLMEvalKit with the TimeLens2 grounding entry
README


Overview · Models and data · Codebase · Reproduction
Find the moments that matter. TimeLens2 turns natural-language queries into precise, traceable evidence intervals on the video timeline.
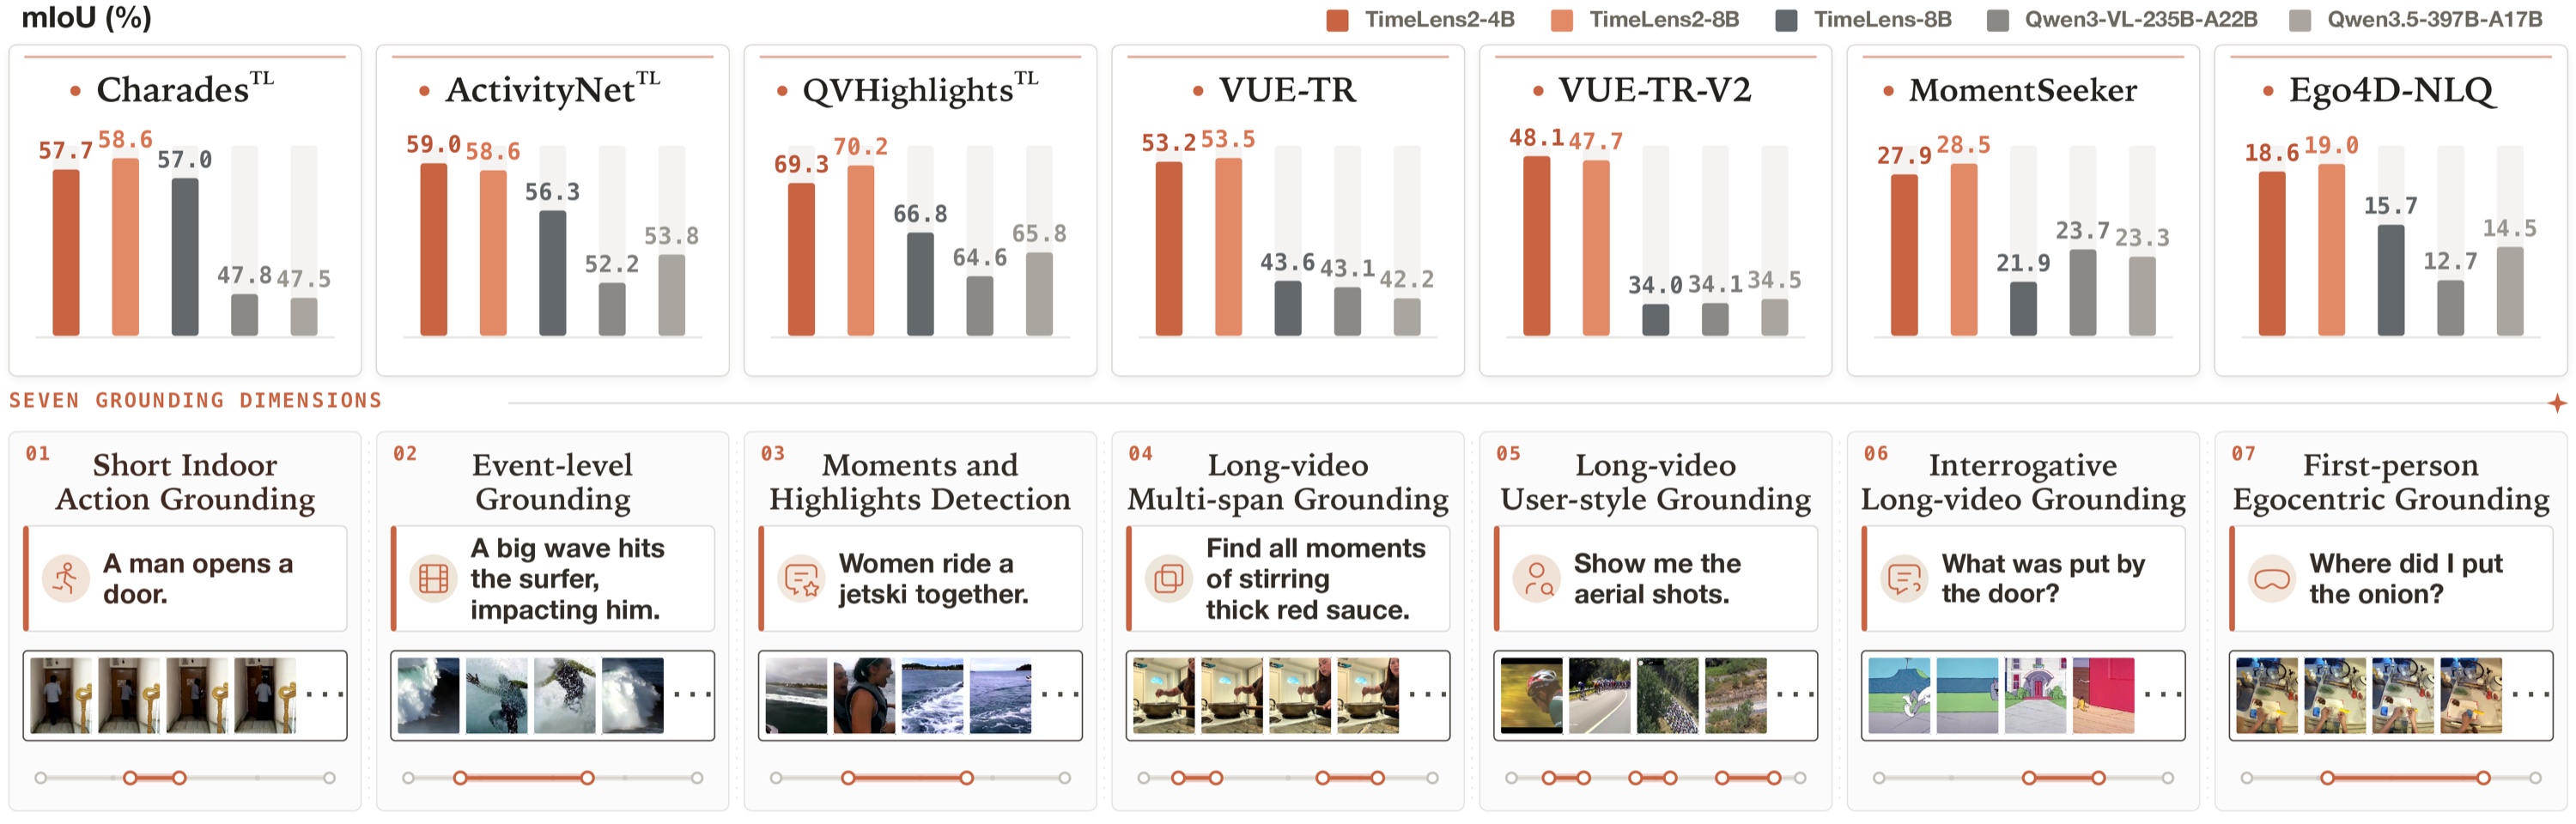 One model family across seven temporal-grounding settings, from short indoor actions to long-form and egocentric video.
Overview
TimeLens2 is a generalist video temporal-grounding MLLM. Given a video and a natural-language description or question, it finds
when the supporting visual evidence occurs and returns one or more temporal
intervals. A single model handles short and long videos, single and repeated
events, descriptive and question-form queries, and both third-person and
egocentric footage through a unified generative interface.
| Scope | Training | Output |
|---|---|---|
| Short and long videos · third-person and egocentric footage | Verified SFT data · temporal-grounding GRPO | One or more precise temporal intervals |
TimeLens2 treats temporal evidence as a set of intervals throughout training.
Its supervised stage uses verified single- and multi-span annotations from
TimeLens2-93K. Its GRPO stage combines temporal IoU with a matching-free temporal
Wasserstein reward. The SFT, GRPO, and evaluation code are released in this
repository.
Models and data
| Resource | Type | Description |
|---|---|---|
| TimeLens2-4B | Model | Compact TimeLens2 checkpoint based on the 4B backbone |
| TimeLens2-8B | Model | Higher-capacity TimeLens2 checkpoint based on the 8B backbone |
| TimeLens2-93K | Dataset | 23,793 videos · 93,232 temporal-grounding pairs |
The repository includes the ready-to-use annotations and rollout data used by
the provided SFT and GRPO recipes. Video files are distributed separately through
the linked Hugging Face dataset and must be downloaded before training. To use
another framework for SFT or RL, download the public data and convert it to that
framework's required format.
Codebase
The official training and evaluation code is organized around the three stages
used in the project:
| Stage | Purpose | Guide | Main entry points |
|---|---|---|---|
sft/ |
XTuner-based supervised fine-tuning | SFT guide | train_sft_4b.sh · train_sft_8b.sh |
grpo/ |
Off-policy rollout and GRPO | GRPO guide | rollout_timelens2.sh · train_grpo_4b.sh · train_grpo_8b.sh |
evaluation/ |
VLMEvalKit with the TimeLens2 grounding entry | Evaluation guide | run_grounding.sh |
Reproduction
- Prepare the videos. Download TimeLens2-93K, TimeLens-100K, and
Ego4D-NLQ. The SFT and GRPO annotations are already included in this repository. - Run supervised fine-tuning. Launch
train_sft_4b.shor
train_sft_8b.sh. - Prepare rollouts. Use the bundled results, or regenerate them with
rollout_timelens2.sh. Its single
configuration includes bothtimelens2-93kandtimelens-100k. - Run GRPO. Launch
train_grpo_4b.shor
train_grpo_8b.sh. Both default to the
bundled official rollout files for both sources. - Evaluate. Run
run_grounding.sh.
Each module has a focused README with installation, data layout, environment
variables, and launch examples. Paths are configurable and may contain
environment variables.
License and acknowledgements
The project is released under the Apache License 2.0. The SFT, evaluation, and
GRPO modules contain code derived from InternLM/xtuner,
open-compass/VLMEvalKit, and
TencentARC/TimeLens, respectively. We
thank their authors for open-sourcing these projects.
Citation
@misc{zhu2026timelens2,
      title={TimeLens2: Generalist Video Temporal Grounding with Multimodal LLMs},
      author={Yuhan Zhu and Changlian Ma and Xiangyu Zeng and Xinhao Li and Zhiqiu Zhang and Songze Li and Jun Zhang and Tianxiang Jiang and Yuandong Yang and Ziang Yan and Zikang Wang and Xinyu Chen and Haoran Chen and Shaowei Zhang and Limin Wang},
      year={2026},
      eprint={2607.17423},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2607.17423},
}