

- name
- weights
- Mask2Former (Swin-T)
- url
- Mask2Former (Swin-L)
- url
- FC-CLIP (ConvNext-B)
- url (*)
Specs
- nameweights
- Mask2Former (Swin-T)url
- Mask2Former (Swin-L)url
- FC-CLIP (ConvNext-B)url (*)
- FC-CLIP (ConvNeXt-L)url
- MAFTP-Burl
- MAFTP-Lurl
- MAFTP-L-PANOurl
README
MaskCLIP++: High-Quality Mask Tuning Matters for Open-Vocabulary Segmentation





News
- [x] (2025.03.13) Paper has been revised.
- [x] (2025.01.03) Add demo.
Introduction
This repo contains the code for our paper.
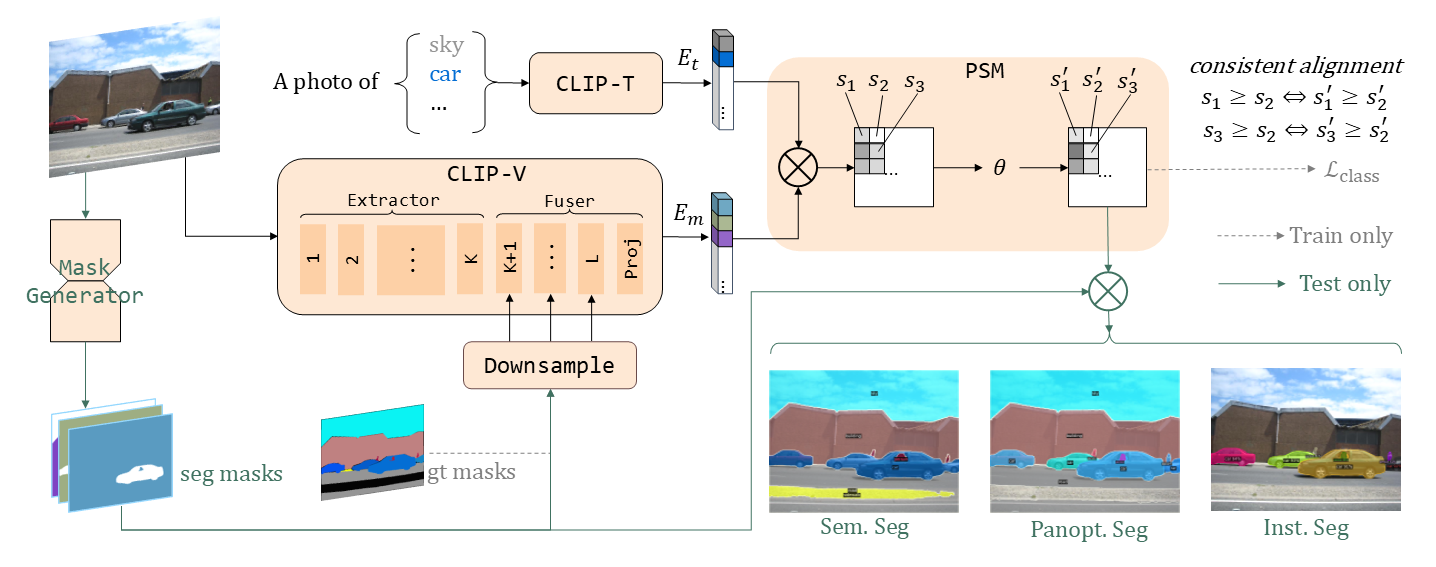
Abstract: Open-vocabulary image segmentation has been advanced through the synergy between mask generators and vision-language models like Contrastive Language-Image Pre-training (CLIP). Previous approaches focus on generating masks while aligning mask features with text embeddings during training. In this paper, we observe that relying on generated low-quality masks can weaken the alignment of vision and language in regional representations. This motivates us to present a new fine-tuning framework, named MaskCLIP++, which uses ground-truth masks instead of generated masks to enhance the mask classification capability of CLIP. Due to the limited diversity of image segmentation datasets with mask annotations, we propose incorporating a consistency alignment principle during fine-tuning, which alleviates categorical bias toward the fine-tuning dataset. After low-cost fine-tuning, MaskCLIP++ significantly improves the mask classification performance on multi-domain datasets. Combining with the mask generator in previous state-of-the-art mask-based open vocabulary segmentation methods, we achieve performance improvements of +1.7, +2.3, +2.1, +3.1, and +0.3 mIoU on the A-847, PC-459, A-150, PC-59, and PAS-20 datasets, respectively.
Installation
See installation instructions.
Preparations
Datasets
See Preparing Datasets for MaskCLIP++.
Pretrained CLIP models
The pre-trained CLIP can be downloaded automatically from huggingface.
Mask generators
All models can be automatically downloaded during runtime. If there are network issues in the runtime environment, you can expand the following table and download the models in the url column to the path location.
<details>
<summary>Unfold</summary>
| name | weights | path |
|---|---|---|
| Mask2Former (Swin-T) | url | output/ckpts/mask2former/coco/pan/maskformer2_swin_tiny_bs16_50ep_final_9fd0ae.pkl |
| Mask2Former (Swin-L) | url | output/ckpts/mask2former/coco/pan/maskformer2_swin_large_IN21k_384_bs16_100ep_final_f07440.pkl |
| FC-CLIP (ConvNext-B) | url(*) | output/ckpts/fcclip/fcclip_coco-pan_clip-convnext-base.pth |
| FC-CLIP (ConvNeXt-L) | url | output/ckpts/fcclip/fcclip_coco-pan_clip-convnext-large.pth |
| MAFTP-B | url | output/ckpts/maftp/maftp_b.pth |
| MAFTP-L | url | output/ckpts/maftp/maftp_l.pth |
| MAFTP-L-PANO | url | output/ckpts/maftp/maftp_l_pano.pth |
Except for the asterisk-marked(*) url, all the other urls are from the original repository
</details>
MaskCLIP++ models
Our model can be combined with the previous mask generator to achieve better open-vocabulary image segmentation performance. The following checkpoint should be manually downloaded to a local path.
Our best checkpoint: EVA02 CLIP-L-14, finetuned both CLIP-V and CLIP-T, on COCO Stuff
(i) Sem. Seg
| Config | A-847 | PC-459 | A-150 | PC-59 | PAS-20 |
|---|---|---|---|---|---|
| FC-CLIP | 14.8 | 18.2 | 34.1 | 58.4 | 95.4 |
| Ours + FC-CLIP | 15.4 | 21.3 | 37.1 | 62.6 | 96.4 |
| MAFTP | 15.1 | 21.6 | 36.1 | 59.4 | 96.5 |
| Ours + MAFTP | 16.8 | 23.9 | 38.2 | 62.5 | 96.8 |
(ii) Panopt. Seg and Inst. Seg
| Config | PQ | SQ | RQ | AP |
|---|---|---|---|---|
| FC-CLIP | 26.8 | 71.5 | 32.2 | 16.8 |
| Ours + FC-CLIP | 27.7 | 72.0 | 33.6 | 17.3 |
| MAFTP | 27.1 | 73.5 | 32.9 | - |
| Ours + MAFTP | 28.1 | 74.0 | 34.7 | - |
<details>
<summary>Other models</summary>
Finetuned CLIP-V, on COCO-Stuff, Use mask generators from MAFTP.
| config | ckpt | A-847 | PC-459 | A-150 | PC-59 | PAS-20 |
|---|---|---|---|---|---|---|
| clip-convnext-base | url | 14.5 | 18.7 | 35.4 | 59.1 | 95.8 |
Finetuned CLIP-V, on COCO-Panoptic, Use mask generators from FC-CLIP. Eval on ADE20K.
| config | ckpt | mIoU | PQ | AP |
|---|---|---|---|---|
| clip-rn50x16 | url | 29.3 | 21.8 | 11.1 |
| clip-convnext-base | url | 35.1 | 24.5 | 13.6 |
| clip-convnext-large | url | 35.6 | 26.5 | 16.7 |
| clip-convnext-xxlarge | url | 36.4 | 27.1 | 16.6 |
| eva-clip-vit-b-16 | url | 33.8 | 24.4 | 13.2 |
| eva-clip-vit-l-14-336 | url | 36.6 | 27.3 | 17.0 |
| eva-clip-vit-g-14-plus | url | 36.8 | 27.7 | 17.1 |
</details>
Usage
Demo
Evaluation
Mask Classification Evaluation
source eval_mask_acc.sh
eval_mask_acc_ade150 $config $ckpt $ngpu $tag 1
# $ngpu is an integer representing the number of GPUs in use.
# $tag is the name of a run.
# more options can be found in eval_mask_acc.sh| Model | Script | A-847 | PC-459 | A-150 | PC-59 | Stuff | Citys | General | Earth | Medical | Engineer | Agriculture |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Origin CLIP | eval_mask_acc_xxx $config "\"\"" $ngpu $tag 0 |
35.2 | 44.8 | 52.7 | 54.6 | 45.0 | 44.9 | 56.9 | 60.5 | 61.7 | 33.8 | 52.4 |
| MaskCLIP++ | eval_mask_acc_xxx $config $ckpt $ngpu $tag 1 |
38.4 | 56.4 | 67.0 | 85.2 | 67.8 | 71.0 | 67.9 | 68.6 | 74.7 | 50.3 | 65.5 |
Mask Accuracy is reported above.
Use the config and our best checkpoint.
OVS Evaluation
source eval_all.sh
eval_ade150 $config $ckpt $ngpu $tag
# $ngpu is an integer representing the number of GPUs in use.
# $tag is the name of a run.
# Other options include: eval_ade847, eval_ctx459, eval_ctx59, eval_pc20
Fine-tuning
For base/large sized CLIPs, the fine-tuning requires about 2-4 hours on 2x NVIDIA 24G 3090 GPUs.
python train_maskclippp.py \
    --config-file $config \
    --num-gpus $ngpu \
    --dist-url "auto" \
    --tag $tag \
    WANDB.ENABLED True
Citing MaskCLIP++
@misc{zeng2025maskclippp,
      title={High-Quality Mask Tuning Matters for Open-Vocabulary Segmentation},
      author={Quan-Sheng Zeng and Yunheng Li and Daquan Zhou and Guanbin Li and Qibin Hou and Ming-Ming Cheng},
      year={2025},
      eprint={2412.11464},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2412.11464},
}
Acknowledgement
Thanks to the following open source code and models: