

Repository
context-scaling
[Tech Report] Context Scaling: Scaling Properties of Text Conditioning in Visual Generation
- Endpoint
- Input
- POST /api/generate_sp
- {user_prompt, width, height}
- POST /api/caption_image
- {image_base64}
- POST /api/generate_image
- {prompt, width, height, num_steps, seed, cfg_scale}
Specs
- EndpointInput
- POST /api/generate_sp{user_prompt, width, height}
- POST /api/caption_image{image_base64}
- POST /api/generate_image{prompt, width, height, num_steps, seed, cfg_scale}
- PathWhat it does
- training/QwenImage DiT training + serving stack (FSDP, NaviT-packed batches, EMA, delta-merge / model-soup checkpoint tools).
- evalkit/Multi-benchmark T2I eval (9 benchmarks), structured-prompt prompter pipeline, and the ED/GPG detailness metrics.
- pe-rsft/Distributed rejection-sampling pipeline that generates SFT (and optionally DPO) data for the prompter.
- demo/The in-process FastAPI + browser studio wrapping PE, captioner, and DiT.
README
Context Scaling: Scaling Properties of Text Conditioning in Visual Generation



Zilong Chen · Chaorui Deng · Kunchang Li · Hongyi Yuan · Haoqi Fan ByteDance Seed [email protected]
We study empirical scaling properties for text conditioning in visual
generation. Such properties have rarely been measured because diffusion
loss does not scale with the number of tokens in natural-language prompts.
Surprisingly, we find that the converged diffusion loss scales with the
amount of structured language in the prompt. To quantify structured
language, we adapt two complementary measures: a white-box likelihood
metric (GPG) and a black-box attribute metric (ED). Across
controlled training runs, the converged diffusion loss decreases
approximately linearly with GPG and follows a power law with ED.Guided by these scaling properties, we improve diffusability by
constructing structured prompts with semantic and geometric annotations
derived from images, and improve promptability by training a prompter
through supervised fine-tuning, cold-start, and verifier-gated on-policy
distillation. The resulting system outperforms all evaluated open-weight
models on nearly every compositional, reasoning, and world-knowledge
benchmark, while matching or surpassing the strongest closed-weight models
on most evaluations.
Highlights
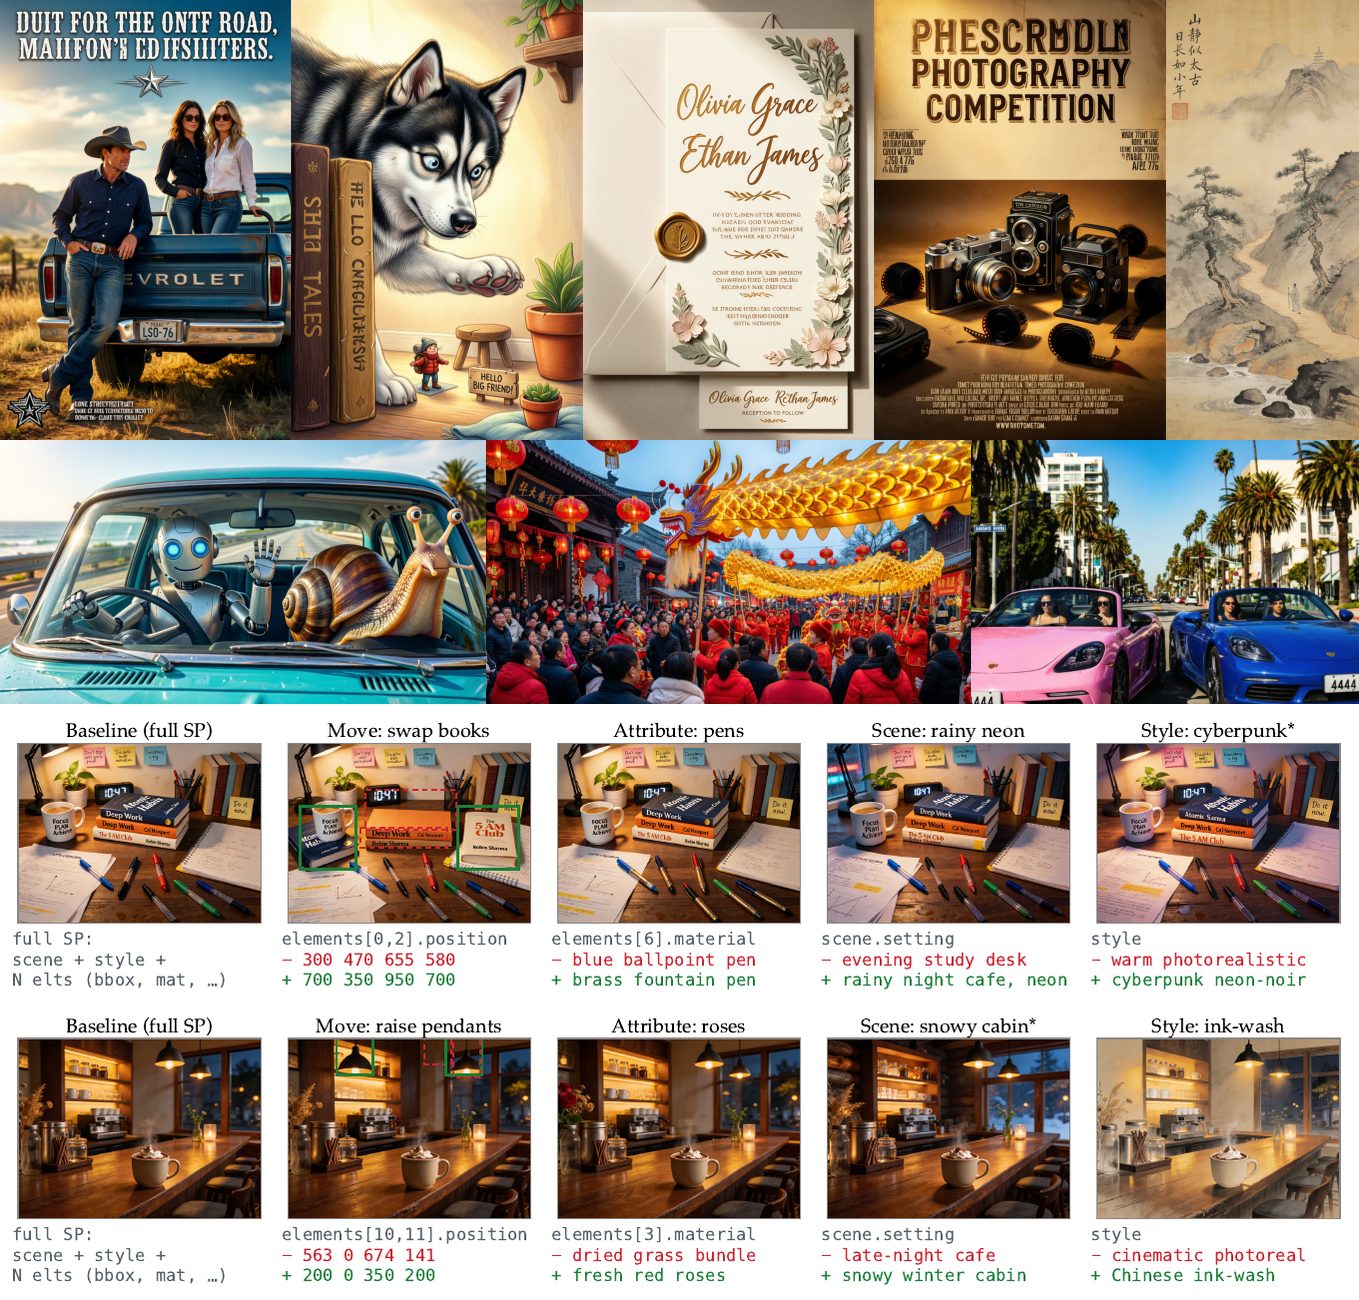
- Scaling laws for text conditioning. A controlled fifteen-cell sweep
showing that converged diffusion loss tracks two caption-information
metrics (GPG, likelihood-based; ED, attribute-based) much more
tightly than it tracks caption length. - Structured prompts (SP) as a diffusability upgrade — a JSON schema
with semantic and geometric fields, annotated by expert models. - A trainable LLM prompter + captioner that turns a user request or
an image into SP. - Zero-shot structured editing — SP exposes each factor as a named
field, so targeted edits regenerate an image with the rest of the
composition preserved.
Installation
git clone https://github.com/heheyas/context-scaling.git
cd context-scaling
pip install -r requirements.txt
CUDA 12, torch >= 2.4, flash-attn. The demo, ED/GPG scoring, and
serving pipelines run on a single GPU (2 for the demo); DiT training
expects multi-GPU FSDP.
Quickstart
Try the demo — PE → DiT + image captioner in the browser
Boots one FastAPI process on a 2-GPU box: the released prompter LLM
(heheyas/SP-PE-Qwen3.5-35B-A3B)
plus the fine-tuned DiT (heheyas/Qwen-Image-SP),
both loaded resident in GPU memory, fronted by an HTML studio at
http://localhost:7860/.
pip install -r demo/requirements.txt
python demo/build_index.py            # one-off: assemble the studio HTML
export CUDA_VISIBLE_DEVICES=0,1
python -m demo.app                    # → http://localhost:7860/
Both PE_CKPT and DIT_CKPT default to the released HF Hub repos;
first launch downloads ~110 GB and merges the DiT overlay shards into a
cached file under $HF_HOME/context-scaling/. Subsequent launches take
seconds.
The demo exposes three JSON endpoints:
| Endpoint | Input | Output | System prompt |
|---|---|---|---|
POST /api/generate_sp |
{user_prompt, width, height} |
{sp: ...} |
rft_iter0_with_ratio_v6_synthesis_student.txt |
POST /api/caption_image |
{image_base64} |
{sp: ...} |
image2json.txt — bboxes on a 1000×1000 grid |
POST /api/generate_image |
{prompt, width, height, num_steps, seed, cfg_scale} |
{image_base64} |
— |
generate_sp and caption_image share the same VLM weights (loaded
once); the difference is text-only vs multimodal chat template + the
corresponding system prompt. caption_image accepts either raw base64
or a full data:image/png;base64,… URL:
IMG=$(base64 -w0 /path/to/some_image.png)
curl -s -X POST http://localhost:7860/api/caption_image \
  -H "Content-Type: application/json" \
  -d "{\"image_base64\": \"$IMG\"}" | jq .sp
Full env-var reference (GPU pinning, HF token for gated repos, PE memory
caps) and Hugging Face Docker Space deployment recipe live in
demo/README.md.
Measure caption quality of a dataset — ED + GPG
Score one or both metrics over an (image, caption) JSONL. Use this to
compare captions from different sources (human, GPT-4o, Gemini, your
prompter) on the same image pool.
{"image": "/abs/path/to/img.png", "caption": "A short caption.", "uid": "row-0001"}# ED only — no GPU, LLM-bound (Gemini-3-pro + GPT-4o).
export GEMINI_API_KEY_FILE=<path> # one Gemini key per line
export GEMINI_API_CONFIG=<path> # GPT-4o key JSON (matcher)
python -m evalkit.detailness.evaluator \
--jsonl /path/to/dataset.jsonl \
--out /tmp/scored_ed.jsonl \
--metrics ed
# ED + GPG — needs one GPU for Qwen3-VL-8B-Instruct forward passes.
python -m evalkit.detailness.evaluator \
--jsonl /path/to/dataset.jsonl \
--out /tmp/scored_both.jsonl \
--metrics ed,gpg \
--gpg-model <WEIGHTS_ROOT>/Qwen3-VL-8B-Instruct \
--gpg-device cuda:0Each output row is the input row plus:
{"ed": 0.27, "ed_F05_A": 0.27, "ed_P_A": 1.0, "ed_R_A": 0.07,
 "gpg": 0.382, "gpg_total_nats": 289.4, "gpg_n_tokens": 758, ...}
Higher is more informative. See
evalkit/detailness/README.md for
metric definitions, cache options, and per-metric CLIs.
Repo layout
Everything past the quickstart lives in per-package docs.
| Path | What it does | Doc |
|---|---|---|
training/ |
QwenImage DiT training + serving stack (FSDP, NaviT-packed batches, EMA, delta-merge / model-soup checkpoint tools). | docs/training.md |
evalkit/ |
Multi-benchmark T2I eval (9 benchmarks), structured-prompt prompter pipeline, and the ED/GPG detailness metrics. | docs/evalkit.md |
pe-rsft/ |
Distributed rejection-sampling pipeline that generates SFT (and optionally DPO) data for the prompter. | docs/pe-rsft.md |
demo/ |
The in-process FastAPI + browser studio wrapping PE, captioner, and DiT. | demo/README.md |
Citation
@article{chen2026contextscaling,
  title   = {Context Scaling: Scaling Properties of Text Conditioning in Visual Generation},
  author  = {Chen, Zilong and Deng, Chaorui and Li, Kunchang and Yuan, Hongyi and Fan, Haoqi},
  journal = {Technical Report, ByteDance Seed},
  year    = {2026}
}
Acknowledgements
This release stands on the shoulders of several open-source projects.
We are grateful to their authors and maintainers.
- Qwen-Image (Alibaba) — DiT
architecture, tokenizer, and reference pipeline that
training/modeling/qwenimage/and the demo'sQwenImagePipelineare
built on. Also Qwen2.5-VL for
training/modeling/qwen2/. - Bagel — provided the
Bagel training runs used as the ground-truth MSE side of the ED/GPG
scaling-law measurements inevalkit/detailness/. - ms-swift (ModelScope) —
used to serve and fine-tune the prompt-expansion LLM (PE) throughout
the RFT loop inpe-rsft/. - huggingface/diffusers
and huggingface/transformers
— modeling primitives underpinningtraining/modeling/. - Evaluation benchmarks (vendored under
evalkit/context-scaling/benchmarks/):
GenEval, GenEval2, GenEval++ (Echo-4o), DPG-Bench (ELLA), OneIG-Bench,
TIIF-Bench, T2I-CoReBench, GenExam, WISE — each used under its own
upstream license (see per-benchmarkLICENSEfiles and
NOTICE for the full attribution list).