

Repository
kimi-k3-in-c
A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU.
- OS
- OS
- CPU
- CPU
- RAM
- RAM
- Storage
- Storage
Specs
- OSOS
- CPUCPU
- RAMRAM
- StorageStorage
- ToolchainToolchain
- PythonPython
- flagargument
- --promptTEXT
- --prompt-filePATH
- --ids1,2,3
- flagargument
- --presetNAME
- --trunk-gbX
- --cache-gbX
- flagargument
- --genN
- --incrementalnone
- --tokDIR
- flagargument
- --configPATH
- --layersN
- --outFILE
- --dump-logitsPATH
- --dump-cache-traceDIR
- 0success
- 1a tensor failed to bind, or a forward pass failed
- 2usage error, or a config that could not be read with confidence; the engine declines to guess
- 4the run finished, but at least one routed expert failed to load, so the emitted ids are unsound. Distinct from 1 because the process otherwise succeeded, and it is the code that catches silent numerical corruption
- variableused by
- HF_TOKENdownload-model.sh
- OMP_NUM_THREADSthe engine
- K3_TOK_FILEStokenizer tools and CI
- K3_MODEL_DIRtools/budget.py
README
kimi-k3-in-c
A 2.78-trillion-parameter model. One CPU. 8 GB of RAM.
Kimi K3 inference in portable C99.No BLAS. No framework. No GPU.


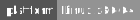

<br>
$ ./bin/k3 ~/k3model --trunk ~/k3trunk --preset laptop \
           --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental

--- generated text ---
 Paris.",
+            "The Eiffel
----------------------
8 tokens in 261.5 s, 32.69 s/token average
PEAK RSS for the whole run: 8.24 GB
Slow, and answering correctly, in 8.24 GB, from a checkpoint of 1.56 TB. This is a base
model, so what follows " Paris." is a continuation rather than a reply; there is no chat
template. Give it more memory and the answer does not change, only the clock:
$ ./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
           --tok ~/k3model --prompt "def fibonacci(n):" --gen 28 --incremental

--- generated text ---
    if n <= 1:
        return n
    else:
        return fibonacci(n-1) + fibonacci
----------------------
28 tokens in 299.3 s, 10.69 s/token average
PEAK RSS for the whole run: 127.92 GB
Every figure in this document comes from the measurement output in
docs/data/.
The dense trunk stays in memory to whatever depth you choose and streams the rest; the
1.45 TB of routed experts are never resident, and are multiplied straight out of their
packed 4-bit form. The consequence is that the same model runs in 8 GB and in 224 GB and
produces byte-identical output at every budget between.
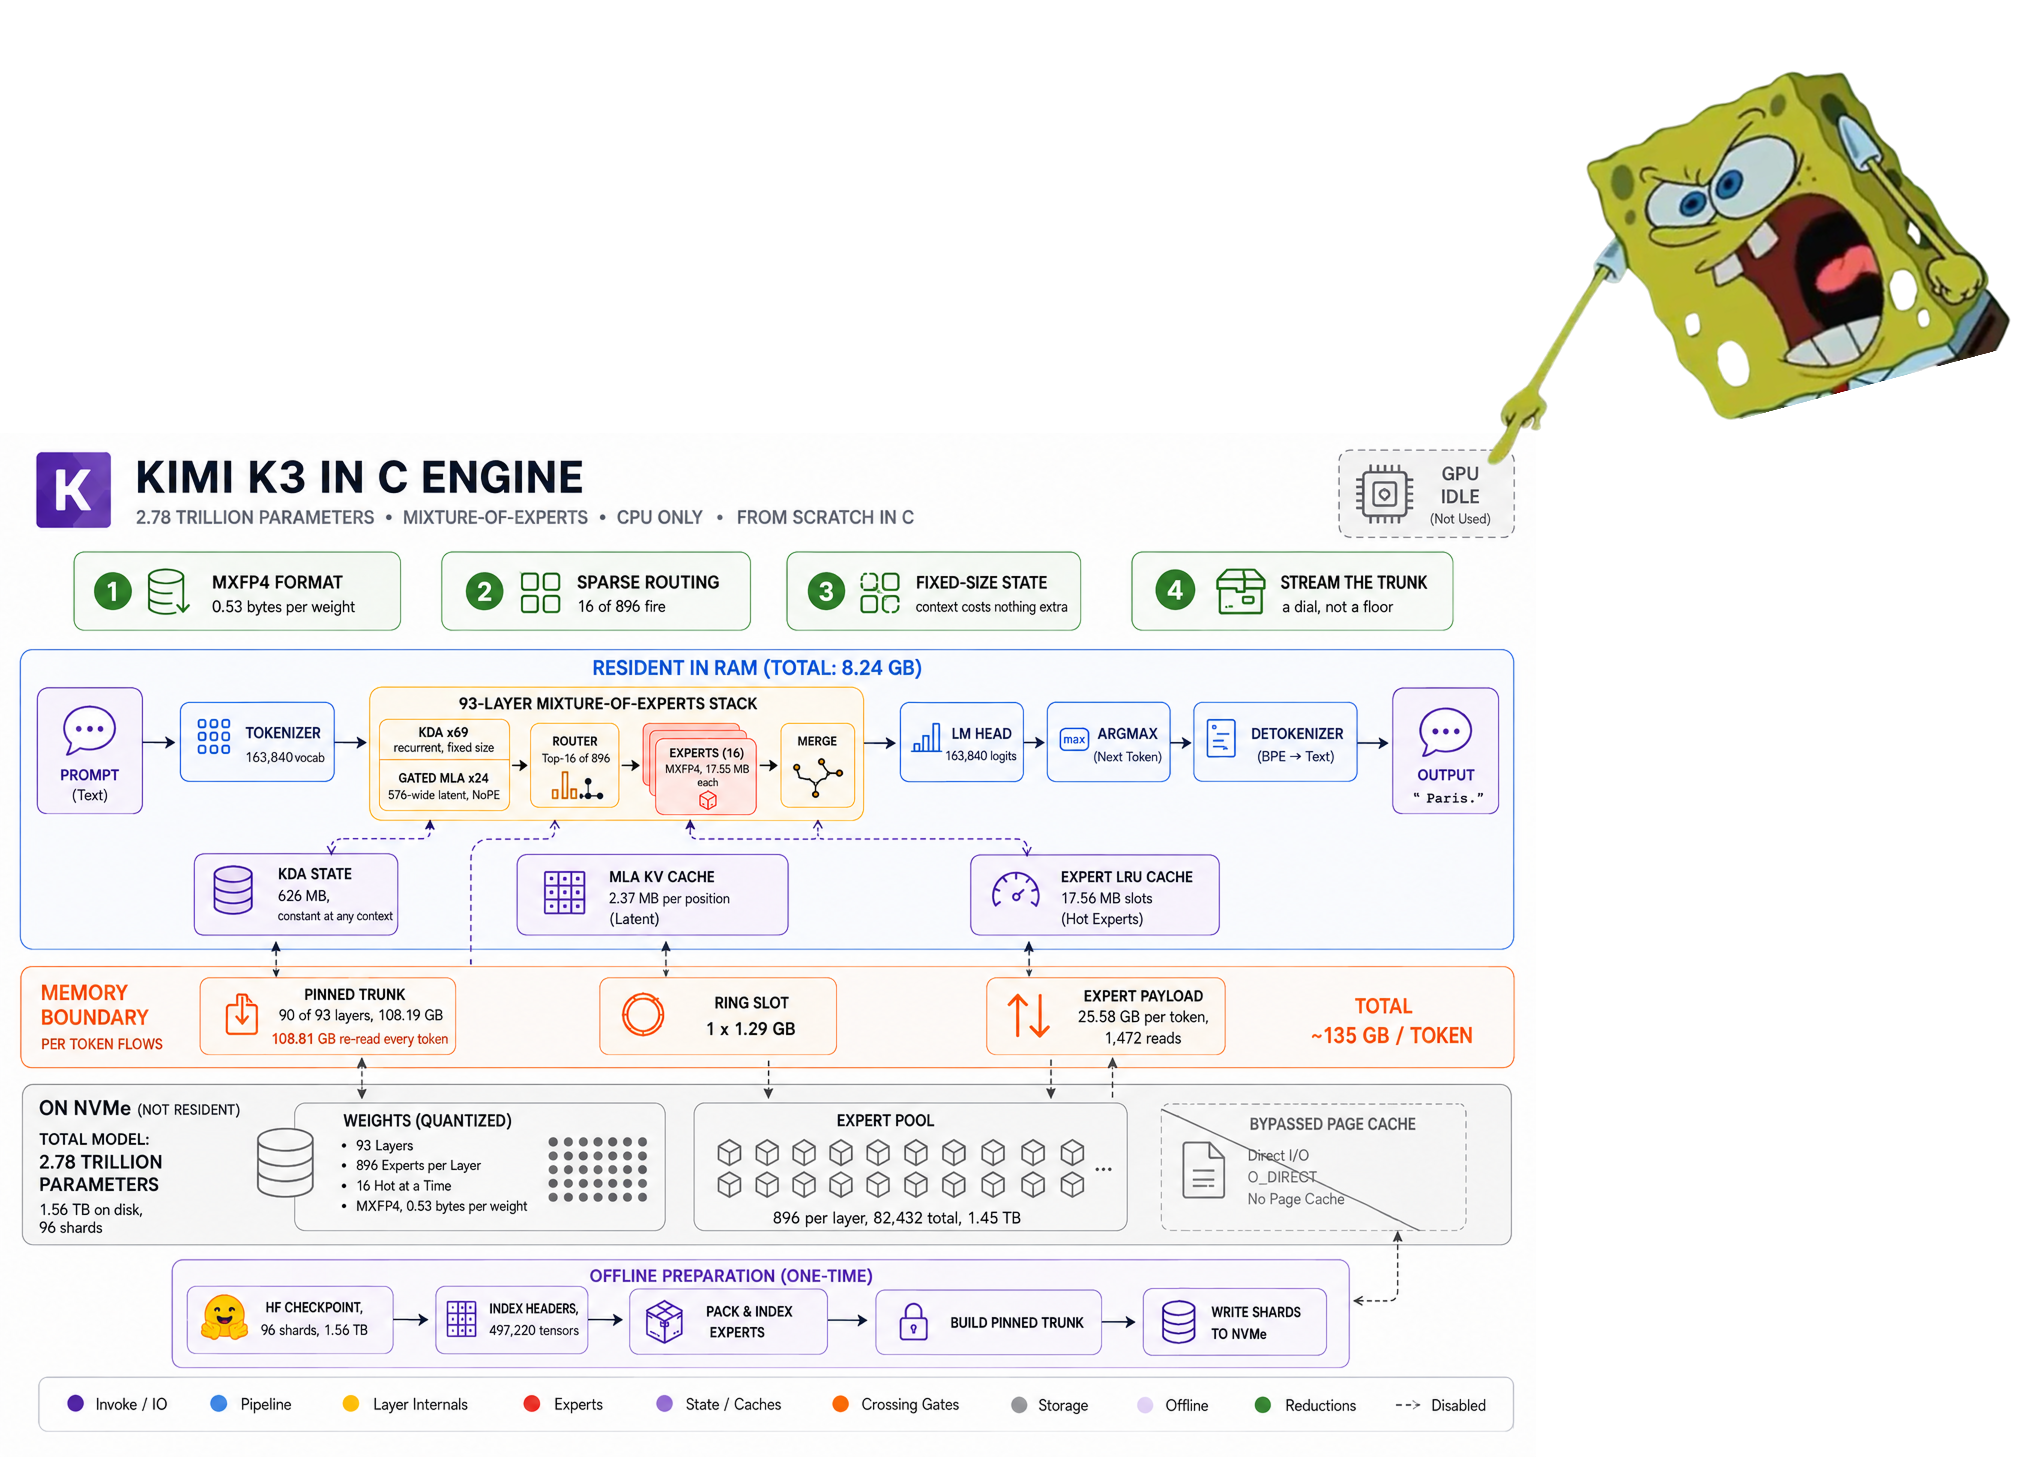
Four decisions about where bytes live take it from a cluster to a laptop, and the answer
at the bottom is the same as the answer at the top:
Part II builds every box in both diagrams from scratch, one
component at a time.
Contents
- Requirements
- Quick start: clone, build and verify in about a minute, with no model
- Full setup: the whole path to generated text
- Usage
- Choosing a preset
- Reading the run report
- Common questions
- The problem: a model that does not fit
- The four reductions
- The machine, and what it assumes
- The codebase
- Five invariants
- 1. Reading a 1.56 TB checkpoint from its headers
- 2. The config reader that refuses to guess
- 3. The tokenizer, byte for byte
- 4. Reduction one: the experts already ship at half a byte
- 5. Kernels with a floating point contract
- 6. Reduction two: KDA, attention with a memory that never grows
- 7. Reduction three: MLA, one latent instead of ninety-six heads
- 8. Attention residuals: layers that look back
- 9. Picking 16 experts of 896
- 10. Packing the trunk: 93 layers, one read each
- 11. Reduction four: streaming the trunk turns a floor into a dial
- 12. An LRU cache for the experts
- 13. How big should that cache be? Ask the trace
- The gate ladder
- A tiny oracle first
- Proving it on the full checkpoint
- The first tokens
- Sustained generation: text in, text out
- The memory ladder: 8 GB to 224 GB
- The cache that was not participating
- Allocation beats capacity
- Measuring the measurement
- Storage is the whole game
- Why the trunk is not quantised
Part I: Getting started
Requirements
The gate is storage: the checkpoint is 1.56 TB. Everything else is ordinary.
| OS | Linux, x86-64 | uses O_DIRECT, posix_memalign, getrusage |
| CPU | AVX2 + FMA | AVX-512 unnecessary. make portable targets generic AVX2 |
| RAM | 8 GB and up | every preset works; more memory is faster, never different |
| Storage | ~1.7 TB free | 1.56 TB checkpoint + 109 GB packed trunk, ideally on fast local disk |
| Toolchain | GCC ≥ 9 or Clang ≥ 10 | GNU make, or CMake |
| Python | 3.9+ | for the download, pack and analysis tools; not for make test |
The tokenizer and config reader are portable C99 and build anywhere. Without a checkpoint
you can still do everything in Quick start.
Quick start
Clone, build and run the entire test suite. No checkpoint, no network, no Python. The
whole thing takes about a minute.
git clone https://github.com/FareedKhan-dev/kimi-k3-in-c.git
cd kimi-k3-in-c

make -j            # seconds. Seven C files, a compiler and OpenMP
make test          # under a minute
It ends like this, or it failed:
GATE 1  teacher forcing : 32/32 positions match tf_pred
        generated span  : 20/20  <- must be exact
GATE 2  greedy decode   : 20/20 generated tokens match full_ids
GATE 3  incremental    : 20/20 generated tokens match full_ids  <- KV cache + carried KDA state

VERDICT: ENGINE MATCHES THE REFERENCE EXACTLY

ALL WEIGHTLESS TESTS PASSED
That is the whole engine: every kernel, the streaming cache, the safetensors reader, the
config reader, the tokenizer, and an end-to-end oracle over a 13-layer model built with the
same tensor graph as the released one, checked against a PyTorch reference from fixtures
committed to the repository.
One published measurement also replays on the spot, from a trace recorded during a full
93-layer run (this one needs Python 3.9+ and numpy):
python3 tools/sim_cache.py tests/fixtures/expert_trace.bin100,096 expert requests, reprinting the capacity table in
expert-cache-capacity.txt.
Full setup
Six steps from an empty directory to generated text. Only step 4 is slow.
./scripts/k3-doctor.sh can be run at any point. It checks the toolchain, sizes your RAM
to a preset, measures your storage, and prints the exact command to run next.
Step 0. clone
git clone https://github.com/FareedKhan-dev/kimi-k3-in-c.git
cd kimi-k3-in-c
About 45 MB, most of it the diagrams and the test fixtures.
Step 1. check the machine
./scripts/k3-doctor.shTakes about a minute, because it measures your disk the way the engine reads it. It exits
non-zero if the machine cannot run the model at all.
Step 2. build
make -jSeconds. The only dependencies are a C99 compiler, libm and OpenMP. CMake works too:
cmake -B build && cmake --build build -j && ctest --test-dir buildStep 3. verify before downloading anything
make testThis is worth doing before committing to a 1.56 TB download: it proves the engine matches
its reference on a model with the same tensor graph, and it needs nothing but the
repository.
Step 4. fetch the checkpoint
1.56 TB, so hours rather than minutes. Get a token from
huggingface.co/settings/tokens:
export HF_TOKEN=hf_your_token_here          # read from the environment, never echoed
./scripts/download-model.sh ~/k3model       # resumable, re-run to continue
The script finishes by verifying the shard count, the exact byte total, and then every
individual per-shard size against the published figures:
verifying…
  shards : 96 (expect 96)
  bytes  : 1560936091448 (expect 1560936091448)
  shards : all 96 match their published sizes individually
  RESULT : byte-exact match
A partial download does not fail loudly; it produces wrong tokens. Treat a FAIL here as
a stop. Checking per shard also turns "re-download 1.56 terabytes" into "re-download this
one 17 gigabyte file", and it catches the one case a total cannot: two shards wrong in
opposite directions by the same amount.
Step 5. pack the trunk
./scripts/pack-trunk.sh ~/k3model ~/k3trunkAbout four minutes, once. It rewrites the 93 dense layers into one 109 GB file where layer
L lives at a known offset and can be read in a single call. This is what turns the
memory requirement into a dial. Put the output on the fastest disk you have.
Step 6. run
./bin/k3 ~/k3model --trunk ~/k3trunk --preset workstation \
         --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental
The tokenizer ships with the checkpoint, which is why --tok points at the model
directory.
Where everything ends up
kimi-k3-in-c/    ~45 MB   source, docs, images, and bin/k3
~/k3model/      1.56 TB   96 shards · config.json · tiktoken.model · tokenizer_config.json
~/k3trunk/       109 GB   trunk.bin · trunk.json, on the fastest disk you have
The first token of any run loads every pinned layer from disk, about 108 GB at the
server preset, so it takes far longer than the steady rate. That cost is paid once per
run, not once per token.
Usage
Synopsis
k3 <model_dir> [prompt] [memory] [generation] [diagnostics]<model_dir> is the directory holding the .safetensors shards. It is required for any
run, but --help, --version and --list-presets work without it:
./bin/k3 --help
./bin/k3 --version
./bin/k3 --list-presets
Prompt options
Exactly one of these is required. Passing none, or more than one, is a usage error
(exit 2).
| flag | argument | |
|---|---|---|
--prompt |
TEXT |
tokenize TEXT and run it. Requires --tok. |
--prompt-file |
PATH |
tokenize the file's bytes. Requires --tok. Preferred for anything non-ASCII: the shell re-encodes argv, whereas a file is read verbatim |
--ids |
1,2,3 |
token ids directly. No tokenizer is loaded at all, so this works on a machine with no tokenizer files. The reproducible channel the tests use |
# text in
./bin/k3 ~/k3model --tok ~/k3model --prompt "The capital of France is" ...

# text in, from a file. Use this for CJK, emoji, accents
printf 'La capitale de la France est' > /tmp/p.txt
./bin/k3 ~/k3model --tok ~/k3model --prompt-file /tmp/p.txt ...

# ids in, ids out, no tokenizer needed
./bin/k3 ~/k3model --ids 1008,10484,318,15383,387 ...
Memory options
| flag | argument | default | |
|---|---|---|---|
--preset |
NAME |
none | laptop · desktop · workstation · server · max. Sets both budgets below |
--trunk |
DIR |
off | the packed trunk directory from step 5. This is what enables streaming. Without it the trunk loads fully resident, around 113.5 GB |
--trunk-gb |
X |
16 | budget for pinned layers plus the streaming ring |
--cache-gb |
X |
64 | budget for the routed-expert LRU cache |
--preset and the two -gb flags set the same two numbers, so a preset is just a
shorthand. Order matters if you mix them: a later flag wins, so
--preset server --cache-gb 40 gives you the server trunk budget with a 40 GB cache.
--presetwithout--trunkdoes nothing useful. Every preset assumes the trunk is
streamed. Omit--trunkand the engine loads all 113.5 GB resident regardless of the
budget you asked for.
Generation options
| flag | argument | default | |
|---|---|---|---|
--gen |
N |
8 | tokens to generate. Ceiling 4096; prompts may be up to 32768 tokens |
--incremental |
none | off | carry the KV cache and the recurrent state between tokens instead of re-running the whole prefix |
--tok |
DIR |
none | directory holding tiktoken.model and tokenizer_config.json |
Pass --incremental for any generation of length. Without it every step re-runs the
entire prefix, which is O(T²); with it, step 0 pays for the prompt and every later step
costs the same fixed amount. Both paths are gated on producing identical tokens, so this
is a pure speed choice.
Diagnostic options
| flag | argument | |
|---|---|---|
--config |
PATH |
model config; defaults to <model_dir>/config.json |
--layers |
N |
bind only the first N layers, for partial shard sets |
--out |
FILE |
JSON results (default k3_run.json) |
--dump-logits |
PATH |
float32 logits for the first step, for elementwise comparison |
--dump-cache-trace |
DIR |
writes expert_hist.json and expert_trace.bin, which tools/sim_cache.py replays |
Exit codes
Scripts can rely on these.
0 |
success |
1 |
a tensor failed to bind, or a forward pass failed |
2 |
usage error, or a config that could not be read with confidence; the engine declines to guess |
4 |
the run finished, but at least one routed expert failed to load, so the emitted ids are unsound. Distinct from 1 because the process otherwise succeeded, and it is the code that catches silent numerical corruption |
Environment variables
| variable | used by | |
|---|---|---|
HF_TOKEN |
download-model.sh |
HuggingFace token, read from the environment and never echoed |
OMP_NUM_THREADS |
the engine | thread count, defaulting to all cores |
K3_TOK_FILES |
tokenizer tools and CI | directory holding tiktoken.model, when it is not in a default location |
K3_MODEL_DIR |
tools/budget.py |
checkpoint directory, when not given as an argument |
Worked examples
# Smallest possible run, the 8 GB floor.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset laptop \
         --tok ~/k3model --prompt "Hello! My name is" --gen 16 --incremental

# Fastest per gigabyte. Pins 90 of 93 trunk layers.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
         --tok ~/k3model --prompt "def fibonacci(n):" --gen 28 --incremental

# Hand-tuned split instead of a preset: everything to the trunk.
./bin/k3 ~/k3model --trunk ~/k3trunk --trunk-gb 110 --cache-gb 13 \
         --tok ~/k3model --prompt-file prompt.txt --gen 32 --incremental

# Reproducible: ids in, ids out, no tokenizer, JSON results.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset desktop \
         --ids 1008,10484,318,15383,387 --gen 8 --incremental --out run.json

# Capture a cache trace, then replay it offline at any capacity.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset workstation \
         --ids 1008,10484,318,15383,387 --gen 8 --incremental \
         --dump-cache-trace /tmp/trace
python3 tools/sim_cache.py /tmp/trace/expert_trace.bin

# Elementwise logit comparison against the PyTorch reference.
./bin/k3 ~/k3model --trunk ~/k3trunk --preset server \
         --ids 3,4,5,6,7 --gen 1 --dump-logits /tmp/c_logits.bin
python3 tools/cmp_logits.py /tmp/c_logits.bin ref_logits.json

# Partial shard set: bind only the first 8 layers.
./bin/k3 ~/k3model --trunk ~/k3trunk --layers 8 \
         --ids 1,2,3 --gen 1

# Under a hard memory ceiling, which is how the ladder was measured.
systemd-run --scope --user -q -p MemoryMax=8G -p MemorySwapMax=0 \
  ./bin/k3 ~/k3model --trunk ~/k3trunk --trunk-gb 2.5 --cache-gb 0.5 \
           --ids 1008,10484,318,15383,387 --gen 8 --incremental
Choosing a preset
$ ./bin/k3 --list-presets
presets (trunk / expert-cache, in GB):
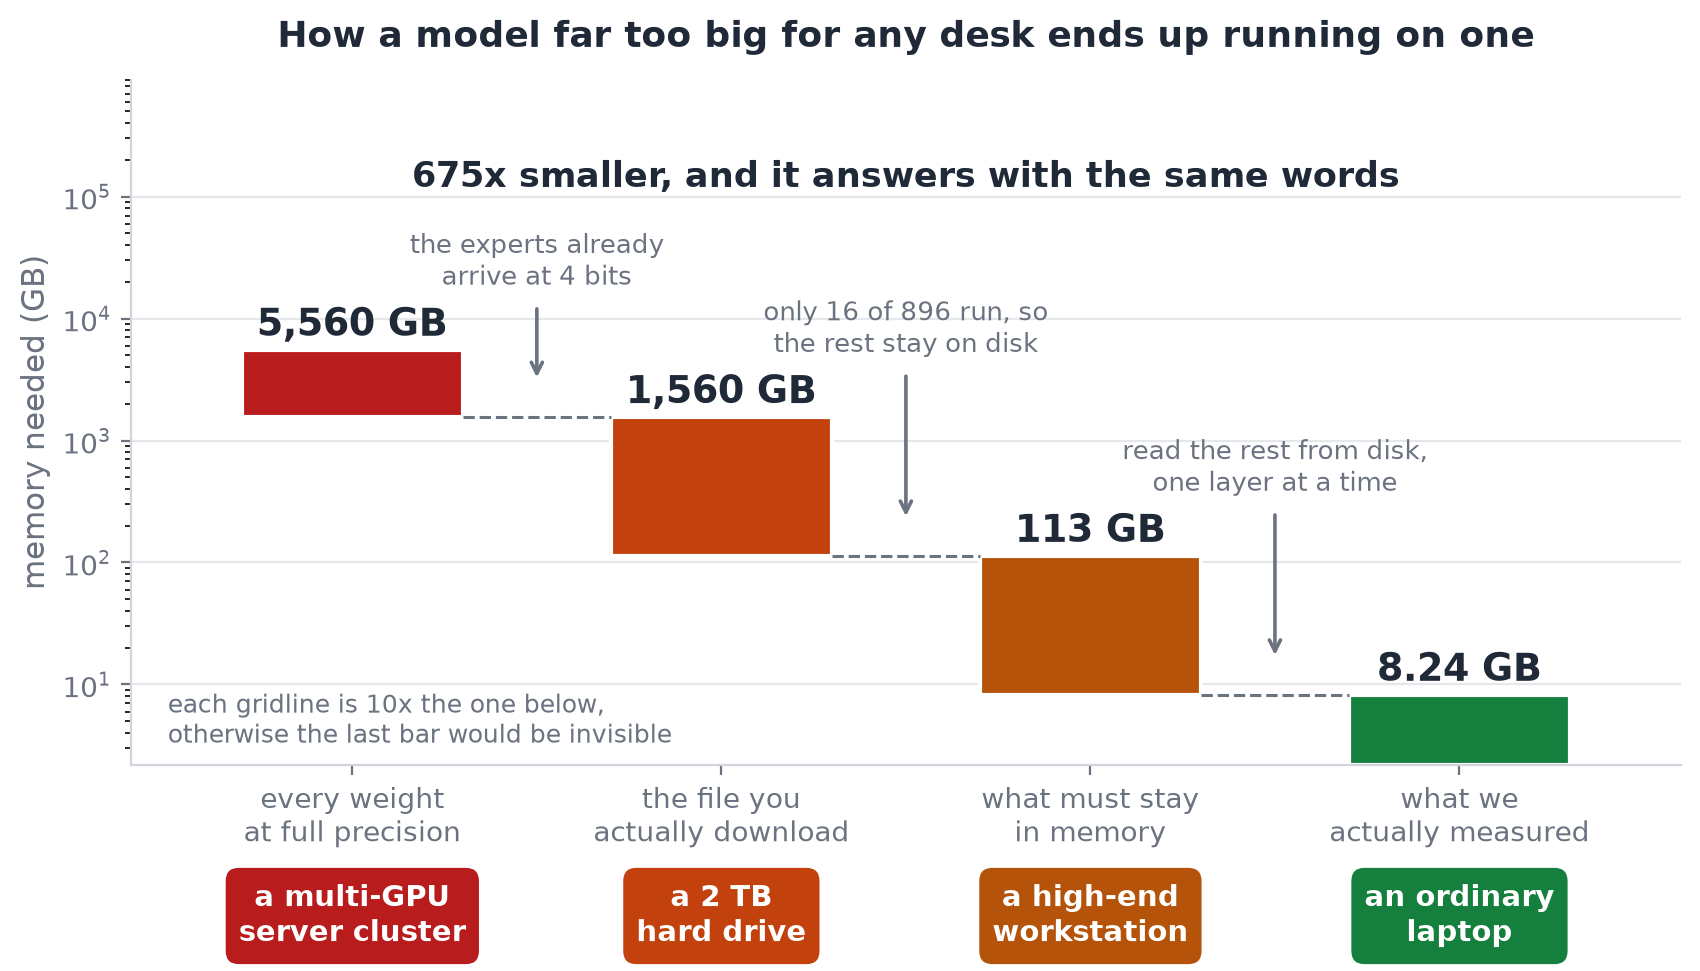
  laptop          3.0 / 1.0     8.2 GB peak RSS. The floor. Runs, slowly.
  desktop        16.0 / 10.0    31.9 GB peak RSS.
  workstation    60.0 / 30.0    95.5 GB peak RSS; the expert cache starts to matter here.
  server        110.0 / 13.0    ~128 GB peak RSS; 90 of 93 trunk layers pinned. Fastest.
  max           110.0 / 109.0   ~224 GB peak RSS; trunk pinned and a large expert cache.

All presets stream the trunk, so they need --trunk <packed_dir>.
Run scripts/k3-doctor.sh to see which one this machine fits.
The boundaries come from the measured ladder, and the doctor keys on MemAvailable rather
than MemTotal:
if   [ "$AVAIL_GB" -ge 192 ]; then PRESET=server;      EXPECT="~19-21 s/token"
elif [ "$AVAIL_GB" -ge  96 ]; then PRESET=workstation; EXPECT="~24 s/token"
elif [ "$AVAIL_GB" -ge  32 ]; then PRESET=desktop;     EXPECT="~28-31 s/token"
elif [ "$AVAIL_GB" -ge  10 ]; then PRESET=laptop;      EXPECT="~32 s/token"
else PRESET=""; fi
Two things worth knowing before you pick:
maxis not faster thanserverin these measurements. The extra 96 GB buys nothing
outside the noise floor.- Give the trunk memory before the expert cache. At a fixed 128 GB budget that was
worth 1.69×. Allocation beats capacity has the data.
Reading the run report
The engine prints a memory plan, then a line per generated token, then a summary. Abridged
from a workstation run:
cache [final step]
  requests     : 1472  hits 1472 (100.00%)  misses 0  evictions 729
                 TRUE resident hit rate 50.48%
I/O share of wall clock: 71.1%  (trunk 62.4 s + experts 34.2 s of 135.8 s)
trunk [final]
  pinned 48/93 layers, ring 1 slots
  read 368.65 GB in 62.40 s (5908 MB/s)
PEAK RSS for the whole run: 94.74 GB   <- quote this, not the plan
Three numbers carry the meaning:
TRUE resident hit rate: experts served from RAM. The rawhitscounter also
counts experts the prefetcher pulled off disk moments earlier, so it reads 100% at every
cache size; the resident figure is printed beneath it.I/O share of wall clock: whole-run disk time against total, measured between 41%
and 61% across the ladder.PEAK RSS: fromgetrusage, after the run. This is the memory figure; the up-front
plan runs slightly above it.
Common questions
Memory sits near 113 GB even at a small preset. --trunk was omitted. Without a packed
trunk directory the whole trunk is loaded resident; every preset assumes streaming.
A non-ASCII prompt tokenizes oddly. The shell re-encodes argv, so the engine receives
different bytes than you typed. Put the prompt in a file and use --prompt-file, which is
read verbatim.
--prompt/--prompt-file need --tok DIR. The tokenizer ships with the checkpoint, so
add --tok ~/k3model. The engine exits rather than guessing where the vocabulary lives. To
skip the tokenizer entirely, pass token ids with --ids.
Throughput is well below the table. Almost always storage. python3 tools/devbw.py <file-on-that-disk> measures the disk the way the engine reads it, using large random
O_DIRECT reads at queue depth 1 and 16, which dd does not. Network volumes run several
times slower than local NVMe; keep ~/k3trunk local.
The run refused to start over the KV cache. Context costs about 2.37 MB per position
regardless of budget, and the engine computes that up front rather than discovering it an
hour in. Shorten the request, or drop --incremental, which carries no KV cache at all.
Is the whole 1.56 TB needed? For generation, yes. For development, no: make test
needs nothing at all, and --layers N runs against partial shard sets.
macOS, Windows, WSL? The engine targets Linux. The tokenizer and config reader are
portable C99 and are built portably in CI.
Part II: How it works
The problem: a model that does not fit
Kimi K3 has 2.78 trillion parameters and
is 1.56 terabytes as shipped. No consumer machine can hold it, and waiting for better
hardware does not help, because the wall is not speed, it is capacity.
But it is a mixture of experts, so only 16 of its 896
experts per layer fire for any given token and the rest sit asleep on disk. Keep the
always-on part in memory, stream the sleeping experts, and it fits in 8.24 gigabytes
on one CPU with no GPU.
The naive requirement is the one every parameter count implies.
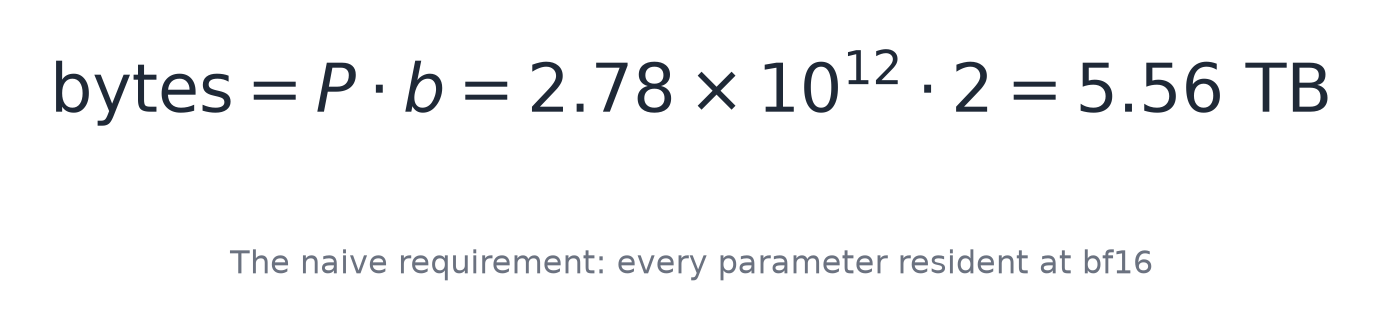
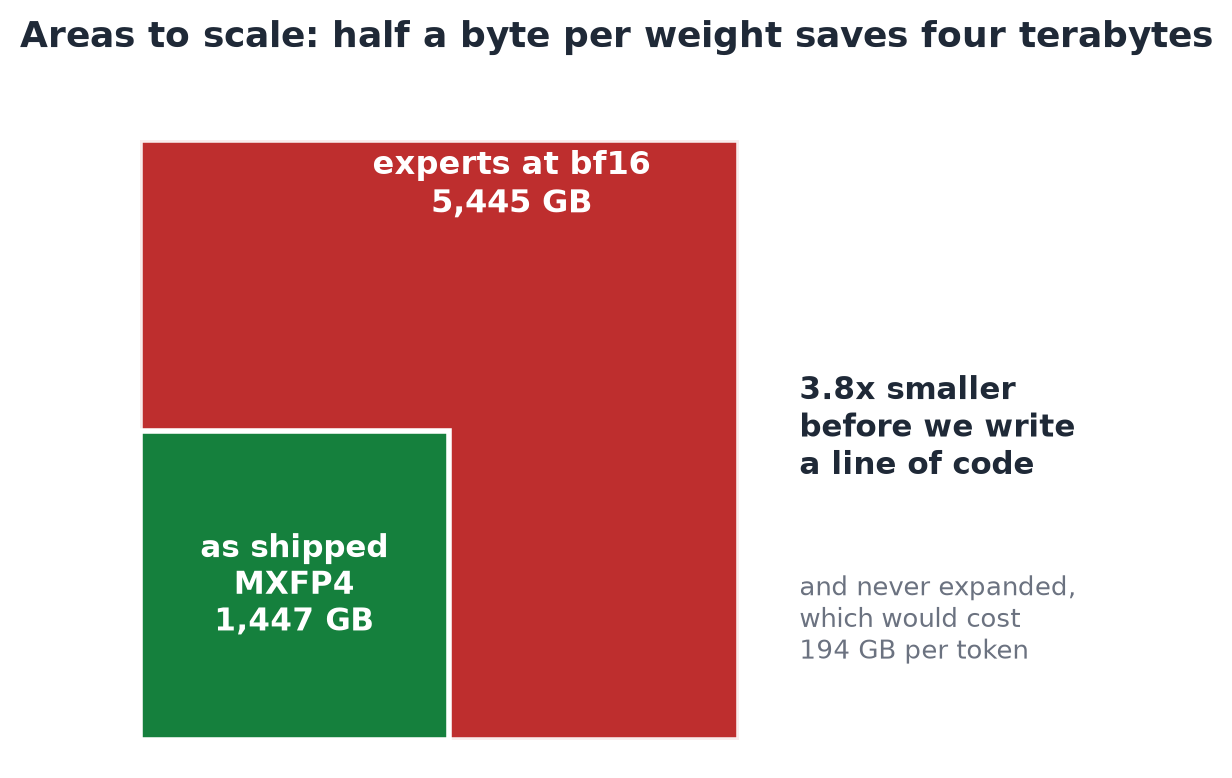
So 5.56 terabytes is the number to beat.
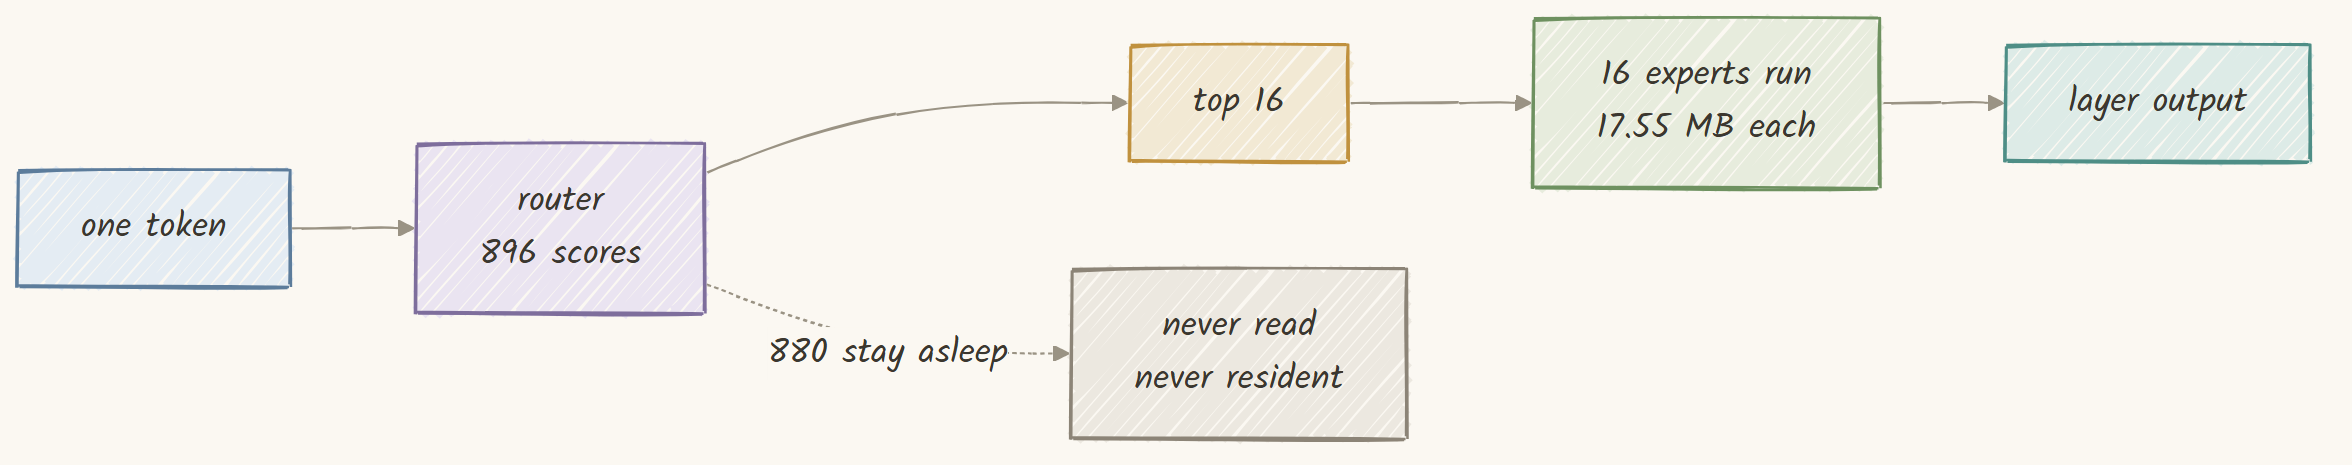
Kimi K3 has 93 layers. Layer 0 is a plain dense feed-forward layer, so the other 92
layers route, and each of those picks the top 16 experts out of 896.
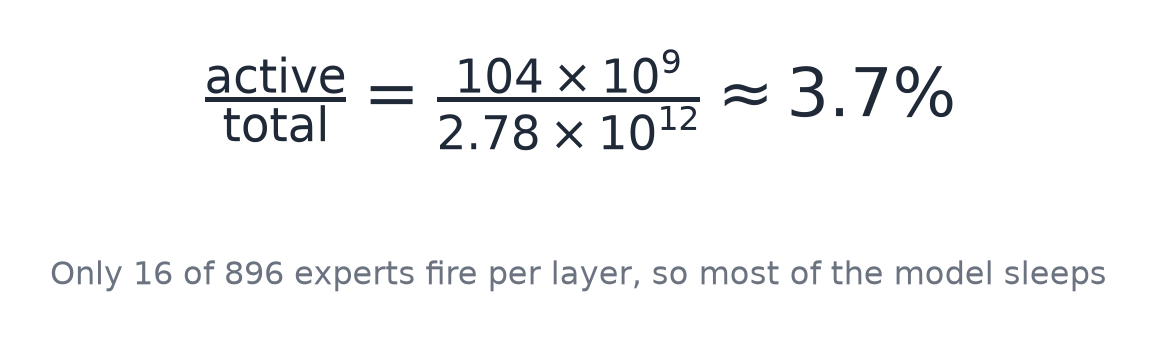
About 104 billion parameters are active for any given token, out of 2.78 trillion, which is 3.7
percent. The other 96.3 percent still has to exist somewhere reachable, but it does not
have to be in RAM.
Counting the actual bytes on disk rather than guessing:
=== shard census: what the 1.56 TB actually is ===
shards            : 96
total bytes       : 1560936091448  (1.56 TB)

--- routed experts (the part that is streamed, never resident) ---
  experts total     : 82,432   (896 routed x 92 MoE layers)
  bytes per expert  : 17,547,264  exactly
                      = 33,030,144 params x 0.53125 bytes
                      = 0.5 bytes/nibble + 1/32 byte for the shared E8M0 scale
  routed expert set : 82,432 x 17,547,264 = 1.447 TB
There are 82,432 routed experts, each occupying exactly 17,547,264 bytes. Together
they are 1.447 terabytes, which is 93 percent of the entire checkpoint. Everything
else (attention projections, routers, norms, embeddings) is the remaining 7 percent.
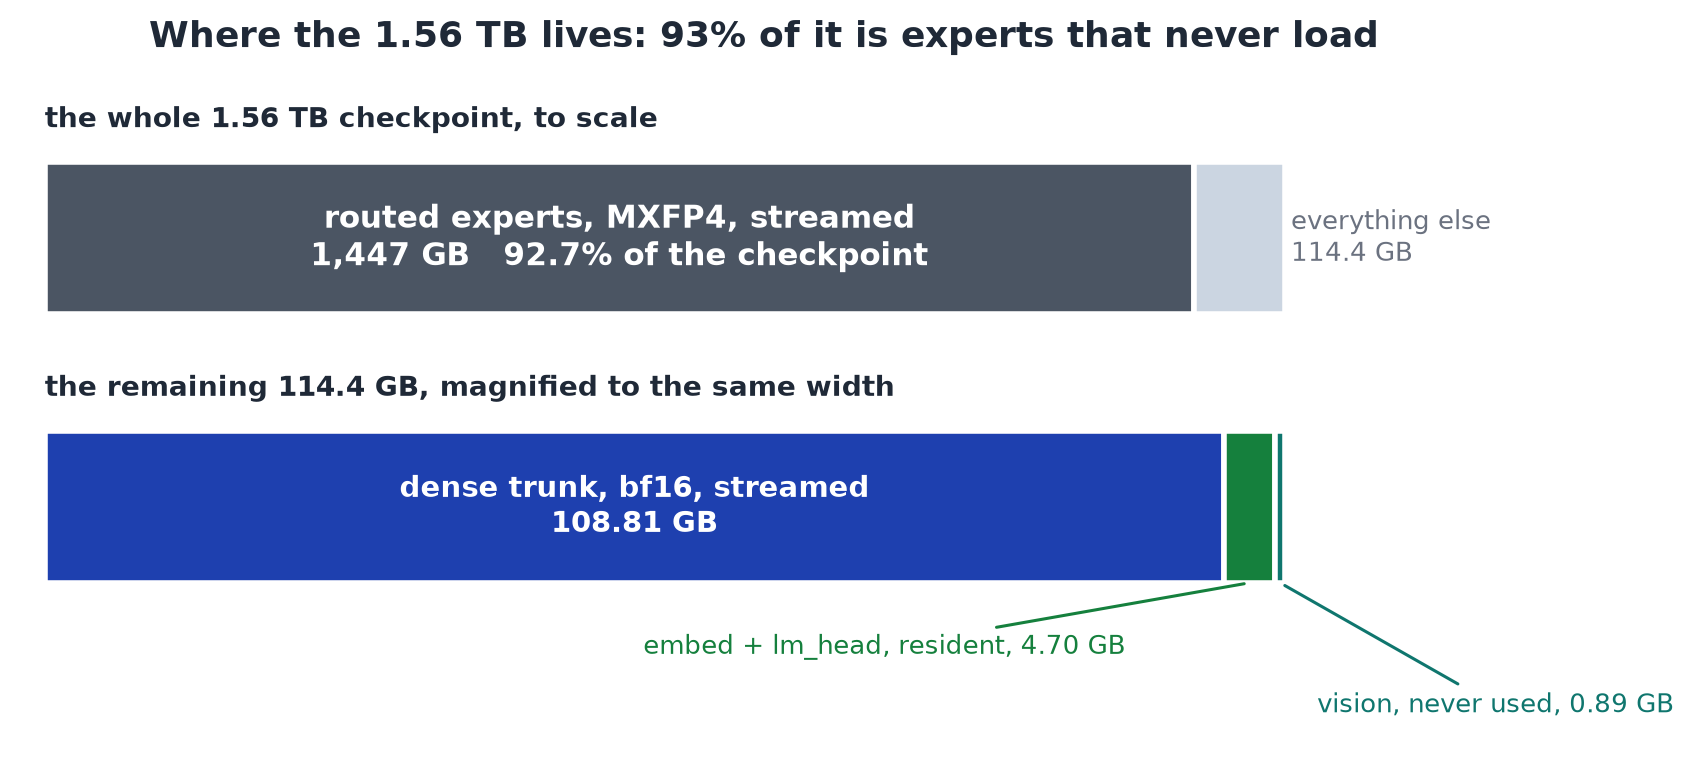
That census is the whole strategy in one picture. If those 1.447 terabytes can be
reachable but never resident, the memory problem shrinks by more than an order of
magnitude before a single kernel is written.
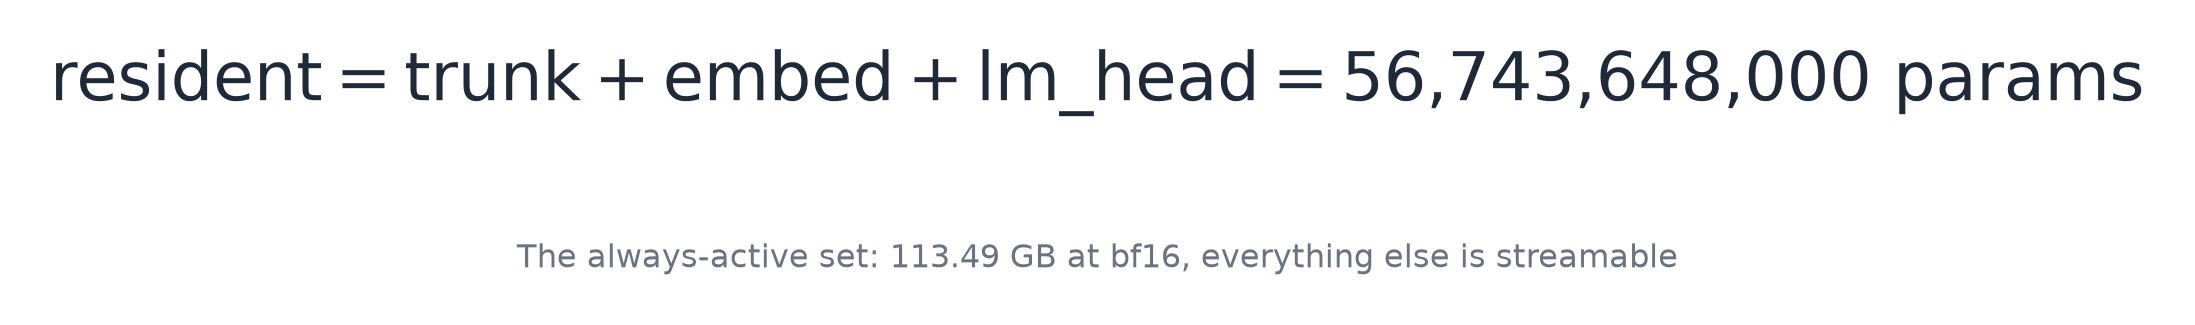
What is left is 56,743,648,000 parameters, or 113.49 gigabytes at bfloat16. Of that,
108.81 GB is the per-layer dense trunk and 4.70 GB is the embedding table plus the output
head.
The four reductions
- 5,560 GB: every parameter at bfloat16, where we start.
- 1,560 GB: the checkpoint as shipped, because the experts already arrive at half a
byte per weight. - 113.49 GB: what has to be resident once routing means the experts never load.
- 8.24 GB: what is measured, once the trunk is streamed instead of held.
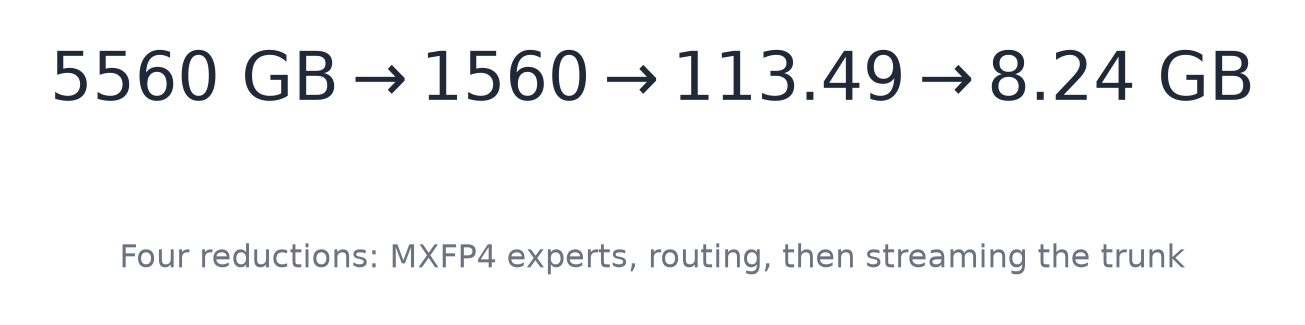
End to end that is a 675× reduction from the bfloat16 model and 189× from the
shipped checkpoint. Nothing is approximated and no weight is dropped: the output at the
bottom of that ladder is byte for byte the output at the top. The chart at the top of
this document is that ledger drawn to scale.
The machine, and what it assumes
Every measurement here comes from one workstation: a two-socket AMD EPYC 7763 with 124
cores and no SMT, 228 GB of RAM, and 3.2 TB of NVMe. It also has four NVIDIA L40 GPUs,
which sat completely idle for the entire campaign, because this engine has no GPU path.
--- ISA (note: AVX2 present, AVX-512 ABSENT) ---
avx avx2 fma sse4_2

--- memory ---
Mem:           228Gi       5.1Gi       207Gi       3.1Mi        18Gi       223Gi
MemTotal:       239308464 kB
MemAvailable:   233961008 kB
Hugepagesize:       2048 kB
There is no AVX-512. The engine needs AVX2 and FMA and nothing more, the instruction
set on any desktop CPU from the last decade.
The storage numbers matter more than the CPU numbers, and one runs against expectation.
--- storage bandwidth, measured ---
O_DIRECT cold : 3.2 GB/s     (dd bs=4M iflag=direct after drop_caches)
buffered warm : 2.3 GB/s
engine, trunk : 5373-6064 MB/s sustained during runs
NOTE O_DIRECT is FASTER than buffered here. That is the opposite of the usual
expectation, and it is why the engine opens the trunk O_DIRECT.
Reading with O_DIRECT, bypassing the page cache entirely, is faster here than
reading through it. That single measurement decided the whole I/O design.
One piece of hygiene, because a loaded machine is easy to measure badly:
--- measurement hygiene ---
unattended-upgrades: STOPPED and DISABLED before measurement (was using ~63% of a
  core during the smoke run).
apt-daily.timer and apt-daily-upgrade.timer: DISABLED
A background package updater eating most of a core moves a timing by more than most
optimisations do, so it goes off before anything is measured.
How much memory does the engine actually need? Multiplying config values by hand gives the
wrong answer in an instructive way, which is why tools/budget.py exists:
# Streamable only if ROUTED. The 2 SHARED experts sit in the same namespace and
# are NOT streamable, which is where hand arithmetic goes wrong.
def classify(name: str) -> str:
    if ".block_sparse_moe.experts." in name:
        return "routed_expert"          # streamable: only 16 of 896 per token
    if ".block_sparse_moe.shared_expert" in name:
        return "shared_expert"          # RESIDENT: runs on every token
    if ".self_attn." in name:
        return "attention"              # resident
    if "embed_tokens" in name or "lm_head" in name:
        return "embedding"              # resident
    return "other"                      # norms, router gates, biases: resident
The two shared experts run on every token, so they belong in the resident set even though
their tensor names sit next to the routed experts. Getting that wrong makes the floor look
smaller than it is, which is the worst direction to be wrong in.
The codebase
Six C files compiled into one binary. No BLAS, no PyTorch, no ONNX runtime, no GPU
library. The only dependencies are libm and OpenMP.
include/k3/
  k3.h              # the public header: config, weights, every kernel prototype
  k3_cfg.h          # config reader, header-only, refuses to substitute defaults
src/
  core/k3_ops.c     # every numeric kernel: RMSNorm, KDA, MLA, MoE, MXFP4 matmul
  io/k3_st.c        # safetensors reader, hand-written JSON scan, O_DIRECT reads
  io/k3_load.c      # locating one expert's bytes inside a shard
  io/k3_trunk.c     # streaming the dense trunk, pinned prefix plus a ring slot
  cache/k3_cache.c  # the routed-expert LRU cache and its batch prefetch
  model/k3_bind.c   # binding checkpoint tensor names to kernel arguments
  tokenizer/k3_tok.h# byte-level BPE loaded from tiktoken.model
  cli/k3_run.c      # the k3 binary: memory plan, decode loop, reporting
tools/              # python: pack the trunk, replay the cache, verify against torch
benchmarks/         # the cgroup memory ladder and the split sweep
tests/              # fixtures, the tiny oracle, the 93-layer conformance run
CFLAGS = -O3 -std=gnu99 -Wall -Wextra -Wpointer-arith -Wshadow -Wvla \
-march=native -fopenmp -ffp-contract=off
LDFLAGS = -lm -fopenmpThe flag that looks unusual is -ffp-contract=off. By default a compiler may fuse a
multiply and an add into a single FMA, which changes the rounding. That is normally good.
Here it is a problem, because the scalar path, the OpenMP path and the AVX2 path must
produce bit-identical results, so that a performance change can never quietly become
an accuracy change.
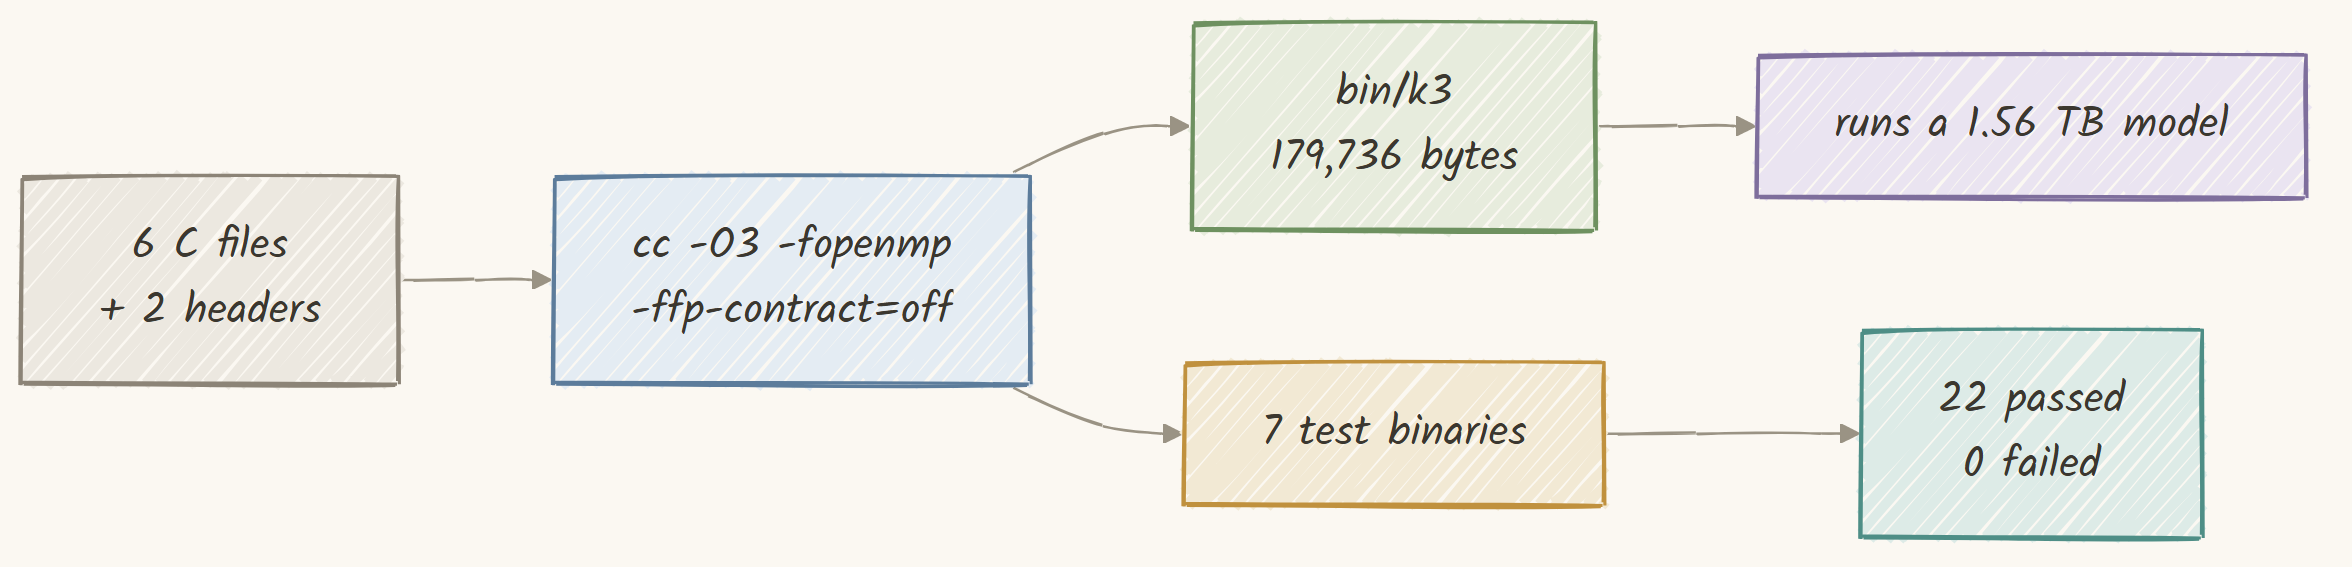
1. build, warnings are failures
  -> clean build, no diagnostics
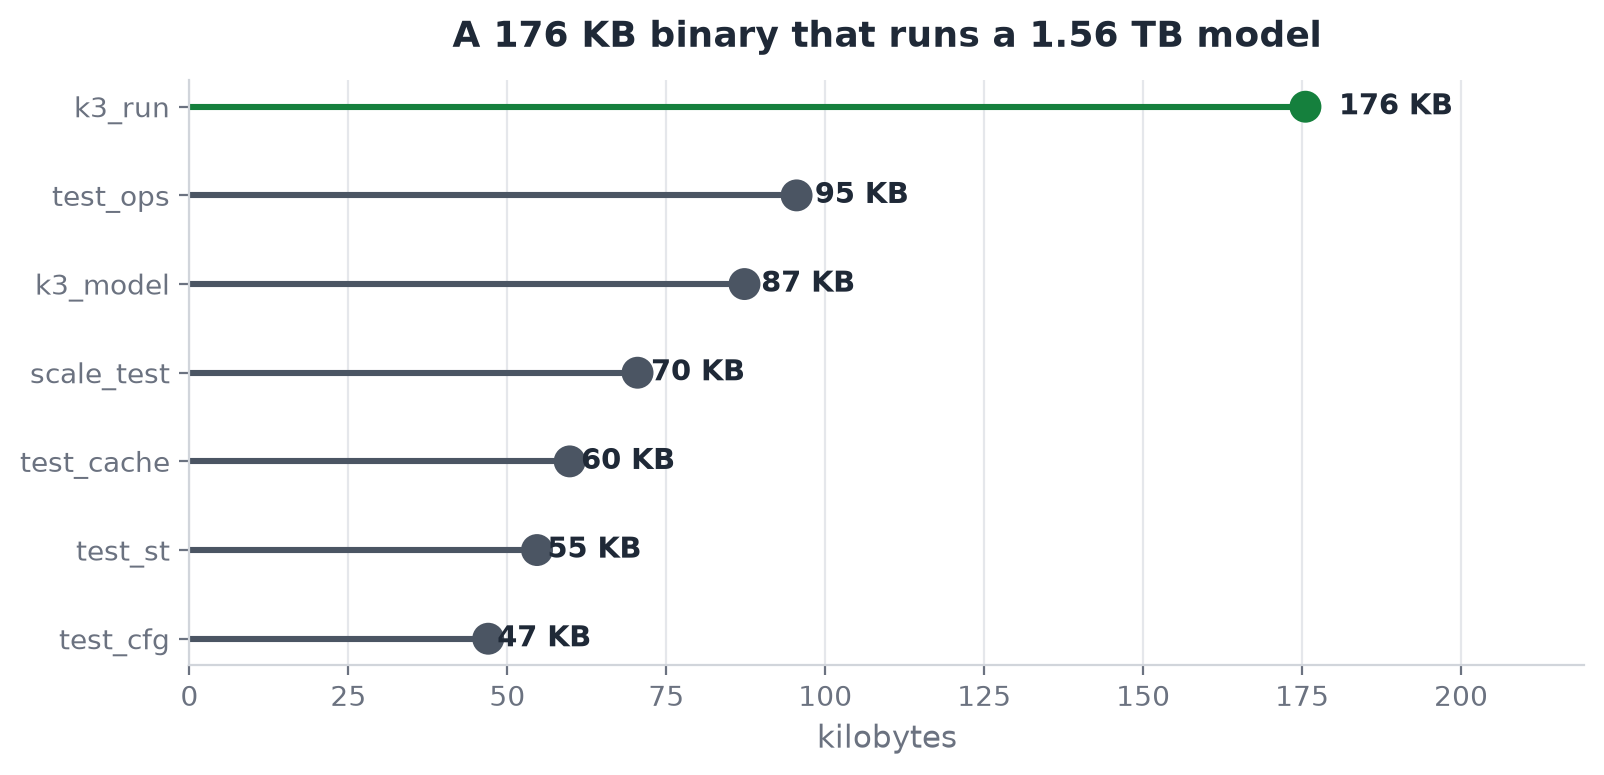
  test_ops          97784 bytes
  k3_model          89392 bytes
  k3_run           179736 bytes
The whole inference engine is 179,736 bytes, a 176 kilobyte binary whose job is to
run a 1.56 terabyte model.
One check crosses machines. The tokenizer was run on the same input file under Windows and
under Linux:
=== cross-platform tokenizer determinism ===
  Linux   gcc 13.3.0  x86_64
  Windows gcc 16.1.0  x86_64
  input   src/k3.h (24,499 bytes) -> 6,862 ids
  result  IDENTICAL id streams

  (a naive md5 of stdout DIFFERS by one byte: Windows text-mode stdout writes the
   trailing newline as CRLF. That is the pipe, not the tokenizer.)
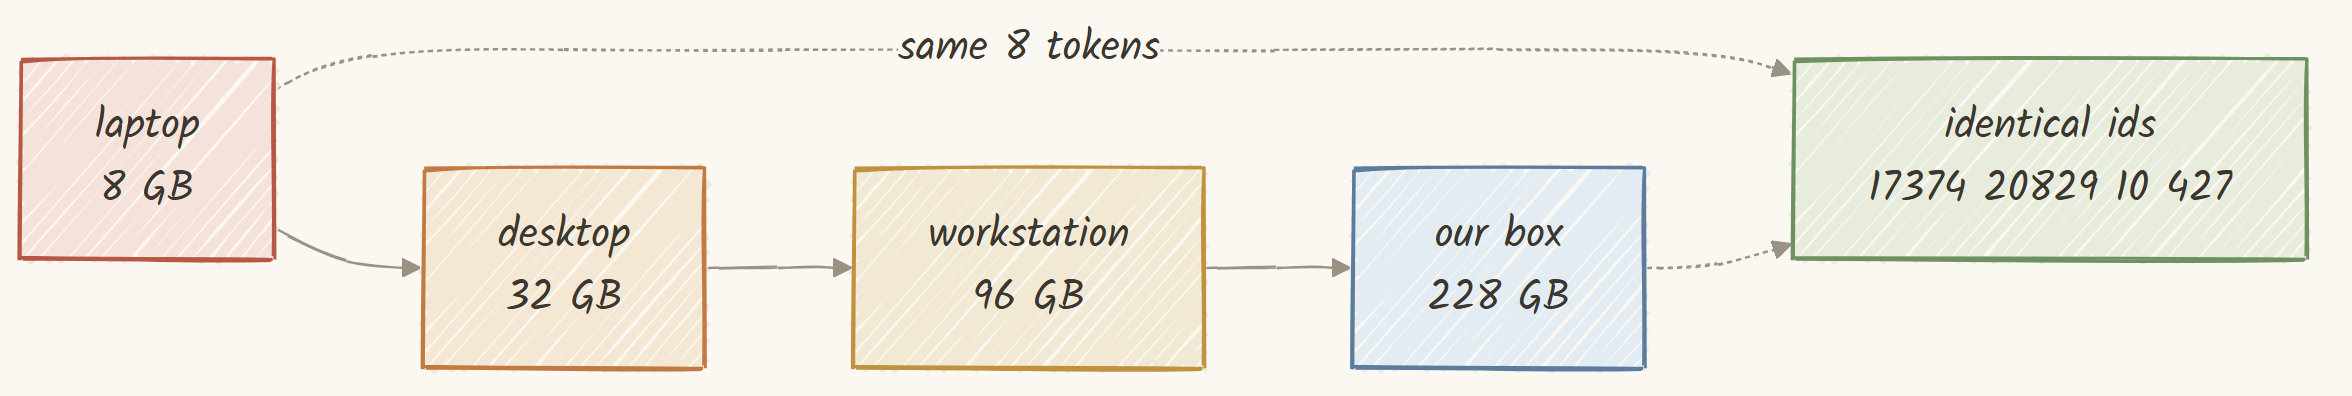
Two compilers on two operating systems produce the same 6,862 token ids from the same
24,499 bytes. The md5 sums differ by exactly one byte, and the reason is the line ending
the shell added, not anything the tokenizer did.
Five invariants
The public header opens with five invariants that must hold. Each one is a place where a
plausible-looking implementation produces a model that runs, emits fluent text, and is
wrong, with no crash and no NaN to warn you.
A_logis indexed per head, not per channel. The checkpoint shipshead_dim
floats but only the firstnum_headsare meaningful; the rest are padding.- The UT-transform inverse is
(I + Akk)^-1. The sign is not a convention. Aqkretains its diagonal andAkkdoes not.- MLA uses NoPE, yet the 64 rope dimensions still exist and are still cached. Only
the rotation is absent; dropping the slots changes the head width. - The MoE routing bias steers selection only. The combining weights come from the
unbiased sigmoid scores.
Each is ticked off below as its component arrives.
1. Reading a 1.56 TB checkpoint from its headers
The checkpoint is 96 safetensors files. The format is deliberately simple, which is what
makes it possible to treat 1.56 terabytes as an index rather than as data.
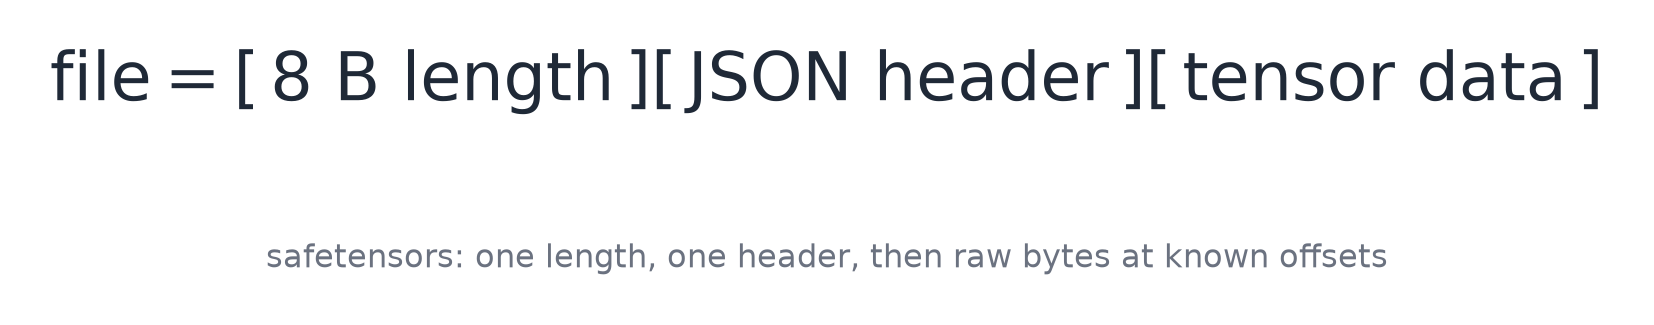
Every file starts with an 8-byte little-endian length, then that many bytes of JSON
describing every tensor, then the raw tensor bytes back to back. Nothing is compressed and
nothing is interleaved.
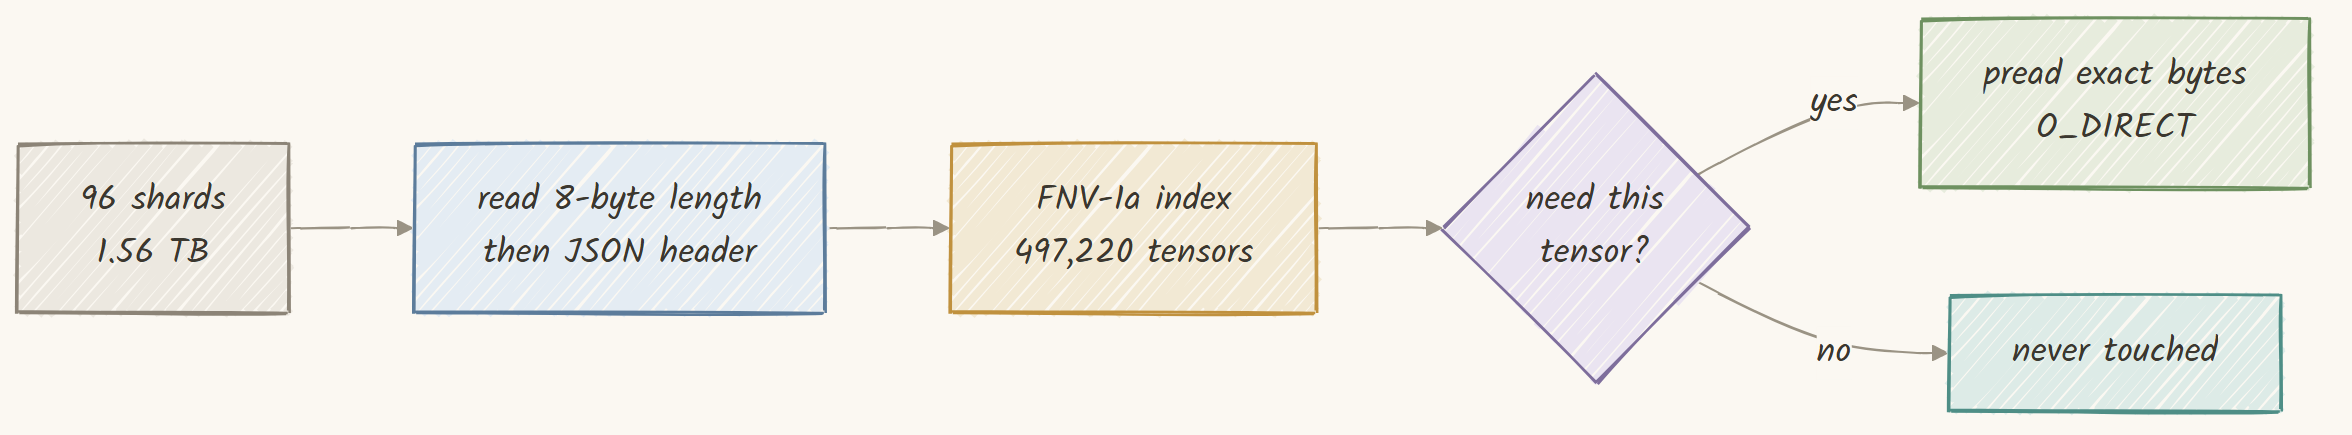
No JSON library is used. The header can be tens of megabytes and only four fields per
tensor are wanted, so the reader scans it directly.
/* Walk the header once, copy nothing we do not need. `p` sits just past the
 * opening quote of the tensor name. */
static const char *st_scan_entry(const char *p, const char *end, K3Tensor *t)
{
    const char *q = memchr(p, '"', (size_t)(end - p));
    if (!q || (size_t)(q - p) >= sizeof t->name) return NULL;
    memcpy(t->name, p, (size_t)(q - p));
    t->name[q - p] = '\0';

    const char *d = st_find_key(q, end, "dtype");
    if (!d) return NULL;
    t->dtype = st_dtype_code(d);

    const char *s = st_find_key(q, end, "shape");
    if (!s) return NULL;
    t->rank = 0;
    t->nelem = 1;
    for (const char *c = s; c < end && *c != ']'; c++) {
        if (*c >= '0' && *c <= '9') {
            long v = strtol(c, (char **)&c, 10);
            if (t->rank >= K3_ST_MAXRANK) return NULL;
            t->shape[t->rank++] = v;
            t->nelem *= (size_t)v;
        }
    }

    /* offsets are RELATIVE to the start of the data section */
    const char *o = st_find_key(q, end, "data_offsets");
    if (!o) return NULL;
    t->off  = (size_t)strtoull(o, (char **)&o, 10);
    while (o < end && (*o < '0' || *o > '9')) o++;
    t->nbytes = (size_t)strtoull(o, (char **)&o, 10) - t->off;
    return o;
}
Every tensor goes into a hash table keyed by a hash of its name. The choice of hash is not
arbitrary.
/* Names are long and share deep prefixes
 * ("language_model.model.layers.N.block_sparse_moe.experts.M...."), so the hash must
 * mix every byte; a prefix-only or length-only hash would pile every expert of a
 * layer into one bucket. */
static uint64_t fnv1a(const char *s)
{
    uint64_t h = 1469598103934665603ull;
    while (*s) { h ^= (unsigned char)*s++; h *= 1099511628211ull; }
    return h;
}
Half a million tensor names that all begin with the same forty characters is a genuinely
hostile input for a hash function. FNV-1a mixes on every byte, so the expert index at the
end of the name still moves the result.
Reading a tensor afterwards has one wrinkle: O_DIRECT requires the offset and the length
to be multiples of the block size, and a tensor starts wherever the previous one ended.
int64_t k3_st_read_aligned(const K3St *s, int shard, int64_t off, int64_t nbytes,
                           void *buf, int64_t bufcap, int64_t *payload_off)
{
    /* widen outward to the enclosing aligned window */
    const int64_t lo  = off & ~(int64_t)(K3_ST_ALIGN - 1);
    const int64_t hi  = (off + nbytes + K3_ST_ALIGN - 1) & ~(int64_t)(K3_ST_ALIGN - 1);
    const int64_t len = hi - lo;
    const int64_t pad = off - lo;
    if (len > bufcap) return 0;
    if (payload_off) *payload_off = pad;

    int64_t got = 0;
    while (got < len) {
        ssize_t r = pread(dfd, (char *)buf + got, (size_t)(len - got), (off_t)(lo + got));
        if (r <= 0) break;      /* the last window may run past EOF */
        got += r;
    }
    return got >= pad + nbytes ? nbytes : (got > pad ? got - pad : 0);
}
Note the break rather than a failure on a short read: the final aligned window of a shard
extends past the end of the file, which is expected, so the return value checks that the
payload was covered rather than that the whole window was.
indexed 497220 tensors from 96 shards in 0.27 sHalf a million tensors indexed in about a quarter of a second. This is what makes
everything afterwards possible: the engine never reads a shard it does not need, so the
1.56 terabytes on disk is a catalogue, not a working set.
A parser that agrees with itself proves nothing, so the index is dumped and re-parsed
independently in Python, comparing dtype, shape, offsets, and the widened float bit
patterns.
# Bit patterns, not tolerances: widening bf16 to f32 is lossless.
c_bits = np.asarray(c_values[name], dtype=np.float32).view(np.uint32)
p_bits = ref.astype(np.float32).view(np.uint32)
if not np.array_equal(c_bits, p_bits):
    bad = int(np.count_nonzero(c_bits != p_bits))
    fail(f"{name}: {bad} of {c_bits.size} float32 bit patterns differ")
=== shard verification ===
shards: 96
bytes: 1560936091448
expected: 1560936091448
RESULT: EXACT MATCH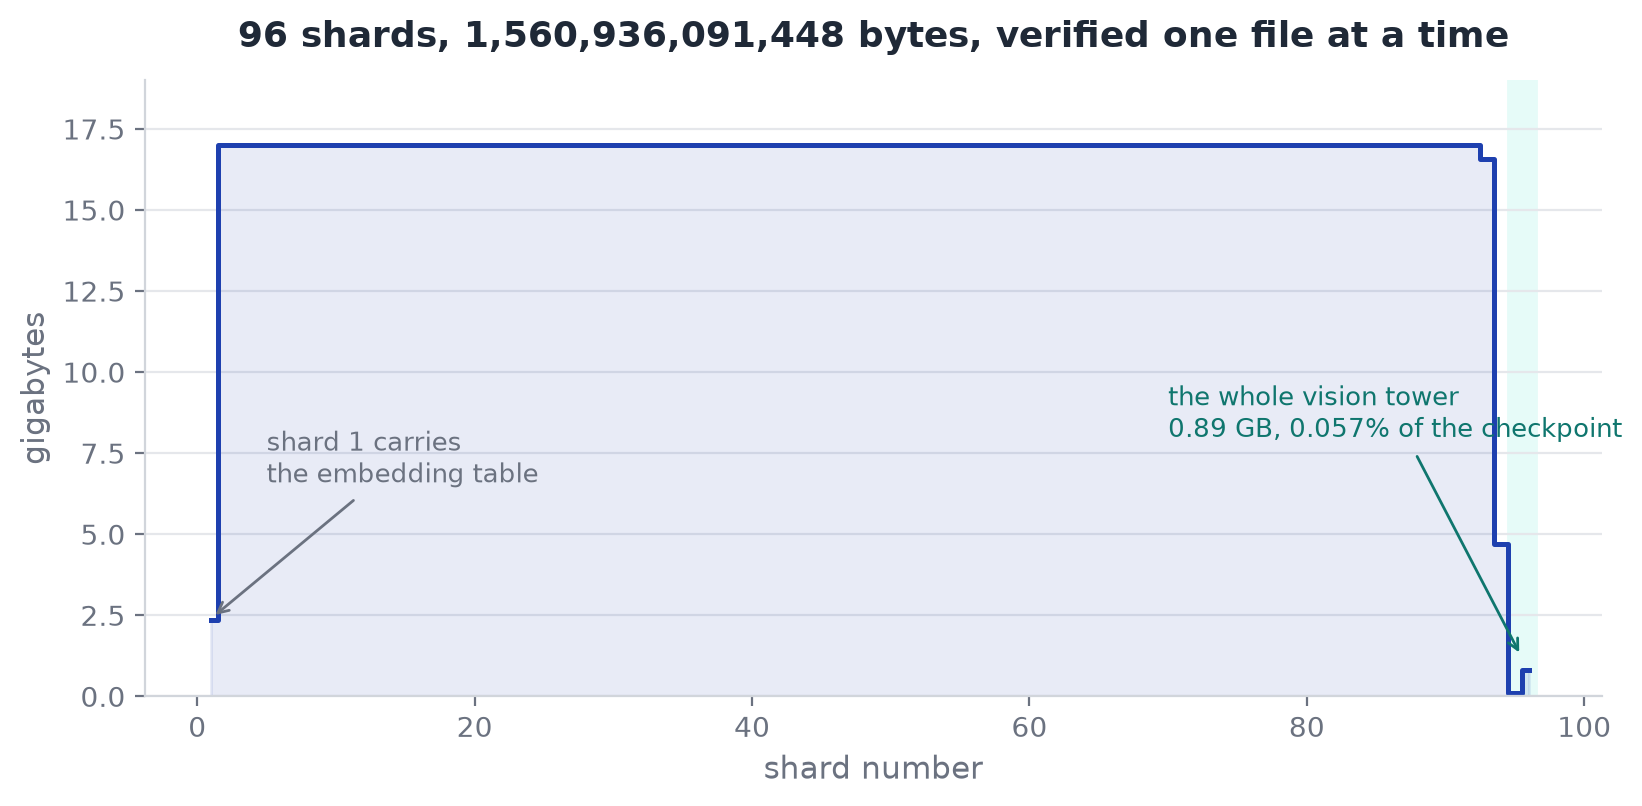
2. The config reader that refuses to guess
The model's dimensions come from the checkpoint's own config.json, and this is the first
place invariant four can silently bite.
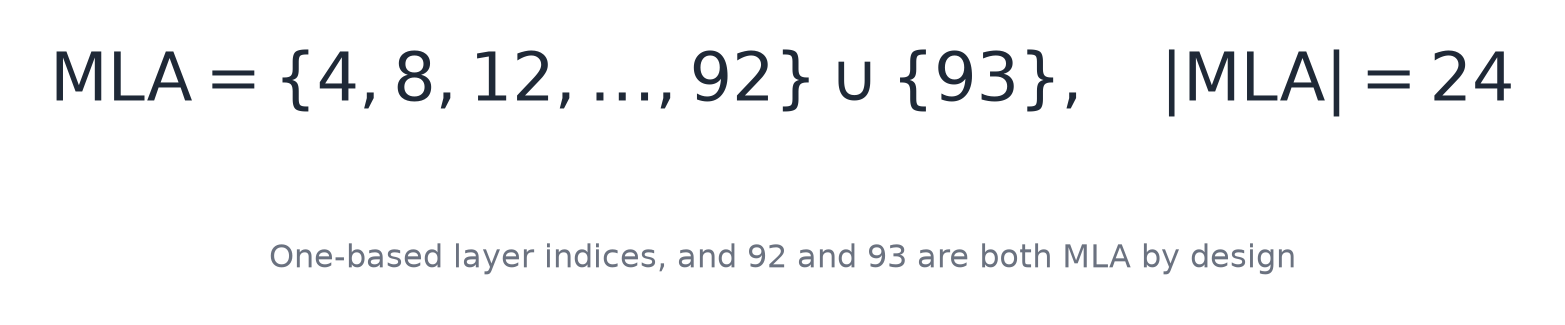
Kimi K3 alternates two attention mechanisms. Most layers use one, every fourth uses the
other, and the last two are both the second kind so the final layer always does global
attention. The config lists those layers explicitly, and the list is one-based.
--- every value below is READ from the checkpoint, not assumed ---
config: config.json (nested shape) | hidden=7168 layers=93 vocab=163840
        | 24 MLA + 69 KDA | experts 896 top16 shared2 | latent=3584

--- KDA/MLA layer map (ONE-based, from full_attn_layers) ---
full_attn_layers (24, all MLA): 4,8,12,16,20,24,28,32,36,40,44,48,52,56,60,64,68,72,76,80,84,88,92,93
  note 92 AND 93 are both MLA - the report (2.1) places an extra Gated MLA layer
  at the end of the backbone so the final layer always does global attention.
kda_layers (69): every other layer.
Every one of those numbers is read from the file; none is compiled in. They land in one
struct, which is the entire model on one screen:
typedef struct {
    int hidden;            /* 7168  */
    int n_layers;          /* 93    */
    int vocab;             /* 163840 */
    float rms_eps;         /* 1e-5  */

    /* Kimi Delta Attention. 69 of the 93 layers. */
    int kda_heads;         /* 96    */
    int kda_head_dim;      /* 128, and d_k == d_v */
    int conv_k;            /* 4, depthwise, causal, SiLU fused */
    float gate_lb;         /* -5.0, the decay lower bound */

    /* Gated MLA. 24 of the 93 layers. */
    int n_heads;           /* 96    */
    int q_lora;            /* 1536  */
    int kv_lora;           /* 512   */
    int qk_nope;           /* 128   */
    int qk_rope;           /* 64, PRESENT BUT NEVER ROTATED */
    int v_head;            /* 128   */
    int mla_out_gate;      /* 1     */

    /* Stable LatentMoE. 92 of the 93 layers. */
    int n_experts;         /* 896   */
    int topk;              /* 16    */
    int n_shared;          /* 2, full width, added UNWEIGHTED */
    int latent;            /* 3584, the routed-expert width */
    int moe_inter;         /* 3072  */
    float routed_scale;    /* 1.0   */
    int moe_renorm;        /* 1     */
    int latent_norm;       /* 1, RMSNorm on the AGGREGATE, not per expert */

    /* the single dense layer, layer 0 */
    int first_dense;       /* 1     */
    int dense_inter;       /* 33792 */

    int attn_res_block;    /* 12. Boundaries fire when layer_idx % this == 0. */
    float situ_b1;         /* 4.0   */
    float situ_b2;         /* 25.0  */

    int  n_full_attn;      /* 24 */
    int *full_attn;        /* ONE-BASED layer indices */
} K3Cfg;
That struct is the contract between the checkpoint and every kernel. If it is right, the
model is Kimi K3. If any field is wrong, the model is something else that still speaks
English.
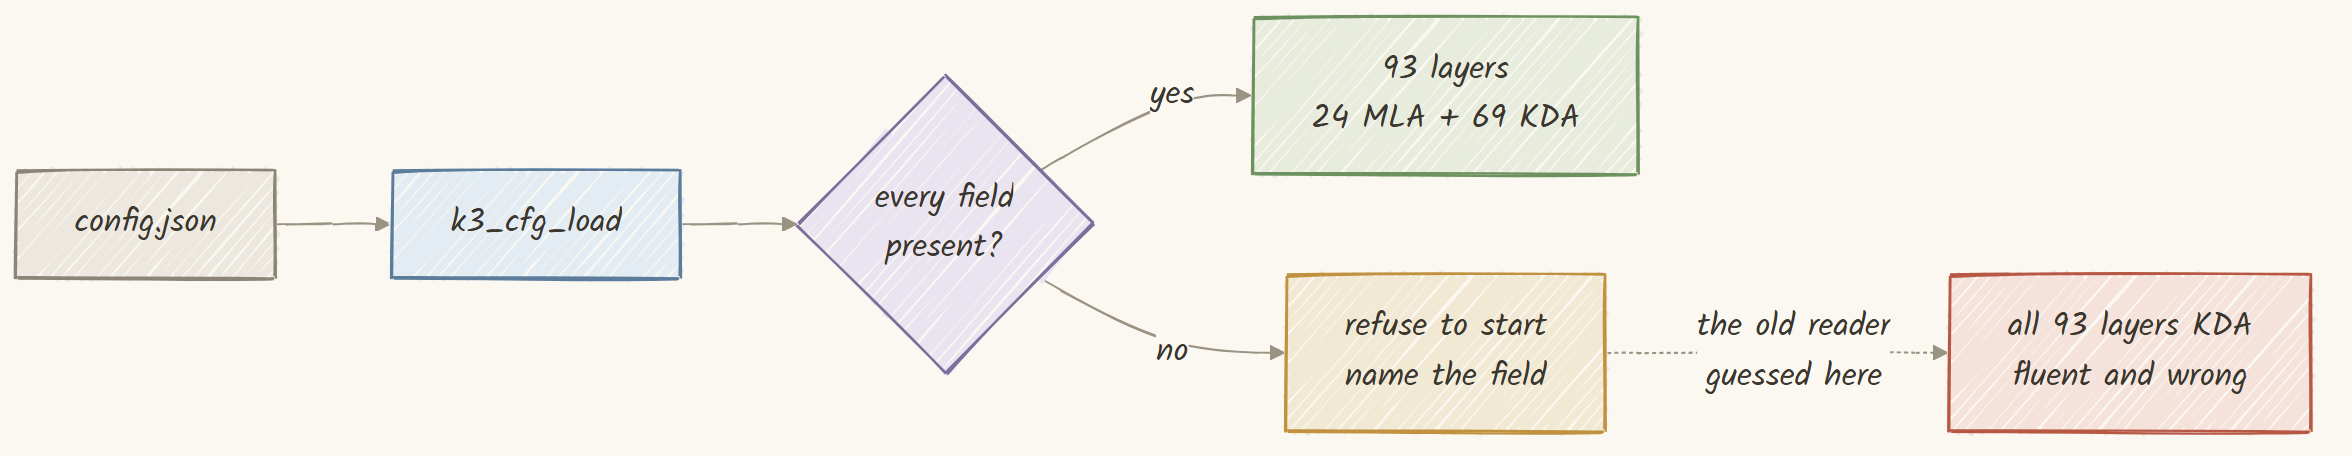
Consider what a permissive reader would do. The released config nests its fields one level
deeper than a fixture does, so a reader that only knows the flat shape finds nothing it
recognises. If it then fills in defaults, two things happen: the SiTU betas get 4.0 and
25.0, which are the correct values, so nothing looks wrong, and full_attn_layers
comes back empty, so all 93 layers run as KDA and the 24 global-attention layers vanish.
The model loads, streams, decodes, and produces grammatical English from an architecture
that is not Kimi K3.
/* An absent field is an ERROR, never a default. Missing names are accumulated so
 * the message lists all of them at once. */
static int cfg_req_int(jval root, const char *key, int *out,
                       const char **missing, int *nmissing)
{
    jval v = json_get(root, key);
    if (v.type != JSON_NUM) {                 /* absent OR the wrong type */
        if (*nmissing < K3_CFG_MAXMISS) missing[(*nmissing)++] = key;
        return 0;
    }
    *out = (int)v.num;
    return 1;
}
[no_layermap]
k3_cfg: no_layermap.json is missing 1 required field(s):
full_attn_layers
refusing to substitute defaults: a config this reader cannot
fully understand would silently produce a DIFFERENT model.
ok correctly rejected no_layermap.json
[bad_layer_index]
k3_cfg: bad_layer_index.json full_attn_layers[2] = 999 is outside 1..93
(the list is ONE-based)
ok correctly rejected bad_layer_index.jsonA config reader is about a hundred and fifty lines of the most boring code in the project,
and it is one of exactly two places that can hand you a different model without telling
you.
3. The tokenizer, byte for byte
The other one is the tokenizer. Kimi K3 uses a byte-level BPE with 163,584 ranks plus 256
special tokens, shipped as a tiktoken.model file.
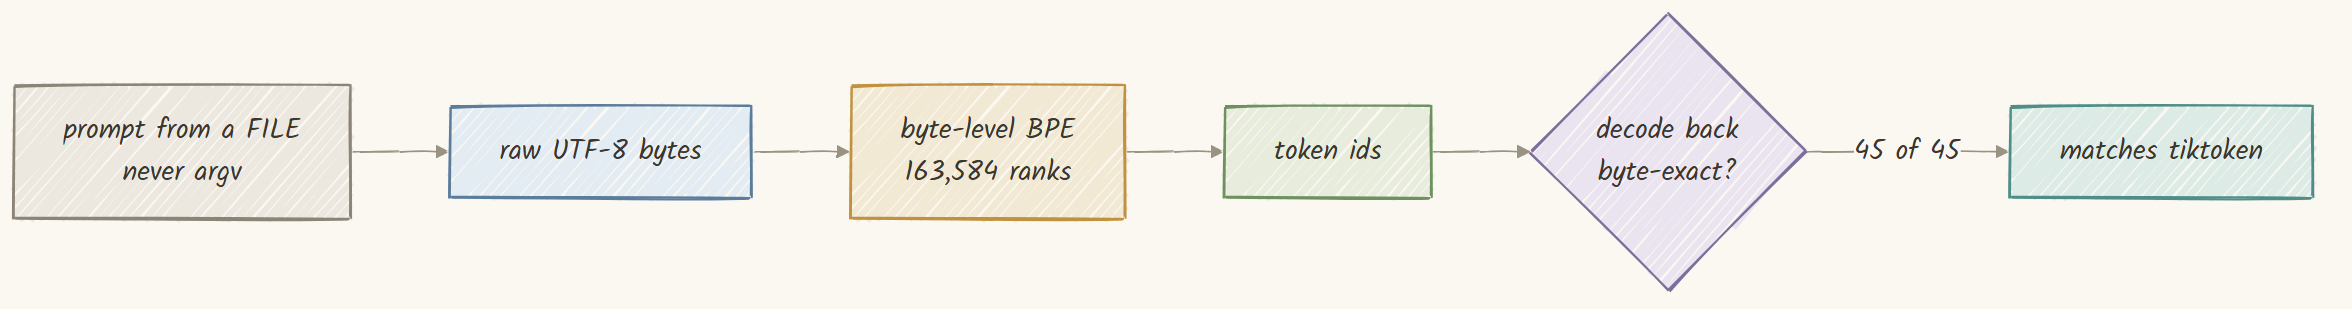
The loader reads that file straight into the vendored BPE structures. It rests on three
assumptions, each of which produces a tokenizer working perfectly on ASCII and diverging
on everything else:
- The merge keys are bytes, not code points. A key that happens to decode as valid
UTF-8 must still be treated as its raw bytes. - Ranks come from the file. They are not derived from frequency at load time.
- The added-token block is appended after the ranks, so an added token's id is 163,584
plus its index, not its position in a merged table.
The test compares the C tokenizer against the Python tiktoken library case by case,
through files rather than command-line arguments:
oracle   : tiktoken 0.13.0
method   : token-for-token comparison; every case passed through a FILE, never argv
           (argv is re-encoded to the active code page on Windows and would compare
            different bytes on every non-ASCII case)

  PASS  han only                 2 ids
  PASS  japanese                 6 ids
  PASS  korean                   5 ids
  PASS  cyrillic                 4 ids
  PASS  arabic                   7 ids
  PASS  emoji zwj                5 ids
  PASS  code python             11 ids
  PASS  json                    19 ids

tokenizer parity: 45/45 cases match
Then whole files are pushed through and decoded back:
roundtrip: 48353 bytes -> 14797 ids -> 48353 bytes : PASS   <- k3_ops.c
roundtrip: 24499 bytes -> 6862 ids -> 24499 bytes : PASS   <- k3.h
roundtrip: 201775 bytes -> 52671 ids -> 201775 bytes : PASS   <- REPORT.md
roundtrip: 53444 bytes -> 12145 ids -> 53444 bytes : PASS   <- modeling_kimi_k3.py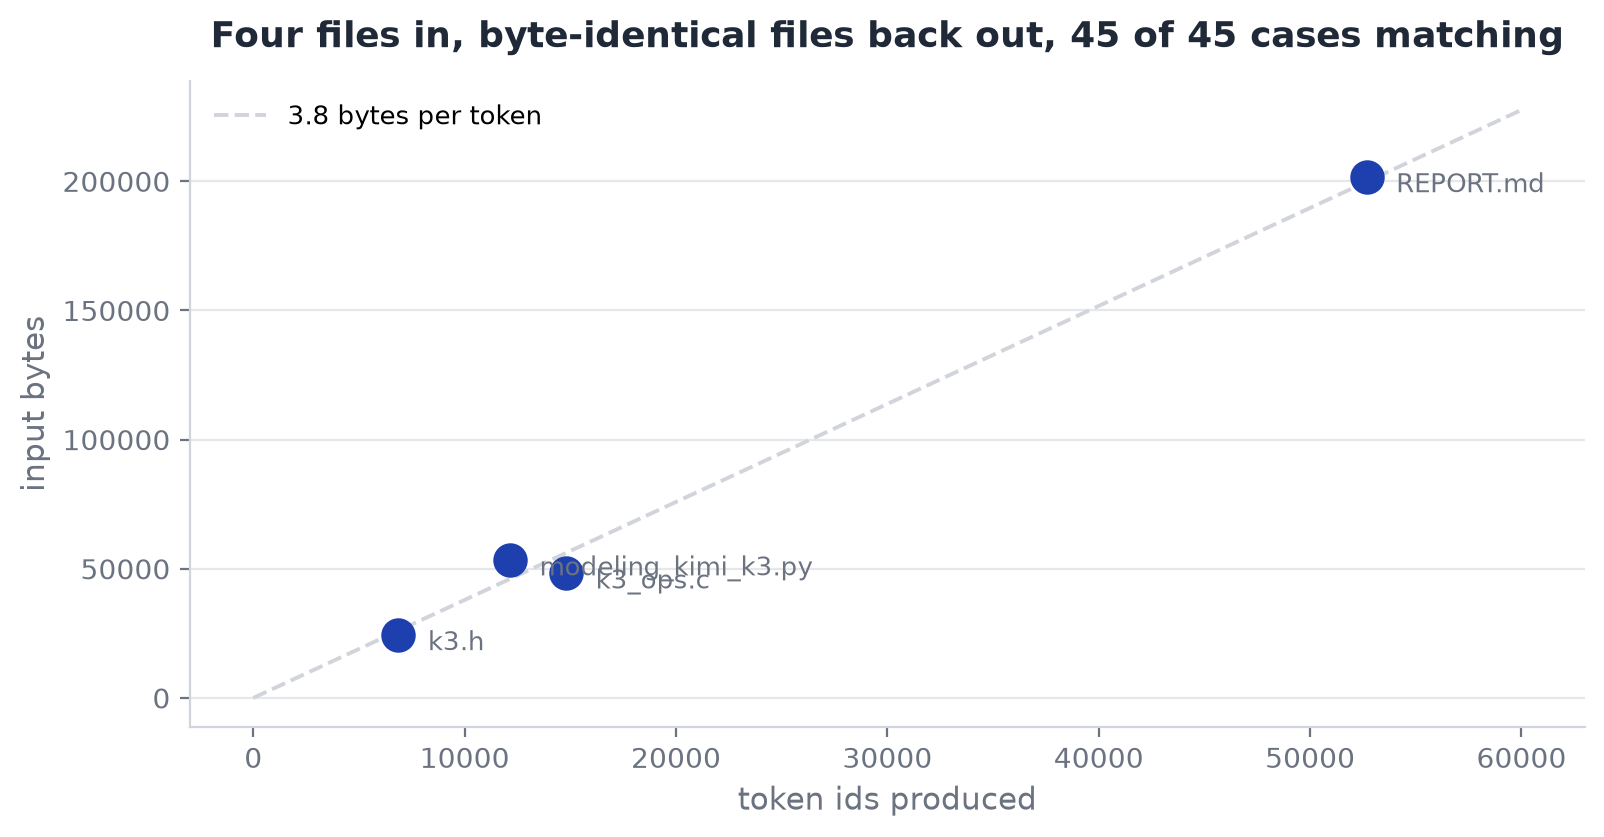
Two hundred kilobytes of markdown becomes 52,671 token ids and comes back as exactly the
same two hundred kilobytes. Every later claim about identical output rests on the
tokenizer being deterministic.
/* Greedily merge the lowest-rank adjacent pair. Everything here is BYTES. */
static int tok_encode_piece(const Tok *t, const unsigned char *p, int n, int *out)
{
    int parts[K3_TOK_MAXPIECE + 1], np = n + 1;
    for (int i = 0; i <= n; i++) parts[i] = i;          /* byte boundaries */

    for (;;) {
        int best = -1, bestrank = INT_MAX;
        for (int i = 0; i + 2 < np; i++) {
            const int r = tok_rank(t, p + parts[i], parts[i + 2] - parts[i]);
            if (r >= 0 && r < bestrank) { bestrank = r; best = i; }
        }
        if (best < 0) break;                            /* no mergeable pair left */
        memmove(&parts[best + 1], &parts[best + 2],
                (size_t)(np - best - 2) * sizeof(int));
        np--;
    }

    for (int i = 0; i + 1 < np; i++)
        out[i] = tok_rank(t, p + parts[i], parts[i + 1] - parts[i]);
    return np - 1;
}
The loop keeps a list of slice boundaries and repeatedly joins whichever adjacent pair has
the lowest rank, which is what makes the result independent of any tie-breaking order.
4. Reduction one: the experts already ship at half a byte
The first of the four reductions, and the largest single one.
The routed experts do not ship at bfloat16. They ship in MXFP4, a microscaling 4-bit
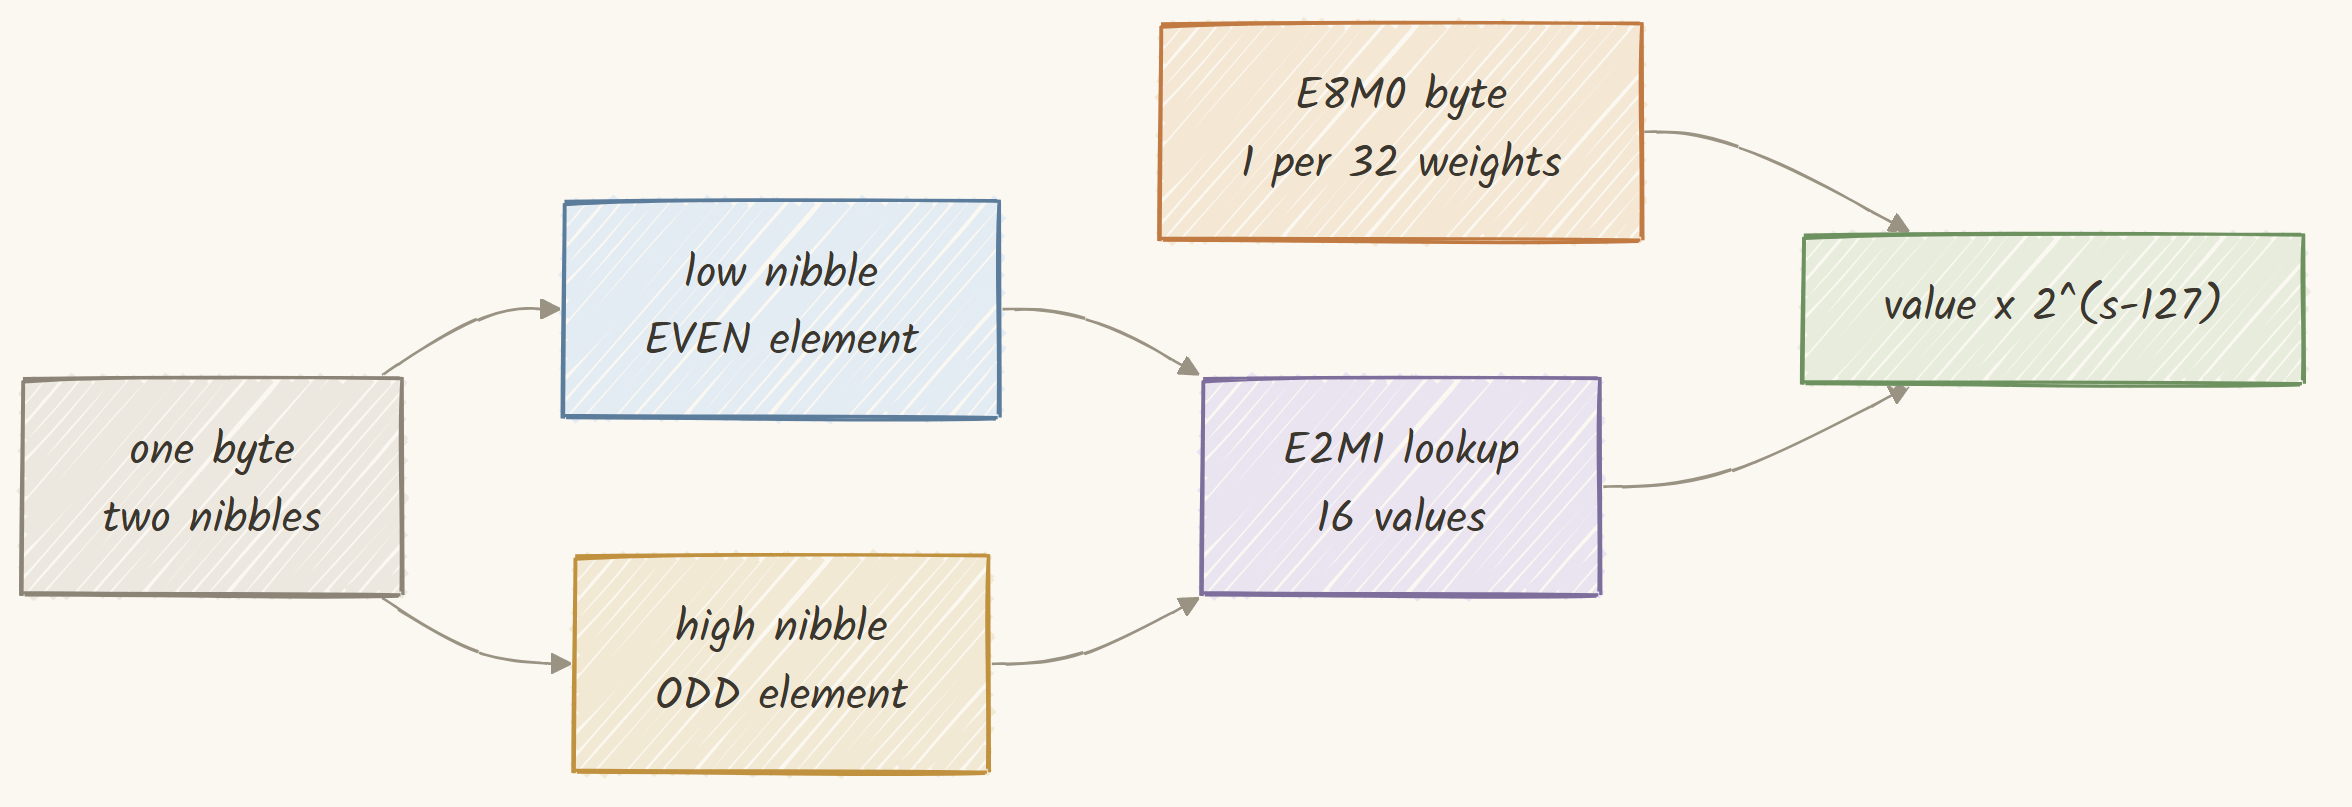
float format. Each weight is a 4-bit nibble indexing a 16-entry table, and every group of
32 consecutive weights shares one 8-bit exponent.
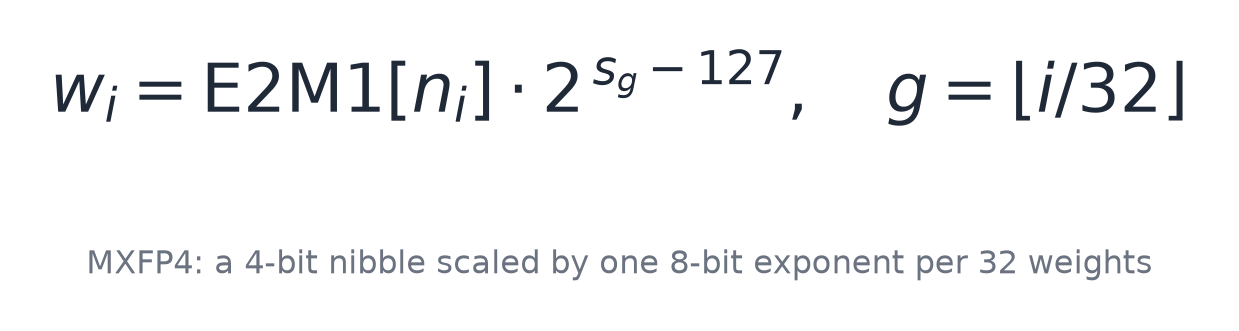
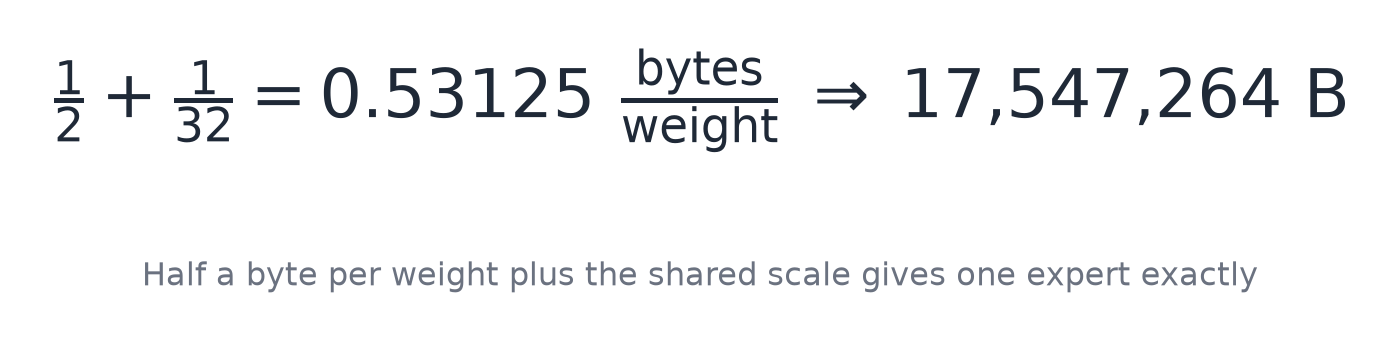
Half a byte plus one thirty-second of a byte is 0.53125 bytes per weight, and one expert
has 33,030,144 parameters, so one expert is exactly 17,547,264 bytes. That matches the
census to the byte.
The format is checked against the released checkpoint rather than against documentation:
{
  "note": "Kimi K3 MXFP4 bytes from the released checkpoint. w = E2M1[nibble] * 2^(scale - 127), one scale per 32 elements.",
  "source": "language_model.model.layers.1.block_sparse_moe.experts.0.w1",
  "rows": 64, "packed_cols": 1792, "scale_cols": 112,
  "logical_width": 3584, "group_size": 32,
  "e2m1_lut": [0.0, 0.5, 1.0, 1.5, 2.0, 3.0, 4.0, 6.0,
              -0.0, -0.5, -1.0, -1.5, -2.0, -3.0, -4.0, -6.0]
}
Both halves of the decode are lookup tables, and building them is the only setup the
format needs.
/* E2M1: sign, two exponent bits, one mantissa bit. Sixteen values in total. */
static const float K3_E2M1[16] = {
    0.0f,  0.5f,  1.0f,  1.5f,  2.0f,  3.0f,  4.0f,  6.0f,
   -0.0f, -0.5f, -1.0f, -1.5f, -2.0f, -3.0f, -4.0f, -6.0f
};

/* Byte -> its two weights, so the inner loop does one lookup, not two shifts. */
static void k3_pair_init(void)
{
    for (int b = 0; b < 256; b++) {
        K3_E2M1_PAIR[b][0] = K3_E2M1[b & 0x0F];   /* low nibble  = EVEN element */
        K3_E2M1_PAIR[b][1] = K3_E2M1[b >> 4];     /* high nibble = ODD  element */
    }
}

/* Scale byte -> power of two. 255 is NaN by spec, mapped to 0 to contain damage. */
static void k3_e8m0_init(void)
{
    for (int b = 0; b < 256; b++)
        K3_E8M0[b] = (b == 255) ? 0.0f : ldexpf(1.0f, b - 127);
}
Now the nibble order, which is a convention no statistic can check.
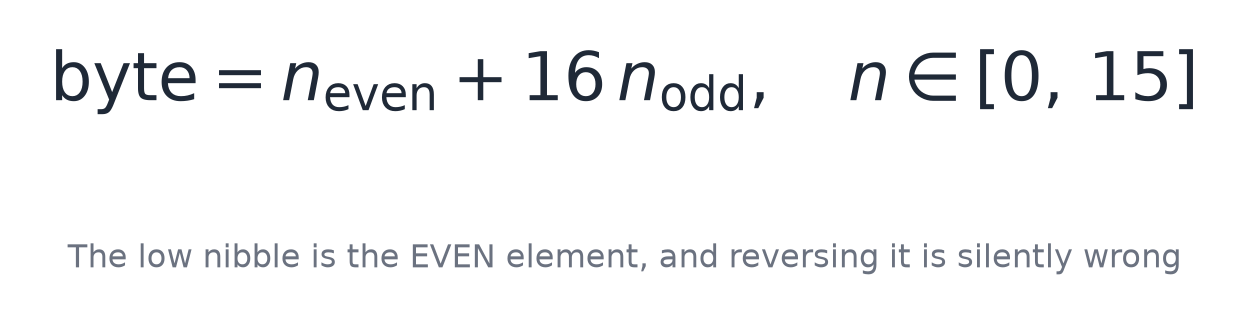
"expected_swapped_nibbles": {
  "note": "what you get if the low nibble is treated as the ODD element.
           Statistics are identical; positions are wrong."
}
Every mean, every standard deviation, every histogram of the swapped version is identical
to the correct one, because it is the same multiset of numbers. Only the positions differ.
A verification that checks distributions would pass a matrix with every adjacent pair of
weights transposed.
The obvious way to use these weights is to decode them into floats and then do a normal
matrix multiply. Pricing that:
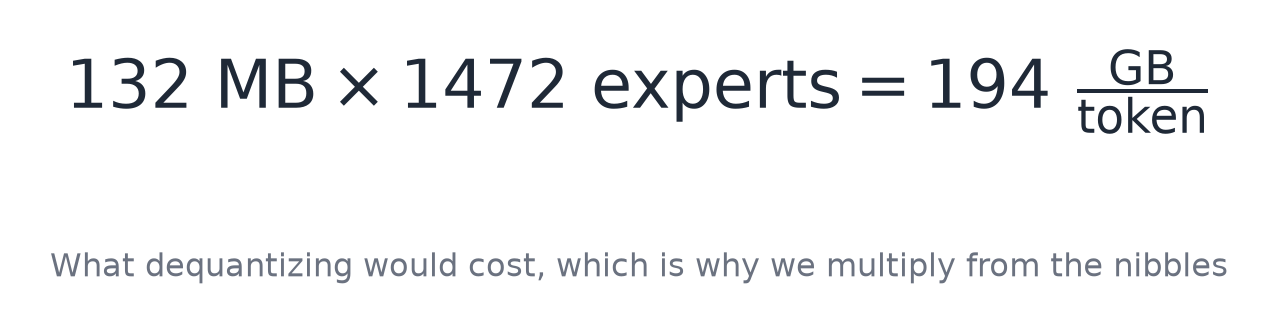
One expert at 17.55 MB becomes 132 MB once expanded to float32. Each token touches 16
experts across 92 layers (1,472 experts), so decoding them all would mean writing out
194 gigabytes per token of pure format conversion, before a single multiply-accumulate.
So nothing is ever dequantised. The matrix multiply reads packed nibbles directly.
/* y[rows] = x[in] . W[rows][in], W stored as MXFP4. Nothing is dequantized. */
void k3_matmul_mxfp4(float *y, const float *x, const unsigned char *packed,
                     const unsigned char *scales, int in, int rows, int group)
{
    const int ngroup = (in + group - 1) / group;
    const int rowbytes = (in + 1) / 2;              /* two nibbles per byte */

#pragma omp parallel for schedule(static)
    for (int o = 0; o < rows; o++) {
        const unsigned char *pb = packed + (size_t)o * rowbytes;
        const unsigned char *sb = scales + (size_t)o * ngroup;
        double acc = 0.0;                            /* double, always */

        for (int g = 0; g < ngroup; g++) {
            const float s = K3_E8M0[sb[g]];
            if (s == 0.0f) continue;                 /* a NaN scale zeroes the group */

            const int i0 = g * group;
            const int n = (i0 + group <= in) ? group : (in - i0);
            float wf[64];

            /* low nibble is the EVEN weight, high nibble the ODD one */
            const int half = n / 2;
            for (int k = 0; k < half; k++) {
                const unsigned char b = pb[(i0 / 2) + k];
                wf[2 * k]     = K3_E2M1_PAIR[b][0];  /* low  nibble -> even index */
                wf[2 * k + 1] = K3_E2M1_PAIR[b][1];  /* high nibble -> odd index  */
            }
            if (n & 1) wf[n - 1] = K3_E2M1_PAIR[pb[(i0 / 2) + half]][0];

            double part = 0.0;
            for (int k = 0; k < n; k++) part += (double)x[i0 + k] * (double)wf[k];
            acc += part * (double)s;
        }
        y[o] = (float)acc;
    }
}
Two details are worth pausing on. if (s == 0.0f) continue handles a scale byte of 255,
which the MXFP4 specification defines as NaN; mapping it to zero means one corrupt byte
kills one group of 32 weights instead of turning an entire row into NaN and poisoning
every downstream layer. And if (n & 1) handles a group with an odd number of elements.
with a group size of 32 that can never happen on this checkpoint, and it is written
anyway. That is the difference between code that works and code that is correct, and it
costs one line.
PASS mxfp4 64 rows x 3584 elems, EXACT on released checkpoint bytesNot "within tolerance", but exact. Both sides read identical bytes off identical weights,
so there is nothing that could legitimately differ, and the test is written with zero
tolerance to say so.
That is reduction one. The experts arrive at 0.53125 bytes per weight instead of 2, which
takes 5.45 TB of expert weights down to 1.447 TB, and never expanding them saves another
194 GB of memory traffic per token.
5. Kernels with a floating point contract
Every code path must produce the same bits. RMSNorm is the most used kernel in the model.
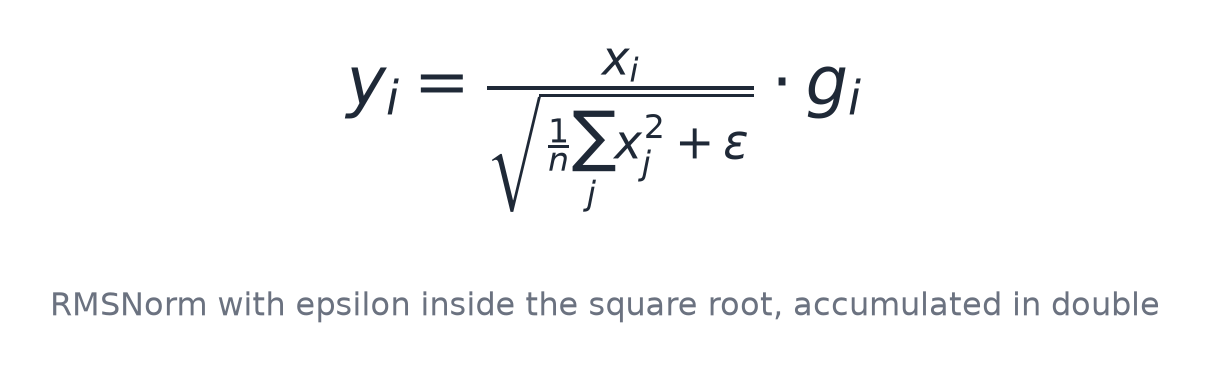
void k3_rmsnorm(float *out, const float *x, const float *w, int n, float eps)
{
    double ss = 0.0;                                   /* double, not float */
    for (int i = 0; i < n; i++) ss += (double)x[i] * (double)x[i];
    const float inv = (float)(1.0 / sqrt(ss / (double)n + (double)eps));
    for (int i = 0; i < n; i++) out[i] = x[i] * inv * (w ? w[i] : 1.0f);
}
Two details are load-bearing: the accumulator is a double even though every input and
output is a float, and epsilon goes inside the square root rather than outside.
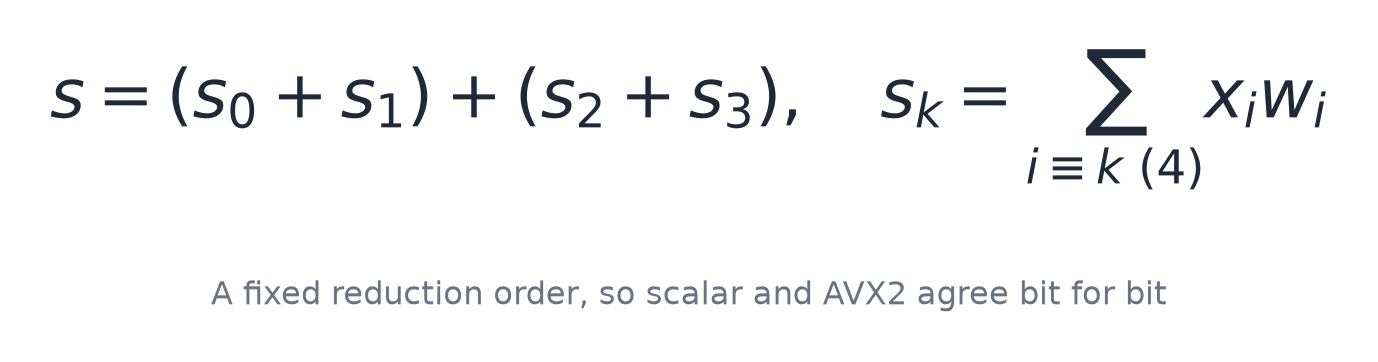
/* Four accumulators partitioned by i % 4. This pins the summation order, so a
 * 4-wide vector loop adds the same numbers in the same sequence. */
static float k3_dot4(const float *x, const float *w, int n)
{
    double a0 = 0.0, a1 = 0.0, a2 = 0.0, a3 = 0.0;
    int i = 0;
    for (; i + 3 < n; i += 4) {
        a0 += (double)x[i]     * (double)w[i];
        a1 += (double)x[i + 1] * (double)w[i + 1];
        a2 += (double)x[i + 2] * (double)w[i + 2];
        a3 += (double)x[i + 3] * (double)w[i + 3];
    }
    for (; i < n; i++) a0 += (double)x[i] * (double)w[i];
    return (float)((a0 + a1) + (a2 + a3));       /* the parentheses are the contract */
}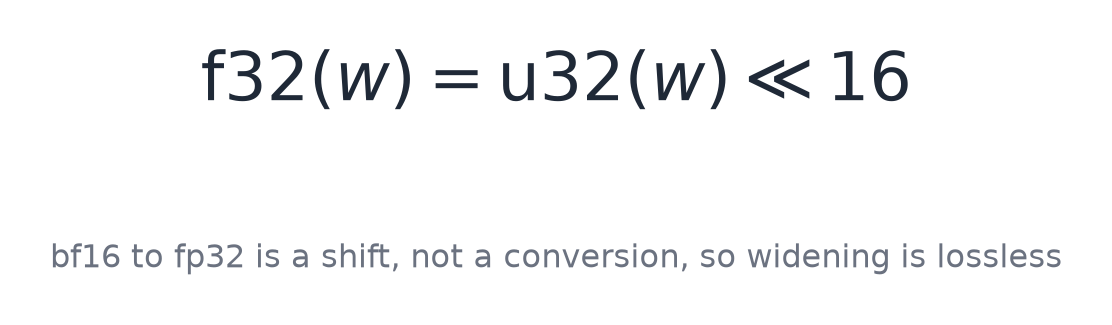
A bfloat16 value is the top 16 bits of a float32 with the bottom 16 dropped, so widening
is a shift left by 16 and it is exact. That is why the trunk can be streamed in its
shipped precision with no accuracy question at all, a point that becomes important much
later.
void k3_matmul_bf16(float *y, const float *x, const uint16_t *W, int in, int out)
{
#pragma omp parallel for schedule(static) if (out > 64)
    for (int o = 0; o < out; o++) {
        const uint16_t *row = W + (size_t)o * in;
        int i = 0;
        double acc;
#if defined(__AVX2__)
        {
            __m256d v = _mm256_setzero_pd();
            for (; i + 3 < in; i += 4) {
                /* bf16 -> f32 is a 16-bit shift: no table, no rounding */
                const __m128i h   = _mm_loadl_epi64((const __m128i *)(row + i));
                const __m128i b32 = _mm_slli_epi32(_mm_cvtepu16_epi32(h), 16);
                const __m256d wd  = _mm256_cvtps_pd(_mm_castsi128_ps(b32));
                const __m256d xd  = _mm256_cvtps_pd(_mm_loadu_ps(x + i));
                v = _mm256_add_pd(v, _mm256_mul_pd(wd, xd));   /* NOT fmadd */
            }
            double a[4];
            _mm256_storeu_pd(a, v);
            acc = (a[0] + a[1]) + (a[2] + a[3]);
        }
#else
        {
            double a0 = 0.0, a1 = 0.0, a2 = 0.0, a3 = 0.0;
            for (; i + 3 < in; i += 4) {
                a0 += (double)k3_bf16f(row[i    ]) * (double)x[i    ];
                a1 += (double)k3_bf16f(row[i + 1]) * (double)x[i + 1];
                a2 += (double)k3_bf16f(row[i + 2]) * (double)x[i + 2];
                a3 += (double)k3_bf16f(row[i + 3]) * (double)x[i + 3];
            }
            acc = (a0 + a1) + (a2 + a3);
        }
#endif
        for (; i < in; i++) acc += (double)k3_bf16f(row[i]) * (double)x[i];
        y[o] = (float)acc;
    }
}
Both branches accumulate into four doubles, both partition by i % 4, and both reduce as
(a0 + a1) + (a2 + a3). The vector path is the scalar path with the same additions
performed in the same order, four at a time.
Note the multiply-add. _mm256_add_pd of an _mm256_mul_pd is deliberately not
_mm256_fmadd_pd. A fused multiply-add rounds once instead of twice and is therefore
more accurate, which is exactly the problem: it would give a different answer from
the scalar loop, and a hardware capability must never change the output.
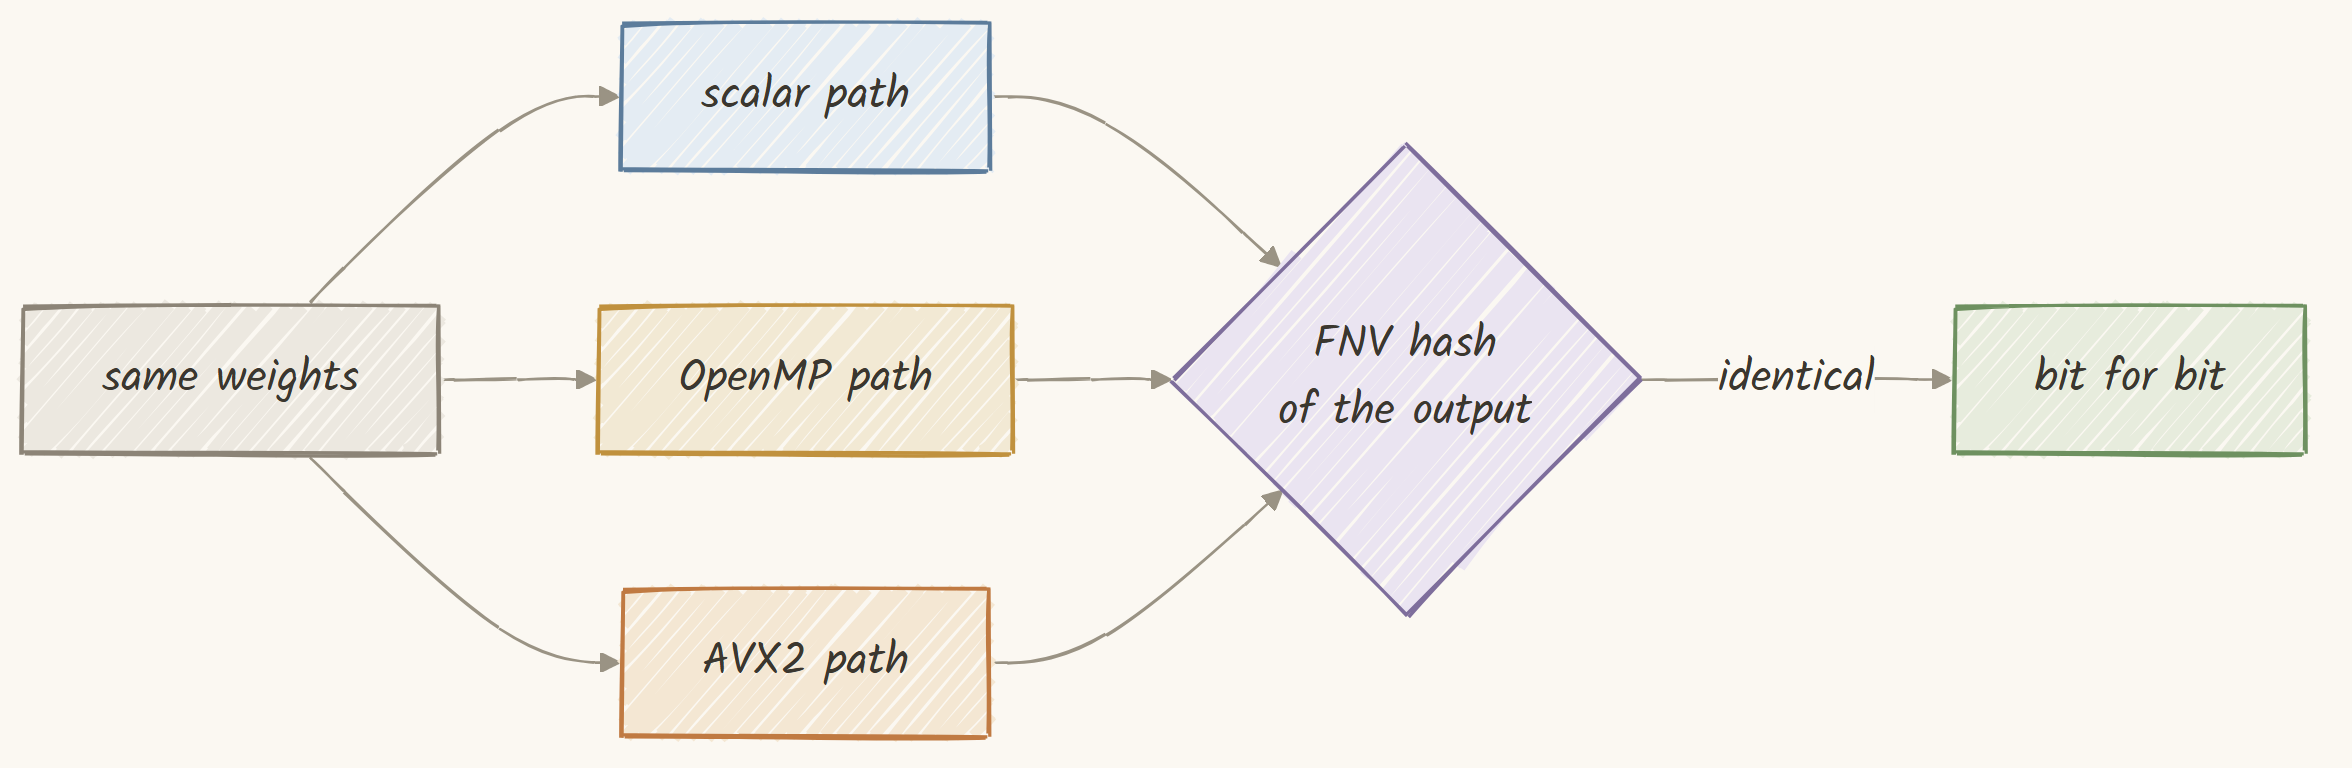
Proving the AVX2 and scalar paths agree cannot be done with a tolerance check, because a
tolerance check happily passes a kernel that quietly reassociated its sum. So the
benchmark hashes the output instead: FNV-1a over the exact bit pattern of every float in
the result, built twice, once with AVX2 and once without, then diff the digests.
tolerance: atol=1.0e-05 rtol=1.0e-04  (from MANIFEST.json)
  PASS  rmsnorm        n=384    worst=0.01x tol
  PASS  situ_glu       n=48     worst=0.00x tol
        bound check |out|=100.000 must be <= b1*b2=100.0 : ok
  PASS  kda_decay      H=4 D=16 tok=4  max|dg|=4.768e-07 max|dalpha|=1.788e-07
  PASS  mla            n=768    worst=0.08x tol
        H=4 qh=32 (nope 24 + rope 8) v=16 kv_lora=32 scale=0.176777
  PASS  mxfp4          64 rows x 3584 elems, EXACT on released checkpoint bytes
  PASS  matmul_bf16   n=129    bit-identical to k3_matmul
22 passed, 0 failed, 0 skipped
The worst case across all 22 kernels is 8 percent of the allowed tolerance, and two are
exact rather than merely close.
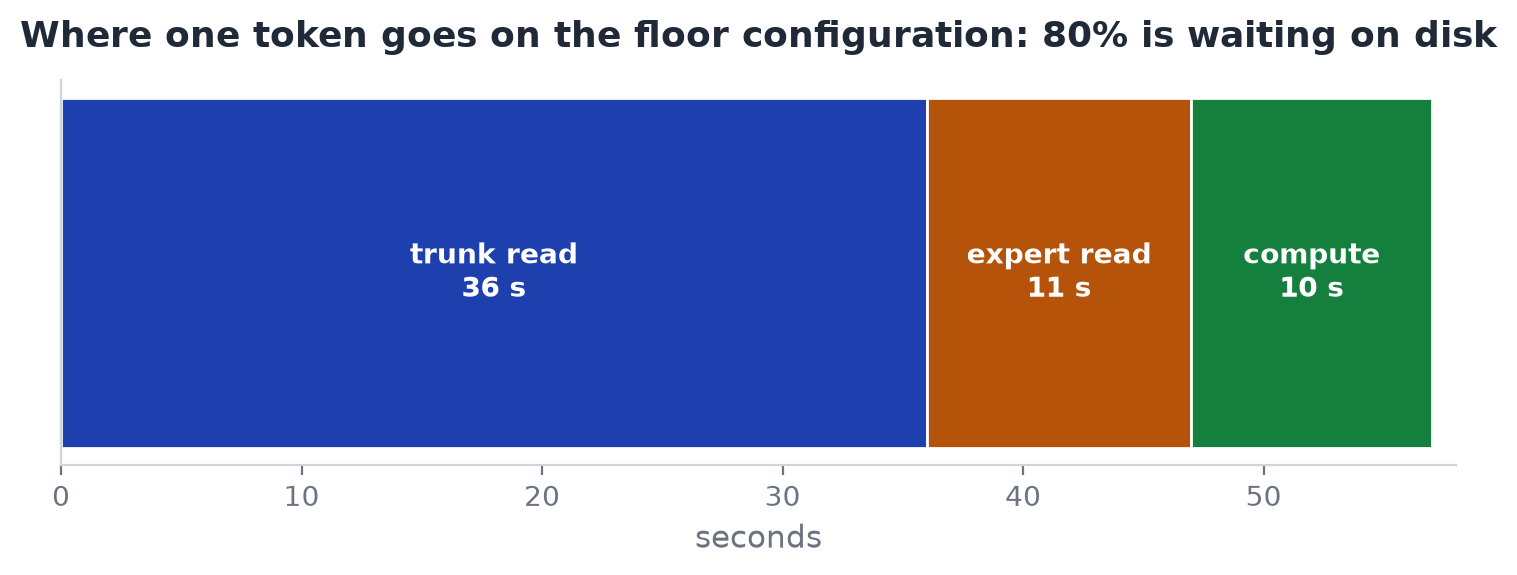
Benchmarked at the model's own dimensions on the smallest configuration, the split is
about 36 seconds of trunk reading, 11 seconds of expert reading and 10 seconds of
arithmetic. Eighty percent of a token is waiting for a disk, which is why the second
half of this document is about I/O and not about kernels.
6. Reduction two: KDA, attention with a memory that never grows
Sixty-nine of the 93 layers use Kimi Delta Attention, and its property that matters here
is easy to state: its memory does not grow with context length.
A standard attention layer stores a key and a value for every token it has seen, so its
cache grows linearly forever. KDA instead keeps one fixed-size matrix per head and updates
it in place as tokens arrive.
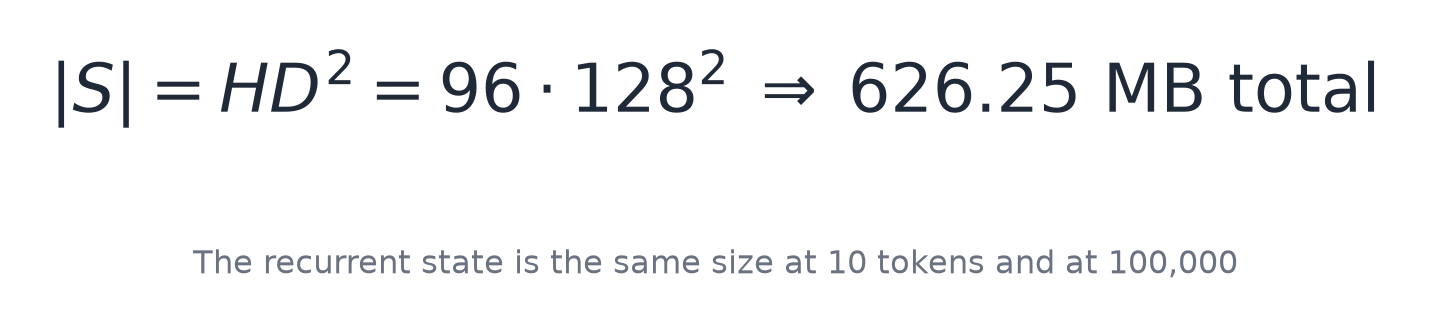
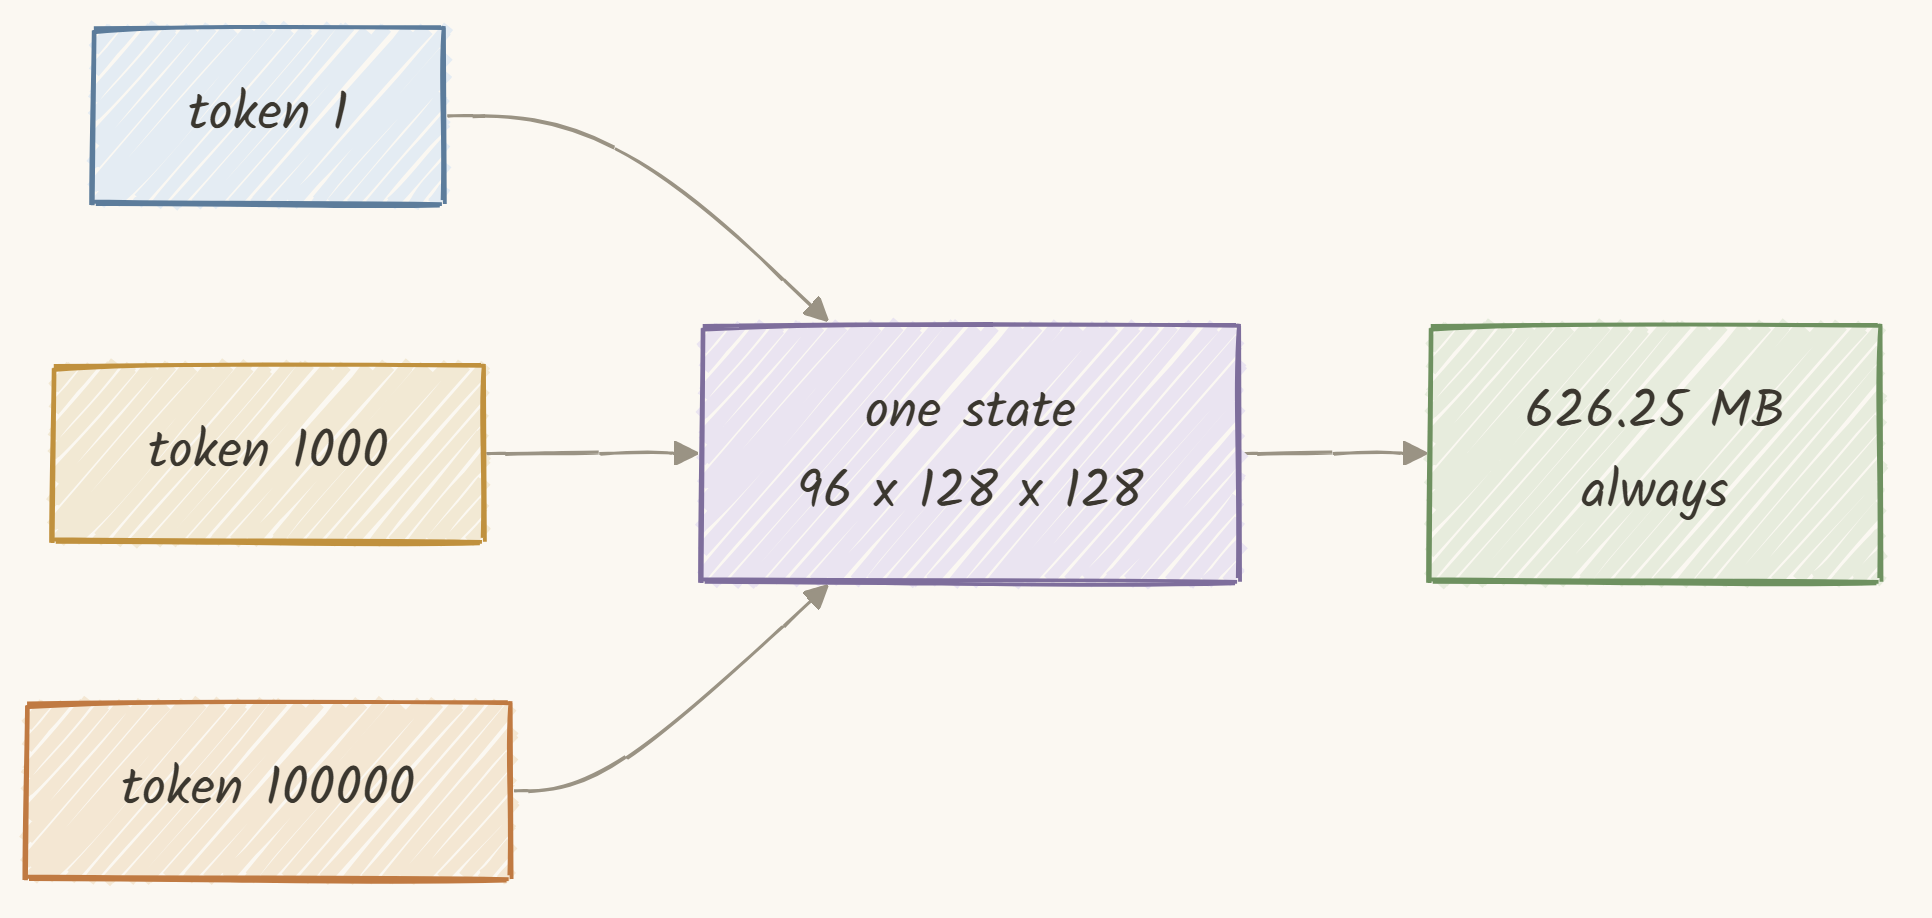
Ninety-six heads times a 128×128 matrix per head is the entire memory of a KDA layer, at
any sequence length. Across all 93 layers that is 626.25 megabytes, whether you feed
it ten tokens or a million.
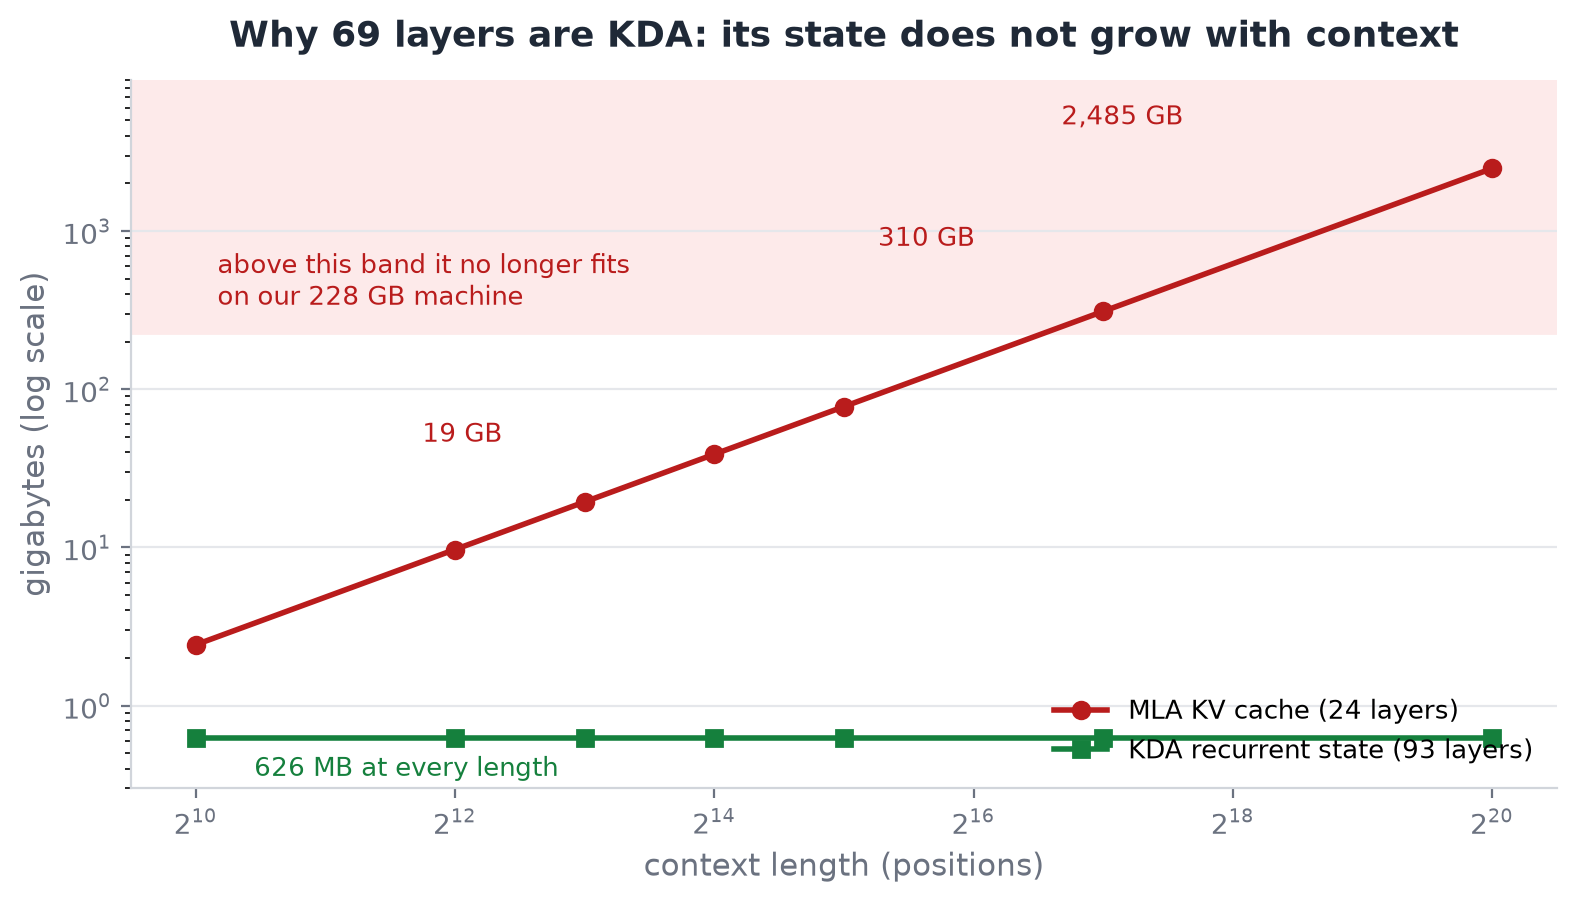
That plot is the argument for the whole design. The flat line is KDA. The rising line is
what the other 24 layers cost, and it crosses this machine's memory somewhere around
100,000 tokens. If all 93 layers behaved like it, the model would not fit at any context
length worth having.
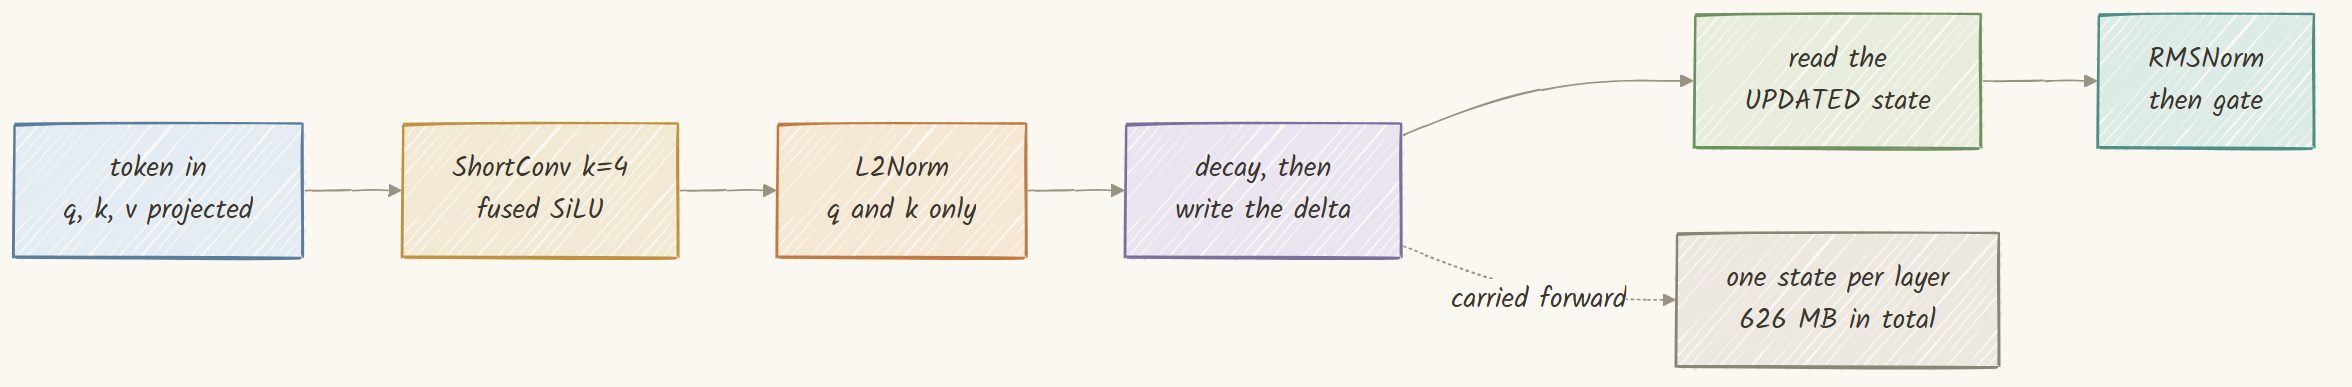
First, the projections go through a short depthwise causal convolution of width four with
SiLU fused in.
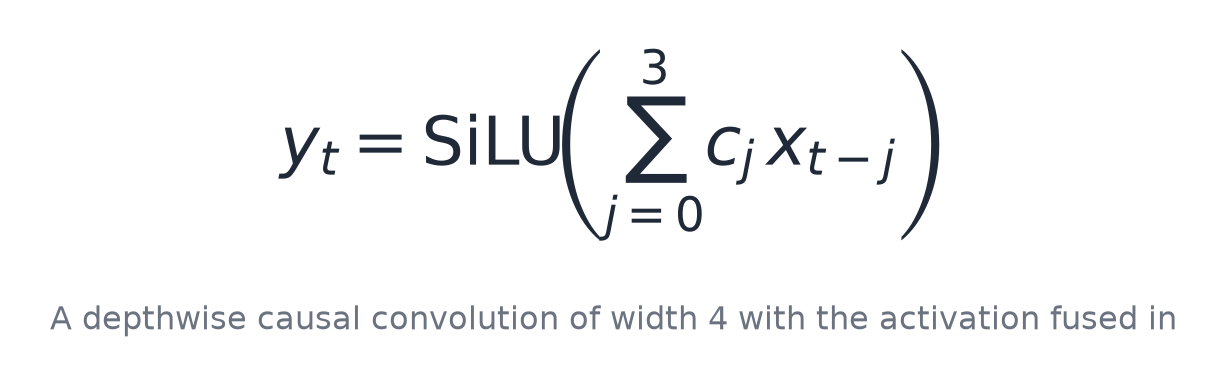
/* Causal depthwise conv with SiLU fused. State is carried across calls. */
void k3_shortconv(float *y, const float *x, const float *w, float *state,
                  int channels, int k, int T)
{
    const int hist = k - 1;                  /* guard on hist, not on buf */
    float *buf = hist ? (float *)malloc((size_t)hist * sizeof(float)) : NULL;
    if (hist && !buf) k3_fatal_oom("ShortConv history", (size_t)hist * sizeof(float));

    for (int c = 0; c < channels; c++) {
        if (hist) {
            if (state) memcpy(buf, state + (size_t)c * hist, (size_t)hist * sizeof(float));
            else       memset(buf, 0, (size_t)hist * sizeof(float));
        }

        for (int t = 0; t < T; t++) {
            const float cur = x[(size_t)t * channels + c];
            float acc = w[(size_t)c * k + hist] * cur;   /* taps run oldest to newest */
            for (int j = 0; j < hist; j++)
                acc += w[(size_t)c * k + j] * buf[j];

            for (int j = 0; j + 1 < hist; j++) buf[j] = buf[j + 1];
            if (hist > 0) buf[hist - 1] = cur;

            y[(size_t)t * channels + c] = acc * sigmoidf_(acc);   /* SiLU, fused */
        }
        if (state && hist) memcpy(state + (size_t)c * hist, buf, (size_t)hist * sizeof(float));
    }
    free(buf);
}
Note the guard on hist rather than on buf: with a kernel width of one there is no
history at all, malloc(0) is allowed to return NULL, and a check on the pointer would
silently skip the entire convolution and leave the output untouched.
Then the queries and keys are L2-normalised, a sum of squares, not a mean of squares,
which is a different function that looks nearly identical in code.
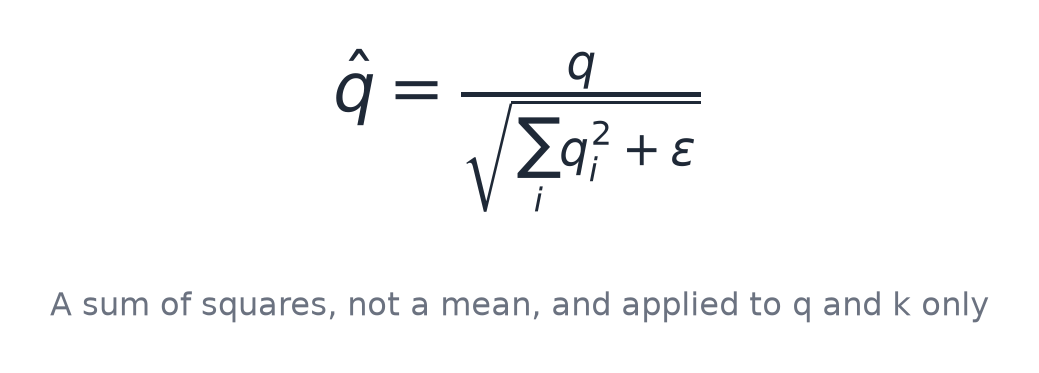
Then the decay gate, which is invariant one.
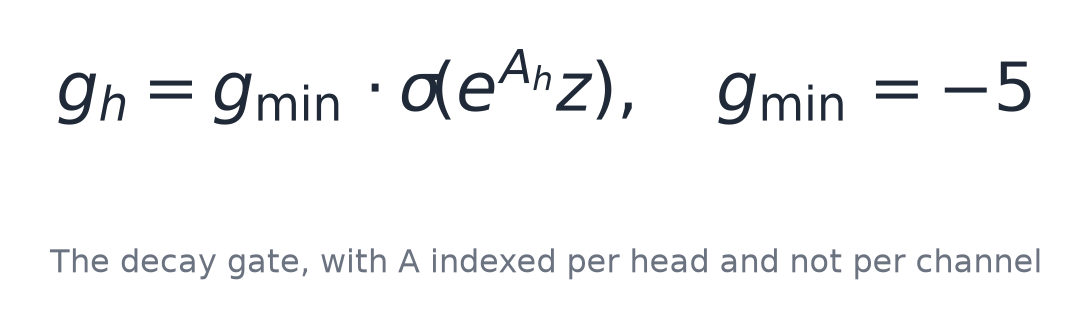
void k3_kda_decay(float *g, float *alpha, const float *z, const float *A_log,
                  const float *dt_bias, int H, int D, float lb)
{
    for (int h = 0; h < H; h++) {
        const float a = expf(A_log[h]);      /* PER HEAD, not per channel */
        for (int d = 0; d < D; d++) {
            const int i = h * D + d;
            const float u  = a * (z[i] + dt_bias[i]);
            const float gi = lb * sigmoidf_(u);   /* in (lb, 0] */
            g[i] = gi;
            alpha[i] = expf(gi);                  /* in (e^lb, 1] */
        }
    }
}
The gate lower bound is −5, so alpha lands between e^-5 and 1. Near one means this key
channel keeps almost all of its history; near e^-5 means it forgets almost everything,
per channel and per token.
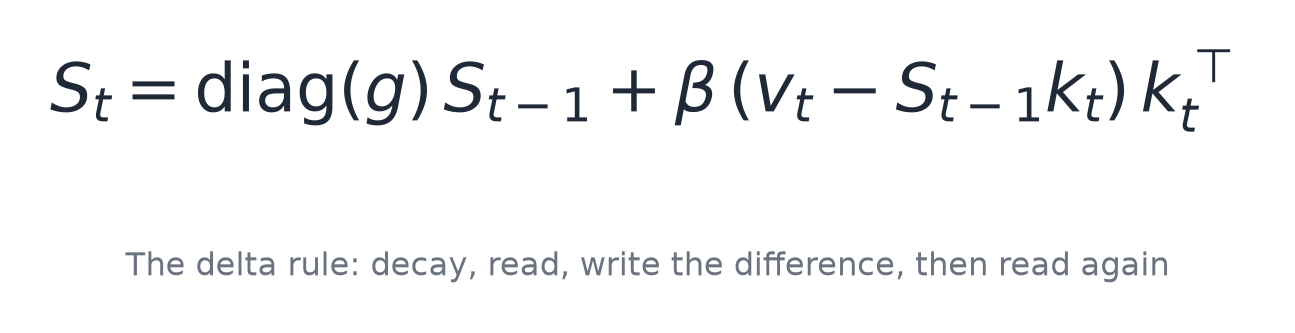
void k3_kda_step(float *S, float *o, const float *q, const float *k,
                 const float *v, const float *alpha, float beta, int dk, int dv)
{
    /* 1. decay: scale ROW i of S by alpha[i], per key channel */
    for (int i = 0; i < dk; i++) {
        float *row = S + (size_t)i * dv;
        const float a = alpha[i];
        for (int j = 0; j < dv; j++) row[j] *= a;
    }

    /* 2. read the state along k: u = S^T k */
    float *u = (float *)calloc((size_t)dv, sizeof(float));
    if (!u) k3_fatal_oom("KDA recurrence temporary", (size_t)dv * sizeof(float));
    for (int i = 0; i < dk; i++) {
        const float ki = k[i];
        if (ki == 0.0f) continue;
        const float *row = S + (size_t)i * dv;
        for (int j = 0; j < dv; j++) u[j] += ki * row[j];
    }

    /* 3. rank-one delta write: (v - u) is the prediction error */
    for (int i = 0; i < dk; i++) {
        const float ki = k[i];
        if (ki == 0.0f) continue;
        float *row = S + (size_t)i * dv;
        for (int j = 0; j < dv; j++) row[j] += ki * beta * (v[j] - u[j]);
    }

    /* 4. output from the ALREADY UPDATED state: o = S^T q */
    for (int j = 0; j < dv; j++) o[j] = 0.0f;
    for (int i = 0; i < dk; i++) {
        const float qi = q[i];
        if (qi == 0.0f) continue;
        const float *row = S + (size_t)i * dv;
        for (int j = 0; j < dv; j++) o[j] += qi * row[j];
    }
    free(u);
}
That calloc happens after step one has already scaled the state, so an early return
on allocation failure would leave the recurrent matrix permanently decayed but never
updated. Every subsequent token would then be computed from a state that is quietly wrong,
with nothing to indicate it. That is why the failure path aborts instead of returning.
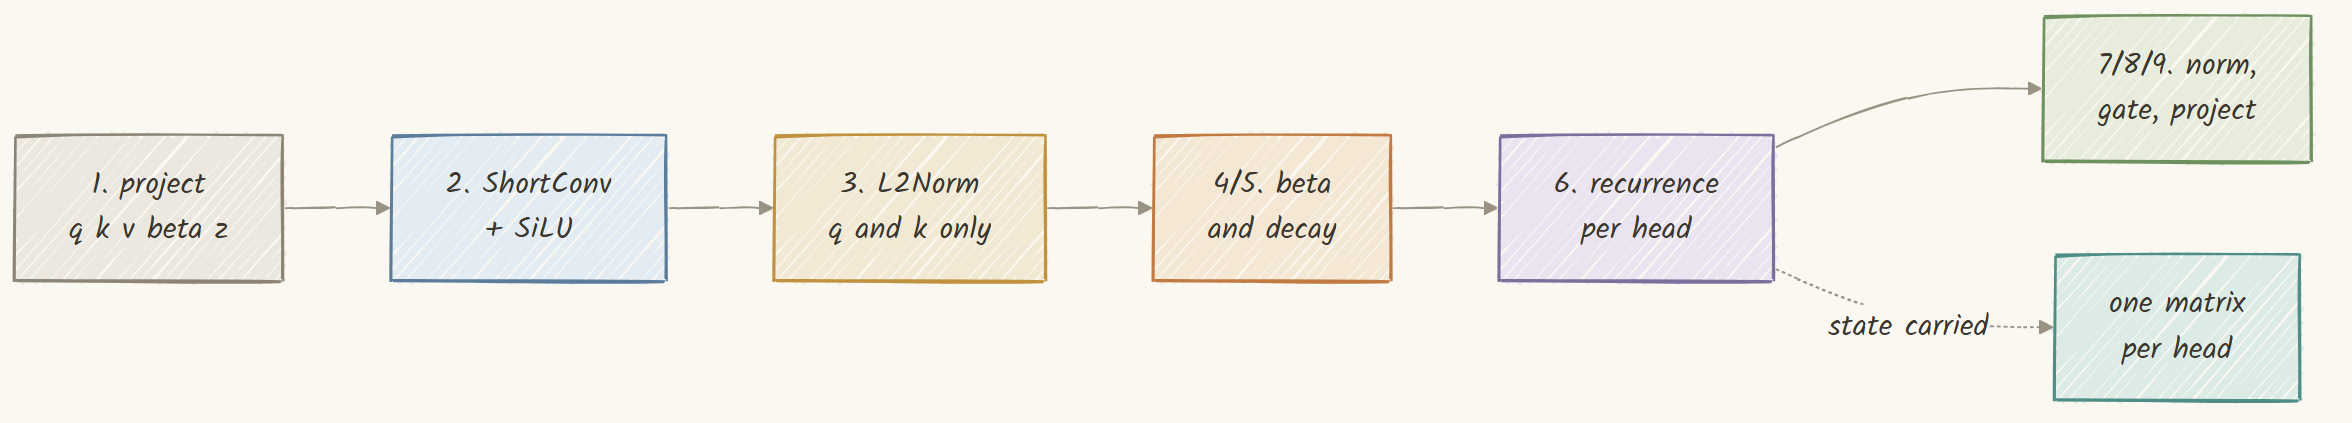
void k3_kda_layer(float *out, const float *x, const K3KdaW *w, const K3Cfg *c,
                  int T, float *state, float *scratch)
{
    const int E = c->hidden, H = c->kda_heads, D = c->kda_head_dim;
    const int P = H * D, K = c->conv_k, hist = K - 1;

    float *q  = scratch;                 float *k  = q + (size_t)T * P;
    float *v  = k + (size_t)T * P;       float *z  = v + (size_t)T * P;
    float *al = z + (size_t)T * P;       float *bt = al + (size_t)T * P;
    float *o  = bt + (size_t)T * H;      float *gb = o + (size_t)T * P;
    float *wr = gb + P;                  float *fa = wr + P;

    /* 1. projections */
    for (int t = 0; t < T; t++) {
        const float *xt = x + (size_t)t * E;
        k3_mmw(q + (size_t)t * P, xt, w->q, w->wdt, E, P);
        k3_mmw(k + (size_t)t * P, xt, w->k, w->wdt, E, P);
        k3_mmw(v + (size_t)t * P, xt, w->v, w->wdt, E, P);
        k3_mmw(bt + (size_t)t * H, xt, w->b, w->wdt, E, H);
        k3_mmw(fa, xt, w->f_a, w->wdt, E, D);        /* one low-rank pair, all heads */
        k3_mmw(z + (size_t)t * P, fa, w->f_b, w->wdt, D, P);
    }

    /* 2. ShortConv with fused SiLU, carrying state across calls */
    float *cs = state ? state + (size_t)H * D * D : NULL;
    k3_shortconv(q, q, w->q_conv, cs ? cs : NULL, P, K, T);
    k3_shortconv(k, k, w->k_conv, cs ? cs + (size_t)P * hist : NULL, P, K, T);
    k3_shortconv(v, v, w->v_conv, cs ? cs + (size_t)2 * P * hist : NULL, P, K, T);

    /* 3. L2Norm on q and k ONLY, per head. v is deliberately left alone. */
    for (int t = 0; t < T; t++)
        for (int h = 0; h < H; h++) {
            l2nor