

README
 [**Tejaswi Kasarla**](https://tkasarla.github.io/)
 [**Yejin Bang**](https://scholar.google.com/citations?user=s2bVuXEAAAAJ)
[**Mustafa Shukor**](https://mustafashukor.github.io/)
 [**Willy Chung**](https://willyhc22.github.io/)
[**Jade Yu**](https://jadeleiyu.github.io/)
[**Allen Bolourchi**](https://viterbi.usc.edu/directory/faculty/Bolourchi/Allen)
[**Théo Moutakanni**](https://scholar.google.com/citations?user=nN2MKGwAAAAJ)
[**Pascale Fung**](https://scholar.google.com/citations?user=QEMJWzEAAAAJ/)
Meta FAIR
HKUST
University of Amsterdam
Sorbonne Université
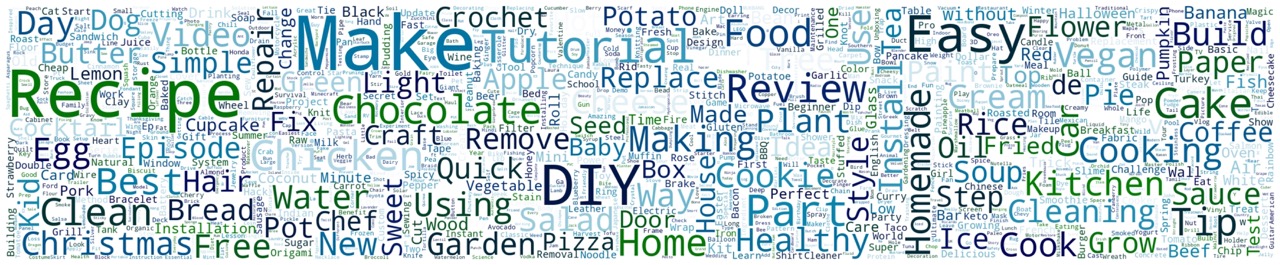
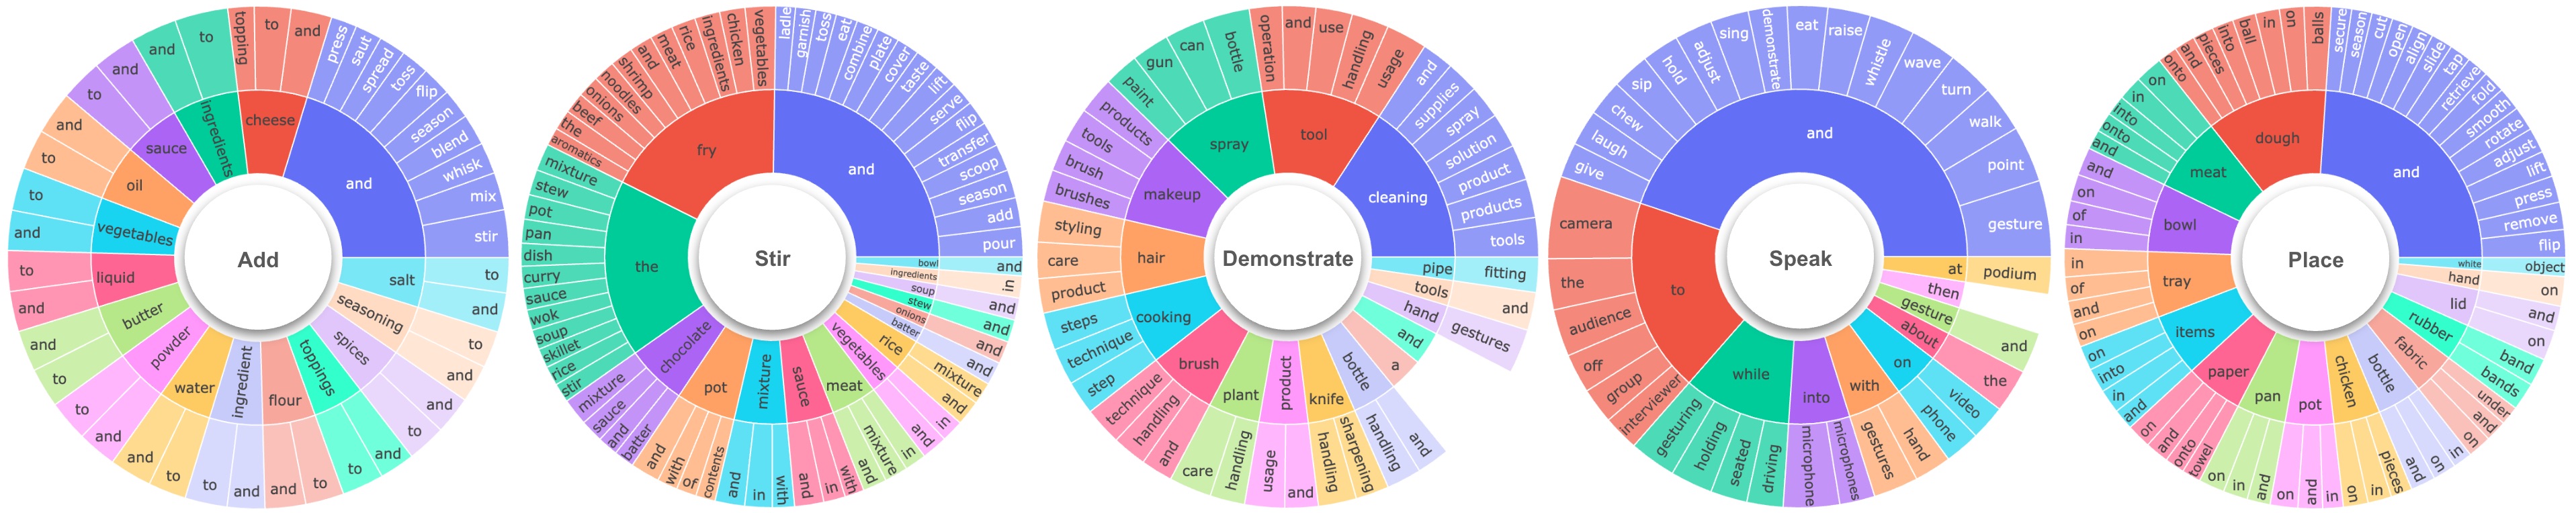
Load Action100M Annotations
Our data can be loaded from the 🤗 huggingface repo at facebook/action100m-preview where we released 10% of the full Action100M for preview. For examples of loading from local parquet files (from cloned repo) and visualization, see usage.ipynb. The data/hySSAAw4t24.json stored in this repo shows a sample.
from datasets import load_dataset

dataset = load_dataset(
    "parquet",
    data_files=f"hf://datasets/facebook/Action100M-preview/data/*.parquet",
    streaming=True,
)
it = iter(dataset["train"])

sample = next(it)
Each sample loaded above contains all annotations for one video, and it has three fields:
video_uid(string): YouTube video id of the source video.metadata(dict): video-level metadata (title / description / ASR transcript, etc.)nodes(list[dict]): annotations for each segments.
Each element in nodes is a temporally localized segment in the hierachical Tree-of-Captions, it contains:
-
start,end(float): segment boundaries in seconds within the full video. -
node_id(string): unique id of this segment node. -
parent_id(string or null): id of the parent segment. The root node (corresponding to the entire video) hasparent_id = null. -
level(int): depth in the hierarchy. Smallerlevelis coarser (longer segments); largerlevelis finer (shorter segments). -
plm_caption(string or null): a caption generated by PLM-3B for this segment. -
plm_action(string or null): a short action label produced by PLM-3B. -
llama3_caption(string or null): middle frame caption produced by LLama-3.2-Vision-11B for leaf nodes. -
gpt(dict or null): main Action100M annotations, available for segments that is not too short:gpt["summary"]["brief"]: one-sentence concise caption of the segment.gpt["summary"]["detailed"]: longer, detailed summarization of the video segment.gpt["action"]["brief"]: short verb phrase naming the step.gpt["action"]["detailed"]: imperative-style instruction describing how the action is done.gpt["action"]["actor"]: who/what performs the action (noun phrase).
Exampls
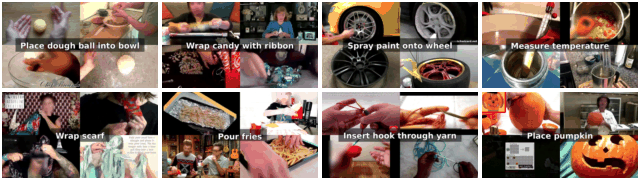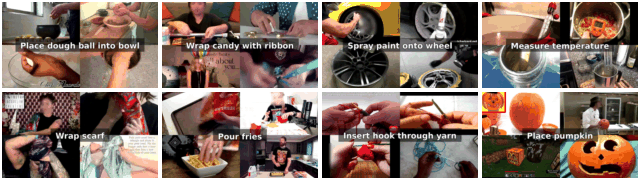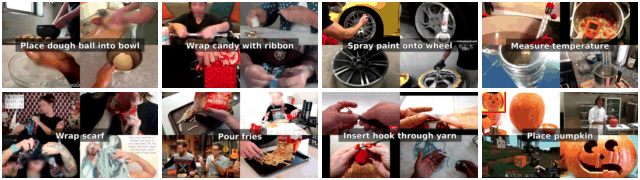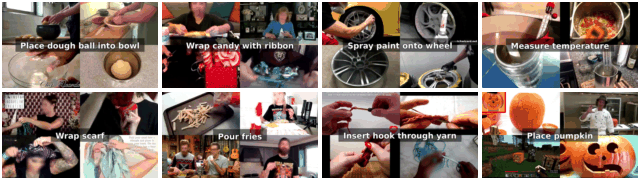
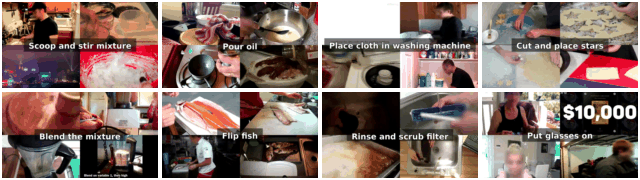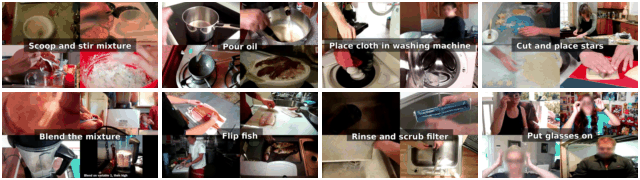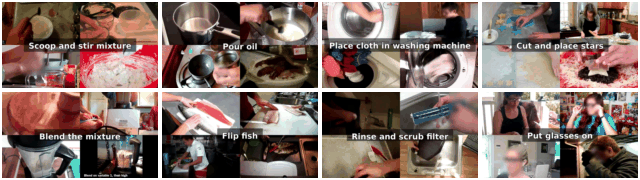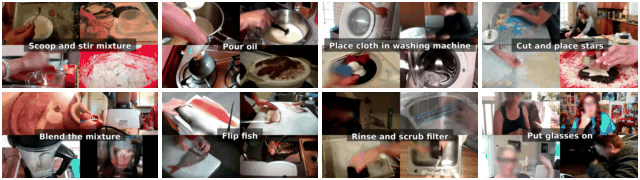
Texts shown correspond to brief action description (i.e., gpt["action"]["brief"]).
License
Action100M is under FAIR Noncommercial Research License, as found in the LICENSE file.
Citation
@article{chen2026action100m,
  title={Action100M: A Large-scale Video Action Dataset},
  author={Chen, Delong and Kasarla, Tejaswi and Bang, Yejin and Shukor, Mustafa and Chung, Willy and Yu, Jade and Bolourchi, Allen and Moutakanni, Théo and Fung, Pascale},
  journal={arXiv preprint arXiv:2601.10592},
  year={2026}
}