

Repository
On-Policy-Self-Adaptation
Does On-Policy Distillation Really Distill? From Noisy Teacher to Self-Improvement
README
📖 Introduction • 📊 Results • 🚀 Reproduce OPSA • 🗂️ Dataset Preparation
<a id="introduction"></a>
Introduction
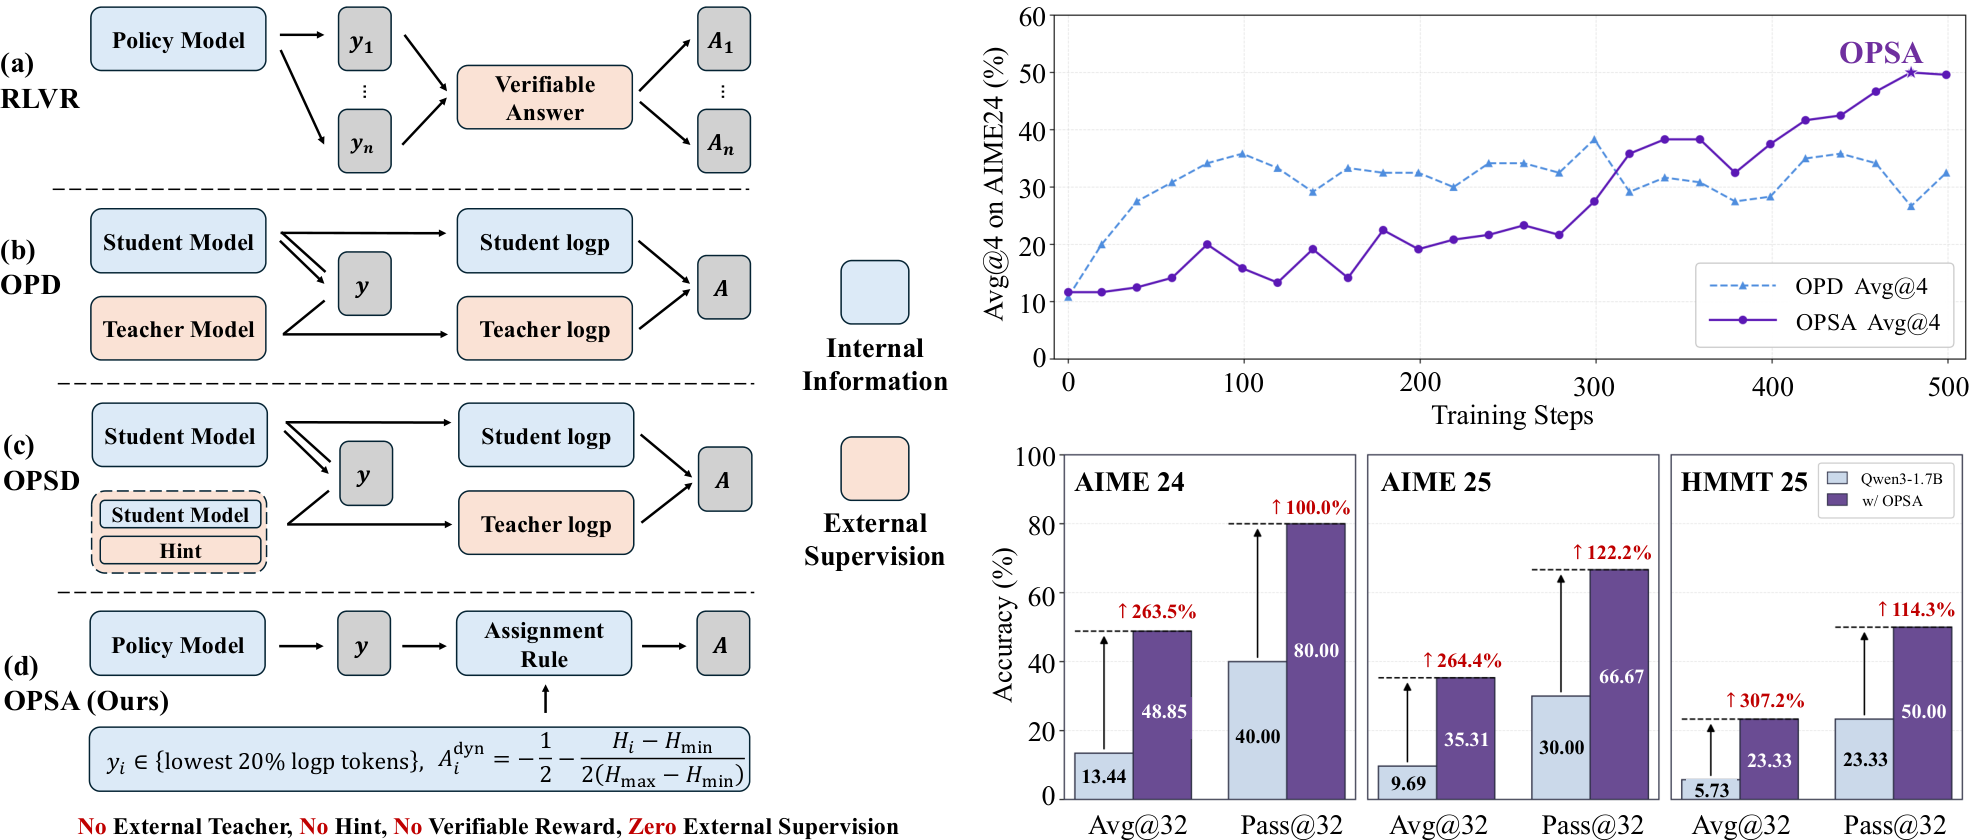
OPSA improves a policy without a teacher model, reward model, reference-model
forward pass, or task reward. The canonical configuration trains only the 20%
of valid response tokens with the lowest actor log probabilities and assigns
entropy-adaptive negative advantages between -0.5 and -1.0. All other
tokens are excluded from the policy loss.
<a id="results"></a>
Results
The three math columns report Avg@32 / Pass@32; the two O.O.D. columns
report Avg@32 only. All values are from the OPSA manuscript.
| Model | Variant | AIME24 | AIME25 | HMMT25 | MBPP+ Avg@32 | GPQA_D Avg@32 |
|---|---|---|---|---|---|---|
| Qwen3-1.7B | Base | 13.44 / 40.00 | 9.69 / 30.00 | 5.73 / 23.33 | 58.24 | 27.92 |
| Qwen3-1.7B | + OPSA | 48.85 / 80.00 | 35.31 / 66.67 | 23.33 / 50.00 | 59.44 | 32.40 |
| Qwen3-4B | Base | 23.33 / 56.67 | 20.52 / 56.67 | 13.13 / 33.33 | 66.93 | 38.46 |
| Qwen3-4B | + OPSA | 62.08 / 83.33 | 58.44 / 83.33 | 37.40 / 60.00 | 68.35 | 41.29 |
| Qwen3.5-9B | Base | 76.35 / 93.33 | 56.04 / 93.33 | 44.48 / 86.67 | 77.33 | 70.53 |
| Qwen3.5-9B | + OPSA | 87.81 / 96.67 | 76.98 / 96.67 | 67.40 / 93.33 | 79.27 | 73.70 |
The models are trained and evaluated in non-thinking mode. Training uses only
the questions from DAPO-17k. Evaluation samples 32 responses per prompt with
temperature 0.7, top-k 20, top-p 0.8, and maximum response length
32,768.
<a id="reproduce-opsa"></a>
Reproduce OPSA
Installation
git clone https://github.com/DripNowhy/On-Policy-Self-Adaptation.git
cd On-Policy-Self-Adaptation/slime
pip install -e .
<a id="dataset-preparation"></a>
Dataset preparation
Install the Hugging Face CLI and choose an external data directory:
python3 -m pip install --upgrade huggingface_hub
export OPSA_DATA_DIR=/path/to/opsa-data
mkdir -p "${OPSA_DATA_DIR}"
Download the exact Slime-ready JSONL files used by this project:
hf download zhuzilin/dapo-math-17k dapo-math-17k.jsonl \
  --repo-type dataset \
  --revision 2e65612930298bde4c5d58fd97b3f23a483aaff9 \
  --local-dir "${OPSA_DATA_DIR}/dapo-math-17k"

hf download zhuzilin/aime-2024 aime-2024.jsonl \
  --repo-type dataset \
  --revision 1c625e328db94ec7ef7ff169016b097c468d60b9 \
  --local-dir "${OPSA_DATA_DIR}/aime-2024"
The resulting training file has 17,398 rows and the AIME24 evaluation file has
30 rows. Both already contain the required prompt and label fields, so no
conversion is needed. OPSA training loads only prompt and always uses zero
task reward; label is read only during evaluation.
The training JSONL is the pinned
Slime-ready mirror
of the
original DAPO-Math-17k.
Use the pinned mirror for exact reproduction rather than the currently
duplicated 1.79M-row upstream parquet. The AIME24 file comes from the
Slime-ready AIME24 mirror.
These external datasets remain subject to their own terms.
CPU dry run
This resolves and prints the complete command without checking paths, querying
GPUs, starting Ray, or training:
bash examples/opsa/run_opsa.sh \
  --model qwen3-1.7b \
  --preset opsa \
  --fraction 0.2 \
  --dry-run
GPU training
Prepare a Hugging Face checkpoint, its converted Megatron actor checkpoint, and
a Megatron-LM checkout. See the
checkpoint conversion instructions.
After replacing the model and output paths below, this command starts the
canonical Qwen3-1.7B OPSA run on a single machine with 8 GPUs:
bash examples/opsa/run_opsa.sh \
  --model qwen3-1.7b \
  --preset opsa \
  --fraction 0.2 \
  --hf-checkpoint /path/to/Qwen3-1.7B \
  --actor-checkpoint /path/to/qwen3-1.7b-megatron \
  --save-dir /path/to/outputs/opsa-qwen3-1.7b-lowest20 \
  --prompt-data "${OPSA_DATA_DIR}/dapo-math-17k/dapo-math-17k.jsonl" \
  --eval-data "${OPSA_DATA_DIR}/aime-2024/aime-2024.jsonl" \
  --megatron-path /path/to/Megatron-LM
This preset uses 4 actor GPUs and 4 rollout GPUs, runs for 700 steps, and saves
and evaluates every 20 steps. The launcher starts a local Ray cluster and stops
only the cluster it started. See the
launcher guide for existing Ray clusters and the
other supported models.
<a id="training-logs"></a>
Training logs
Reference training curves and metrics are available in the
public W&B workspace.
<a id="license"></a>
License
This project is built on slime and released
under the Apache License 2.0. See UPSTREAM.md for
snapshot provenance.