

Repository
TextCall
Official implementation of TextCall: tool calls as text scaffolds for visual reasoning.
- Resource
- Status
- Training
- Available
- Evaluation
- Available
- Checkpoint
- Coming soon
Specs
- ResourceStatus
- TrainingAvailable
- EvaluationAvailable
- CheckpointComing soon
- DatasetAvailable
- ComponentRequirement
- Python3.11+
- CUDA12.4+
- PyTorch2.4+ and below 2.9
- PlatformLinux with NVIDIA GPU for training and evaluation
- GPU countOne or more for evaluation and LoRA; multi-GPU for full SFT / RL
- VariablePurpose
- TEXTCALL_DATA_ROOTRoot directory for public datasets
- TEXTCALL_OUTPUT_ROOTTraining and evaluation outputs
- TEXTCALL_BASE_MODELBase model used for SFT
- TEXTCALL_MODEL_PATHSFT checkpoint used to initialize RL
- BYPASSEnable TextCall bypass evaluation mode
- DP_REPLICAS / TP / NPROCData replicas / tensor parallelism / eval workers
- GEMINI_API_KEYCredential for the Gemini image-editing backend
- GEMINI_IMAGE_MODELGemini image-editing model
README
<h1 align="center">TextCall</h1>
Thinking With Tools, Not With Pixels: Tool Calls as Text Scaffolds for Visual Reasoning


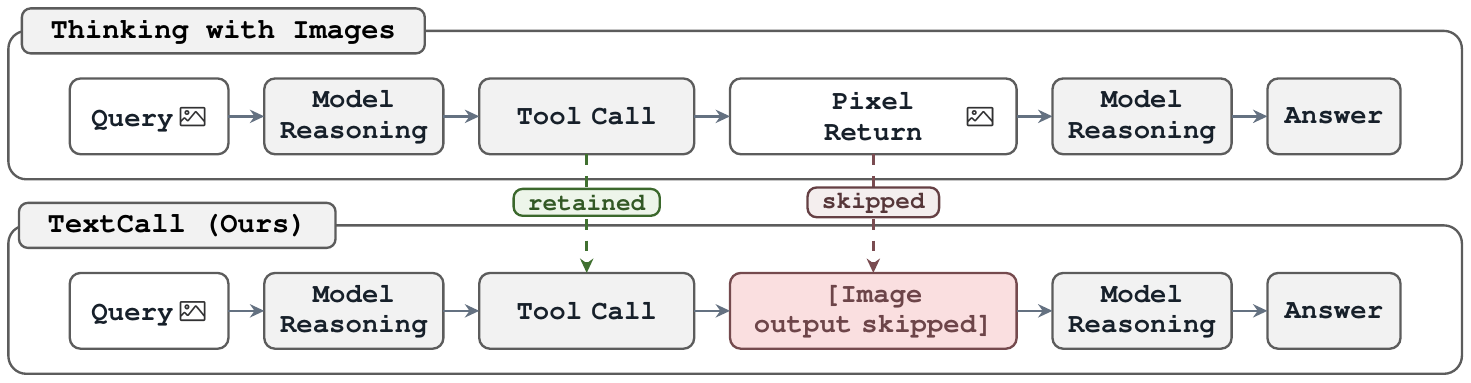
TextCall is the official implementation for training and evaluating
visual-reasoning models that retain tool calls as textual reasoning context.
Contents
- Overview
- Availability
- Quick Start
- Configuration
- Data
- Evaluation
- Training
- Implementation Notes
- Documentation
- Related Work
- License
- Acknowledgments
- Citation
Overview
- Tool-call traces remain in the context even when returned images are omitted.
- The repository includes SFT, RL, inference, and benchmark entry points.
- Training and evaluation frameworks are pinned as Git submodules. Compatibility
fixes live underpatches/instead of modifying upstream code.
Availability
| Resource | Status | Link |
|---|---|---|
| Training | Available | Training guide |
| Evaluation | Available | Evaluation guide |
| Checkpoint | Coming soon | — |
| Dataset | Available | DeepEyesV2 SFT · DeepEyesV2 RL |
Quick Start
Requirements
| Component | Requirement |
|---|---|
| Python | 3.11+ |
| CUDA | 12.4+ |
| PyTorch | 2.4+ and below 2.9 |
| Platform | Linux with NVIDIA GPU for training and evaluation |
| GPU count | One or more for evaluation and LoRA; multi-GPU for full SFT / RL |
Clone the repository with its pinned third-party dependencies, then install the
full environment with uv:
git clone --recurse-submodules https://github.com/ant-research/TextCall.git
cd TextCall

UV_EXTRA_INDEX_URL=https://download.pytorch.org/whl/cu124 uv sync --extra all
cp .env.example .env
# Edit .env, then load it into the current shell.
source .env
Alternatively, the setup script initializes submodules, installs dependencies,
and runs the checks and offline smoke pipeline:
bash scripts/setup/run_all.shSee the quickstart for smoke tests and the
environment guide for detailed hardware requirements.
Configuration
Set local paths and credentials in .env, then run source .env; never commit
API keys. The most
frequently used settings are:
| Variable | Purpose | Example |
|---|---|---|
TEXTCALL_DATA_ROOT |
Root directory for public datasets | /data/textcall |
TEXTCALL_OUTPUT_ROOT |
Training and evaluation outputs | /outputs/textcall |
TEXTCALL_BASE_MODEL |
Base model used for SFT | /models/Qwen2.5-VL-7B-Instruct |
TEXTCALL_MODEL_PATH |
SFT checkpoint used to initialize RL | /outputs/sft_checkpoint |
BYPASS |
Enable TextCall bypass evaluation mode | 1 |
DP_REPLICAS / TP / NPROC |
Data replicas / tensor parallelism / eval workers | 4 / 2 / 16 |
GEMINI_API_KEY |
Credential for the Gemini image-editing backend | Set locally |
GEMINI_IMAGE_MODEL |
Gemini image-editing model | gemini-3-pro-image |
The complete template is .env.example. Evaluation-specific
options are documented in docs/evaluation.md.
Data
Training data comes from the public DeepEyesV2 Hugging Face datasets:
Download the datasets from Hugging Face and set the local paths in .env or on
the command line.
Evaluation
Evaluate a checkpoint on a supported benchmark:
bash scripts/benchmark/run_public_eval.sh /path/to/checkpoint VStarBenchFor TextCall bypass checkpoints, set BYPASS=1. A multi-GPU example with four
data-parallel replicas and tensor parallelism of two is:
DP_REPLICAS=4 TP=2 NPROC=16 BYPASS=1 \
  bash scripts/benchmark/run_public_eval.sh \
  /path/to/checkpoint "VStarBench,HRBench4K,MMStar"
See docs/evaluation.md for supported benchmarks, modes,
environment variables, and troubleshooting.
Training
Supervised Fine-Tuning
TEXTCALL_BASE_MODEL=/path/to/Qwen2.5-VL-7B-Instruct \
  bash scripts/training/run_public_sft.sh \
  configs/llamafactory/public_sft_lora.yaml
Reinforcement Learning
TEXTCALL_MODEL_PATH=/path/to/sft_checkpoint \
  bash scripts/training/run_public_rl.sh configs/verl/public_rl.yaml
For the complete training and evaluation workflow, follow
docs/full_reproduction.md.
Implementation Notes
<details>
<summary><strong>Repository structure</strong></summary>
TextCall/
├── third_party/              # Clean, pinned upstream submodules
│   ├── verl/                 # RL training framework
│   ├── LlamaFactory/         # SFT training framework
│   └── VLMEvalKit/           # Evaluation framework
├── patches/                  # Runtime compatibility patches
├── eval/                     # VLMEvalKit extensions
├── rl/                       # RL data, rewards, and agent loop
├── configs/                  # SFT, RL, and evaluation configs
├── scripts/                  # Setup, training, and benchmark entry points
├── data/                     # Sample inputs for offline smoke tests
├── tests/                    # Lightweight data and evaluation tests
└── docs/                     # Reproduction documentation
</details>
Third-party code is never edited in place. Framework compatibility changes are
applied through patches/, and custom VLMEvalKit files are installed from
eval/vlmevalkit_extensions/ during setup. Dependency provenance is recorded
in THIRD_PARTY.md, and the patch policy is documented in
PATCHES.md.
Documentation
Related Work
- Thinking with images —
OpenAI's overview of models integrating visual information directly into the
reasoning process. - DeepEyes
(code) — learns active visual
perception through reinforcement learning. - DeepEyesV2
(code) — extends this direction
to multimodal agents using code execution and search.
License
TextCall is released under the Apache License 2.0. Third-party
submodules retain their respective upstream licenses; see
THIRD_PARTY.md for versions and provenance.
Acknowledgments
This repository builds on
Qwen2.5-VL,
DeepEyesV2,
verl,
LLaMA-Factory, and
VLMEvalKit. We thank their
contributors for making these resources available.
Citation
@misc{shao2026thinkingtoolspixelstool,
  title         = {Thinking With Tools, Not With Pixels: Tool Calls as Text Scaffolds for Visual Reasoning},
  author        = {Jiahao Shao and Yuanbo Yang and Yiyi Liao and Yujun Shen and Ceyuan Yang and Yinghao Xu},
  year          = {2026},
  eprint        = {2608.09682},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2608.09682}
}