

Repository
ai-ds-job-market
A simple open-source dashboard to analyze how AI is disrupting the Data Science job market
- Category
- Examples
- Programming Languages
- Python, R, SQL, Java, Scala
- Data Storage & Databases
- PostgreSQL, MongoDB, Snowflake, Redis
- Data Processing & ETL
- Spark, Kafka, Airflow, Databricks
Specs
- CategoryExamples
- Programming LanguagesPython, R, SQL, Java, Scala
- Data Storage & DatabasesPostgreSQL, MongoDB, Snowflake, Redis
- Data Processing & ETLSpark, Kafka, Airflow, Databricks
- Data VisualizationTableau, Power BI, Looker, Plotly
- ML/DL FrameworksPyTorch, TensorFlow, Scikit-learn, XGBoost
- Cloud PlatformsAWS, GCP, Azure
- Development ToolsGit, Jupyter Notebook, Anaconda
- DevOps & MLOpsDocker, Kubernetes, MLflow
- Core Data ScienceMachine Learning, A/B Testing, Feature Engineering
- Artificial IntelligenceLLMs, GenAI, RAG, Prompt Engineering, LangChain
README
AI in the Data Science Job Market
<a href="https://ai-in-ds.streamlit.app/" target="_blank">

</a>
<a href="https://futureproofds.com" target="_blank">
</a>
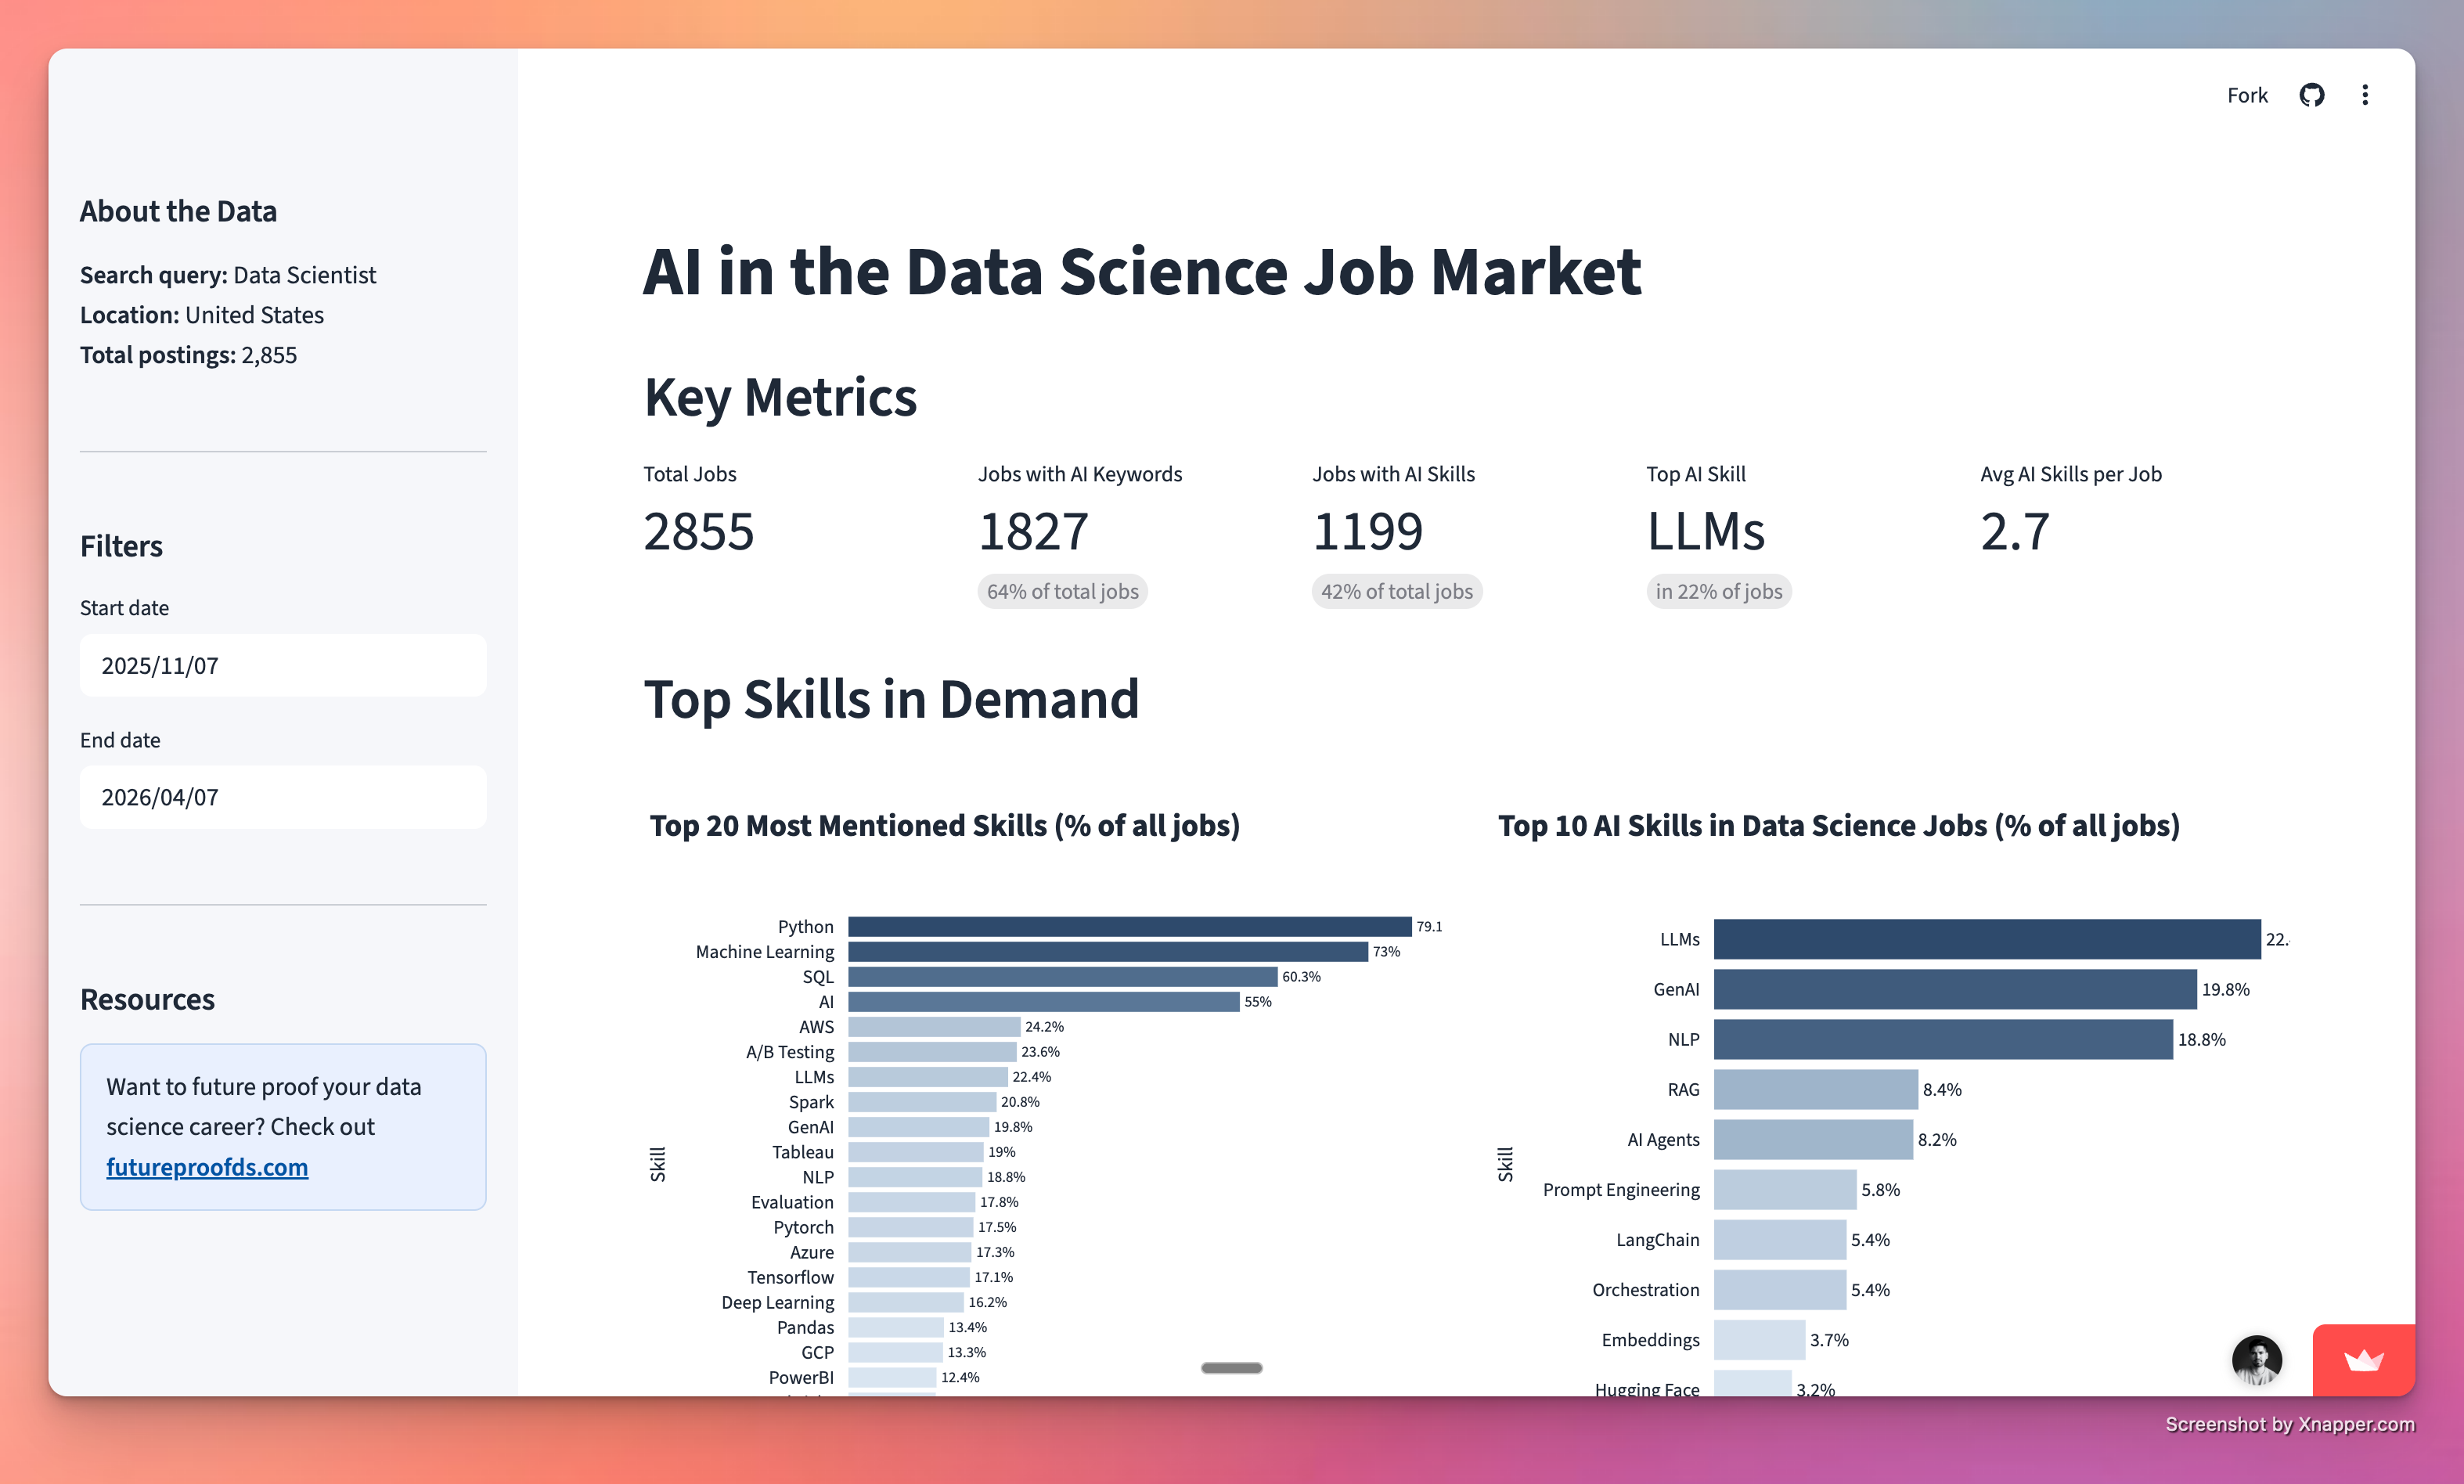
What skills do Data Scientists actually need right now? This dashboard answers that by extracting and categorizing skills from thousands of real job postings, with a focus on how AI is reshaping the role.
What You'll Find
- Top skills employers are hiring for: ranked by frequency across all postings
- Skills by category: Programming, Cloud, ML/DL, AI/GenAI, and more
- AI disruption analysis: what % of DS roles now require AI skills, which seniority levels are most affected, and the salary premium for AI-skilled candidates
- Interactive job explorer: browse individual postings with matched skills highlighted
Getting Started
Prerequisites
- Python 3.10+
- Poetry
Installation
git clone https://github.com/andresvourakis/ai-ds-job-market.git
cd ai-ds-job-market
make install
Running the Dashboard
make runOpens at http://localhost:8501.
Data
The dataset contains thousands of Data Science job postings collected via Google's Jobs API. Each posting includes title, company, location, full description, salary (when available), posting date, and schedule type.
The data file is included in the repo at data/jobs_merged.json.
How Skill Extraction Works
Job descriptions are matched against ~230 curated keyword groups in analyse_job_market.py. Each group maps variations of a skill to a canonical name (e.g., "PostgreSQL", "psql" → "SQL"). Both original and NLTK-lemmatized forms are matched to handle plurals and word variations.
Skills are organized into 10 categories:
| Category | Examples |
|---|---|
| Programming Languages | Python, R, SQL, Java, Scala |
| Data Storage & Databases | PostgreSQL, MongoDB, Snowflake, Redis |
| Data Processing & ETL | Spark, Kafka, Airflow, Databricks |
| Data Visualization | Tableau, Power BI, Looker, Plotly |
| ML/DL Frameworks | PyTorch, TensorFlow, Scikit-learn, XGBoost |
| Cloud Platforms | AWS, GCP, Azure |
| Development Tools | Git, Jupyter Notebook, Anaconda |
| DevOps & MLOps | Docker, Kubernetes, MLflow |
| Core Data Science | Machine Learning, A/B Testing, Feature Engineering |
| Artificial Intelligence | LLMs, GenAI, RAG, Prompt Engineering, LangChain |
Tech Stack
- Streamlit: Dashboard framework
- Pandas: Data manipulation
- Plotly: Interactive charts
- NLTK: Lemmatization for keyword matching
License
MIT - see LICENSE.