
Repository
WildDet3D
Allen Institute for AI: WildDet3D: Scaling Promptable 3D Detection in the Wild
- Mode
- Config
- Text
- configs/eval/in_the_wild/text.py
- Text + Depth
- configs/eval/in_the_wild/text_with_depth.py
- Box Prompt
- configs/eval/in_the_wild/box_prompt.py
Specs
- ModeConfig
- Textconfigs/eval/in_the_wild/text.py
- Text + Depthconfigs/eval/in_the_wild/text_with_depth.py
- Box Promptconfigs/eval/in_the_wild/box_prompt.py
- Box Prompt + Depthconfigs/eval/in_the_wild/box_prompt_with_depth.py
- ModeConfig
- Textconfigs/eval/stereo4d/text.py
- Text + Depthconfigs/eval/stereo4d/text_with_depth.py
- Box Promptconfigs/eval/stereo4d/box_prompt.py
- Box Prompt + Depthconfigs/eval/stereo4d/box_prompt_with_depth.py
- Text PromptText Prompt
- Box PromptBox Prompt
- Text PromptText Prompt
- Box PromptBox Prompt
README
 Watch the full demo video
# WildDet3D: Scaling Promptable 3D Detection in the Wild


Weikai Huang♥1,2 Jieyu Zhang♥1,2 Sijun Li2 Taoyang Jia2 Jiafei Duan1,2 Yunqian Cheng1 Jaemin Cho1,2 Matthew Wallingford1 Rustin Soraki1,2 Chris Dongjoo Kim1 Shuo Liu1,2 Donovan Clay1,2 Taira Anderson1 Winson Han1 Ali Farhadi1,2 Bharath Hariharan3 Zhongzheng Ren♥1,2,4 Ranjay Krishna♥1,2
♥ core contributors 1Allen Institute for AI 2University of Washington 3Cornell University 4UNC-Chapel Hill
Demo & Applications
<table>
<tr>
<td align="center">
<a href="demo/huggingface/README.md">
</a>
</td>
<td align="center">
<a href="demo/iphone/README.md">
</a>
</td>
</tr>
<tr>
<td align="center">
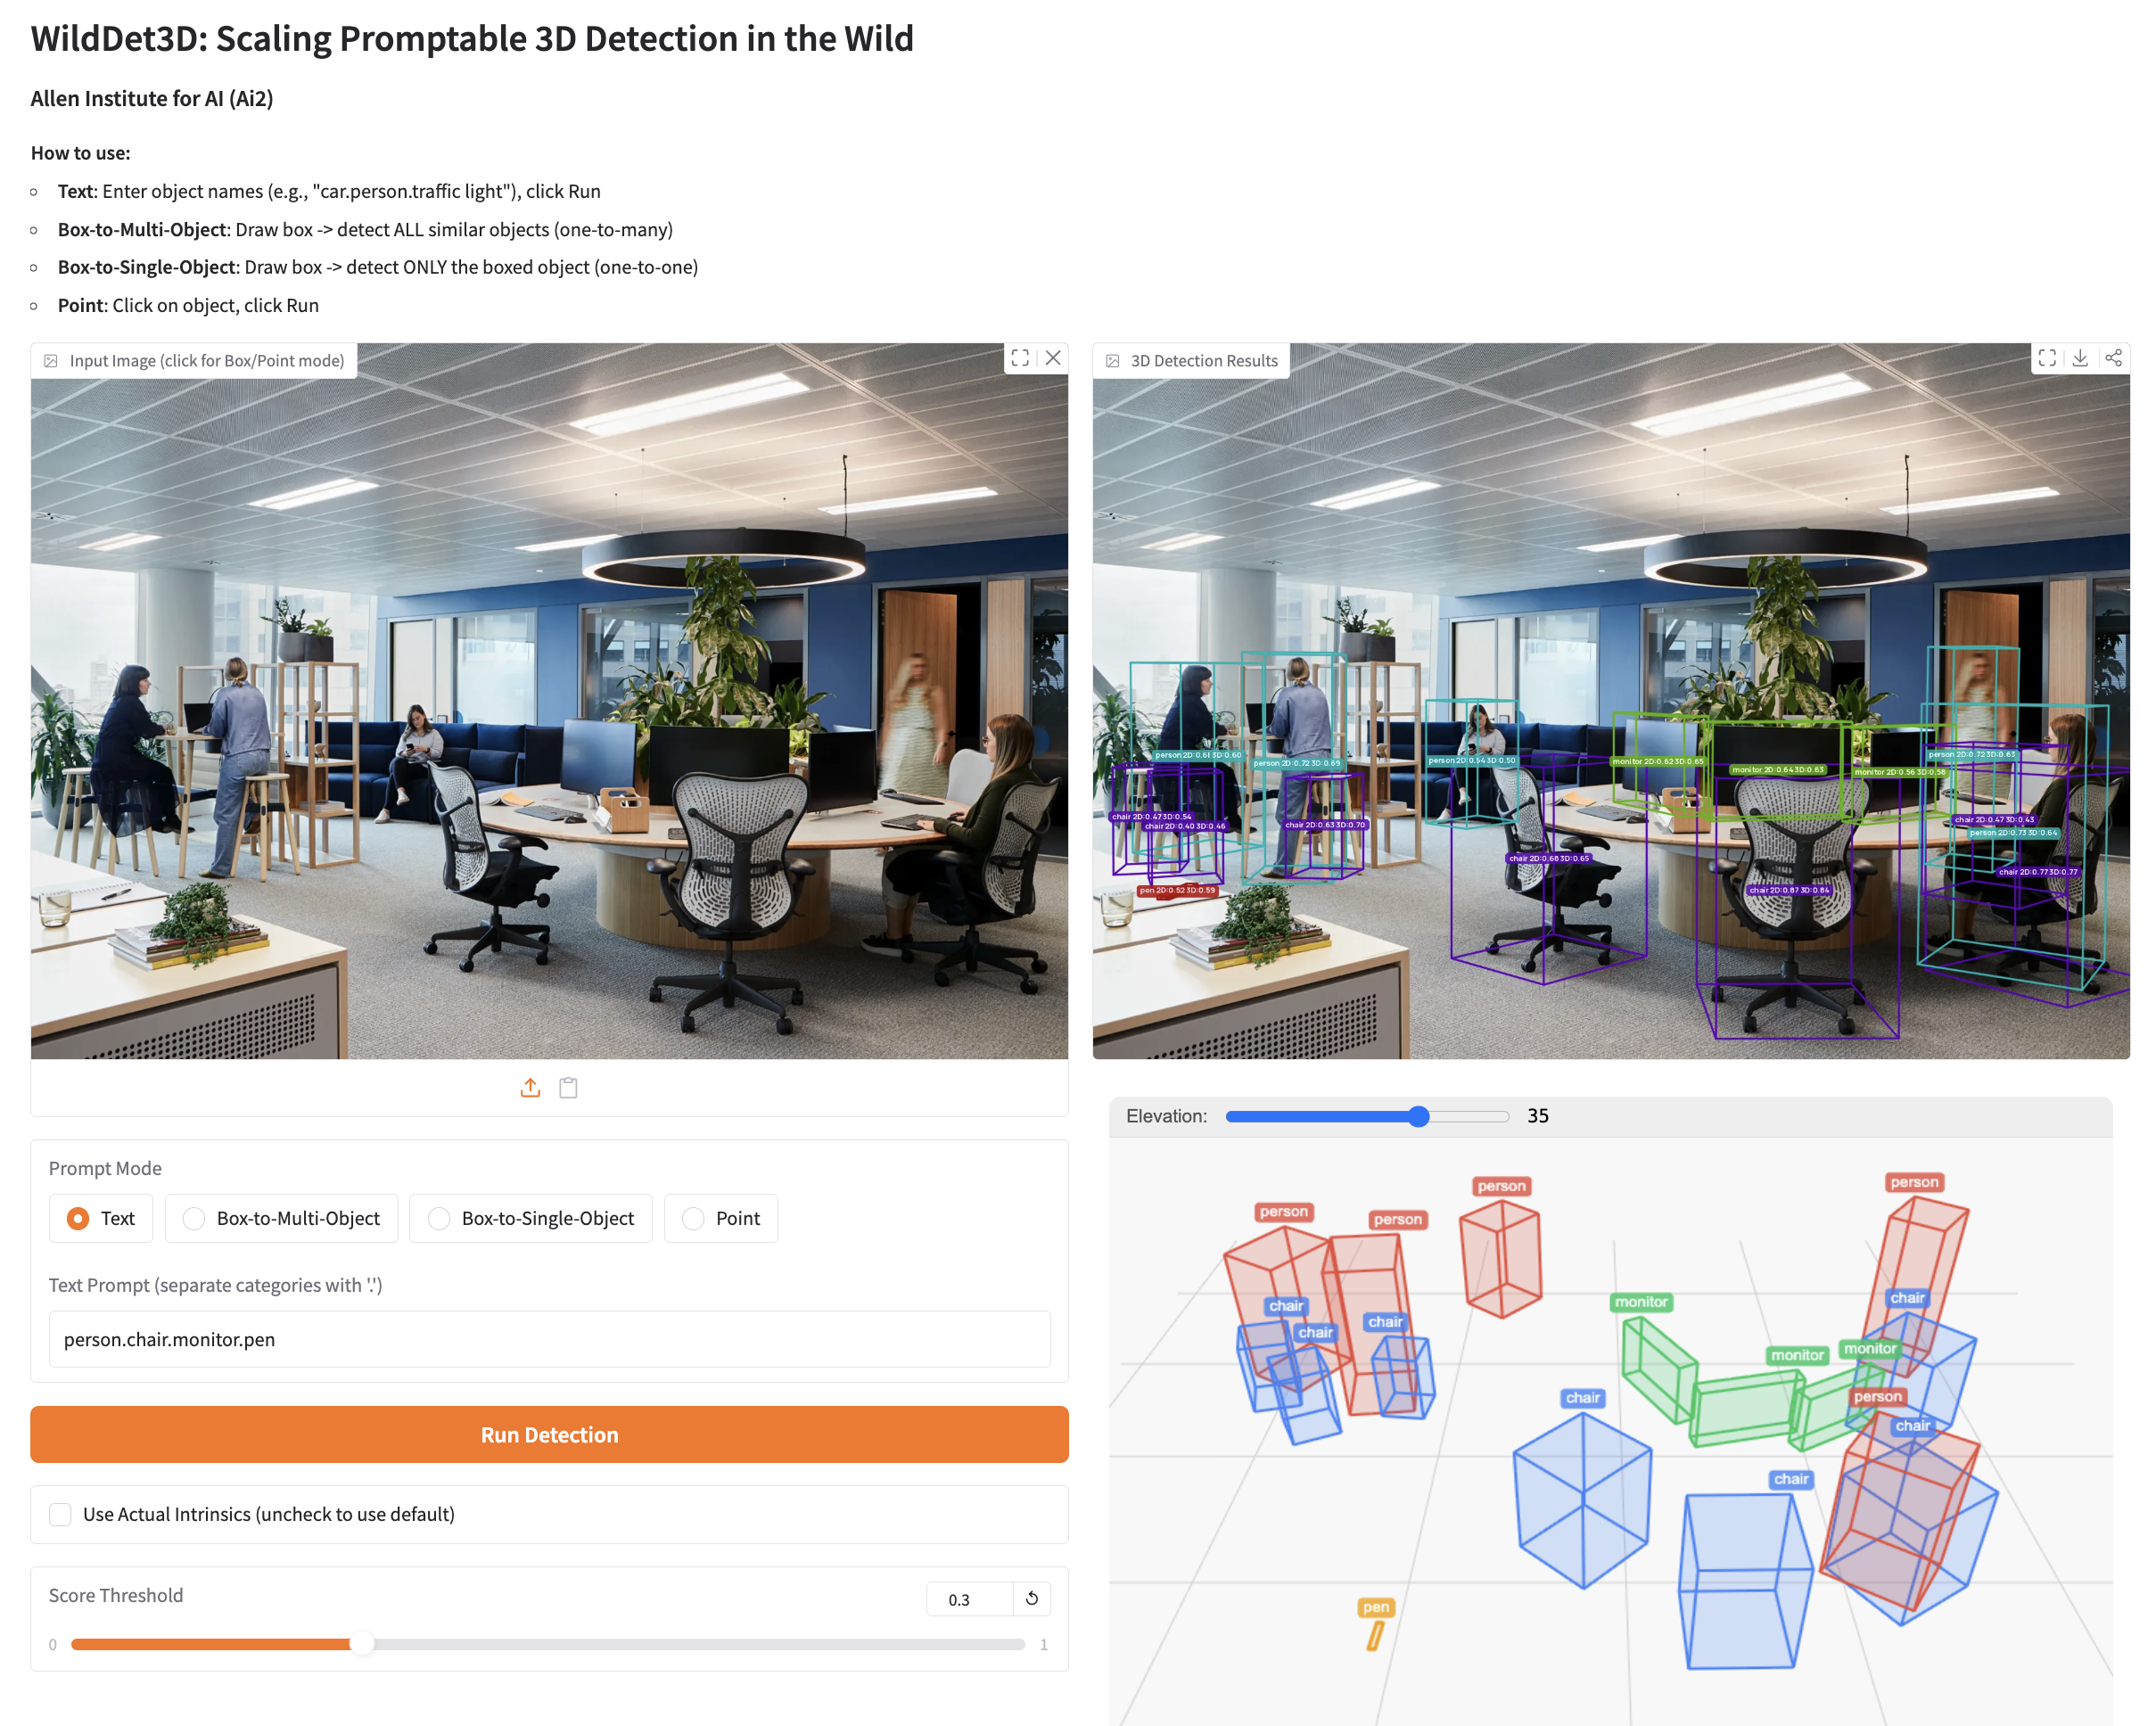
<b>HuggingFace Interactive Demo</b>
<br>Interactive web demo with text, point, and box prompts
<br><a href="https://huggingface.co/spaces/allenai/WildDet3D">Live Demo</a> | <a href="demo/huggingface/README.md">Run Locally</a>
</td>
<td align="center">
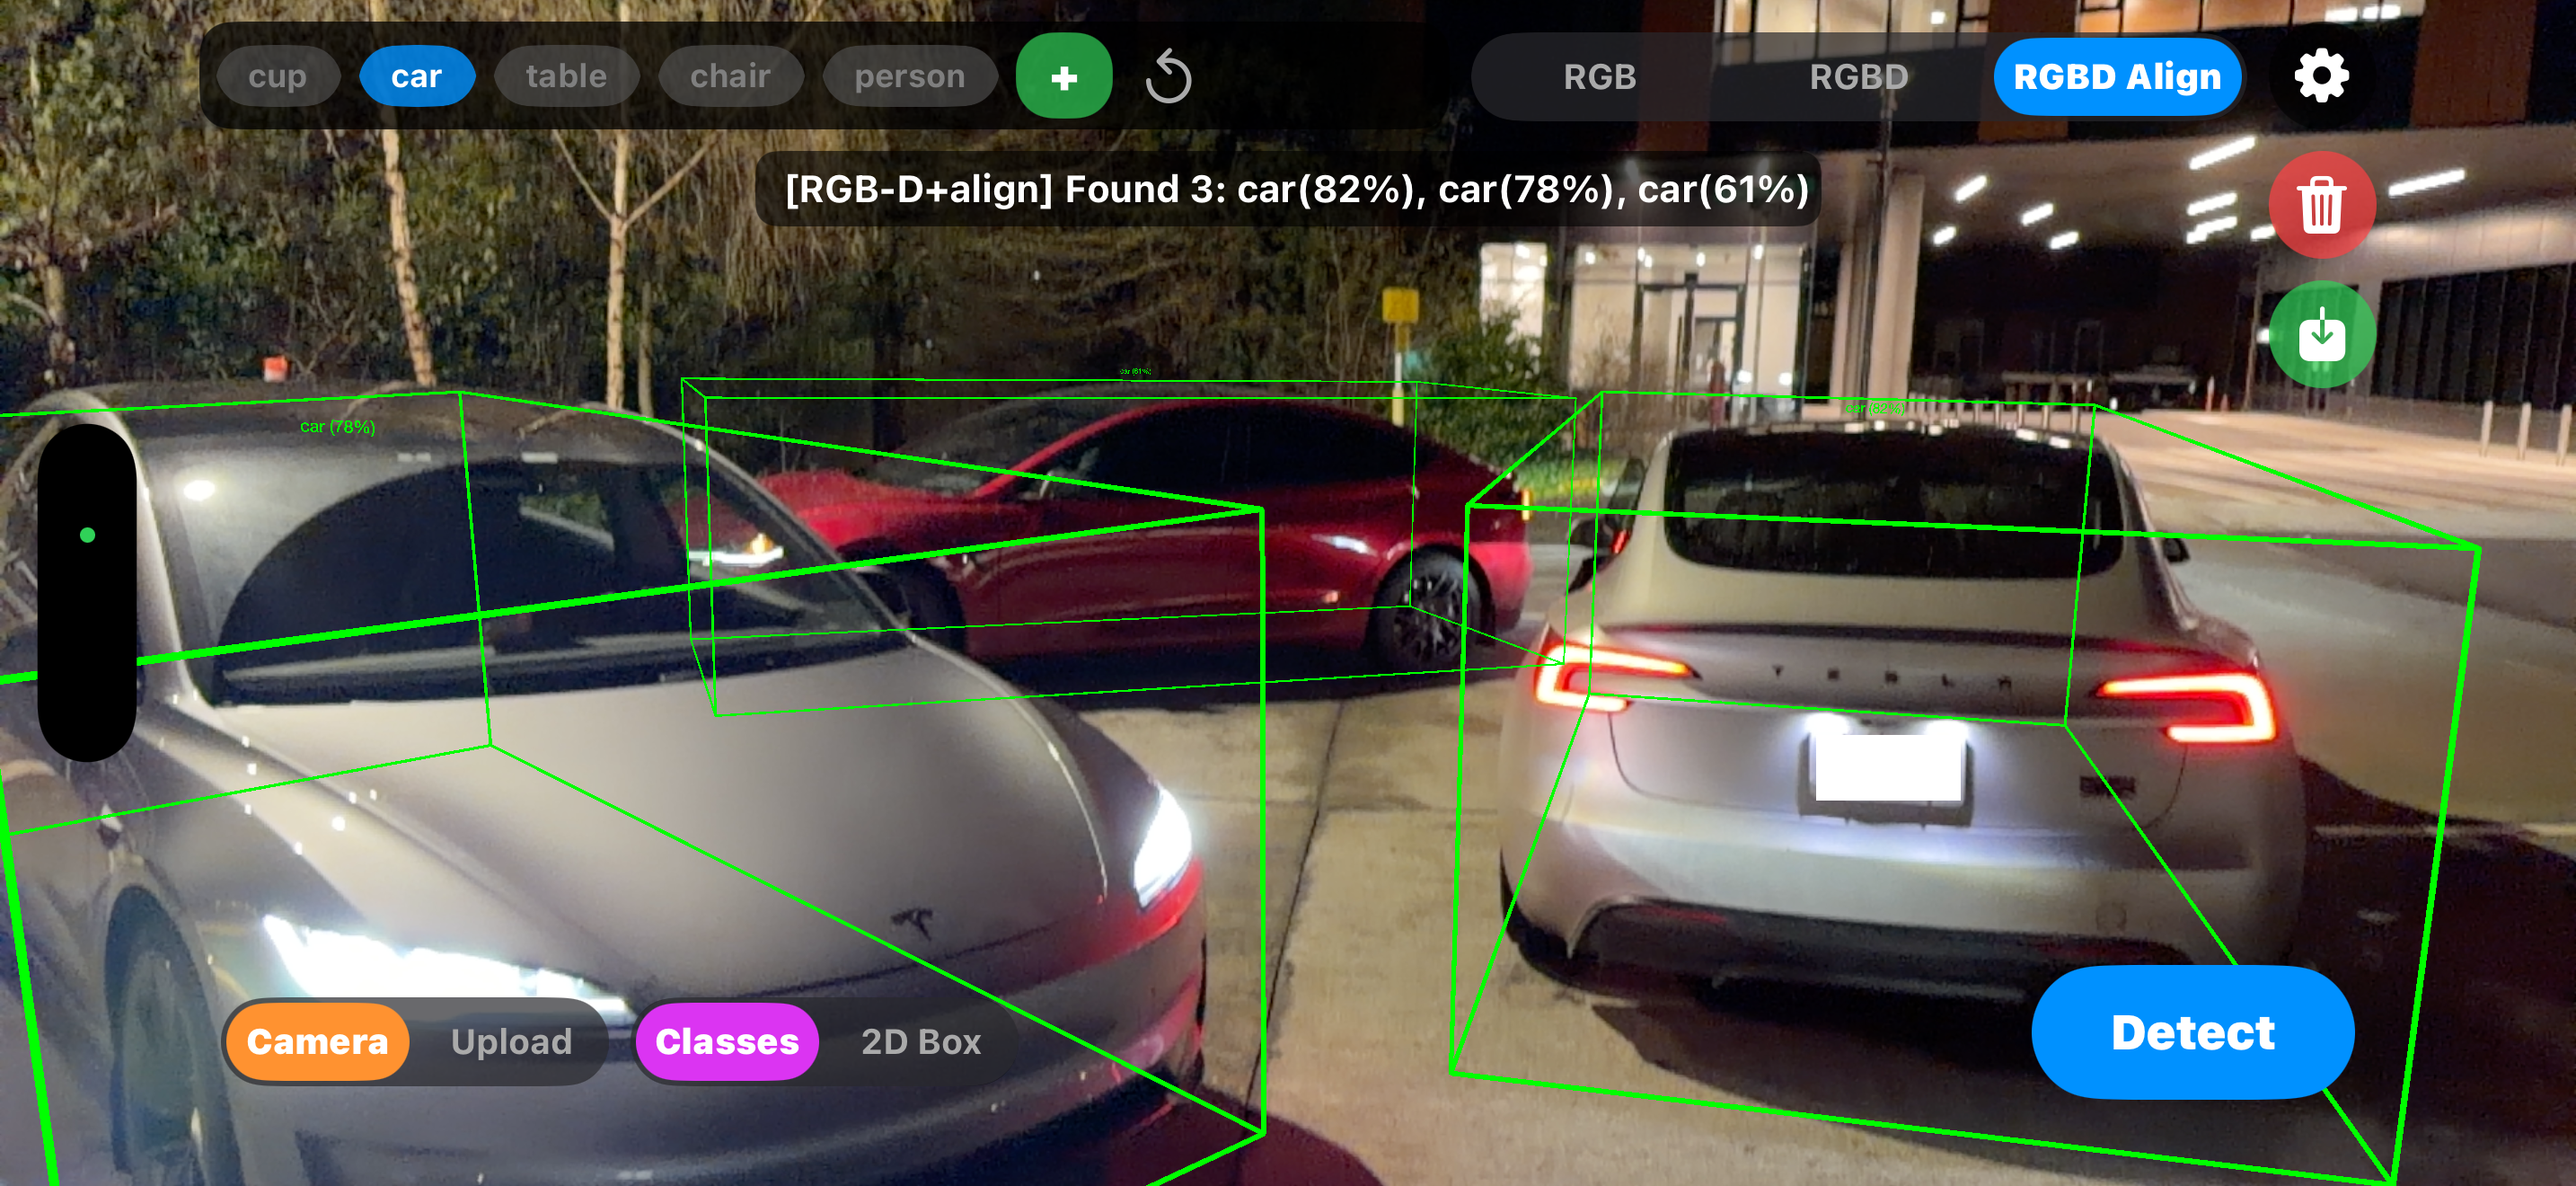
<b>iPhone App</b>
<br>Real-time on-device 3D detection
<br><a href="https://apps.apple.com/us/app/wilddet3d/id6760861157">App Store</a> | <a href="https://youtu.be/LJPNJ8jpOao">Video</a> | <a href="demo/iphone/README.md">README</a>
</td>
</tr>
<tr><td colspan="2"></td></tr>
<tr>
<td align="center">
<a href="demo/vlm/README.md">
</a>
</td>
<td align="center">
<a href="demo/tracking/README.md">
</a>
</td>
</tr>
<tr>
<td align="center">
<b>Integrate with VLM</b>
<br>Combine with vision-language models
<br><a href="demo/vlm/README.md">README</a>
</td>
<td align="center">
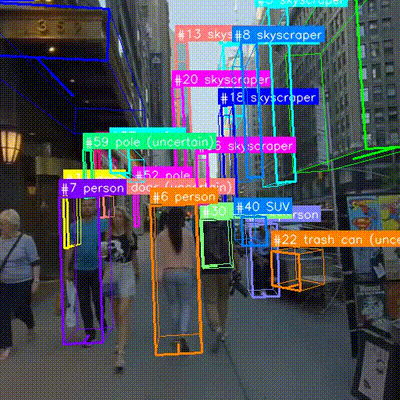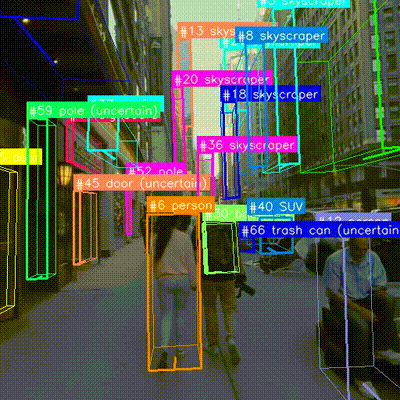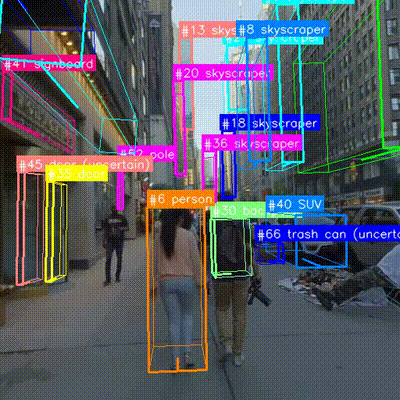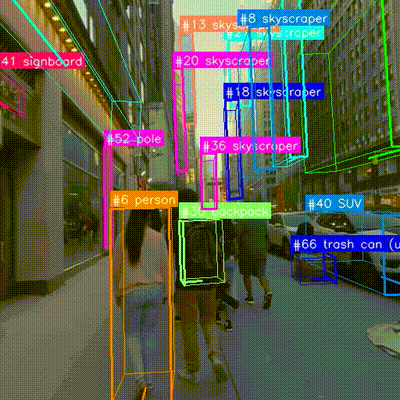
<b>Zero-Shot Tracking</b>
<br>3D object tracking without training
<br><a href="demo/tracking/README.md">README</a>
</td>
</tr>
<tr><td colspan="2"></td></tr>
<tr>
<td align="center">
<a href="demo/meta_quest/README.md">
</a>
</td>
<td align="center">
<a href="demo/robotics/README.md">
</a>
</td>
</tr>
<tr>
<td align="center">
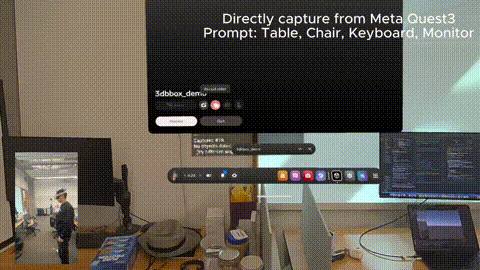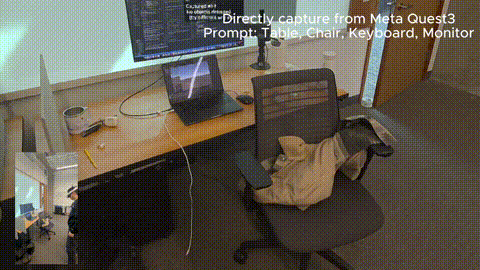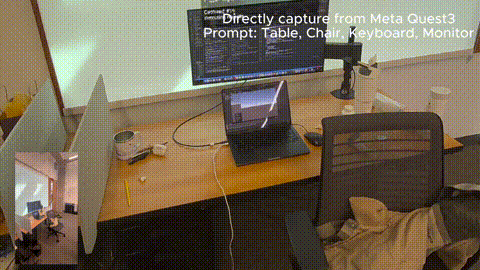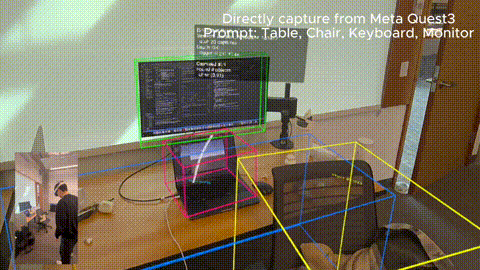
<b>Meta Quest</b>
<br>3D detection in AR/VR
<br><a href="assets/demo_meta_quest.mp4">Video</a>
</td>
<td align="center">
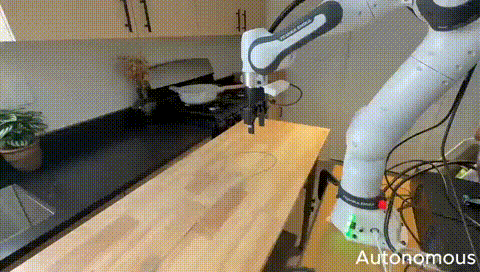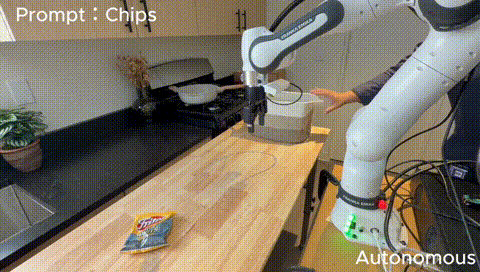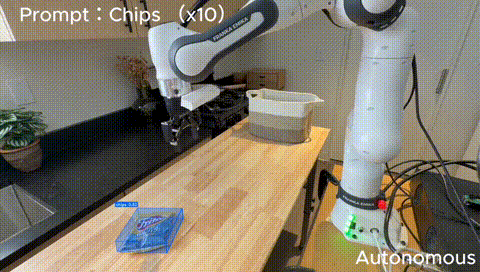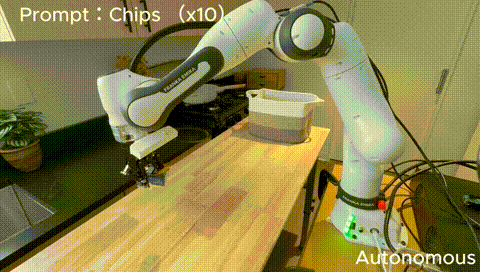
<b>Robotics</b>
<br>3D perception for robotic manipulation
<br><a href="assets/demo_robotics.mp4">Video</a>
</td>
</tr>
</table>
TODO
- [x] Release inference code
- [x] Release WildDet3D-Bench evaluation
- [x] Release training code
- [ ] Release evaluation on other benchmarks (Omni3D, Argoverse2, ScanNet)
Contents
- Demo & Applications
- Model Weights
- Installation
- Inference
- Evaluation
- Training
- Training Data Preparation → see docs/TRAINING_DATA.md
- Results
- WildDet3D Data
- Citation
Model Weights
| Model | Backbone | Depth Backend | Params | Download |
|---|---|---|---|---|
| WildDet3D | SAM3 ViT | LingBot-Depth (DINOv2 ViT-L/14) | ~1.2B | allenai/WildDet3D |
# Download checkpoint
pip install huggingface_hub
huggingface-cli download allenai/WildDet3D wilddet3d_alldata_all_prompt_v1.0.pt --local-dir ckpt/
Installation
git clone --recurse-submodules https://github.com/allenai/WildDet3D.git
cd WildDet3D
# If you forgot --recurse-submodules when cloning:
# git submodule update --init --recursive

# Training also needs MoGe (loss helpers used by the depth backend); clone it under third_party/:
# git clone https://github.com/microsoft/moge.git third_party/moge

conda create -n wilddet3d python=3.11 -y
conda activate wilddet3d

# 1. PyTorch (locked to the tested CUDA / version combination)
pip install torch==2.5.1 torchvision==0.20.1 --index-url https://download.pytorch.org/whl/cu121

# 2. vis4d (pinned to a known-good version; reuses the torch above)
pip install vis4d==1.0.0

# 3. vis4d CUDA ops (built from source, required by wilddet3d/ops)
pip install git+https://github.com/SysCV/vis4d_cuda_ops.git --no-build-isolation --no-cache-dir

# 4. Remaining dependencies (includes sam3's transitive deps;
#    sam3 itself is loaded from third_party/sam3 via sys.path injection
#    in wilddet3d/__init__.py, no separate install needed)
pip install -r requirements.txt
Inference
from wilddet3d import build_model, preprocess
from wilddet3d.vis.visualize import draw_3d_boxes
import numpy as np
from PIL import Image

# Build model
model = build_model(
    checkpoint="ckpt/wilddet3d_alldata_all_prompt_v1.0.pt",
    score_threshold=0.3,
    skip_pretrained=True,
    # Enable this ONLY if you will pass `depth_gt=...` to `model(...)`
    # (i.e. you preprocessed the image with `depth=`). Monocular callers
    # leave it off.
    # use_depth_input_test=True,
)

# Load and preprocess image
image = np.array(Image.open("image.jpg")).astype(np.float32)

# With known camera intrinsics
intrinsics = np.load("intrinsics.npy")  # (3, 3)
data = preprocess(image, intrinsics)

# Without intrinsics (uses default: focal=max(H,W), principal point at center)
# data = preprocess(image)

# With a known depth map (e.g., from LiDAR or stereo), pass it through
# the same preprocess. Depth must be (H, W) float32 in meters at the
# original image resolution; preprocess resizes + center-pads it to
# match the model's input_hw (same transforms eval uses).
#   depth = np.load("depth.npy")  # (H, W) float32, meters
#   data = preprocess(image, intrinsics, depth=depth)
# Omit `depth` (or pass None) to let the model use its monocular
# LingBot-Depth prediction instead. When depth is provided, also pass
# `depth_gt=data["depth_gt"].cuda()` to each model(...) call below.

# Text prompt: detect all instances of given categories
results = model(
    images=data["images"].cuda(),
    intrinsics=data["intrinsics"].cuda()[None],
    input_hw=[data["input_hw"]],
    original_hw=[data["original_hw"]],
    padding=[data["padding"]],
    input_texts=["car", "person", "bicycle"],
    # depth_gt=data["depth_gt"].cuda(),  # include only if preprocess was called with depth=...
)
boxes, boxes3d, scores, scores_2d, scores_3d, class_ids, depth_maps = results

# Box prompt (geometric): lift a 2D box to 3D (one-to-one)
results = model(
    images=data["images"].cuda(),
    intrinsics=data["intrinsics"].cuda()[None],
    input_hw=[data["input_hw"]],
    original_hw=[data["original_hw"]],
    padding=[data["padding"]],
    input_boxes=[[100, 200, 300, 400]],  # pixel xyxy
    prompt_text="geometric",
    # depth_gt=data["depth_gt"].cuda(),  # include only if preprocess was called with depth=...
)

# Exemplar prompt: use a 2D box as visual exemplar, find all similar objects (one-to-many)
results = model(
    images=data["images"].cuda(),
    intrinsics=data["intrinsics"].cuda()[None],
    input_hw=[data["input_hw"]],
    original_hw=[data["original_hw"]],
    padding=[data["padding"]],
    input_boxes=[[100, 200, 300, 400]],
    prompt_text="visual",
    # depth_gt=data["depth_gt"].cuda(),  # include only if preprocess was called with depth=...
)

# Point prompt
results = model(
    images=data["images"].cuda(),
    intrinsics=data["intrinsics"].cuda()[None],
    input_hw=[data["input_hw"]],
    original_hw=[data["original_hw"]],
    padding=[data["padding"]],
    input_points=[[(150, 250, 1), (200, 300, 0)]],  # (x, y, label): 1=positive, 0=negative
    prompt_text="geometric",
    # depth_gt=data["depth_gt"].cuda(),  # include only if preprocess was called with depth=...
)

# Visualize results
boxes, boxes3d, scores, scores_2d, scores_3d, class_ids, depth_maps = results
draw_3d_boxes(
    image=image.astype(np.uint8),
    boxes3d=boxes3d[0],
    intrinsics=intrinsics,
    scores_2d=scores_2d[0],
    scores_3d=scores_3d[0],
    class_ids=class_ids[0],
    class_names=["car", "person", "bicycle"],
    save_path="output.png",
    # Optional debug overlays (both default off):
    #   predicted 2D boxes (green):
    # boxes_2d=boxes[0],
    # draw_predicted_2d_boxes=True,
    #   user prompt boxes (red) / points (red pos, gray neg):
    # input_boxes=[[100, 200, 300, 400]],
    # input_points=[[(150, 250, 1)]],
    # draw_prompt=True,
)
Notes:
- If
intrinsicsis not provided, a default intrinsic matrix is used (focal=max(H,W), principal point at image center). - Optional depth input: pass
depth_gt=depth_tensor(shape(B, 1, H, W), meters) for improved 3D localization with sparse/dense depth (e.g., LiDAR).
See docs/INFERENCE.md for the full API reference.
Evaluation
WildDet3D-Bench
Download the evaluation data from allenai/WildDet3D-Data (including InTheWild_v3_val.json which the eval configs expect at data/in_the_wild/annotations/). Evaluate using the vis4d framework:
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH

# Text prompt
vis4d test --config configs/eval/in_the_wild/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Text prompt + GT depth
vis4d test --config configs/eval/in_the_wild/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Box prompt (oracle)
vis4d test --config configs/eval/in_the_wild/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Box prompt + GT depth
vis4d test --config configs/eval/in_the_wild/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt| Mode | Config |
|---|---|
| Text | configs/eval/in_the_wild/text.py |
| Text + Depth | configs/eval/in_the_wild/text_with_depth.py |
| Box Prompt | configs/eval/in_the_wild/box_prompt.py |
| Box Prompt + Depth | configs/eval/in_the_wild/box_prompt_with_depth.py |
WildDet3D-Stereo4D-Bench
Download the evaluation data from allenai/WildDet3D-Stereo4D-Bench-Images (including Stereo4D_val.json / Stereo4D_test.json -> data/in_the_wild/annotations/). Evaluate (383 images with real stereo depth):
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH

# Text prompt
vis4d test --config configs/eval/stereo4d/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Text prompt + GT depth
vis4d test --config configs/eval/stereo4d/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Box prompt (oracle)
vis4d test --config configs/eval/stereo4d/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt

# Box prompt + GT depth
vis4d test --config configs/eval/stereo4d/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt| Mode | Config |
|---|---|
| Text | configs/eval/stereo4d/text.py |
| Text + Depth | configs/eval/stereo4d/text_with_depth.py |
| Box Prompt | configs/eval/stereo4d/box_prompt.py |
| Box Prompt + Depth | configs/eval/stereo4d/box_prompt_with_depth.py |
Training
WildDet3D is trained in 3 stages. Each stage uses vis4d fit:
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH

# Stage 1 (12 ep): Omni3D canonical pretraining
vis4d fit --config configs/training/stage1_omni3d.py --gpus 8

# Stage 2 (12 ep): all-data dense fine-tuning (Omni3D + CA1M + Waymo + 3EED + FoundationPose + ITW-human + V3Det-human), 5-mode collator (no mask)
vis4d fit --config configs/training/stage2_alldata.py --gpus 8

# Stage 3 (3 ep): high-quality human-reviewed fine-tuning on a mix of box / point / text prompts
vis4d fit --config configs/training/stage3_mix_box_point_text_ft.py --gpus 8
Multi-node: add --num_nodes N. Batch size defaults to 4 samples/GPU (global batch 128 at 8 GPUs × 4 nodes).
Training Data Preparation
See docs/TRAINING_DATA.md for per-dataset download + convert + HDF5-pack instructions (Omni3D, CA1M, Waymo v2, 3EED, FoundationPose, ITW, Stereo4D, mask annotations, pretrained checkpoints). All frame-extraction scripts under scripts/data_prep/ are deterministic, so following the doc reproduces our exact train/val splits.
Results
WildDet3D-Bench (In-the-Wild)
AP is computed using center-distance matching. AP_r, AP_c, AP_f denote rare (<5), common (5-20), and frequent (>20) category splits.
| Method | Data | AP_r | AP_c | AP_f | AP |
|---|---|---|---|---|---|
| Text Prompt | |||||
| 3D-MOOD | Omni3D | 2.4 | 2.1 | 2.6 | 2.3 |
| WildDet3D | Omni3D | 9.0 | 6.5 | 5.2 | 6.8 |
| WildDet3D w/ depth | Omni3D | 23.0 | 21.5 | 16.1 | 20.7 |
| WildDet3D | Omni3D, Others, WildDet3D-Data | 28.3 | 21.6 | 18.7 | 22.6 |
| WildDet3D w/ depth | Omni3D, Others, WildDet3D-Data | 47.4 | 40.7 | 37.2 | 41.6 |
| Box Prompt | |||||
| OVMono3D-LIFT | Omni3D | 7.4 | 8.8 | 5.1 | 7.7 |
| DetAny3D | Omni3D, Others | 9.9 | 7.4 | 6.3 | 7.8 |
| WildDet3D | Omni3D | 12.0 | 7.9 | 5.3 | 8.4 |
| WildDet3D w/ depth | Omni3D | 26.4 | 24.4 | 19.6 | 23.9 |
| WildDet3D | Omni3D, Others, WildDet3D-Data | 30.0 | 24.2 | 20.3 | 24.8 |
| WildDet3D w/ depth | Omni3D, Others, WildDet3D-Data | 53.7 | 46.1 | 42.5 | 47.2 |
Omni3D
AP is computed at 3D IoU [0.5:0.95].
| Method | KITTI | nuScenes | SUNRGBD | Hypersim | ARKitScenes | Objectron | AP |
|---|---|---|---|---|---|---|---|
| Text Prompt | |||||||
| Cube R-CNN | 32.6 | 30.1 | 15.3 | 7.5 | 41.7 | 50.8 | 23.3 |
| 3D-MOOD Swin-T | 32.8 | 31.5 | 21.9 | 10.5 | 51.0 | 64.3 | 28.4 |
| 3D-MOOD Swin-B | 31.4 | 35.8 | 23.8 | 9.1 | 53.9 | 67.9 | 30.0 |
| WildDet3D | 37.0 | 31.7 | 38.9 | 16.5 | 64.6 | 60.5 | 34.2 |
| WildDet3D w/ depth | 36.1 | 32.0 | 51.1 | 26.6 | 73.3 | 68.3 | 41.6 |
| Box Prompt | |||||||
| OVMono3D-LIFT | 31.4 | 32.5 | 23.2 | 11.9 | 54.2 | 63.5 | 29.6 |
| DetAny3D | 38.7 | 37.6 | 46.1 | 16.0 | 50.6 | 56.8 | 34.4 |
| WildDet3D | 44.3 | 35.3 | 43.1 | 17.3 | 66.6 | 60.8 | 36.4 |
| WildDet3D w/ depth | 42.8 | 35.9 | 58.7 | 30.4 | 76.6 | 68.5 | 45.8 |
Qualitative Results
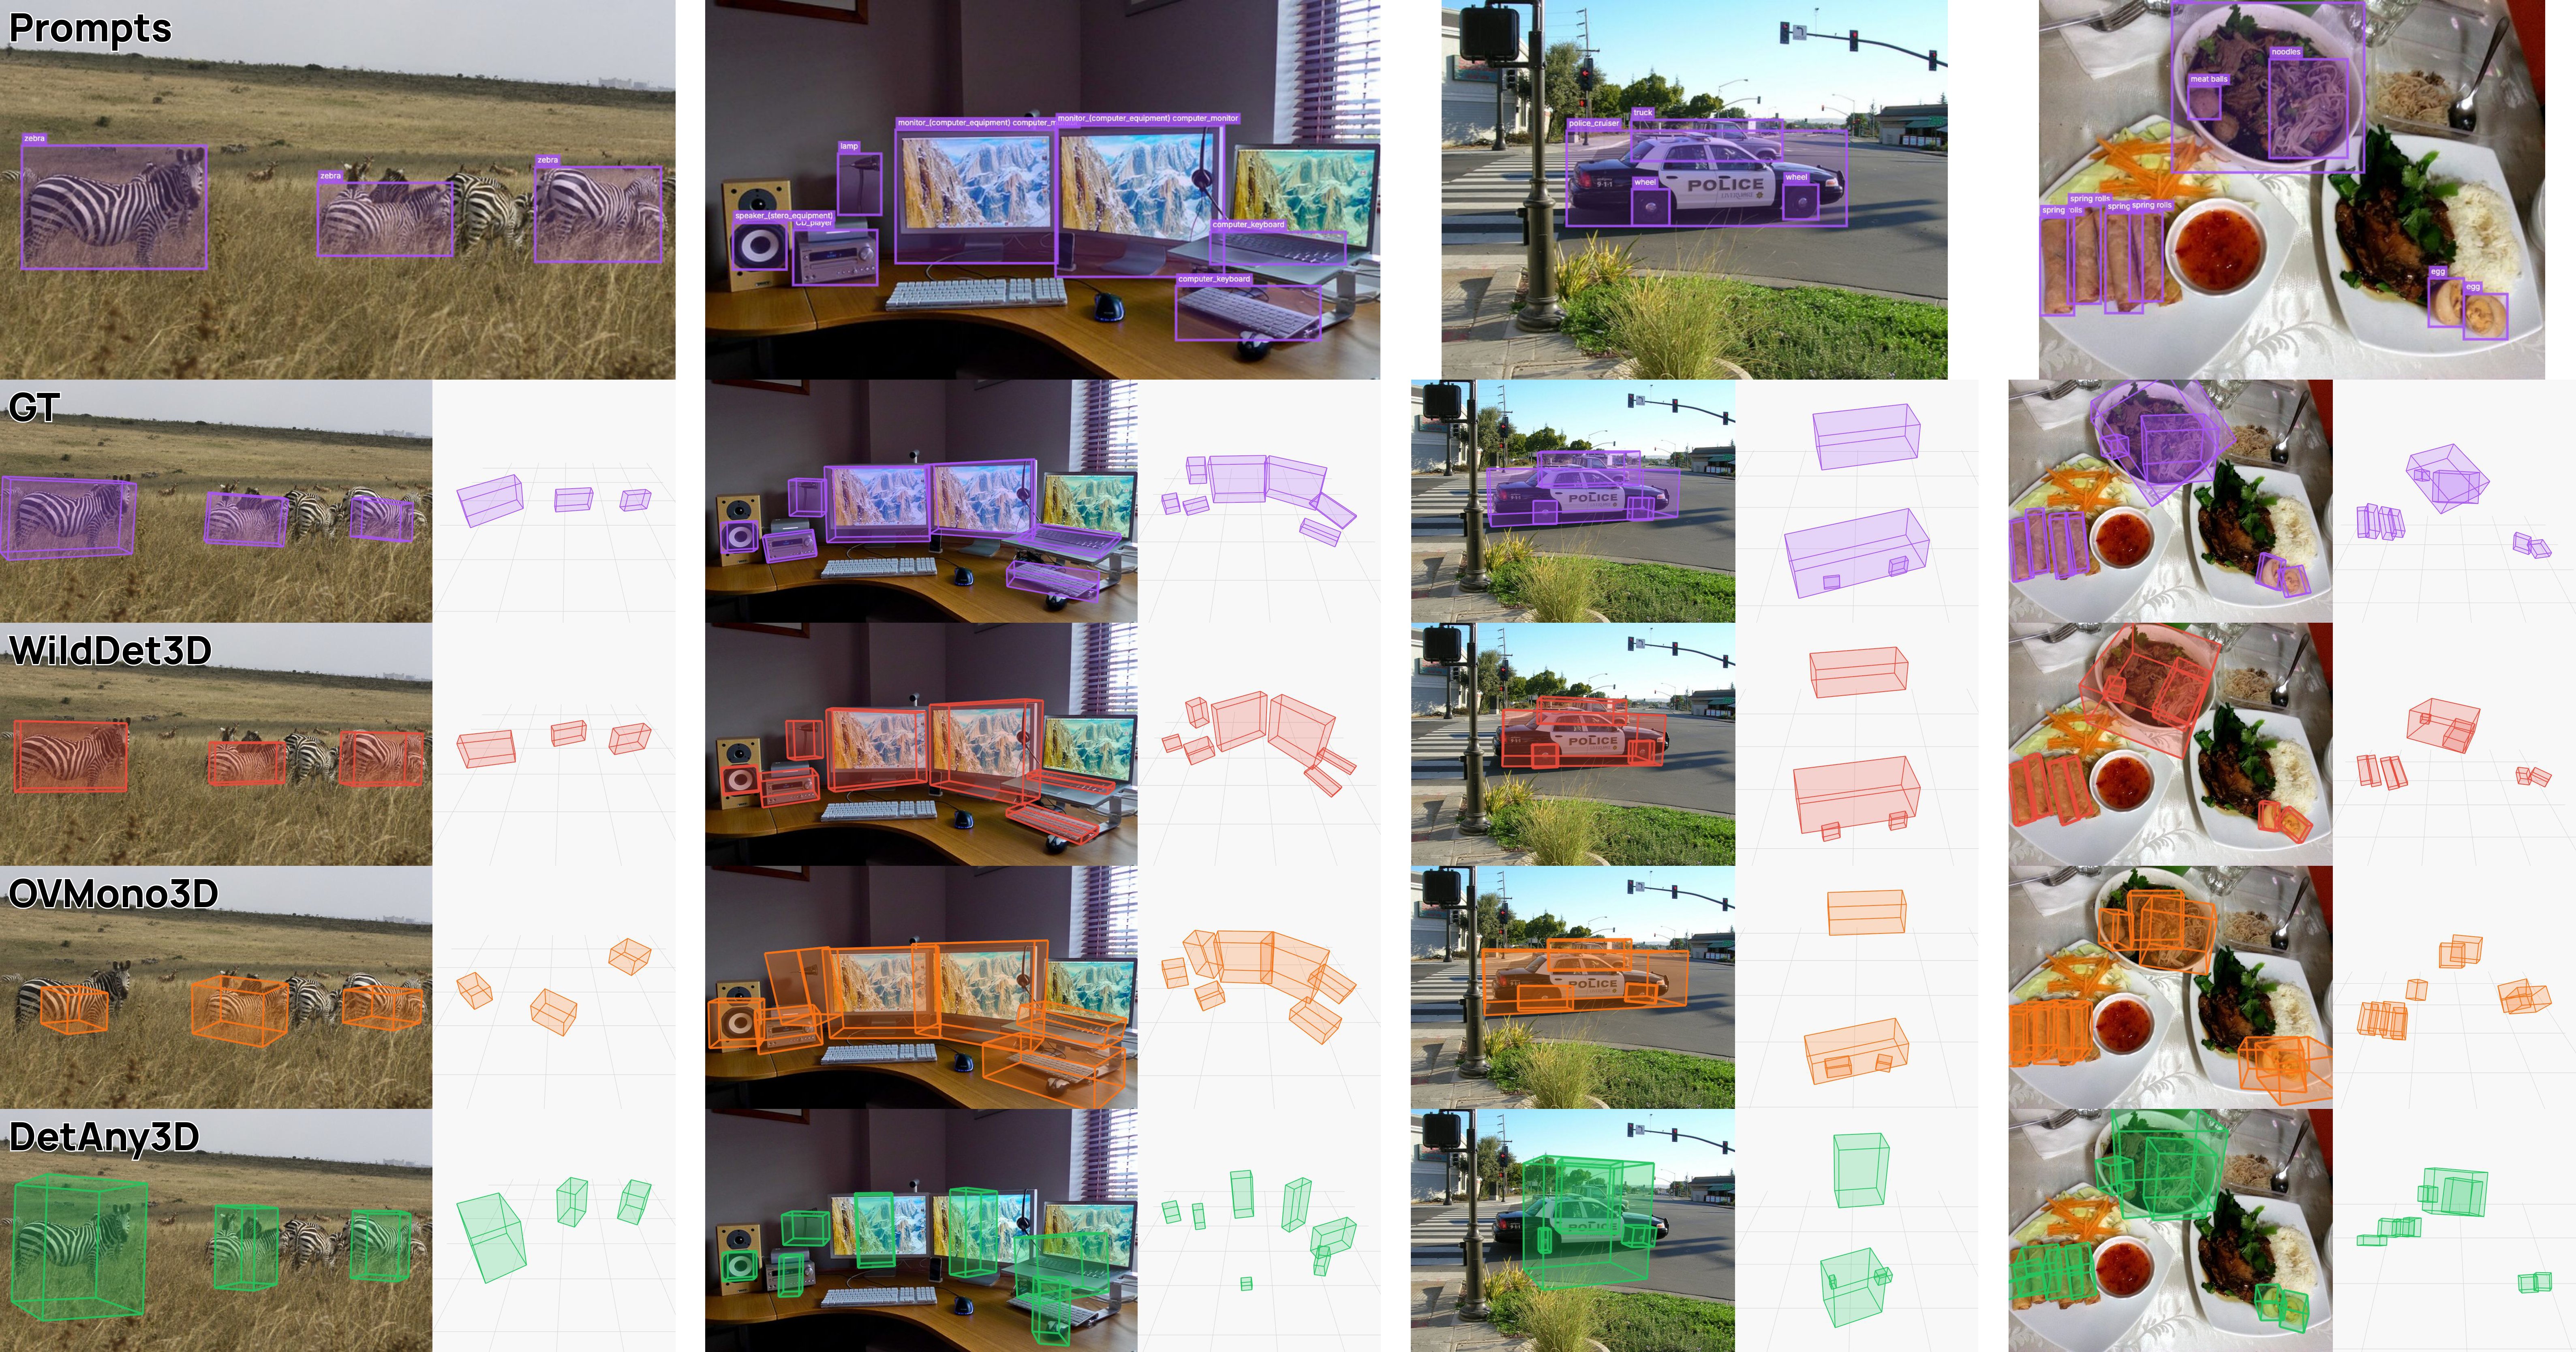
Box prompt comparison (WildDet3D vs OVMono3D vs DetAny3D):
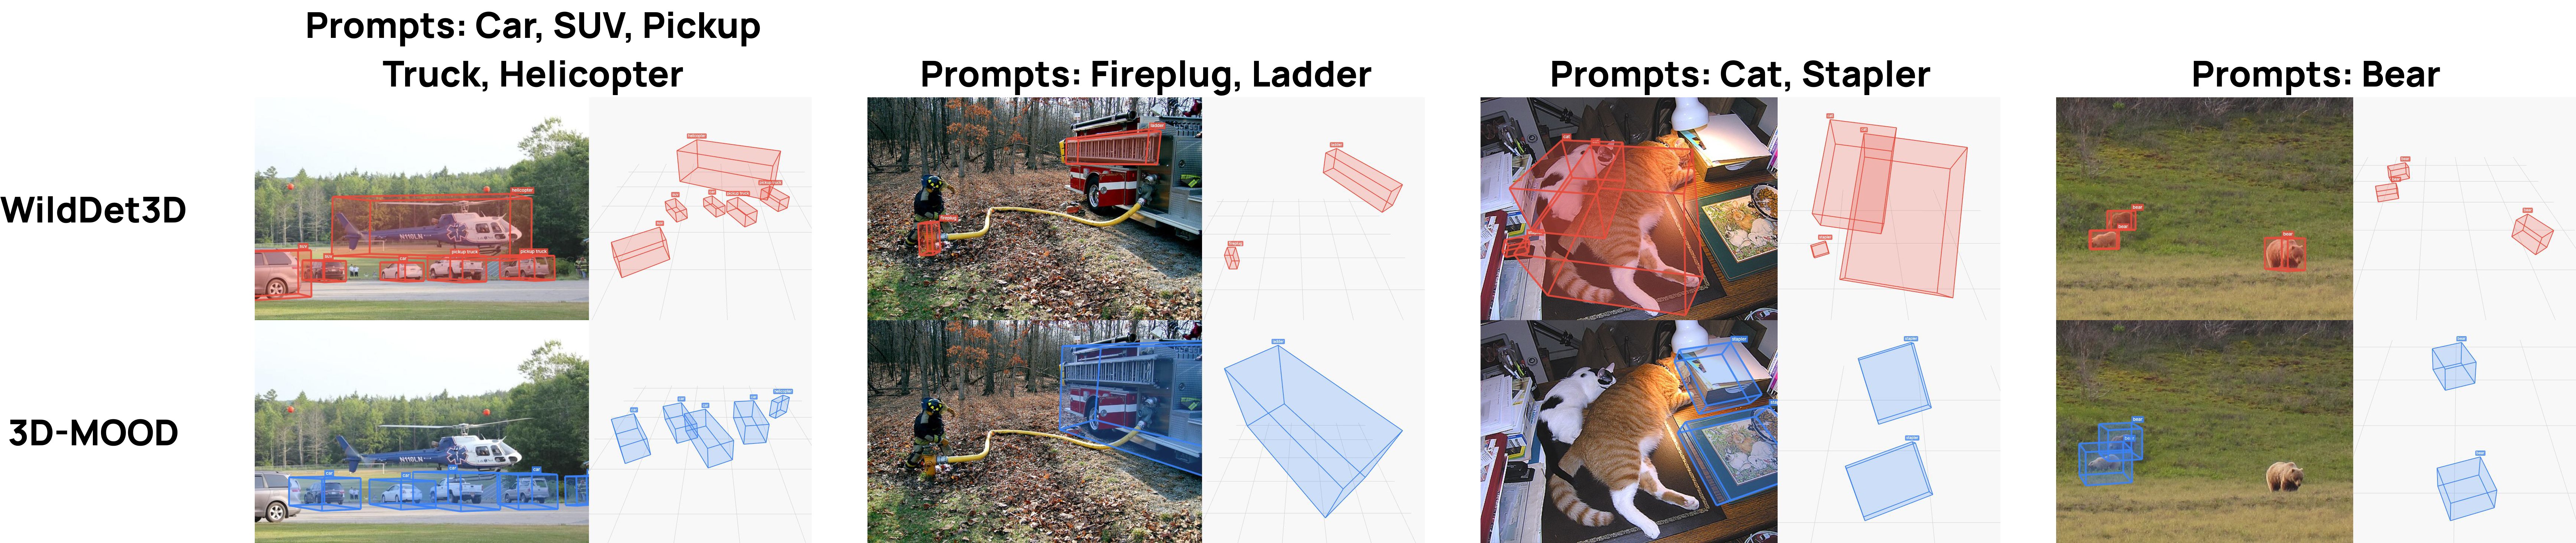
Text prompt comparison:
WildDet3D Data
We introduce WildDet3D-Data, a large-scale in-the-wild dataset for monocular 3D detection with human-verified 3D bounding box annotations. The dataset covers images from COCO, LVIS, Objects365, and V3Det.
| Split | Description | Images | Annotations | Categories |
|---|---|---|---|---|
| Val | Validation set (human) | 2,470 | 9,256 | 785 |
| Test | Test set (human) | 2,433 | 5,596 | 633 |
| Train (Human) | Human-reviewed only | 102,979 | 229,934 | 11,879 |
| Train (Essential) | Human + VLM-qualified small objects | 102,979 | 412,711 | 12,064 |
| Train (Synthetic) | VLM auto-selected | 896,004 | 3,483,292 | 11,896 |
| Total | 1,003,886 | 3,910,855 | 13,499 |
The dataset is hosted on HuggingFace: allenai/WildDet3D-Data. See the dataset README for download instructions and data format.
Citation
If you find this work useful, please cite:
@misc{huang2026wilddet3dscalingpromptable3d,
      title={WildDet3D: Scaling Promptable 3D Detection in the Wild},
      author={Weikai Huang and Jieyu Zhang and Sijun Li and Taoyang Jia and Jiafei Duan and Yunqian Cheng and Jaemin Cho and Mattew Wallingford and Rustin Soraki and Chris Dongjoo Kim and Donovan Clay and Taira Anderson and Winson Han and Ali Farhadi and Bharath Hariharan and Zhongzheng Ren and Ranjay Krishna},
      year={2026},
      eprint={2604.08626},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2604.08626},
}
Acknowledgements
- Omni3D -- 3D detection benchmarks and baselines
- vis4d -- Training and evaluation framework
- SAM 3 -- Segment Anything Model 3
- LingBot-Depth -- Monocular depth estimation
- 3D-MOOD -- Open-vocabulary monocular 3D detection
- DetAny3D -- Detect anything in 3D
- OVMono3D -- Open-vocabulary monocular 3D detection
- LabelAny3D -- 3D bounding box annotation tool
License
Codebase: This codebase incorporates code from SAM 3, and is licensed under the SAM License. It is intended for research and educational use in accordance with Ai2's Responsible Use Guidelines.
Model: This model is based on SAM 3 and LingBot-Depth, and is licensed under the SAM License. This model is intended for research and educational use in accordance with Ai2's Responsible Use Guidelines.