

README
Video-IFBench: Evaluating Instruction Following of Multimodal LLMs in Video Understanding Scenarios
Hongbo Liu1,*, Peixian Chen2,*, Sihan Liu2, Peiyuan Zhang3, Kai Zou4, Dian Zheng5, Xiaoxing Hu3, Yuhao Dong6, Mengdan Zhang2, Yunhang Shen2, Haoyu Cao2, Wei Liu2, Weibo Gu2, Xing Sun2, Shengjie Zhao1,†
1TJU 2Tencent Youtu Lab 3SJTU 4Tencent Hunyuan 5CUHK 6NTU
* Equal contribution † Corresponding author

🚀 Getting Started
Installation
git clone https://github.com/Alexios-hub/Video-IFBench.git
cd Video-IFBench
pip install -e .
Dataset Preparation
Download the evaluation split from Hugging Face:
huggingface-cli download Alexislhb/Video-IFBench \
  --repo-type dataset \
  --local-dir data/Video-IFBench
The runner expects the following layout:
data/Video-IFBench/
├── annotations/
│   └── annotations.jsonl
├── videos/
│   └── <video files>
└── subtitles/                 # optional timestamped ASR files
    └── <subtitle files>
Use this directory as --dataset-root when running inference.
Run Inference
The runner supports OpenAI-compatible endpoints, including OpenAI-style APIs, vLLM, SGLang, and other compatible servers.
video-ifbench-run \
  --dataset-root data/Video-IFBench \
  --output-dir outputs/model_name \
  --api-base http://localhost:8000/v1 \
  --model model_name \
  --media-mode video-url \
  --concurrency 32 \
  --resume
Each output file is a *.response.json record containing the model response and the metadata required for scoring.
Add --use-asr to use timestamped ASR.
Score Responses
video-ifbench-score \
  --response-dir outputs/model_name \
  --output-json outputs/model_name/_instruction_following_report.json \
  --judge-api-base http://localhost:8001/v1 \
  --judge-model judge_model_name \
  --concurrency 16
Summarize Metrics
video-ifbench-summarize \
  --report outputs/model_name/_instruction_following_report.json \
  --model-name "model_name" \
  --format latex
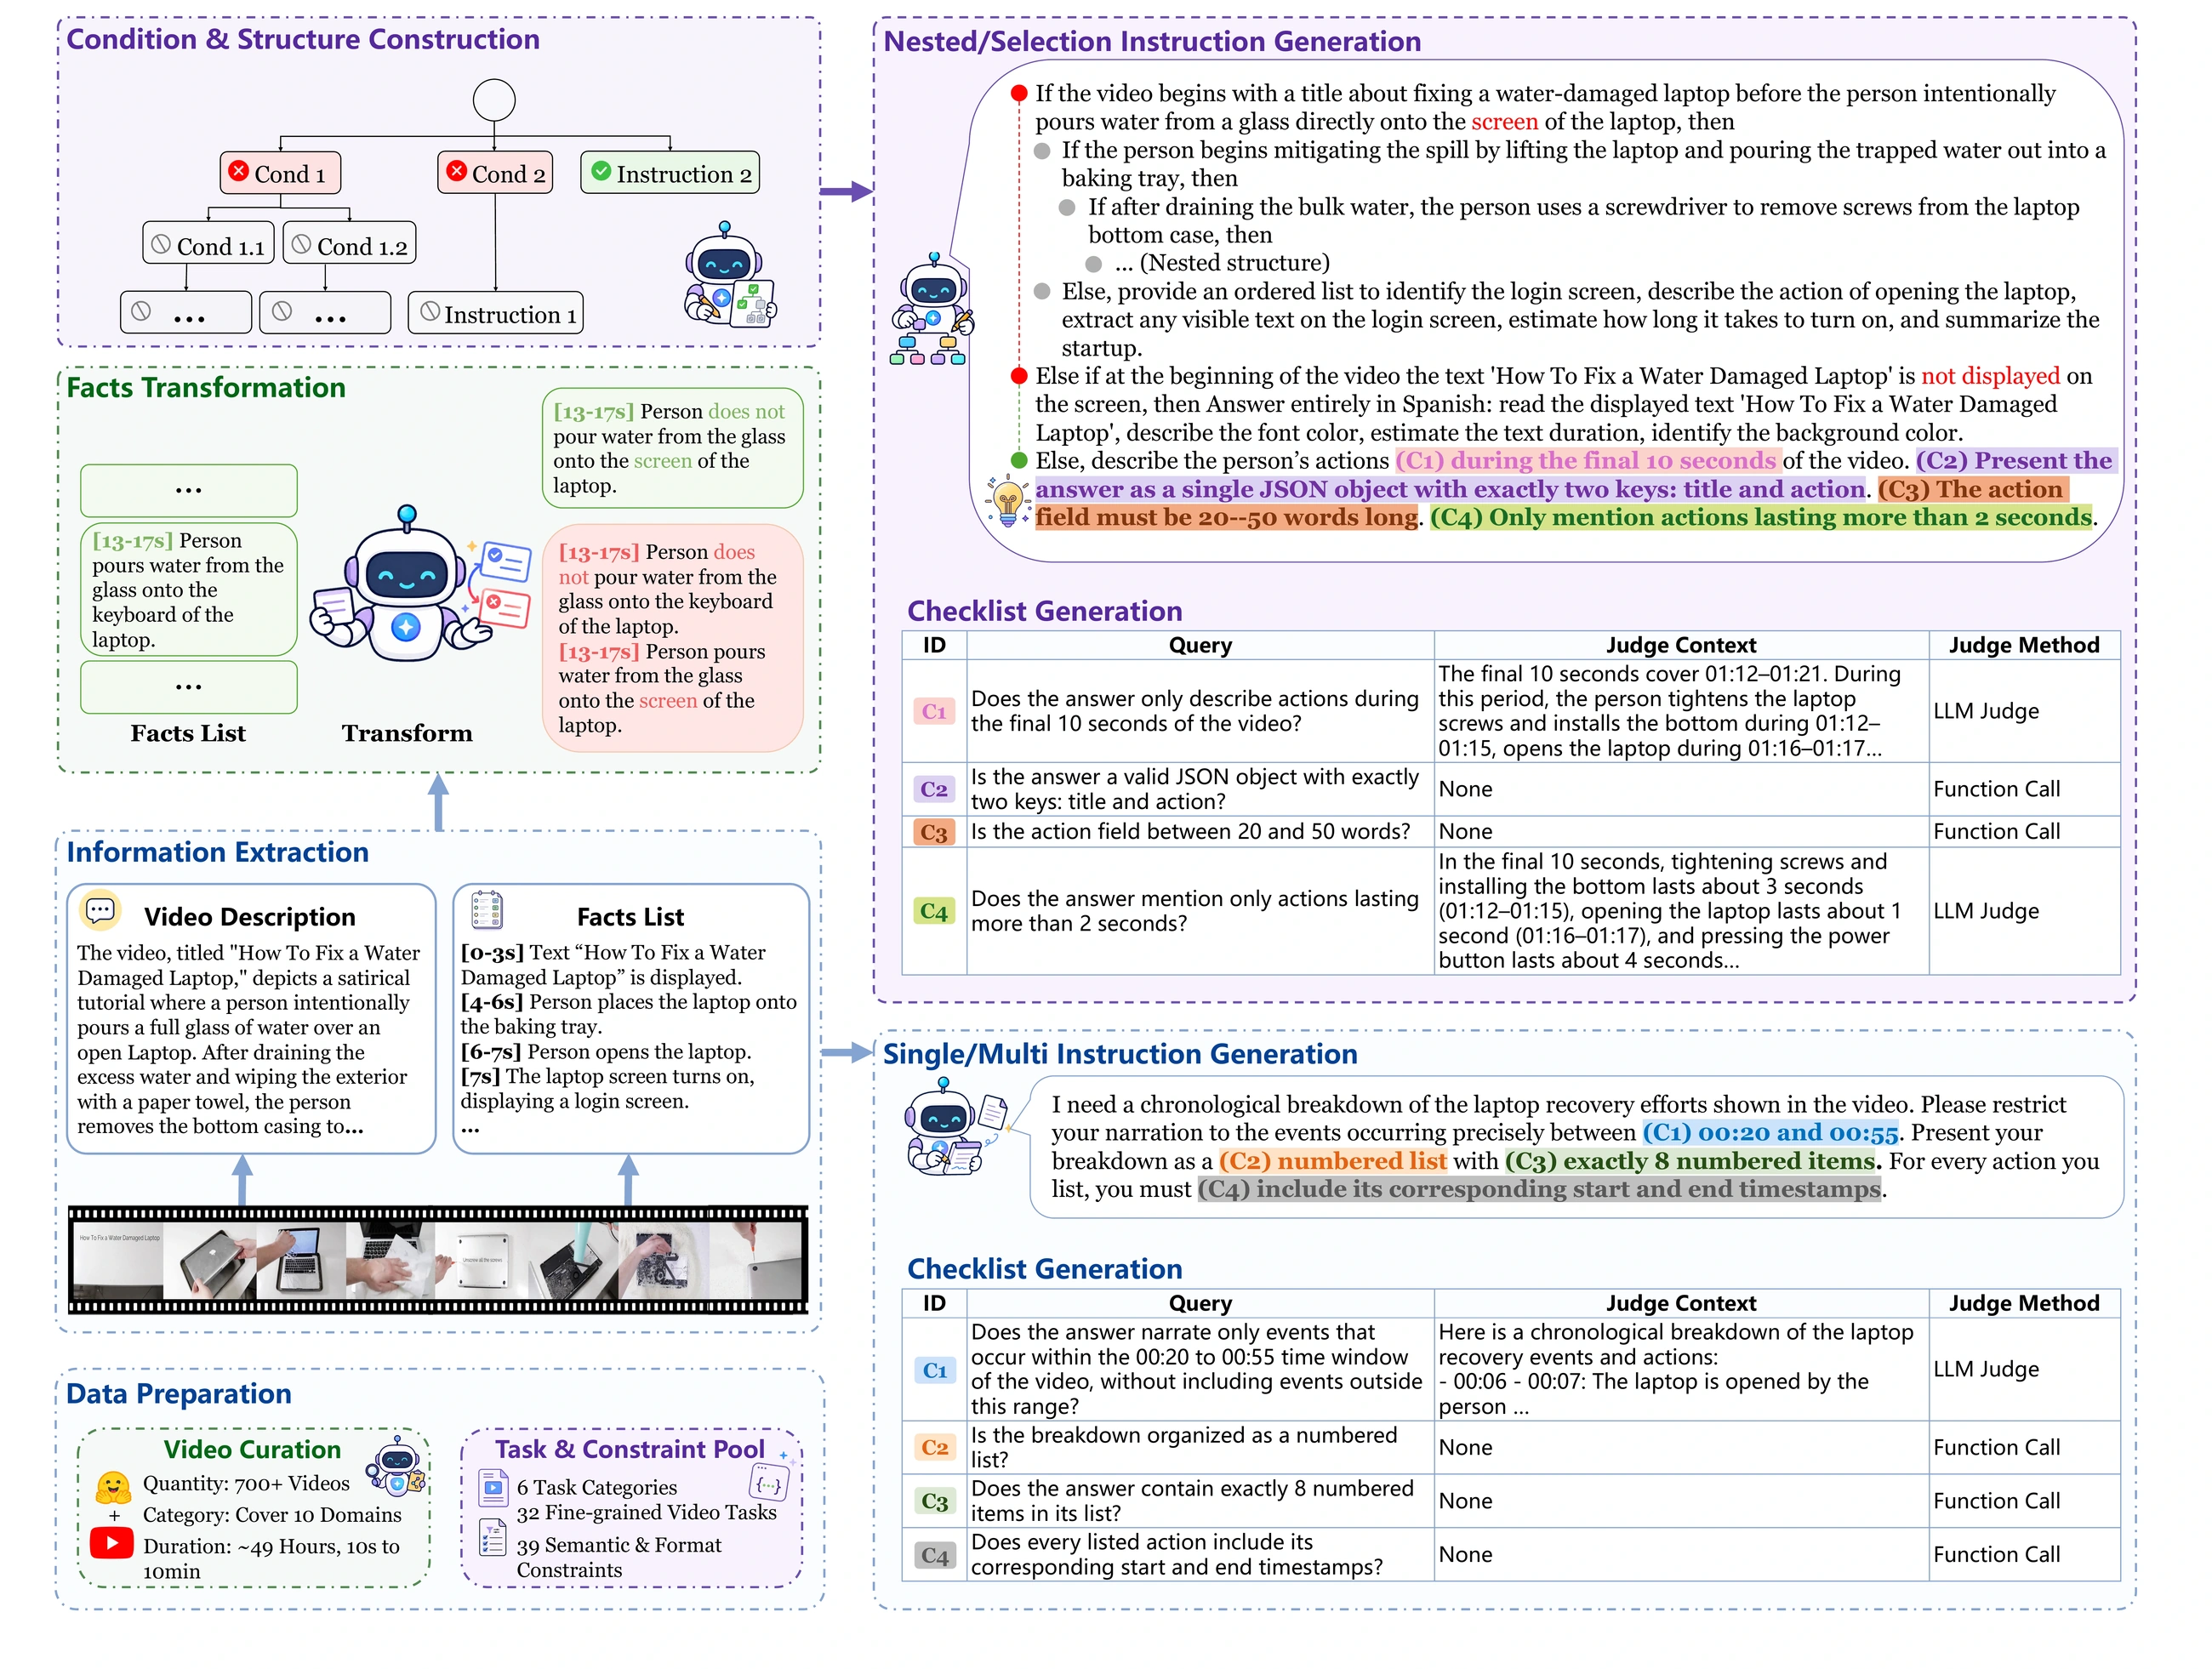
📊 Main Results
🗂️ Repository Structure
Video-IFBench/
├── video_ifbench/
│   ├── run.py                 # inference runner
│   ├── score.py               # three-stage response scorer
│   ├── summarize.py           # metric report formatter
│   ├── metrics.py             # TCSR/TISR aggregation
│   ├── function_judges.py     # deterministic constraint judges
│   ├── dataset.py             # dataset loading and case iteration
│   ├── media.py               # video/frame input handling
│   └── openai_client.py       # OpenAI-compatible API client
├── tools/                     # optional video preparation utilities
├── tests/                     # metric, scoring, and ASR tests
├── docs/                      # static project page and assets
├── pyproject.toml
└── requirements.txt
📝 Citation
If this benchmark or toolkit is useful in your work, please cite the manuscript:
@misc{liu2026videoifbenchevaluatinginstructionfollowing,
  title         = {Video-IFBench: Evaluating Instruction Following of Multimodal LLMs in Video Understanding Scenarios},
  author        = {Hongbo Liu and Peixian Chen and Sihan Liu and Peiyuan Zhang and Kai Zou and Dian Zheng and Xiaoxing Hu and Yuhao Dong and Mengdan Zhang and Yunhang Shen and Haoyu Cao and Wei Liu and Weibo Gu and Xing Sun and Shengjie Zhao},
  year          = {2026},
  eprint        = {2608.25529},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2608.25529}
}