

Repository
HelloWorld
Official repository for “HelloWorld: Enabling Socially Interactive Characters in Video World Models”. Huggingface: https://huggingface.co/papers/2608.05070
README
HelloWorld: Enabling Socially Interactive Characters in Video World Models
Liangyang Ouyang1,2, Ruicong Liu2, Xuangeng Chu2, Kaipeng Zhang2, Yoichi Sato1
1The University of Tokyo 2Alaya Lab
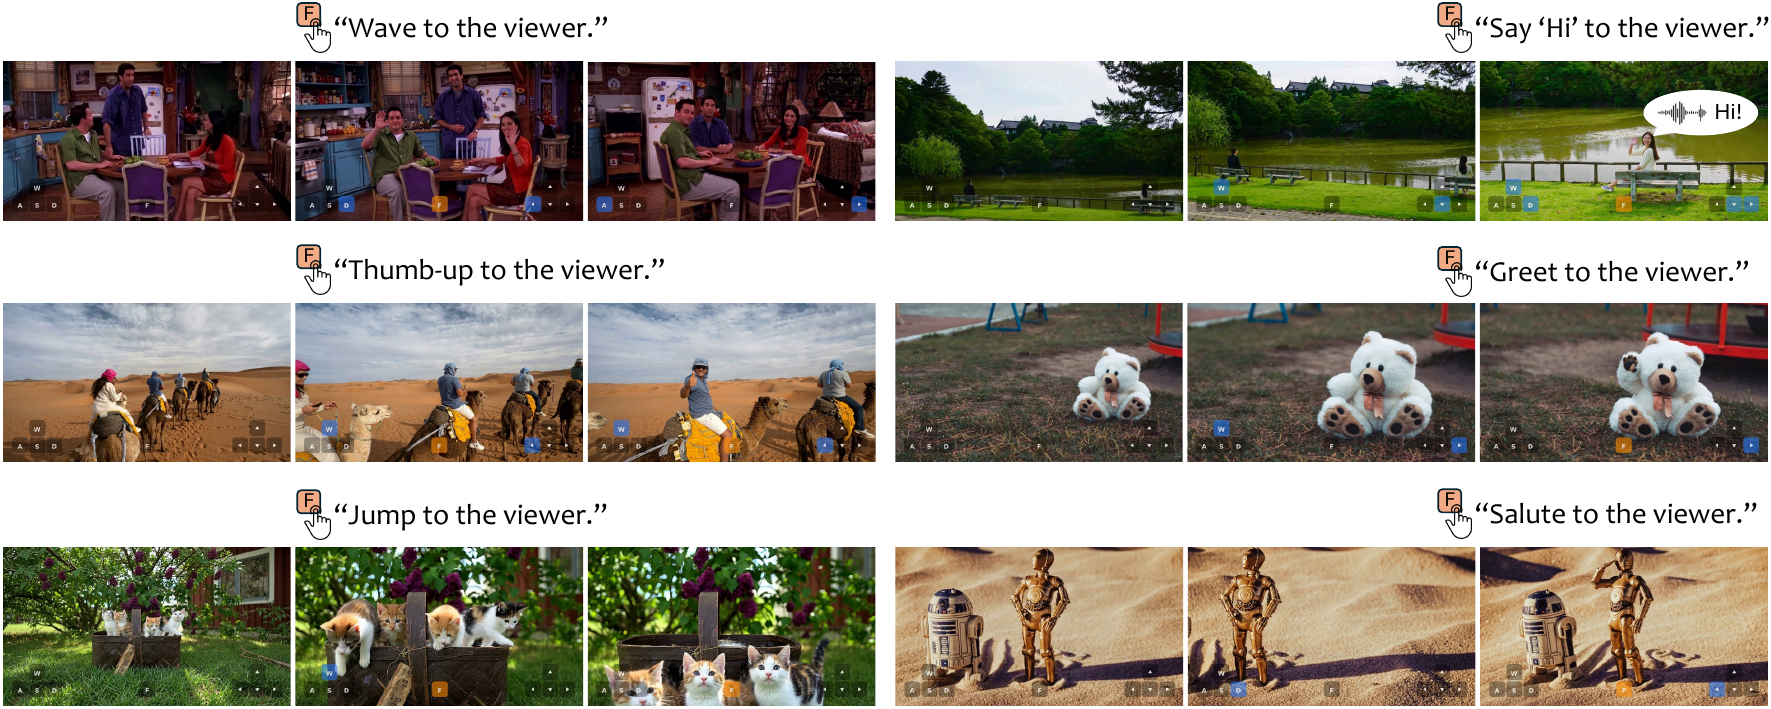
HelloWorld is a video world model that enables social interaction with in-world characters. With a single button press (F), users can prompt the on-screen character to respond toward the camera, e.g., turning to the viewer, waving, nodding, or speaking a short greeting, while maintaining high-quality scene and camera-trajectory reconstruction.
- Self-distillation training: the base video generation model is finetuned on data synthesized by itself, containing both social interactions and camera motion, so it learns camera-pose conditioning without degrading interaction quality.
- Training-free temporal control: at inference, a temporal cross-attention mask localizes the character's response to the
F-press window. - HelloWorldBench: a 400-sample benchmark with three social interaction metrics (ActAcc, TimeAcc, GazeDev) alongside three conventional metrics.
Examples
Warp Video Condition
HelloWorld Generation
A woman on a garden bench turns around and waves ("Hi") while the camera dollies in and orbits right: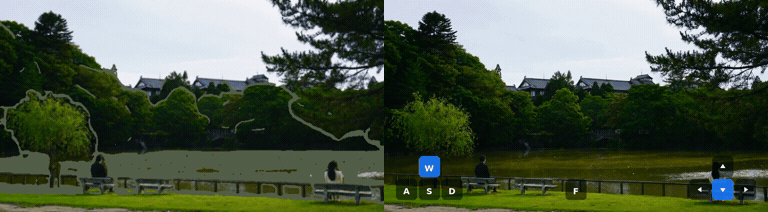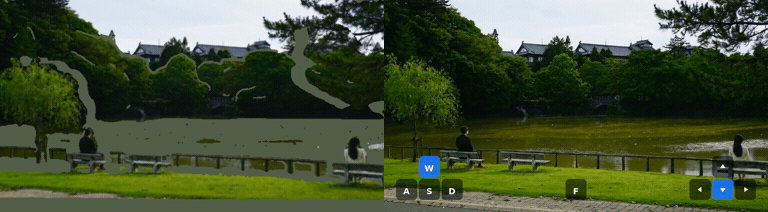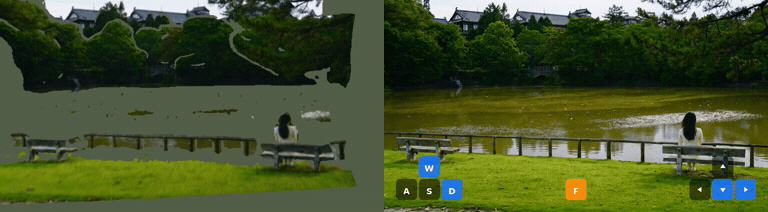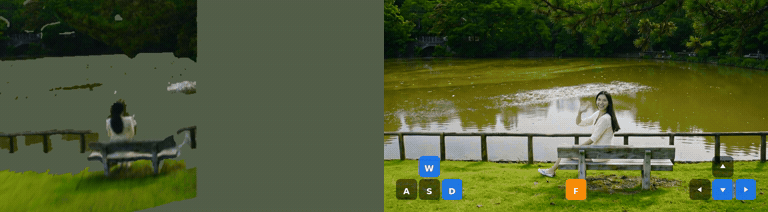
Two hikers turn and raise a thumbs-up ("Good!") while the camera rides a 30° orbit: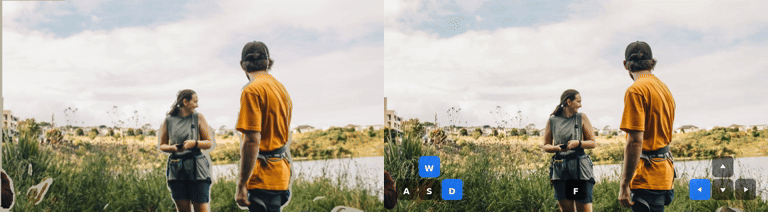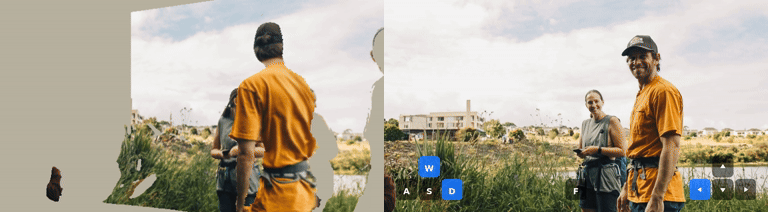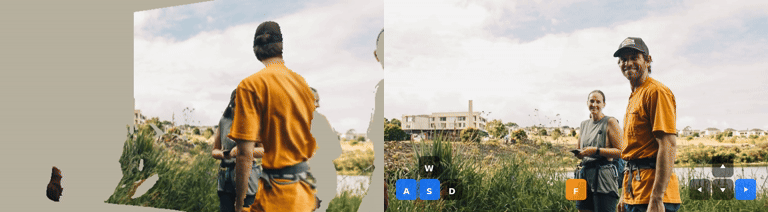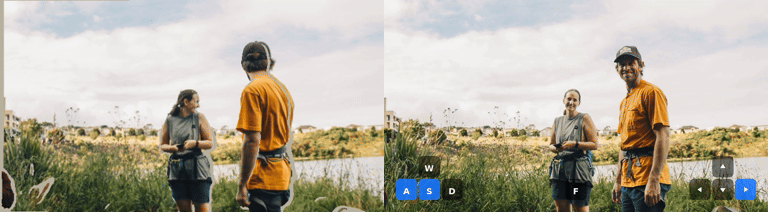
A woman doing yoga presses her palms together and bows ("Namaste") during a left–right camera scan: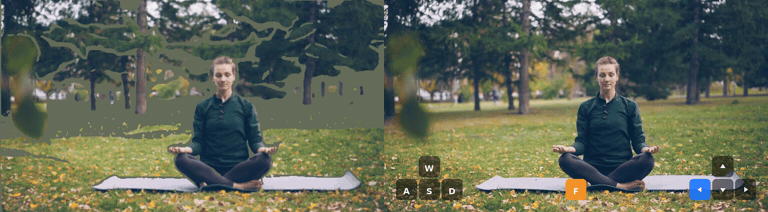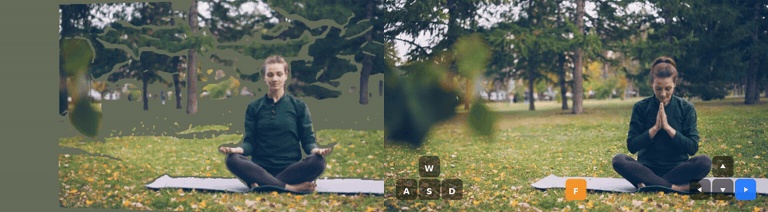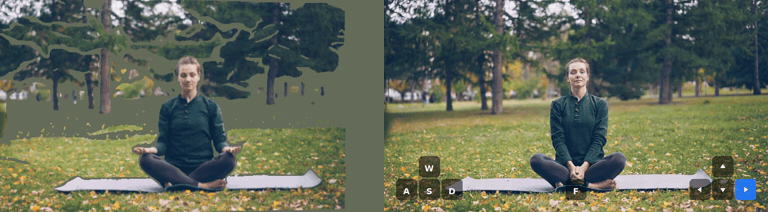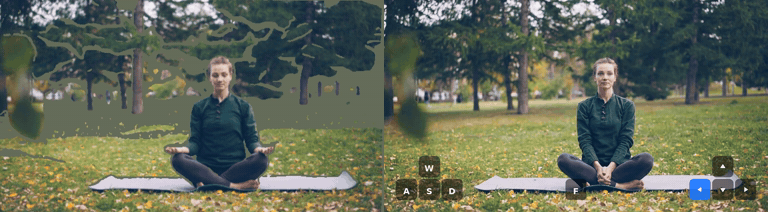
Two anime figurines come alive, raise one hand and wave ("Hello!") as the camera orbits left and pushes in: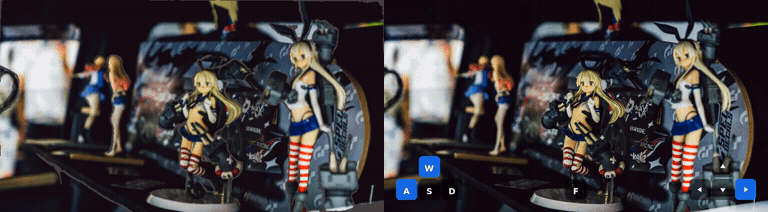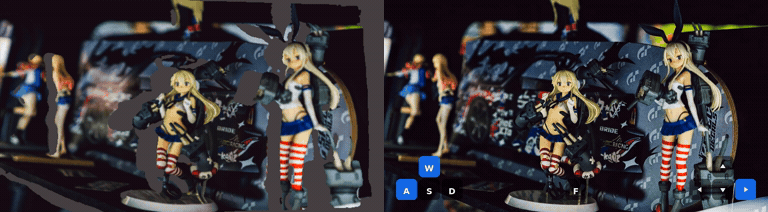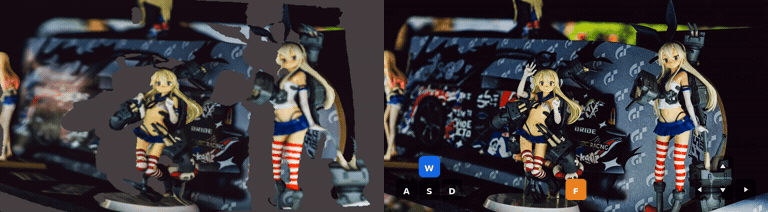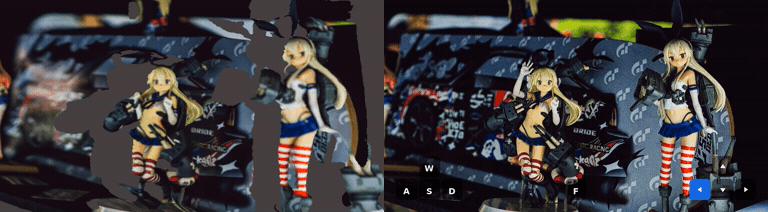
A crow turns to the viewer, spreads its wings and caws while the camera orbits left: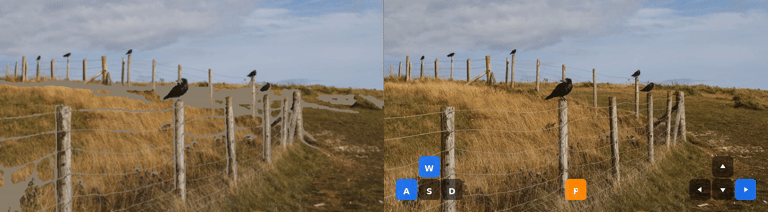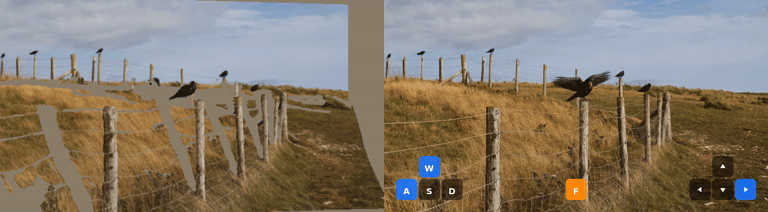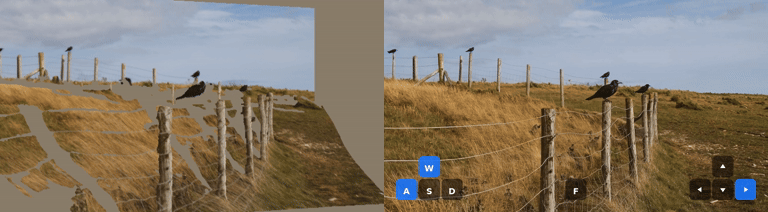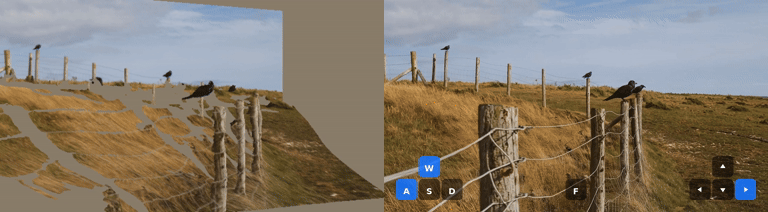
A bear mascot forms a heart with its arms during a right–left camera scan: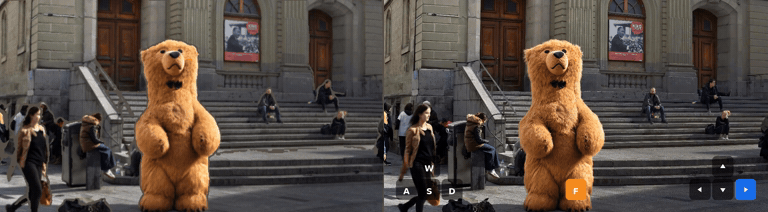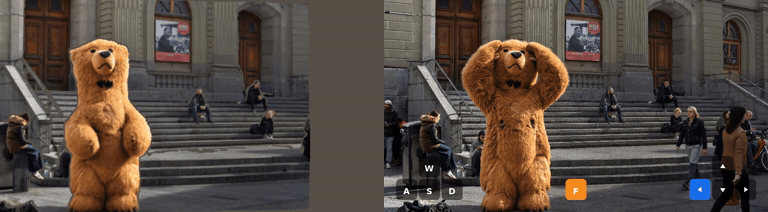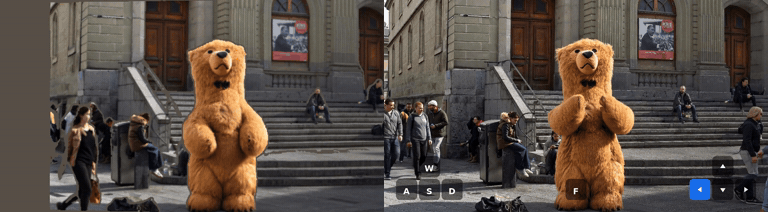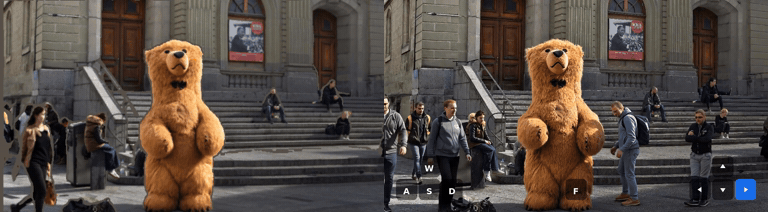
A skeleton prop turns its skull and waves while the camera orbits left: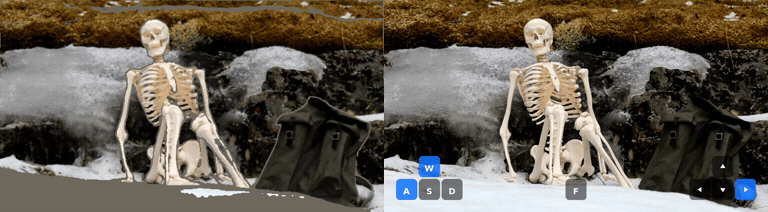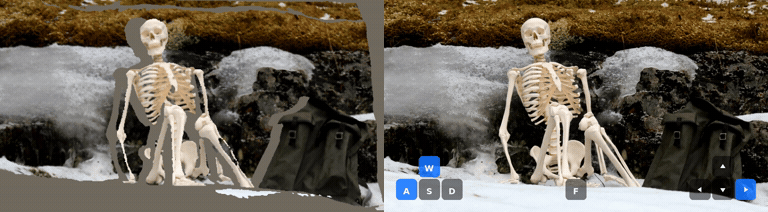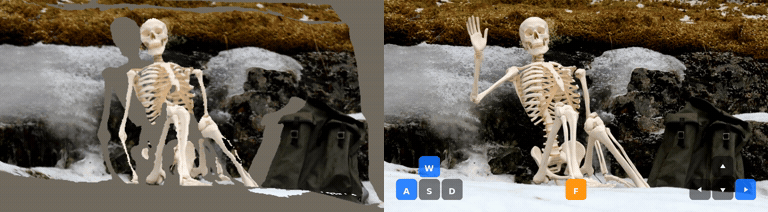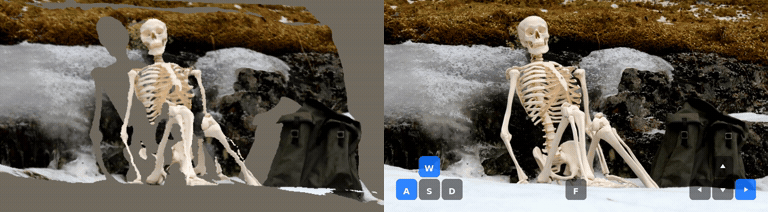
Paper
Demo Video
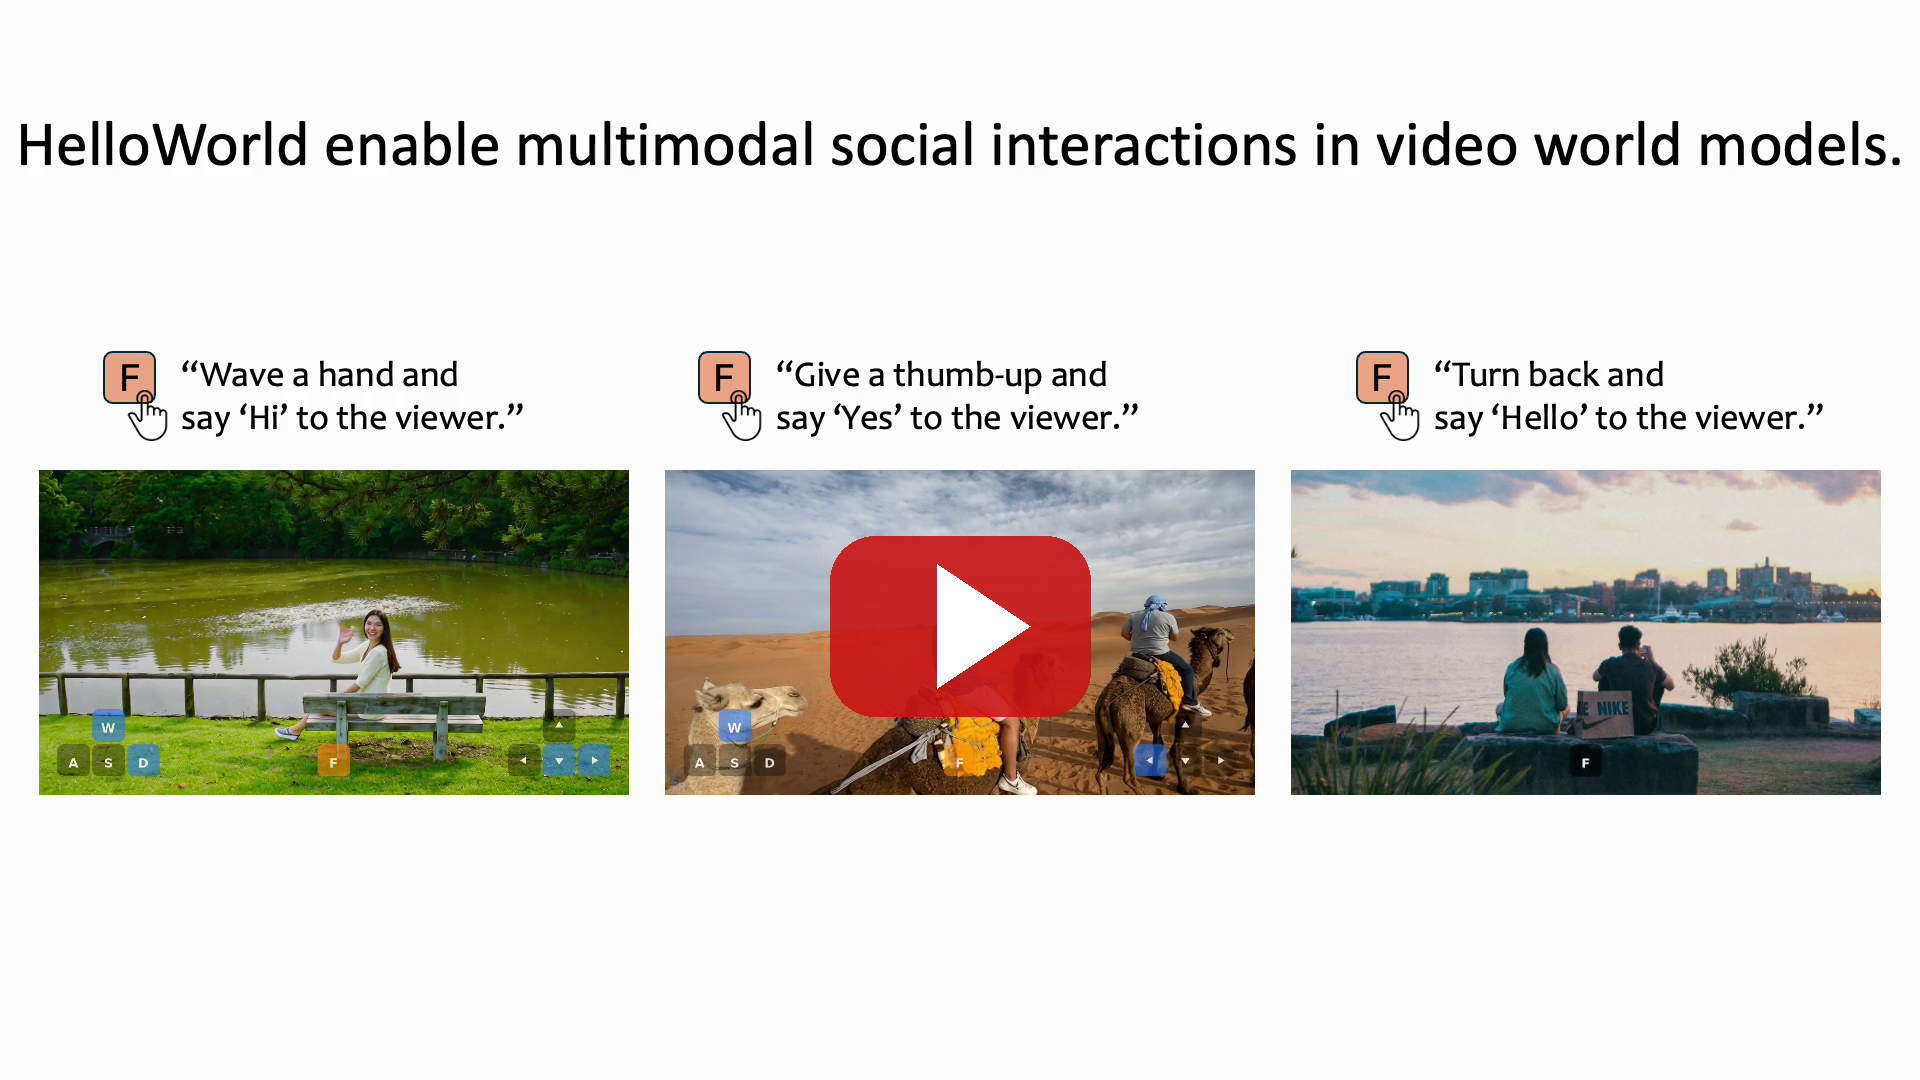
▶️ Watch on YouTube · 📥 Download: HelloWorld.mp4 (35 MB, 1080p)
Code & Model
Inference code is in inference/ — see its README
for environment setup (pinned requirements in env/), model weights, and the
full camera / interaction interface. The trained LoRA is on Hugging Face:
oyly/HelloWorld_V1. Ready-to-reproduce
examples (inputs + full recipes) are in assets/examples/.
cd inference
bash run_helloworld.sh                          # single clip
INPUT=examples_batch.json bash run_batch.sh     # reproduce the bundled examples
Release Schedule
- [x] Demo release
- [x] Model release
- [x] Inference code release
- [ ] Training code release
- [ ] Benchmark release
Unofficial Reproduction
Many thanks to ScrappyLabs for independently reproducing HelloWorld and open-sourcing their trained model — see scrappylabsai/helloworld-interactor and the released LoRA on Hugging Face. We are glad to see that their results align well with the paper. Our official release is in progress; in the meantime, feel free to try their model.
Citation
@article{ouyang2026helloworld,
  title   = {HelloWorld: Enabling Socially Interactive Characters in Video World Models},
  author  = {Ouyang, Liangyang and Liu, Ruicong and Chu, Xuangeng and Zhang, Kaipeng and Sato, Yoichi},
  journal = {arXiv preprint arXiv:2608.05070},
  year    = {2026}
}
Contact
For questions, please contact [email protected] or [email protected].