

Repository
ai4s-skills
Open-source agent skills for AI for Science: topic exploration, literature survey, experiments, paper writing, and integrity audit — driven by any coding agent.
- Skill
- Role
- ai4s-agent
- Runs the four skills below in order
- research-explorer
- Explore topics from a broad direction
- literature-survey
- Write a literature survey
Specs
- SkillRole
- ai4s-agentRuns the four skills below in order
- research-explorerExplore topics from a broad direction
- literature-surveyWrite a literature survey
- experiment-suiteBuild an experiment package
- paper-writerWrite a research paper
- mindmap-renderRender a mindmap
- integrity-auditorAudit a paper's integrity
- PrincipleIn practice
- Real citationsReal citations
- Labelled numbersLabelled numbers
- Runnable experimentsRunnable experiments
- Resumable runsResumable runs
- Publication layoutPublication layout
- Review disclosureReview disclosure
- Integrity checksIntegrity checks
README
English · 中文


Contents
- 🧩 The skills
- 🔗 How they connect
- ✅ Authenticity
- 🔬 Example
- 📦 Install
- 🚀 Usage
- 🗂️ Repository layout
- 🛠️ Included tools
- 🤝 Contributing
- ⚖️ License
- 🙏 Acknowledgments
The skills
| Skill | Role | Primary output |
|---|---|---|
| ai4s-agent | Runs the four skills below in order | the full package |
| research-explorer | Explore topics from a broad direction | research_exploration.md, topic_matrix.md, literature_pre_survey.md |
| literature-survey | Write a literature survey | 6–20 pp PDF, 60+ real citations, LaTeX source, taxonomy figures |
| experiment-suite | Build an experiment package | design doc, runnable code, results.json with provenance, figures, report |
| paper-writer | Write a research paper | 8–14 pp PDF, 200+ citations, 4–8 figures, tables |
| mindmap-render | Render a mindmap | image from a topic_matrix.md (Python script) |
| integrity-auditor | Audit a paper's integrity | image / numerical / logical findings, 4-level evidence grading, audit_report.md |
Each skill is a folder with a SKILL.md plus its own references, templates, and
tools. MIT-licensed; works with Claude Code, Cursor, Codex, and Aider.
How they connect
direction
   │
   ▼
[1] research-explorer ──▶ pick one $TOPIC
   │
   ├──▶ [2] literature-survey   → survey PDF + bibliography.bib
   ├──▶ [3] experiment-suite    → results.json + figures/
   └──▶ [4] paper-writer        → paper PDF  (reuses [2] and [3])

integrity-auditor ──▶ audits any paper: external PDF / DOI / arXiv, or [4]'s output
ai4s-agent runs steps 1–4 in order. Skills pass work to each other through a
shared slug and the path output/<skill>/<slug>/latest/.
Authenticity
The focus of the project. Every skill enforces:
| Principle | In practice |
|---|---|
| Real citations | Every BibTeX entry links to a URL the agent fetched in the same session; none from memory. |
| Labelled numbers | Every number is marked measured, simulated, or illustrative; simulated values are never reported as measured. |
| Runnable experiments | experiment-suite outputs runnable code and a results.json with provenance. Supply real results and they replace the simulated ones; the "simulated" disclosure is then removed. |
| Resumable runs | Long tasks save progress after each step and continue from the last checkpoint, so a reported "done" reflects completed work. |
| Publication layout | booktabs tables, [!t] floats, ~\cite{}; vector-PDF figures with embedded fonts and defined color palettes. |
| Review disclosure | Every generated document states that domain-expert review is recommended. |
| Integrity checks | integrity-auditor inspects a paper for image, numerical, and logical problems and grades the evidence. |
Example
A complete run from experiment-suite + paper-writer: "Learning the Burgers
Solution Operator with a Fourier Neural Operator" — an 8-page paper backed by code
the agent wrote and ran. Full artifact in examples/fno-burgers/
(paper, code, results.json, report).
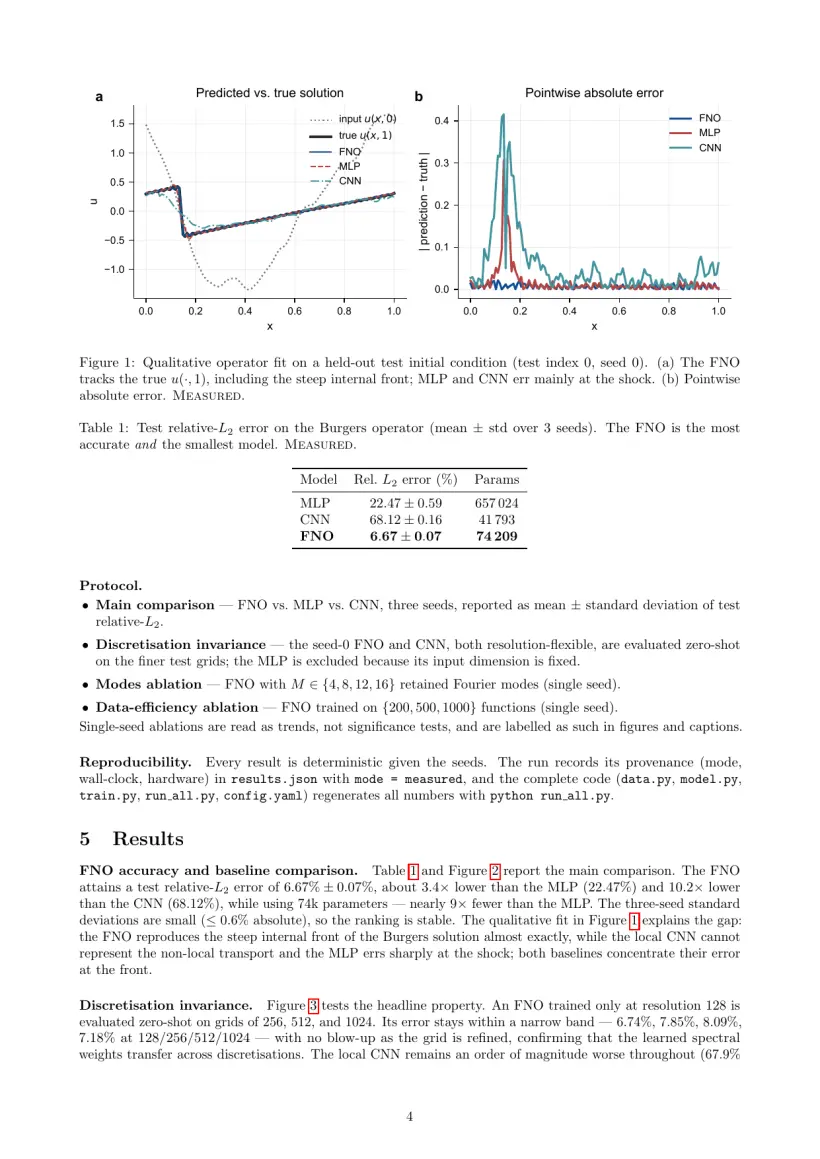
 The 8-page paper (first 6 pages) — click any page for the full PDF.
- Real code, really run —
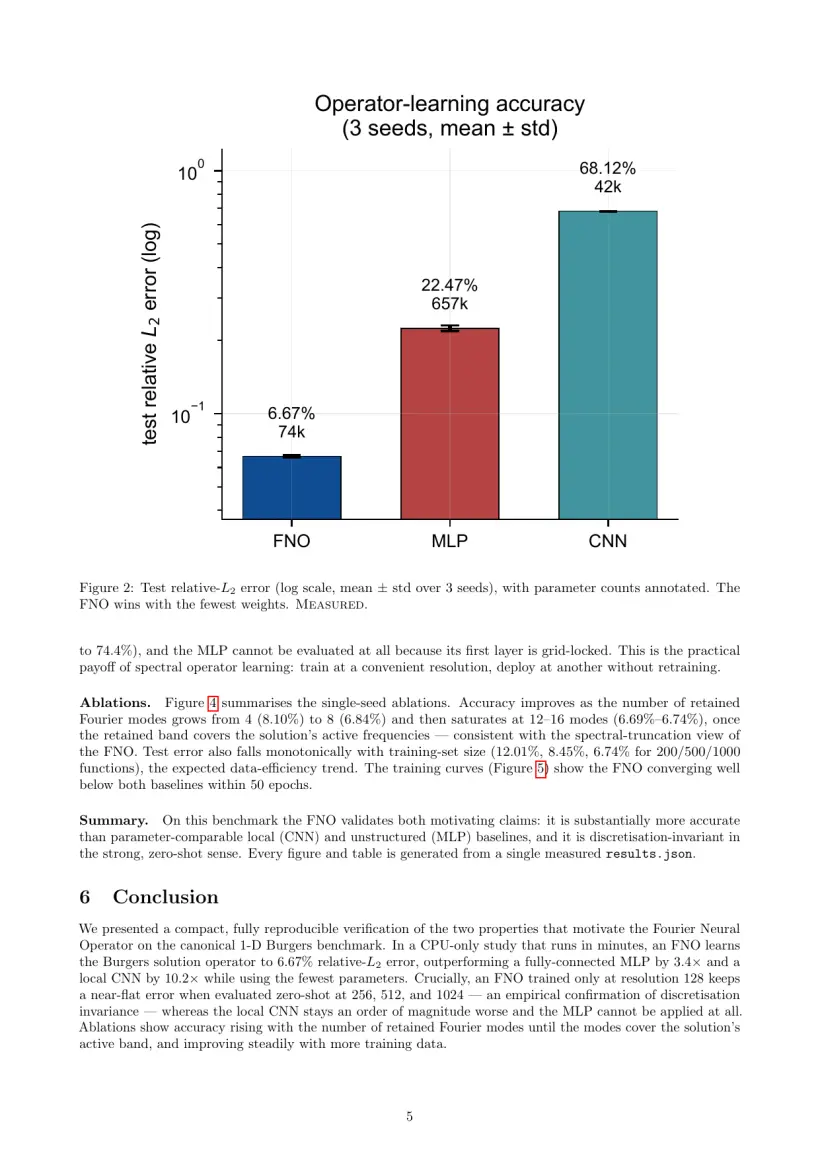
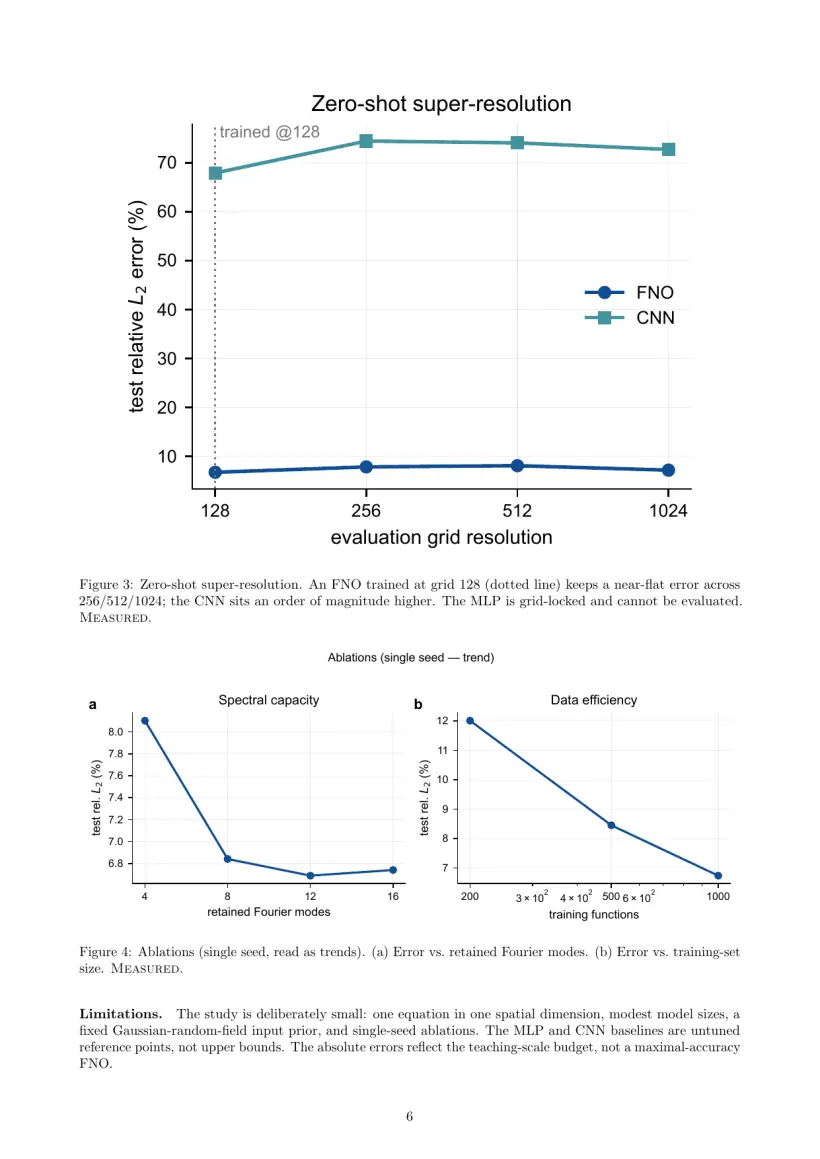
model.pyis a 1-D FNO; the full study runs in ~35 min on a laptop CPU. - Measured results — FNO 4.41% rel-L2 vs MLP 21.63% and CNN 67.69% (3 seeds); zero-shot super-resolution holds 4.2–4.7% from grid 128 to 1024.
- Real citations — 22 references, each traceable to its source.
Every number is measured (provenance in results.json); the paper states it was
AI-generated and recommends domain-expert review.
Install
Run the installer from the project you want the skills in:
git clone https://github.com/ai4s-research/ai4s-skills

cd /path/to/your-project
/path/to/ai4s-skills/install.sh                              # all skills → ./.claude/skills
/path/to/ai4s-skills/install.sh paper-writer                 # or specific ones
SKILLS_DIR=~/.claude/skills /path/to/ai4s-skills/install.sh  # global instead
To install by hand, copy any skills/<name>/ into ~/.claude/skills/ (global) or
<project>/.claude/skills/ (project).
Usage
In Claude Code:
Use the literature-survey skill to write a survey on \<your topic>.
With Cursor, Codex, or Aider, point the agent at the skill file:
Read skills/literature-survey/SKILL.md and its references/, then produce the survey
for "<your topic>" as specified.
Each SKILL.md directs the agent to read its references/ first; those files hold
the procedures for bibliography expansion, figures, layout, and quality checks.
Repository layout
ai4s-skills/
├── skills/
│   ├── ai4s-agent/          SKILL.md + references/
│   ├── research-explorer/   SKILL.md
│   ├── literature-survey/   SKILL.md + references/ + templates/survey/
│   ├── experiment-suite/    SKILL.md + references/ + figure_examples/
│   ├── paper-writer/        SKILL.md + references/ + templates/paper/
│   ├── mindmap-render/      SKILL.md + scripts/ + tests/
│   └── integrity-auditor/   SKILL.md + references/ + forensics_tools/ + templates/ + tests/
├── tools/validate_skills.py   structure / frontmatter validator (run in CI)
├── install.sh
└── .github/workflows/ci.yml
Each SKILL.md carries YAML frontmatter (name, description) so an agent can
find and route to it.
Included tools
Small, single-purpose scripts the skills call. Each directory has its own
requirements.txt.
skills/integrity-auditor/forensics_tools/— image duplication / ORB matching, panel splitting, channel checks, magnitude (Benford-style) consistency, decimal matching, spreadsheet aggregate consistency.skills/experiment-suite/figure_examples/— a matplotlib style kit (style_kit.py) and worked figure examples.skills/mindmap-render/scripts/—generate_mindmap.py.
Contributing
A new skill needs:
skills/<name>/SKILL.mdwithnameanddescriptionfrontmatter (name= folder name).- Optional
references/,templates/, and tools. - No
import anthropic/import openai. python tools/validate_skills.pypassing (CI runs it on every PR).
See CONTRIBUTING.md and the Code of Conduct.
License
MIT.
Outputs are drafts. Review by a domain expert is recommended before any citation,
submission, or decision. Verify numbers, citations, and claims.
Acknowledgments
Thanks to linux.do — a vibrant tech community where this project is shared and discussed.