Text to speech

Miso One

Open-weights 8B AI text-to-speech model for expressive English speech.

Source rating 5.0 (67) 24k views 24k/mo traffic 0 saves Freemium
More categories (5)

Free + from $4.95 per month

Verdict

A quick read before you dig into the full page.

Best if
You are voice-agent builders and need: Running low-latency conversational speech generation locally for voice-agent research
Skip if
You need enterprise SLAs or a fully managed team plan right away
Pick this when
Freemium · Free + from $4.95 per month

Overview

Miso One is an open-weights, 8B-parameter text-to-speech (TTS) system developed by Miso Labs. It is designed specifically for producing highly realistic, expressive, and emotionally varied English conversational speech, making it ideal for voice-agent research and developer workflows. Built on a Sesame-style conversational speech model (CSM) architecture with Mimi audio codes, it features a highly optimized inference capability boasting a published low latency of 110 ms. In addition to text-to-speech generation, the model supports voice continuation and one-shot voice cloning from audio context with clear consent boundaries.

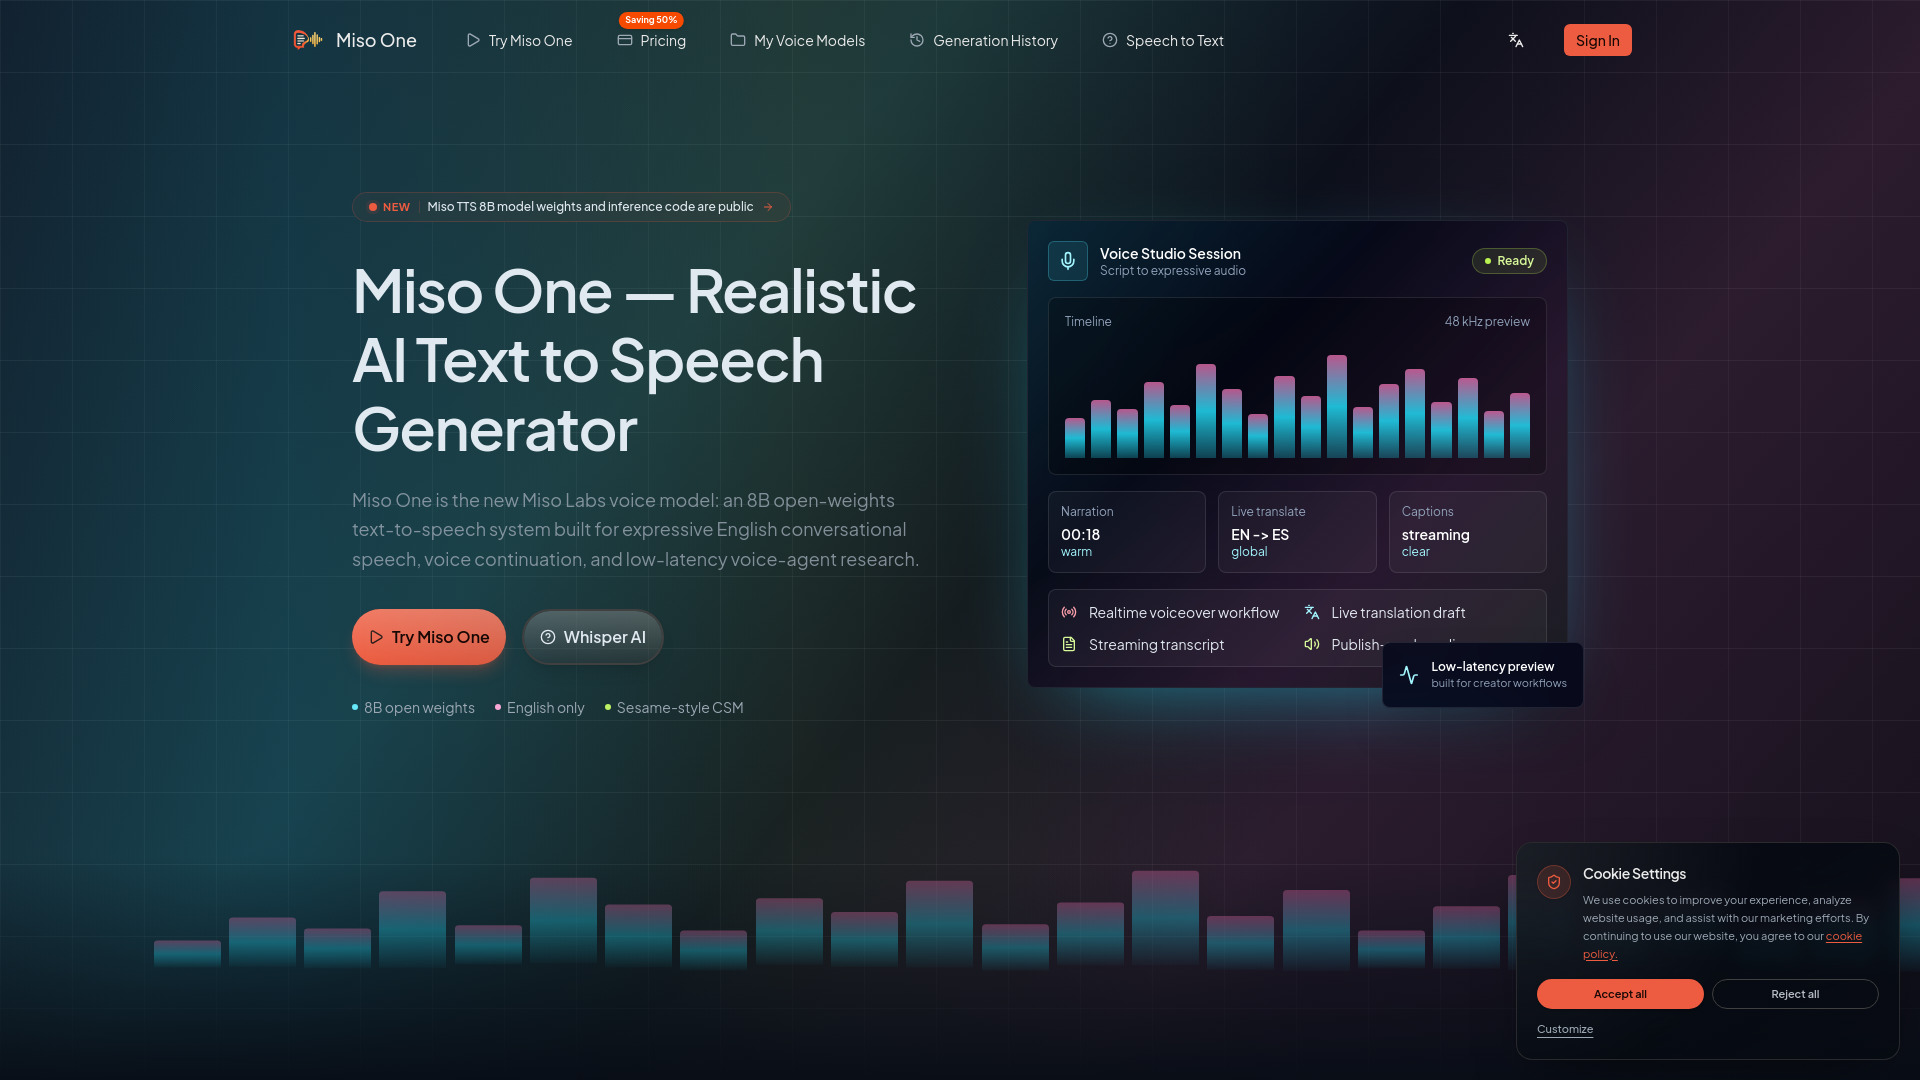
Miso One screenshot

Best for

Short scenarios where Miso One tends to shine.

  • Running low-latency conversational speech generation locally for voice-agent research

    Best for Voice-agent builders

  • Generating high-quality, expressive voiceovers, narrations, and captions for creator content

    Best for Model researchers

  • Creating instant voice clones and personal voice models using brief, consented audio context prompts

    Best for Content creators

Example outputs 1

Sample generations and before/after results for Miso One.

Access & connections

Where you can use Miso One.

Platforms

Web

Capabilities

What this tool accepts, produces, and is strongest at.

Highlights

  • 8B-parameter open-weights text-to-speech model
  • Expressive, conversational, and emotionally varied English speech
  • Low-latency architecture with a published 110 ms response claim
  • One-shot voice cloning and prompt-audio continuation capabilities
  • Discrete audio-code modeling using Mimi audio codes
  • 48 kHz preview quality with built-in watermarking and safety checks

People also view

Tools that often show up alongside Miso One in collections and comparisons.
FAQ 8

What is Miso One?
Miso One is an open-weights, 8B-parameter text-to-speech (TTS) system developed by Miso Labs. It is designed specifically for producing highly realistic, expressive, and emotionally varied English conversational speech, making it ideal for voice-agent research and developer workflows. Built on a Sesame-style conversational speech model (CSM) architecture with Mimi audio codes, it features a highly optimized inference capability boasting a published low latency of 110 ms. In addition to text-to-speech generation, the model supports voice continuation and one-shot voice cloning from audio context with clear consent boundaries.
How to use Miso One?
Users can evaluate Miso One by reading its official model card on the repository or Hugging Face page, trying out the hosted web demo to check voice quality, or downloading the public 8B weights and inference code to run local benchmarks within their own CUDA environment. For hosted creator workflows, users can sign up and choose a subscription plan based on their required annual or monthly character capacity.
What is Miso One?
Miso One is the product-facing name for Miso Labs' Miso TTS 8B release, an open-weights English text-to-speech model built for expressive conversational speech and low-latency workflows.
Is Miso One open source?
Miso One provides open weights. The Miso TTS 8B model weights and inference code are public and available via the official Hugging Face model page and MisoTTS GitHub repository for local inspection and hosting.
How many languages does Miso One support?
The current public release is English-only and focused entirely on English conversational delivery, pacing, and emotional range.
Can I run Miso TTS 8B locally?
Yes, you can download the weights and run local inference. However, because it is an 8B parameter model, you will need a robust local hardware environment with a proper CUDA setup.
Does Miso One support voice cloning?
Yes, it supports prompted generation from audio context for voice continuation and one-shot voice cloning, which should always be evaluated using consented audio.
What are the limitations on character conversions?
Free users have a maximum limit of 120 characters per conversion. Paid plans and credit packs allow for a maximum of 1,000 characters per conversion.
Miso One Free + from $4.95 per month