
Api cost reduction 2026 Rank: #1481
Lexi ✓
AI API proxy — you save first, then we earn. One URL
Verdict
A quick read before you dig into the full page.
- Best if
- AI API proxy — you save first, then we earn. One URL
- Skip if
- Limited language/platform support
- Pick this when
- One URL change integration
Considering SemanticGuard instead? Compare side by side
Overview
One URL change. That's the integration. Swap your OpenAI or Anthropic base URL for api.lexisaas.com. Streaming, tool calls, function calling, structured output — everything passes through unchanged. Your provider API keys are forwarded directly to OpenAI, Anthropic, or Google on each request and are never stored or logged by Lexi.
HOW BILLING WORKS
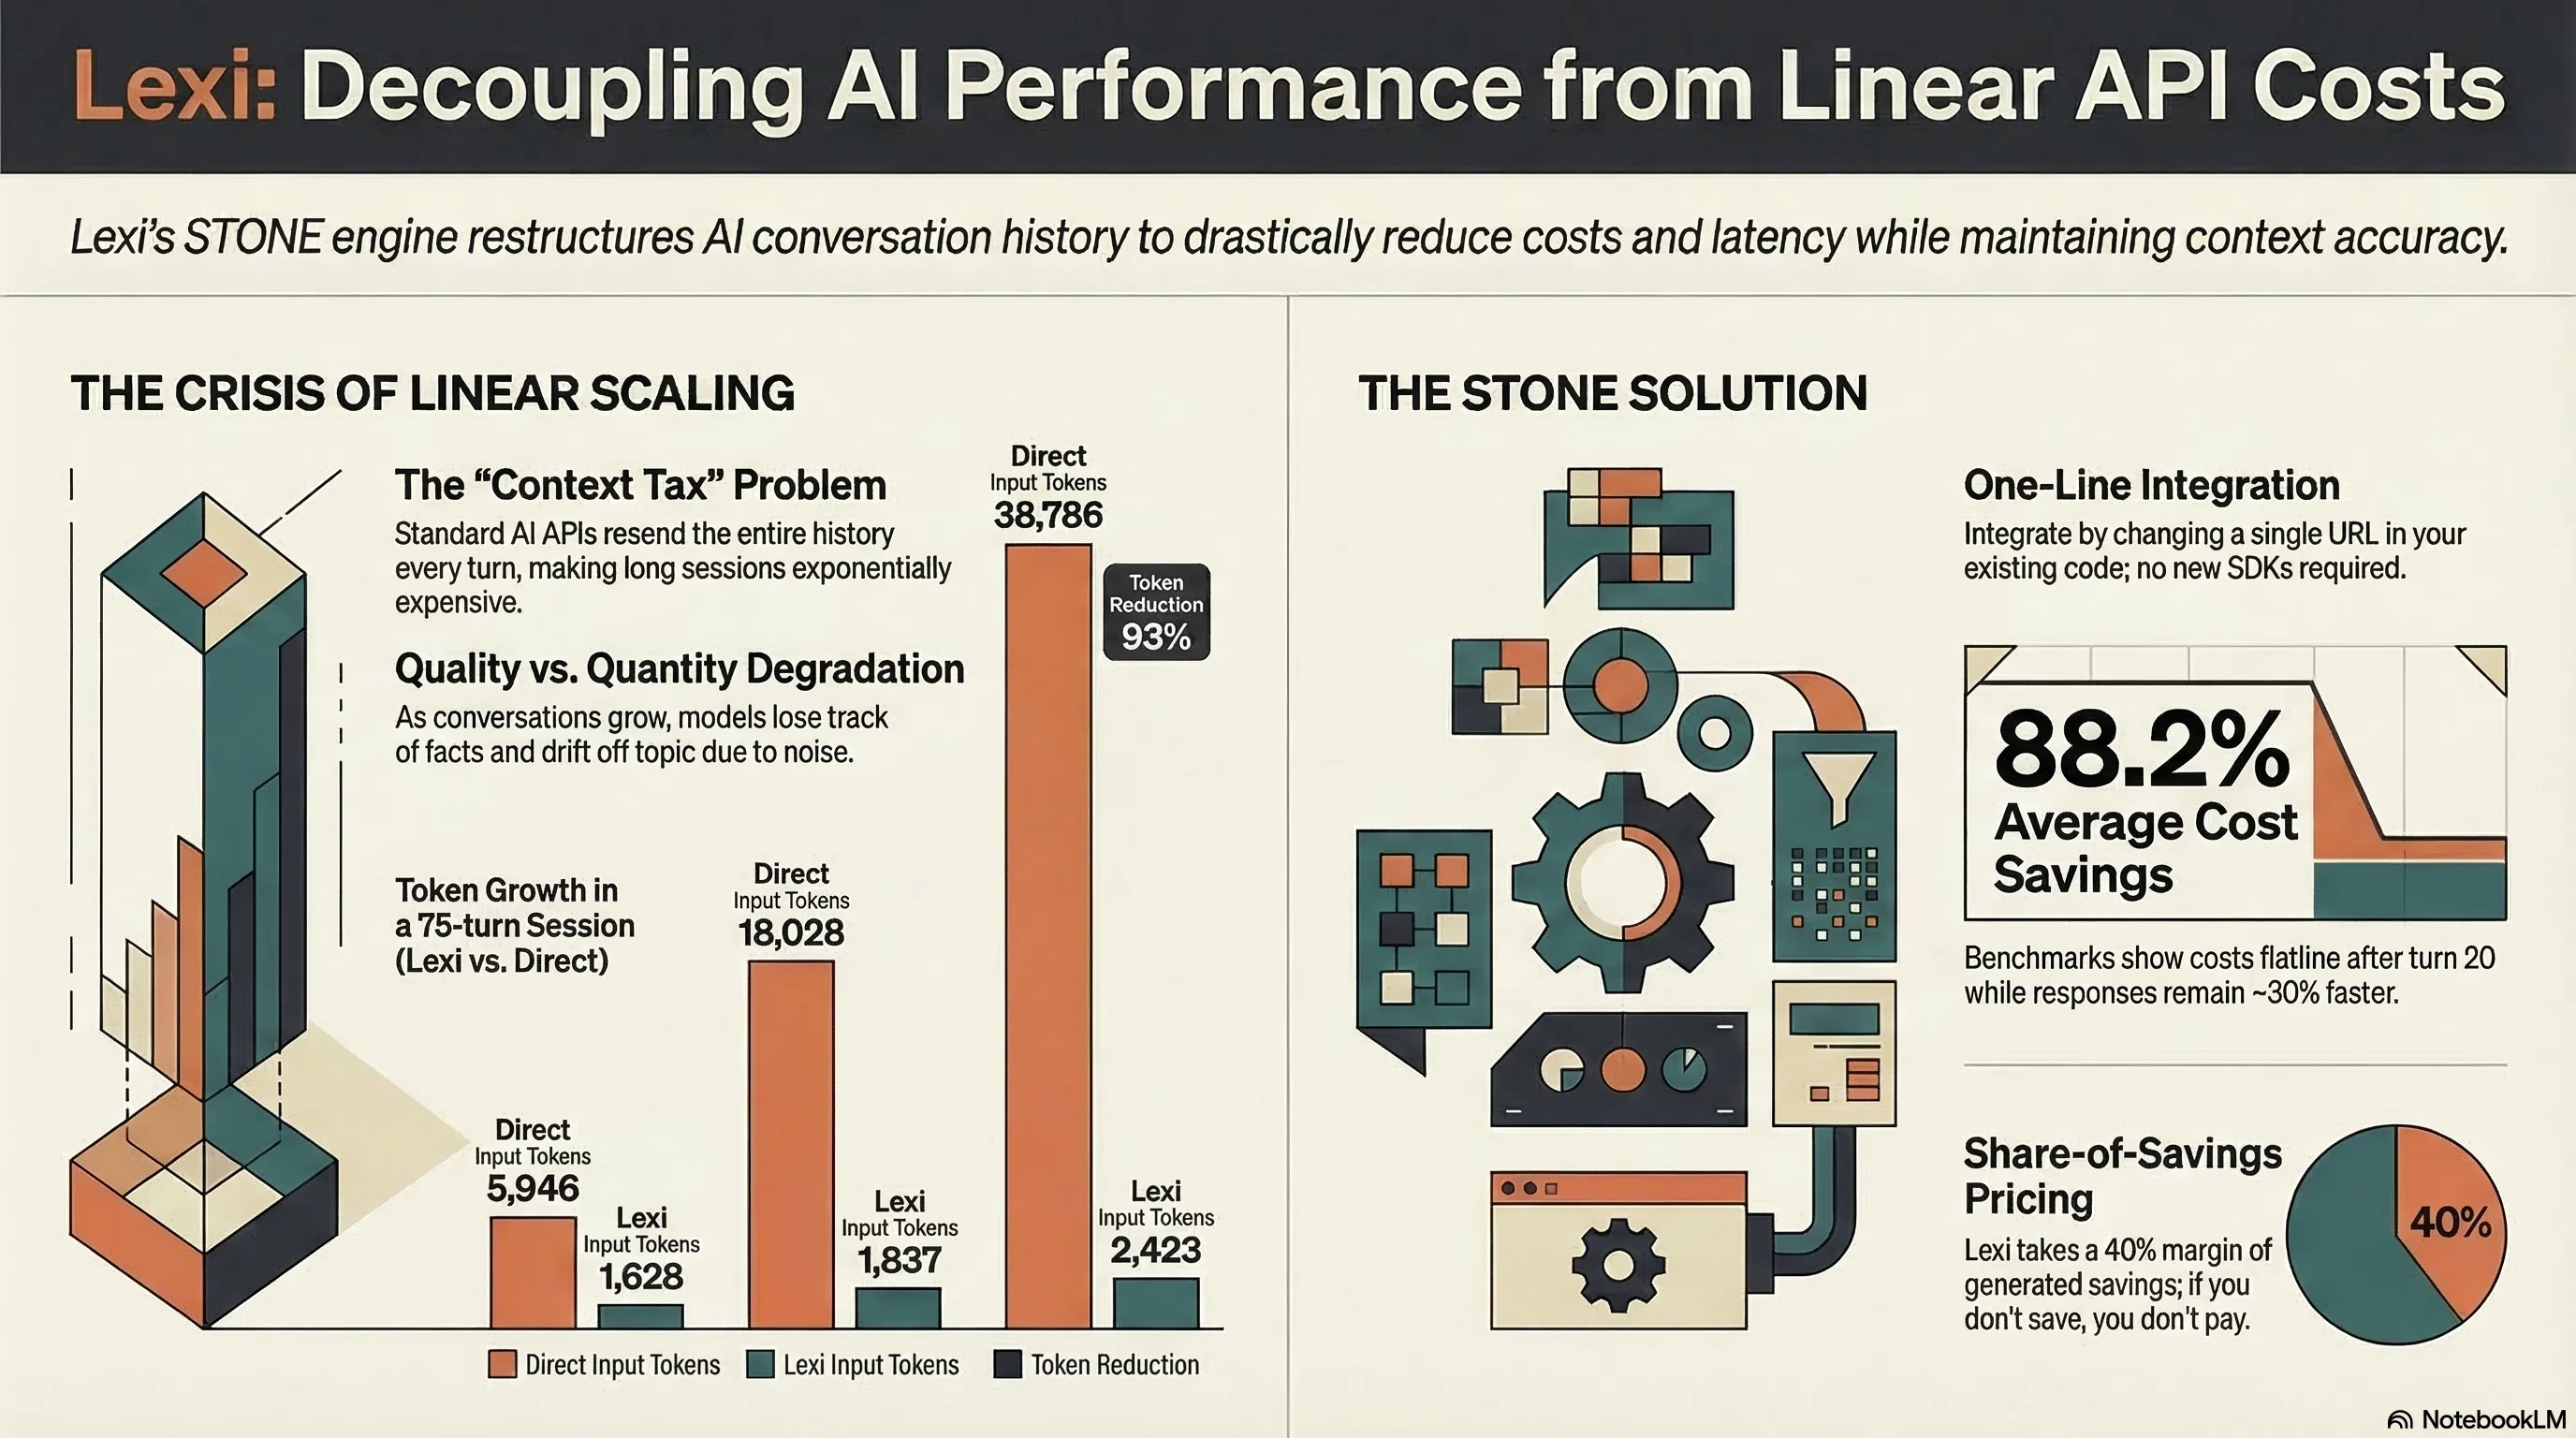
Lexi uses share-of-savings pricing. Your provider charges you less because Lexi sent fewer tokens. Lexi takes 40% of the difference — the savings it generated. The other 60% is yours. If a request produces no savings, there's no Lexi fee. You cannot pay more than going direct.
Every API response includes HTTP headers showing the exact cost breakdown: what you saved, what Lexi earned, and your remaining balance. No estimates, no end-of-month surprises.
WHAT STONE DOES
STONE (Semantic Token Optimization and Natural Encoding) is the engine behind Lexi. Turn 1 passes through unchanged — zero overhead. From turn 2 onward, STONE restructures the conversation history into a bounded form. The payload sent to the AI model stays roughly constant whether you're on turn 5 or turn 75. Cost flatlines instead of growing linearly.
Critical information survives: numbers, dates, decisions, version strings, port numbers, metrics, and named entities are pinned into a permanent anchor. Fact corrections propagate — say "actually it's port 8080, not 5432" and the update sticks.
RECALL SYSTEM
Most AI conversations degrade because the model loses track of what was said 20 or 30 turns ago. Lexi solves this. Every message is permanently archived with AES-256-GCM encryption. When earlier context becomes relevant again, a three-tier recall system retrieves the original content, extracts exactly what the model needs for the current question, and injects it into the request.
This isn't generic retrieval — it's query-conditioned. Ask "what port did we settle on?" and Lexi surfaces the specific decision, not a summary of the entire conversation.
The system also learns from use. After every response, Lexi scores what it recalled against what the model actually used. Strategies that produce useful context get reinforced. The system gets sharper over time.
BENCHMARK RESULTS
In a blind-judged benchmark across a 75-turn conversation covering 7 different topics (project planning, database design, infrastructure, security, debugging, marketing, sprint planning), Lexi delivered:
— 91.6% token savings (1.6M tokens reduced to 136K)
— 88% cost reduction ($0.52 vs $4.37 on GPT-4o)
— 30% lower latency (fewer tokens = faster responses)
— 8.4/10 factual accuracy vs 9.0/10 for full context (0.6-point gap)
— Facts from turn 3 correctly recalled at turn 70+
The benchmark was run 4 times to verify reproducibility. The accuracy gap is in response detail and structure, not factual correctness — Lexi matches full-context on the facts but produces more concise responses.
28 models across 6 providers: OpenAI (GPT-5, GPT-4o, o3, and more), Anthropic (Claude Opus, Sonnet, Haiku), Google (Gemini 3 Pro, Flash), xAI (Grok 4, Grok 3), DeepSeek (V3.2, R1), and Meta (Llama 4).
$10 free credit on signup. No credit card required. Built in Norway by LexiCo AS.
- Developer Tools
- Ai Infrastructure
- Llm Operations
Access & connections
Where you can use Lexi.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Input
- API
- Code
- Text
Output
- Code
- API
- Text
Highlights
- API
Supported features
- API
Pros & cons
Pros
- One URL change integration
- Direct billing from providers
- Reduced API costs
- No extra fee without savings
- Provider API keys security
- Transparent cost breakdown
- Long conversation coherency
- 28 models across 6 providers
Show 39 more
- No credit card required
- Rapid setup and deployment
- Detailed API documentation
- Complementary $10 credit
- No provider keys storage
- Streamlined tool calls
- Structured output support
- Functional call support
- No changes to existing stack
- Interceptable response headers
- Loggable cost data
- Displayable cost breakdown
- Anthropic adaptation supported
- Google API adaptation
- Mistral API adaptation
- Groq API adaptation
- Cost and balance alerts
- Quality conversation extension
- Tokens compression details
- Async call margin info
- Visible savings and margin
- Fully maintained coherency
- No additional tool loading
- Exact cost calculation
- Admins control on cost
- Secured data transmission
- Billing details for users
- Convenient HTTP headers configuration
- Developer friendly tool
- No long term contracts
- Upfront savings estimation
- Usage report in headers
- Low latency response
- High throughput support
- Scriptable configuration
- Flexible for big teams
- Easy to switch providers
- Service cost optimization
- Fluid tool calls
Cons
- Dependent on original API providers
- No offline functionality
- Savings not guaranteed
- Time consuming for multiple APIs
- Customization capacity limited
- No extra security measures
- Limited language/platform support
Compare alternatives
Similar tools in the catalog.
SemanticGuard ✓
FreemiumCut LLM API costs without breaking responses.
Free + from $49/mo
Full comparison

Deepfake Detection by Modulate ✓
PaidDetect deepfakes with 98.9% accuracy instantly.
from $0.25
Full comparison

Releases 1
Imported reviews 1
"Finally — an AI cost tool that actually aligns incentives"
I've been working in enterprise IT and AI infrastructure for years, and Lexi is one of the most elegantly designed products I've seen in this space. The core insight is simple but powerful: don't charge unless you save money. That alignment alone sets it apart from every other API middleware I've tested.
The integration literally took under two minutes — one URL change in our config, and we were live across multiple providers. The cost transparency in the response headers is genuinely useful for us as a team building on top of AI; we can now log, display, and report on exact token costs per request.
The O(1) memory compression is the real technical differentiator. Long AI conversations tend to degrade in quality and balloon in cost — Lexi solves both problems simultaneously. For anyone running AI in production at any scale, this is infrastructure you didn't know you were missing.
Highly recommended for developers, startups, and enterprise teams alike.
FAQ 12
What is Lexi?
How does Lexi work to reduce AI costs?
Is Lexi only compatible with specific AI providers?
How can I integrate Lexi into my developer workflow?
What is unique about Lexi's billing system?
How does Lexi help to maintain coherence in long AI dialogues?
What type of visibility does Lexi provide for the cost breakdown?
Does Lexi hold my AI provider's keys?
What types of integrations are supported by Lexi?
Can any changes occur in my operational stack while using Lexi?
How do I start using Lexi?
How does Lexi's API key work?
Related tools
Recommended
remio: Your Personal ChatGPT ✓
FreemiumGet Tailored Answer with Your Personal ChatGPT

WriteDoc.ai ✓
Free TrialGenerate beautiful documents with AI
VenturusAI ✓
FreemiumBusiness idea analysis and reporting.
MagicSlides.app AI PPT Maker ✓
FreemiumCreate Stunning PPTs in Seconds with the AI PPT Maker

B12 AI Website Builder ✓
FreemiumAI-powered website builder
GetLogit ✓
FreemiumArtificial intelligence, available for everyone.