
InternVL3
Open MLLM excelling in vision, reasoning, and long context via multimodal pre-training.
Source rating 5.0
(82)
35 views
35/mo traffic
0 saves
Unknown
Verdict
A quick read before you dig into the full page.
- Best if
- Open MLLM excelling in vision, reasoning, and long context via multimodal pre-training
- Pick this when
- Open MLLM excelling in vision, reasoning, and long context via multimodal pre-training
Overview
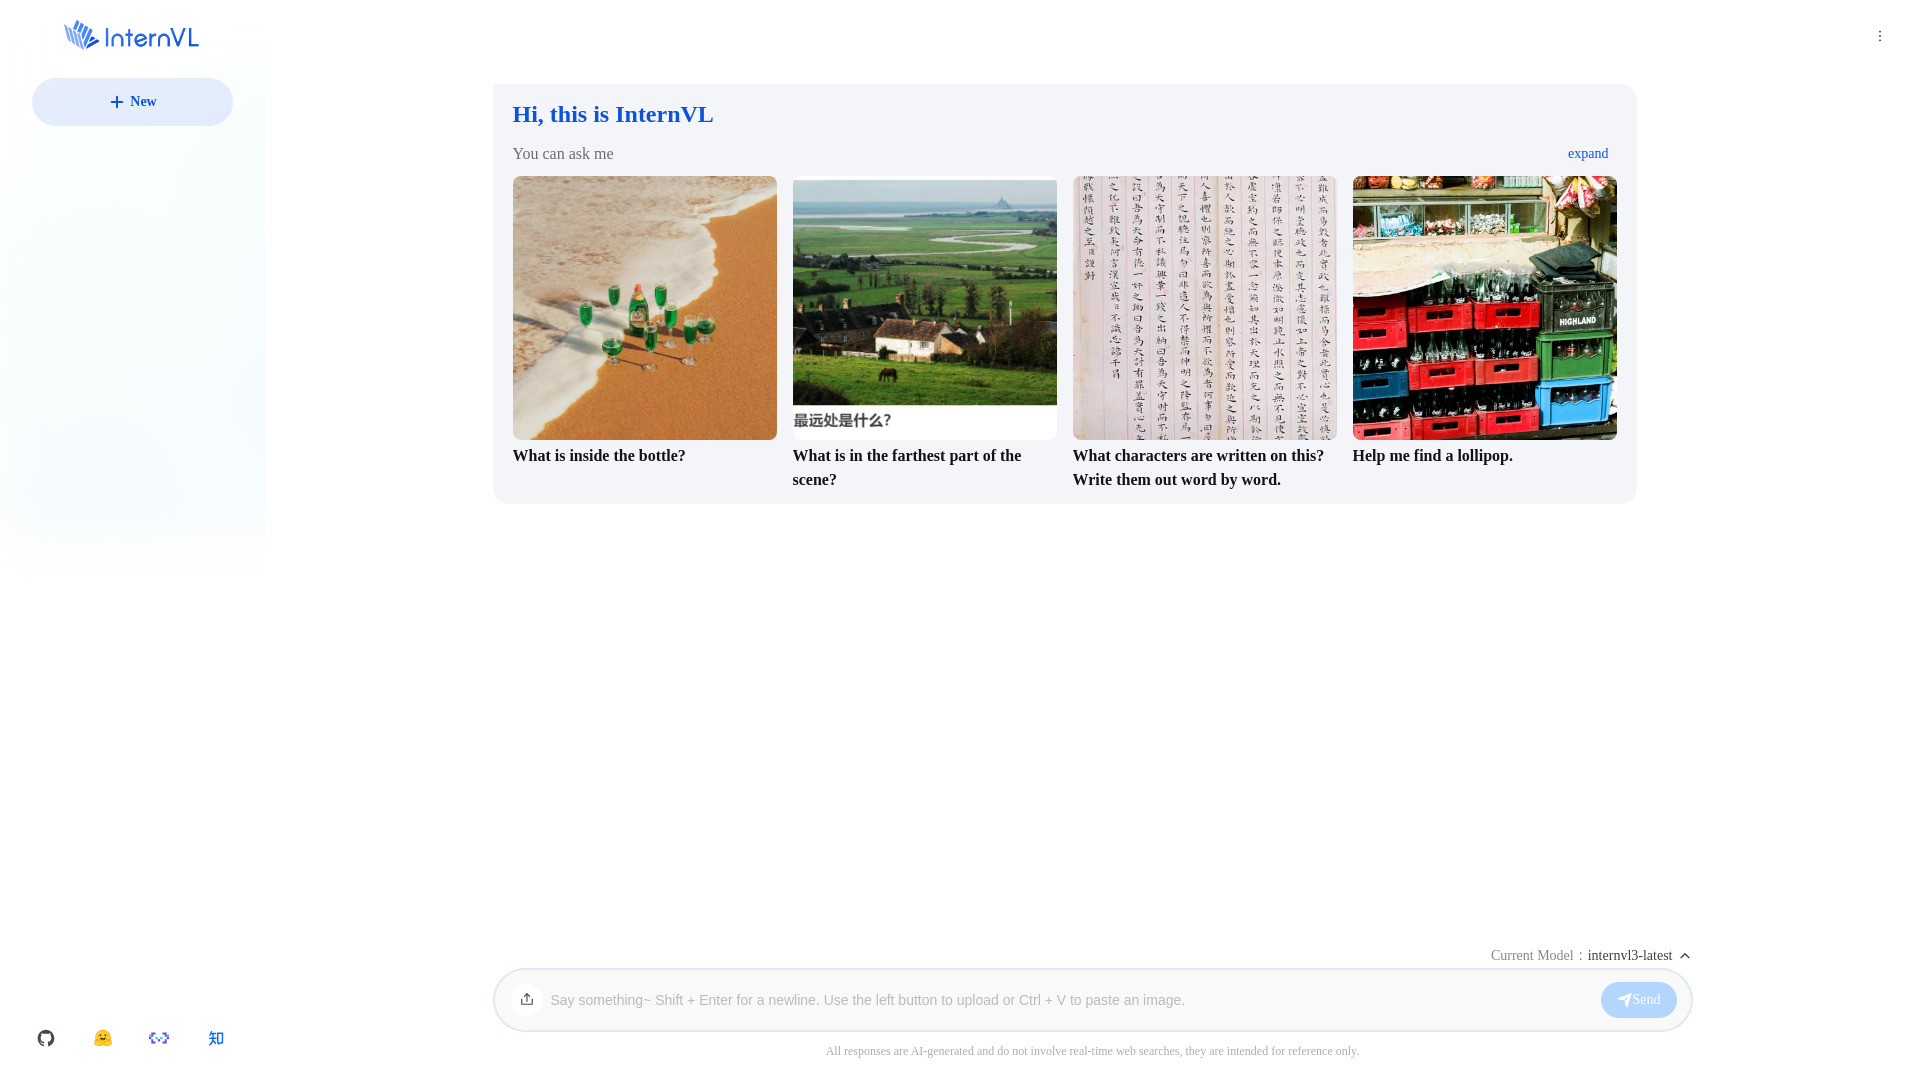
InternVL is an Open MLLM family (1B-78B) from OpenGVLab that excels at vision, reasoning, long context & agents via native multimodal pre-training. It outperforms base LLMs on text tasks.
Access & connections
Where you can use InternVL3.
Platforms
Capabilities
What this tool accepts, produces, and is strongest at.
Highlights
- Multimodal pre-training
- Vision and reasoning capabilities
- Long context understanding
- Agent capabilities
- Outperforms base LLMs on text tasks
FAQ 4
What is InternVL?
InternVL is an Open MLLM family (1B-78B) from OpenGVLab that excels at vision, reasoning, long context & agents via native multimodal pre-training. It outperforms base LLMs on text tasks.
How to use InternVL?
You can ask InternVL questions. Examples include asking what a person is looking at, implementing a flowchart using Python, and relating images to each other.
What is InternVL?
InternVL is an Open MLLM family from OpenGVLab that excels at vision, reasoning, long context & agents via native multimodal pre-training.
What can I ask InternVL?
You can ask InternVL questions about images, request Python implementations of flowcharts, and ask it to relate different images to each other.
Related tools
Recommended

InternVL3